6 min readDevelopmentFeatured
Inference on Apple Silicon with MLX
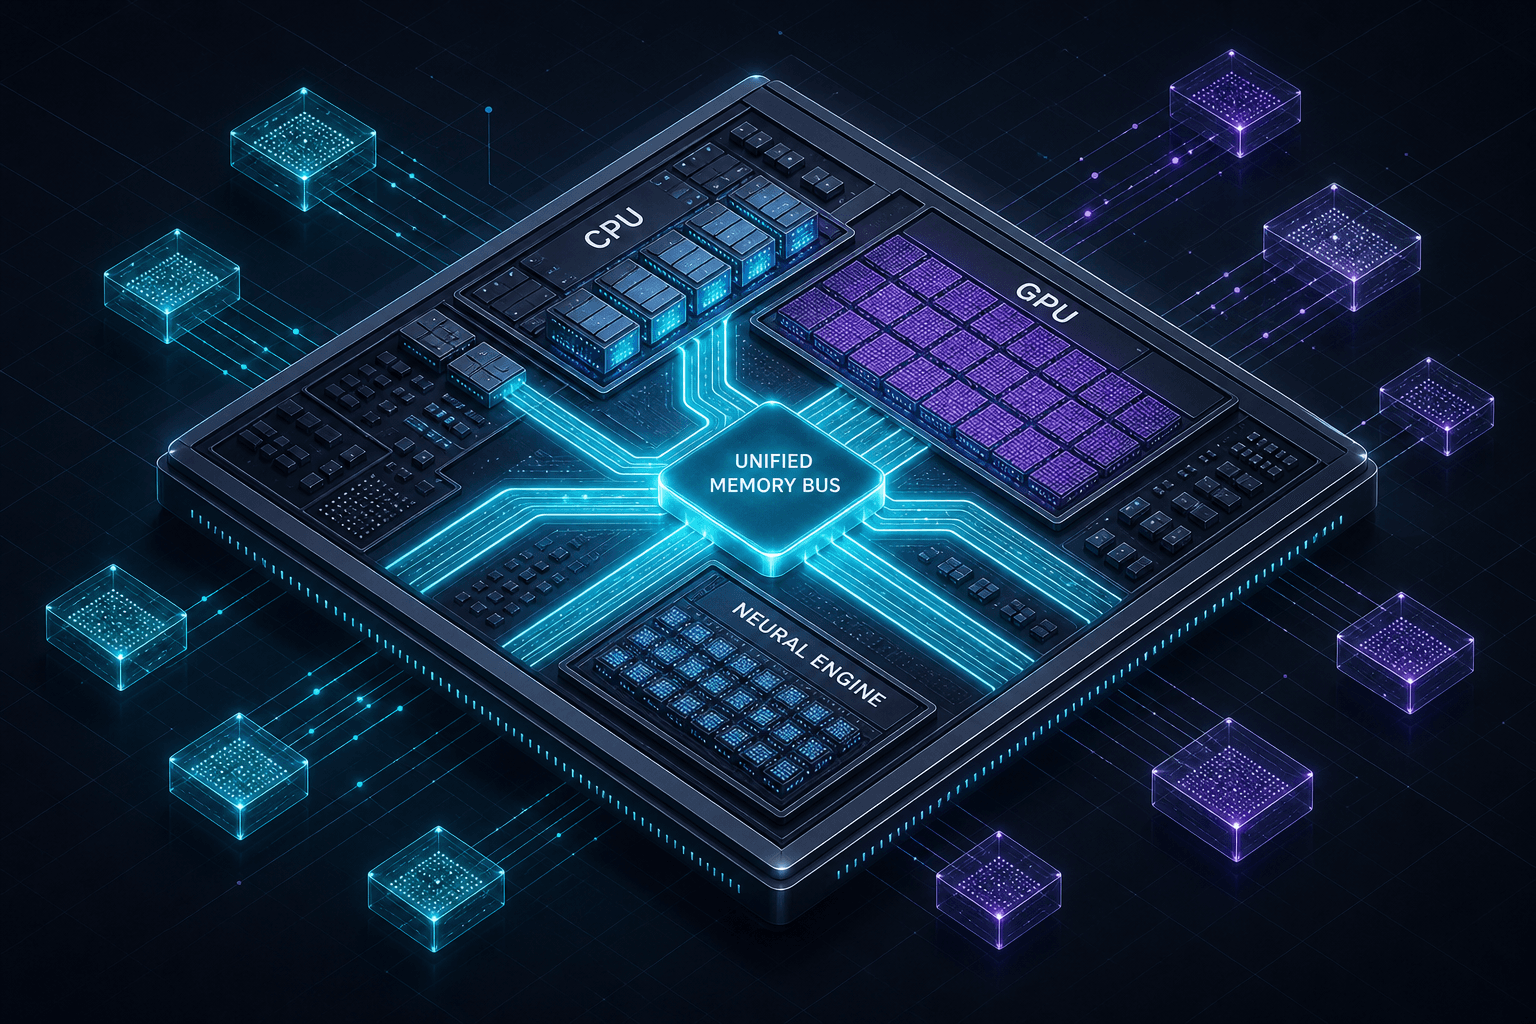
Explore how MLX enables efficient local inference on Apple Silicon by leveraging unified memory, allowing Mac developers and ML engineers to run models without external hardware.
Part 7 · Small Models & Distillation