6 min readDevelopmentFeatured
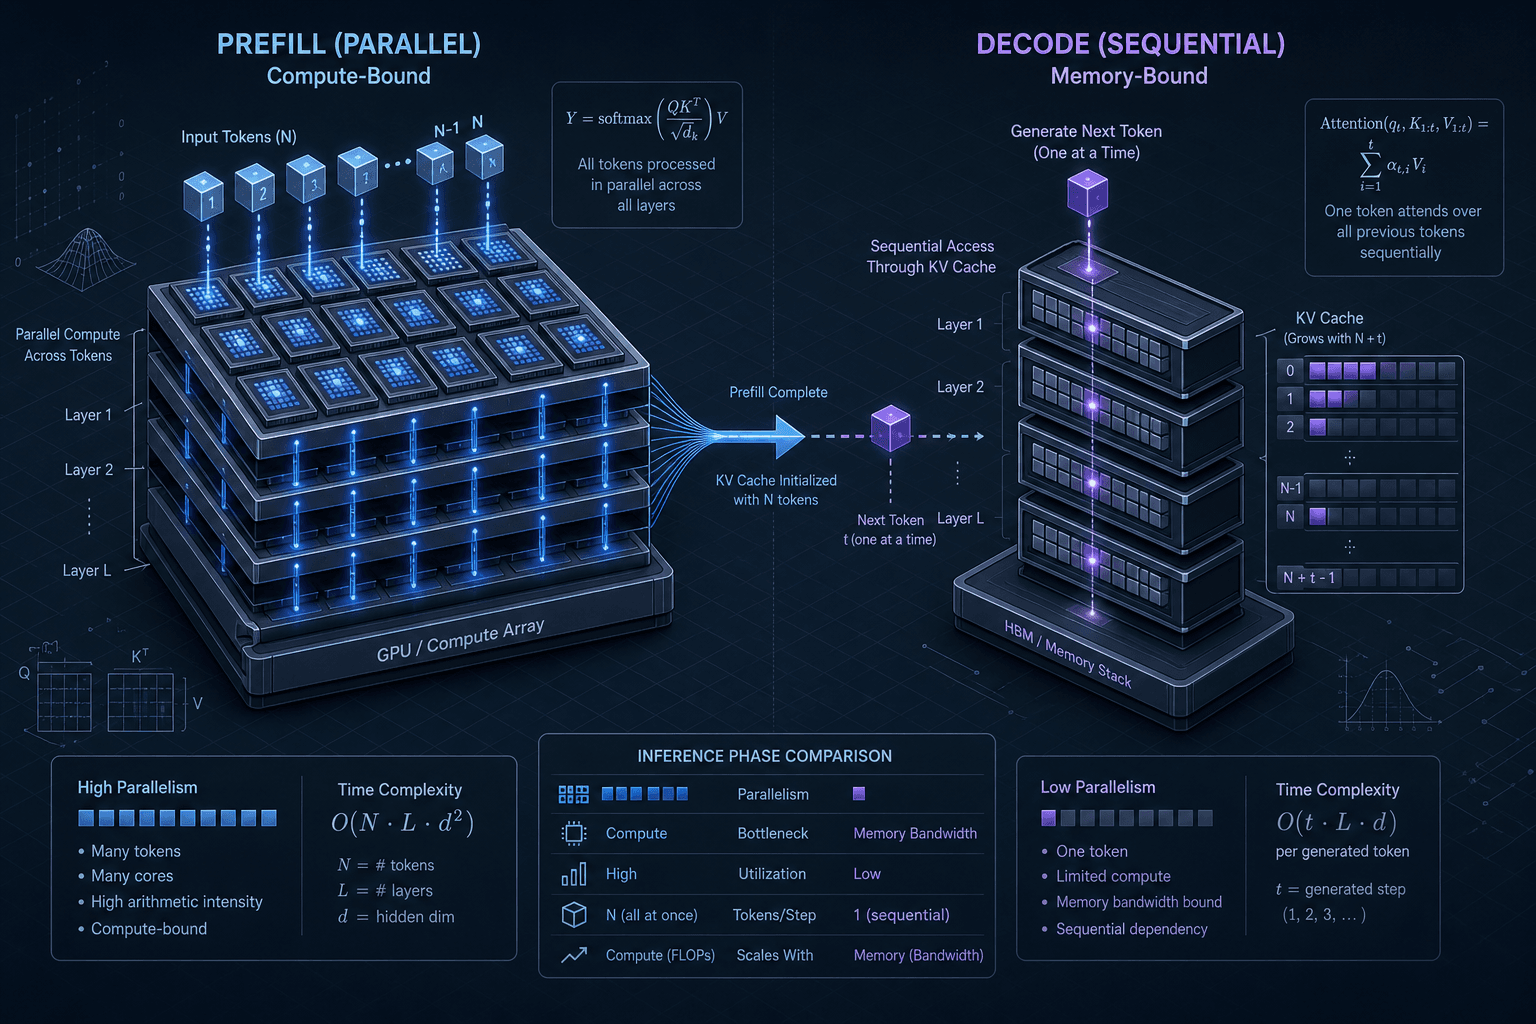
Prefill vs Decode: The Two Halves of Every LLM Request
Understand the distinct computational demands of the prefill and decode stages in large language model inference, from initial token generation to subsequent output.
Part 3 · LLM Inference from Scratch