6 min readDevelopment
SGLang's RadixAttention, Explained
Explore how SGLang uses RadixAttention and prefix caching to significantly boost throughput and efficiency in large language model serving.
Tag
Read 14 articles on Inference by Ashish Srivastava — practical guides covering implementation patterns, security, and production lessons.
14 posts
Explore how SGLang uses RadixAttention and prefix caching to significantly boost throughput and efficiency in large language model serving.
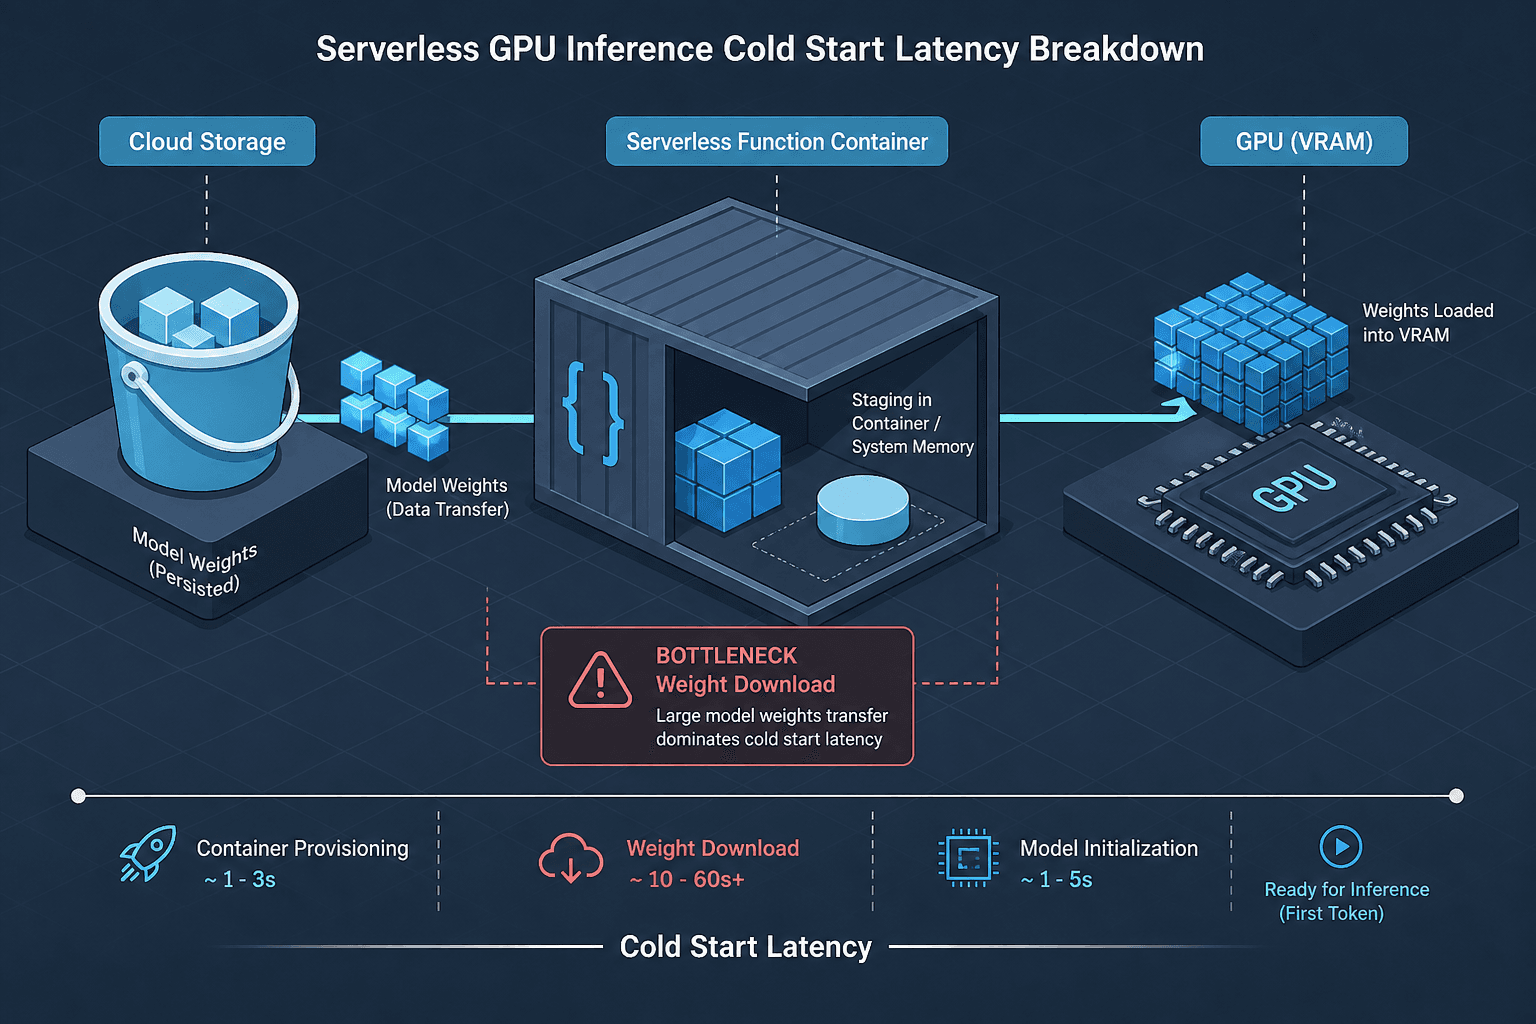
Serverless GPU inference often suffers from high latency during initialization. This article examines methods to reduce cold start times using snapshots and model streaming.
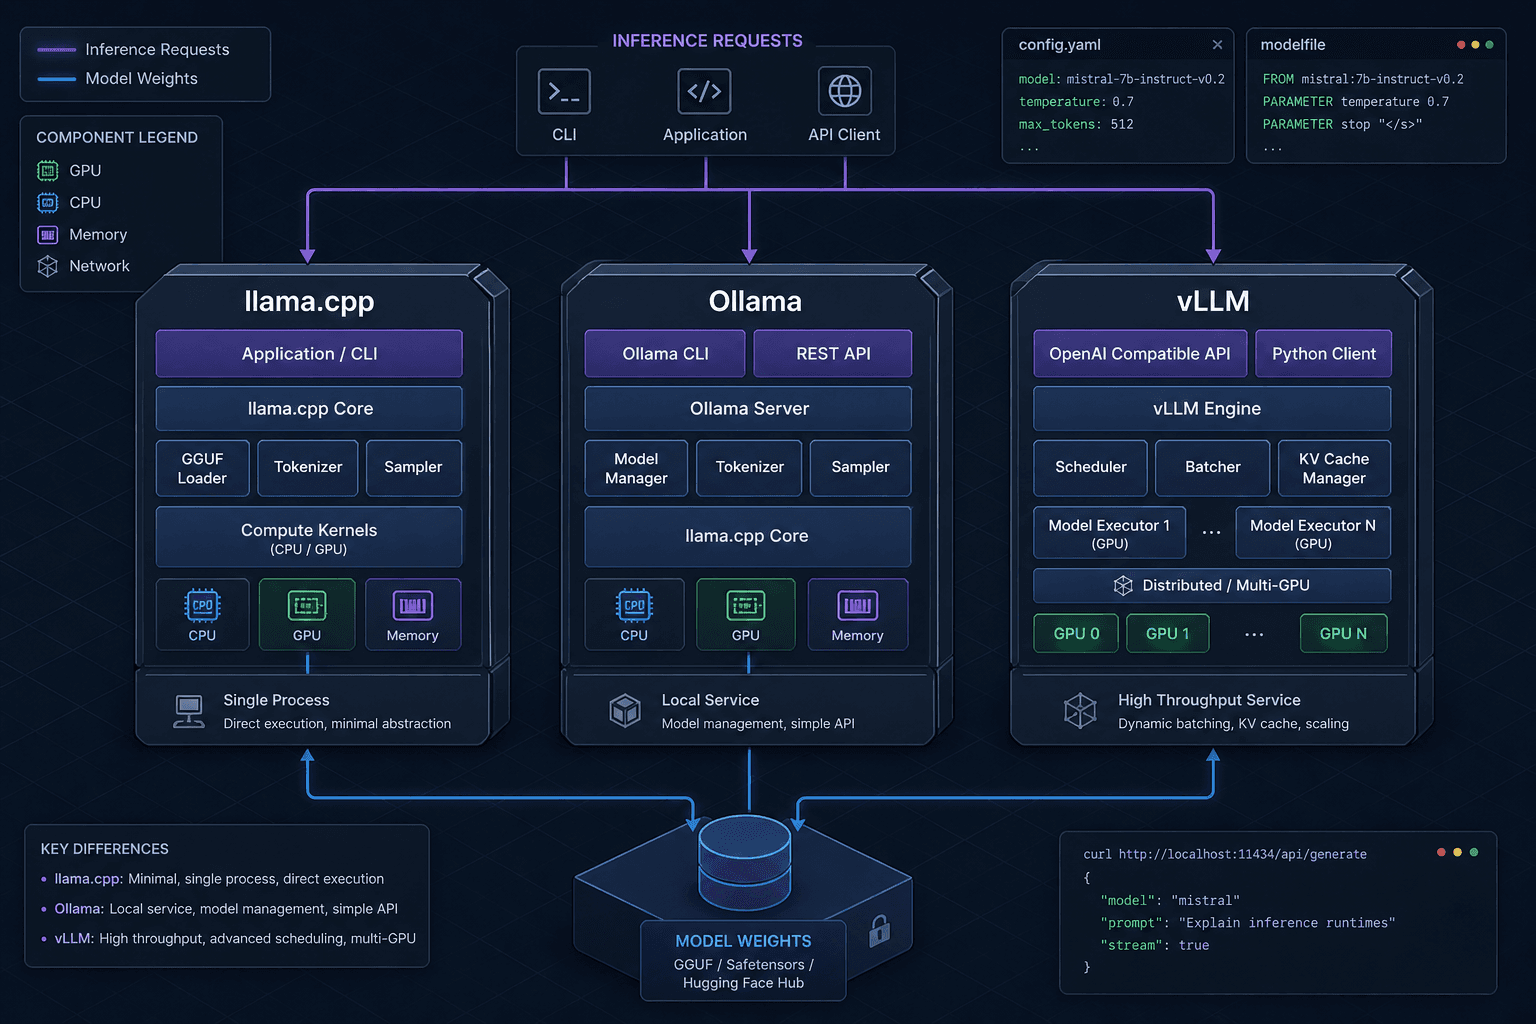
Compare Ollama, vLLM, and llama.cpp to choose the best inference runtime for your specific development or engineering needs.
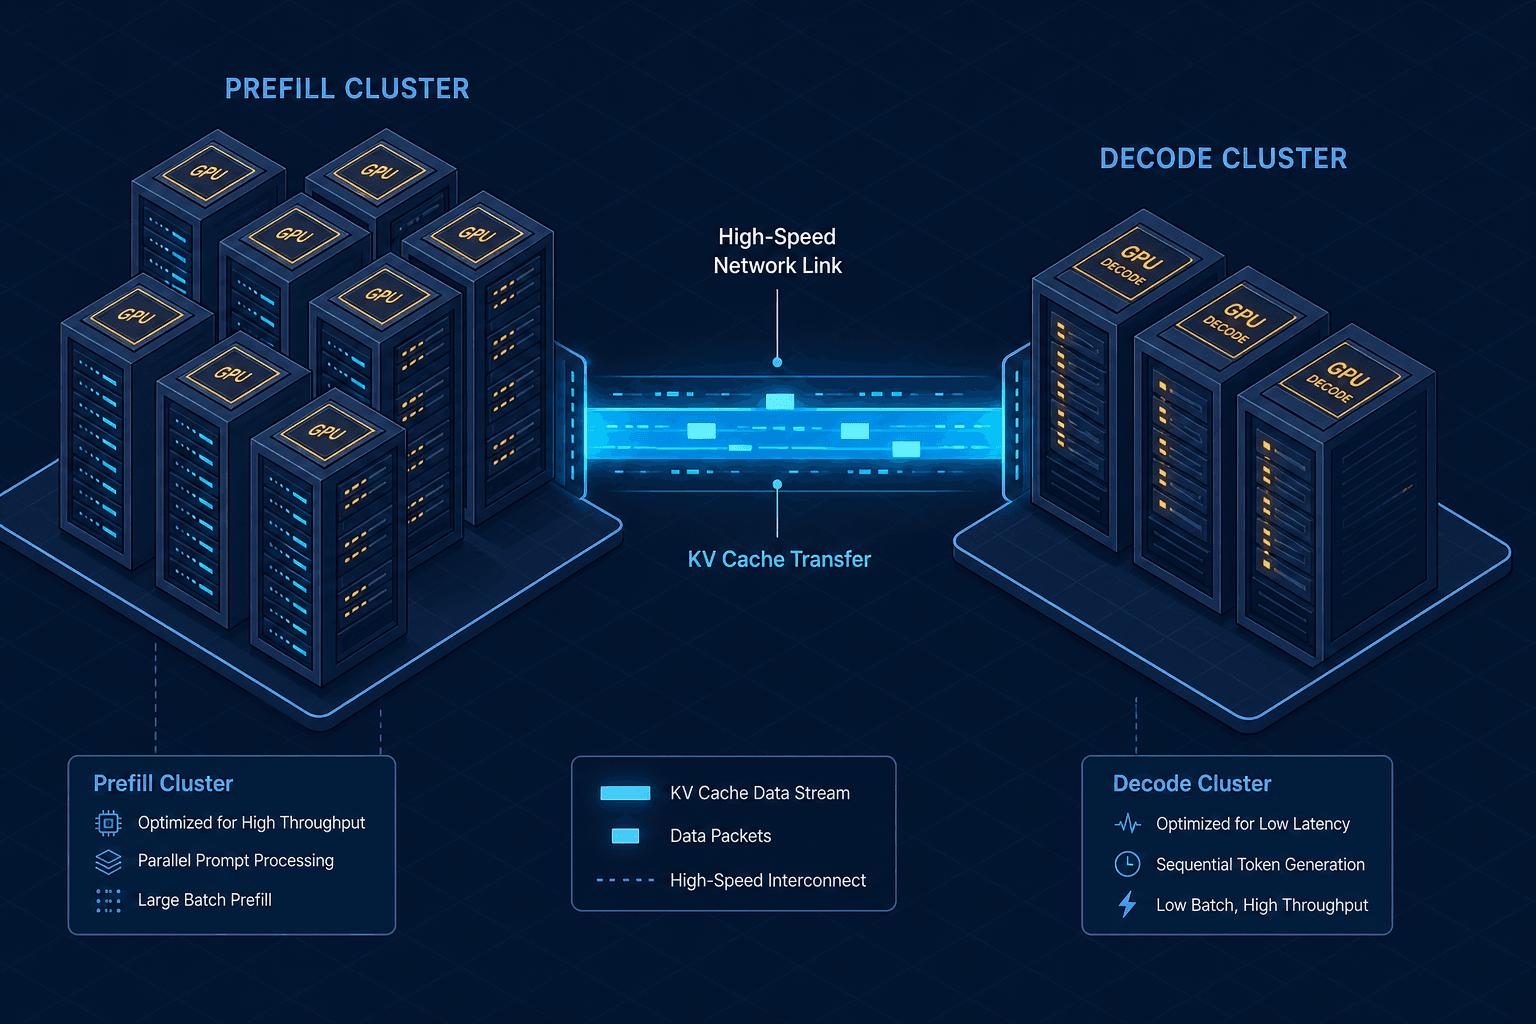
Explore how separating prefill and decode phases in LLM serving improves efficiency through optimized KV cache transfer and disaggregated infrastructure.
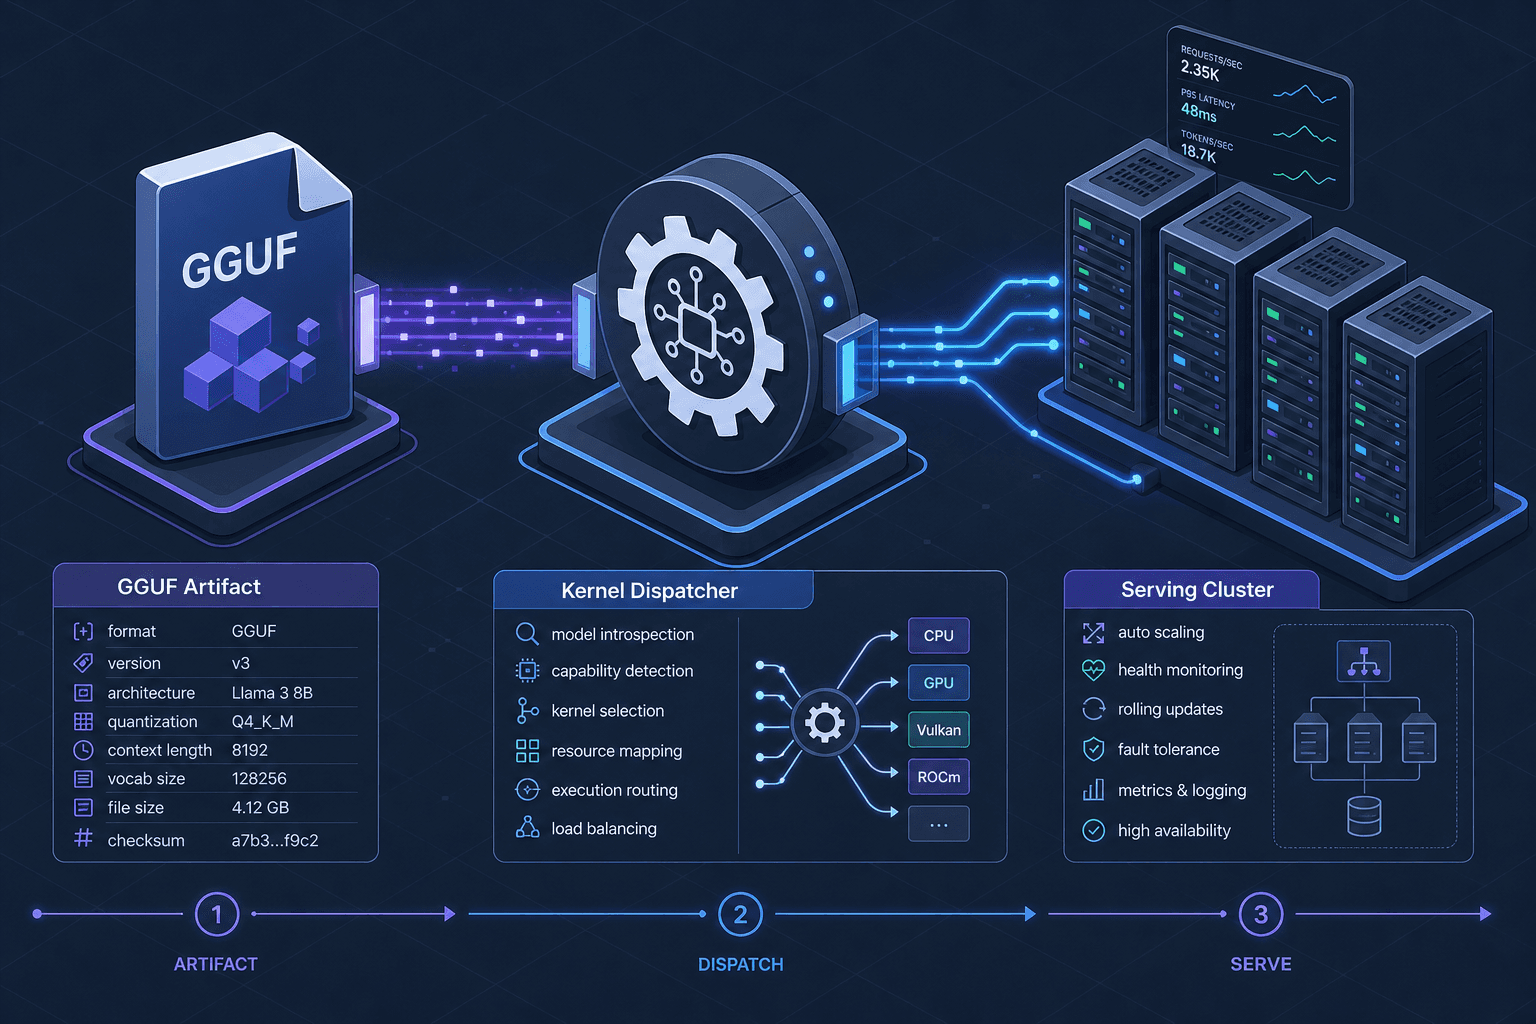
Part 4 · Distributed & MoE ServingLearn how to deploy quantized models in production. This guide covers model artifacts, kernel selection, serving infrastructure, and rollback strategies for ML and platform engineers.
Part 6 · Quantization in PracticeLearn how to apply quantization to the KV cache to save memory and speed up inference without significantly degrading model quality.
Part 4 · Quantization in PracticeA technical walkthrough on configuring vLLM to handle multiple LoRA adapters at serve time, optimizing for multi-tenant ML workloads.
Part 7 · Production vLLMExplore the nuances of prefix caching in vLLM. Learn when automatic prefix caching boosts TTFT and cache hit rates, and identify scenarios where it offers little value.
Part 4 · Production vLLMA practical guide to deploying Hugging Face models via vLLM's OpenAI-compatible API, enabling high-throughput inference with minimal setup.
Part 2 · Production vLLMUnderstanding TTFT, TPOT, and p99 is essential for optimizing LLM inference. This guide breaks down these metrics for SREs and backend developers.
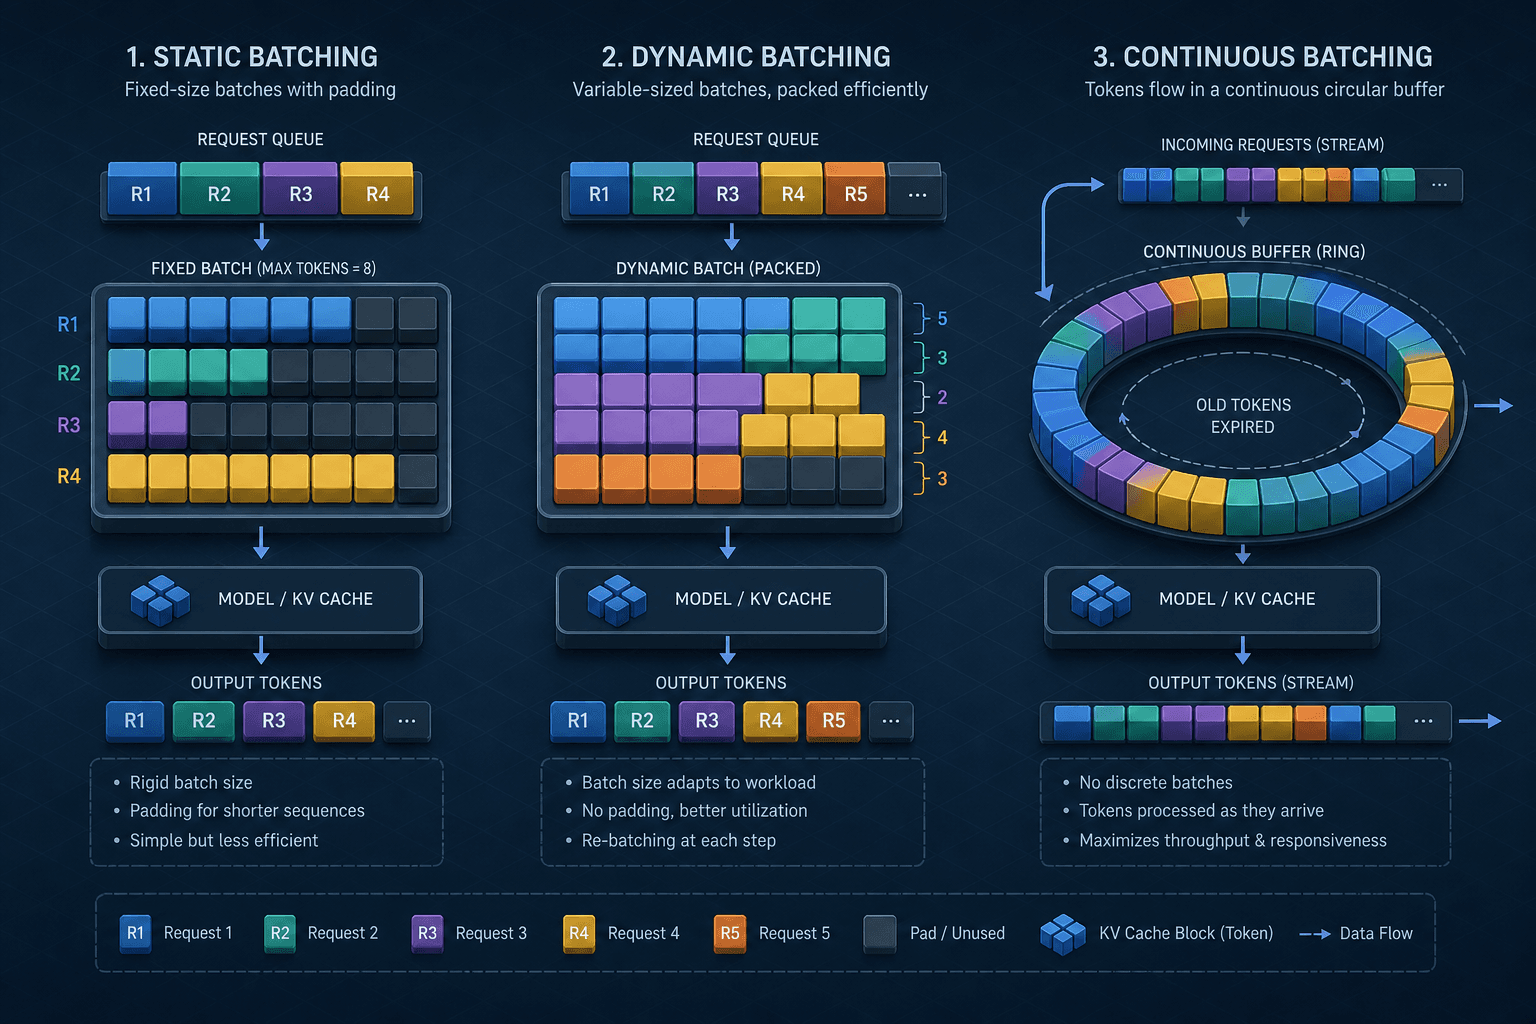
Part 6 · LLM Inference from ScratchExplore how static, dynamic, and continuous batching strategies impact LLM inference performance, focusing on throughput optimization and latency reduction.
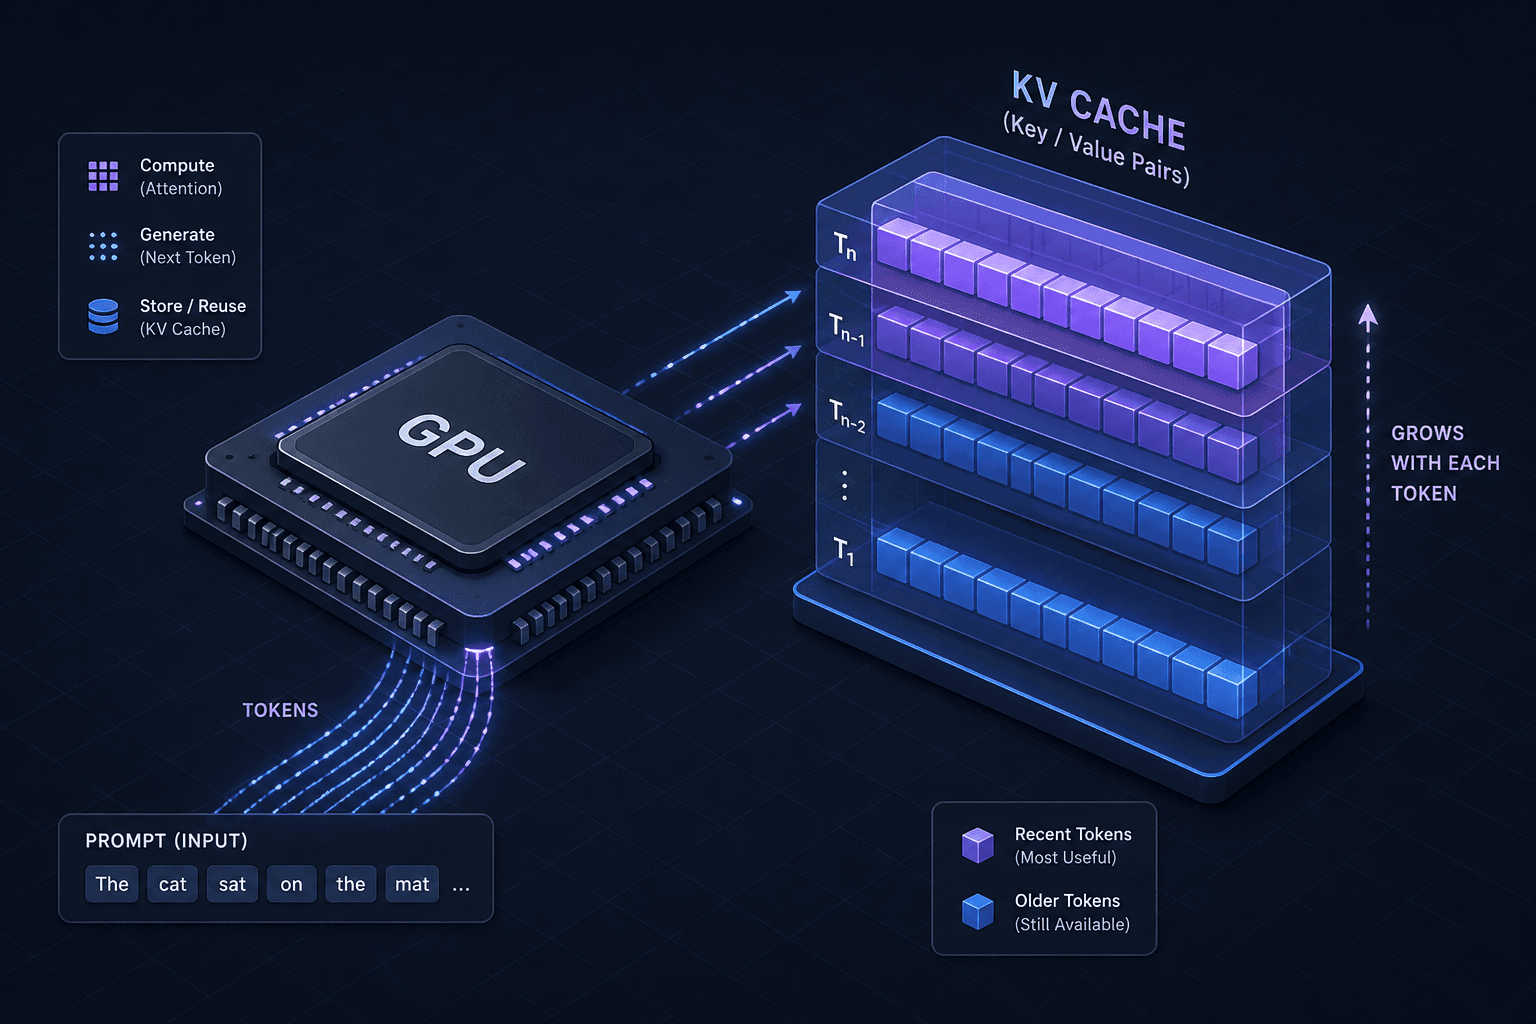
Part 5 · LLM Inference from ScratchUnderstand how the KV cache accelerates LLM inference by storing attention states, reducing redundant computation, and boosting concurrency efficiency.
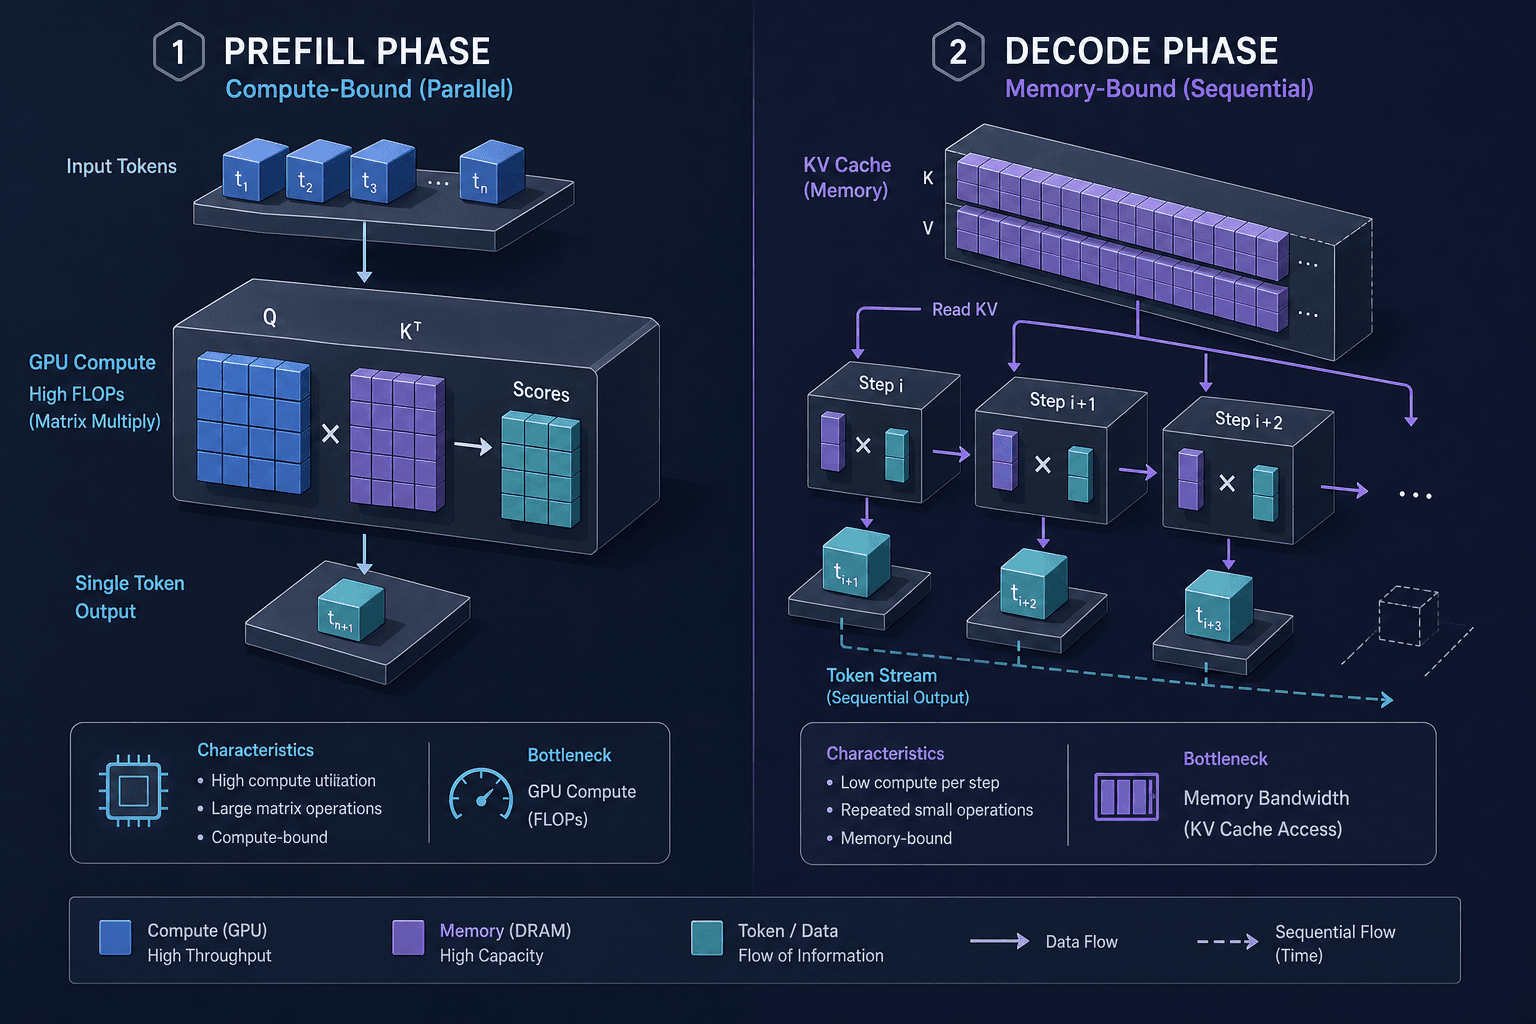
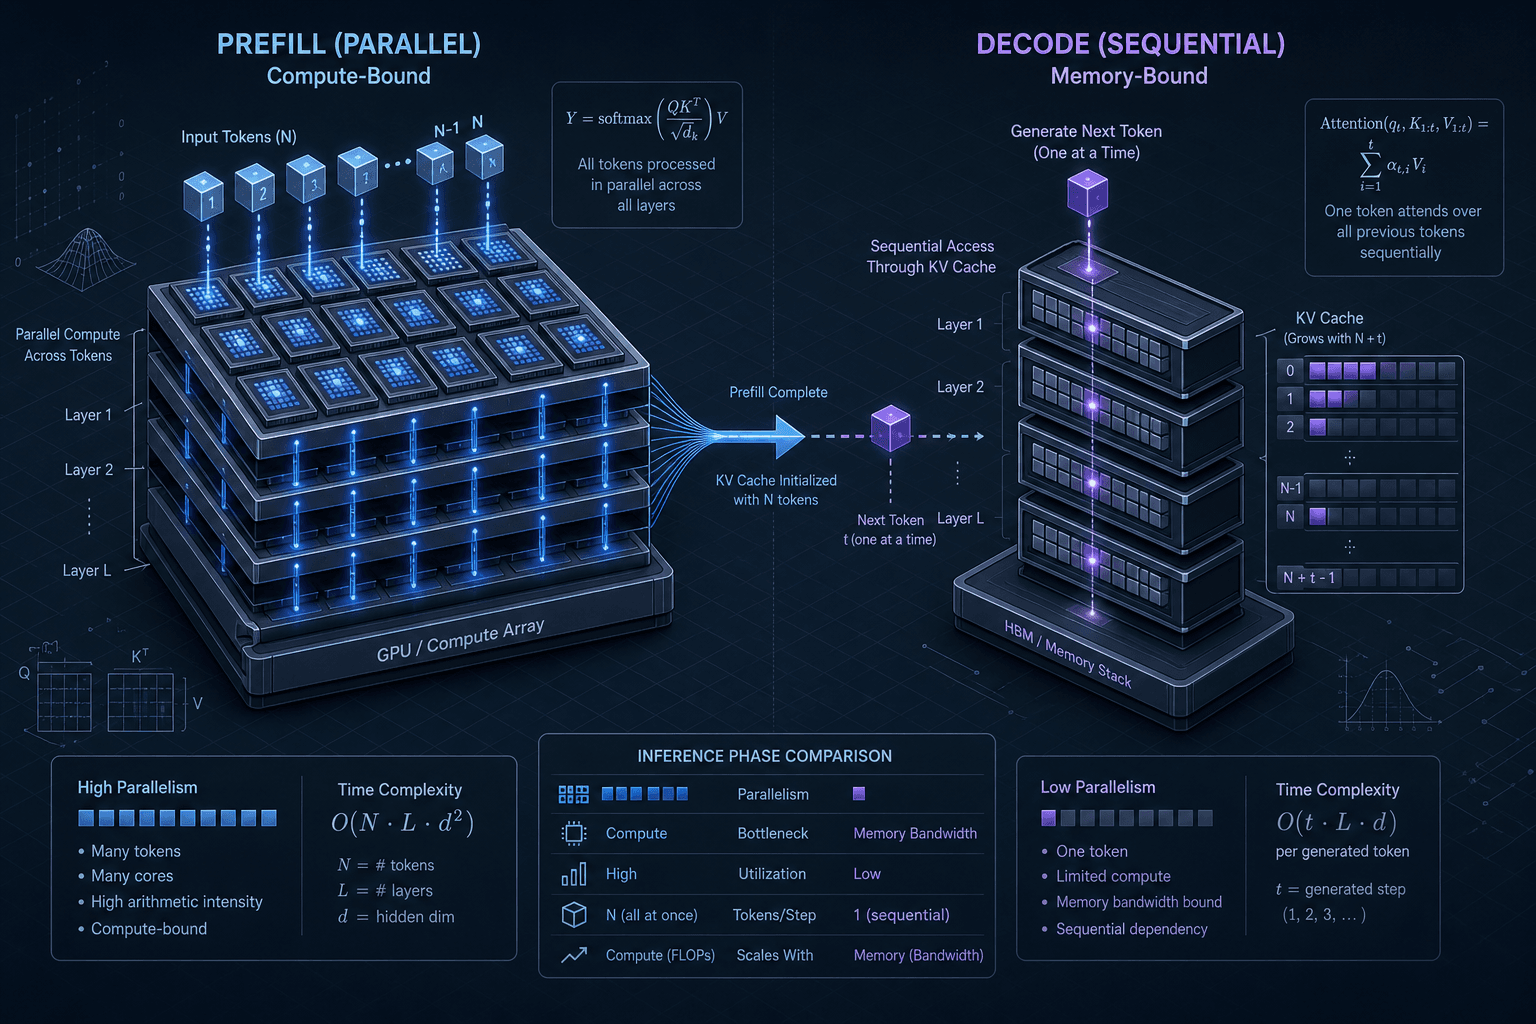
Part 4 · LLM Inference from ScratchUnderstand the distinct computational demands of the prefill and decode stages in large language model inference, from initial token generation to subsequent output.
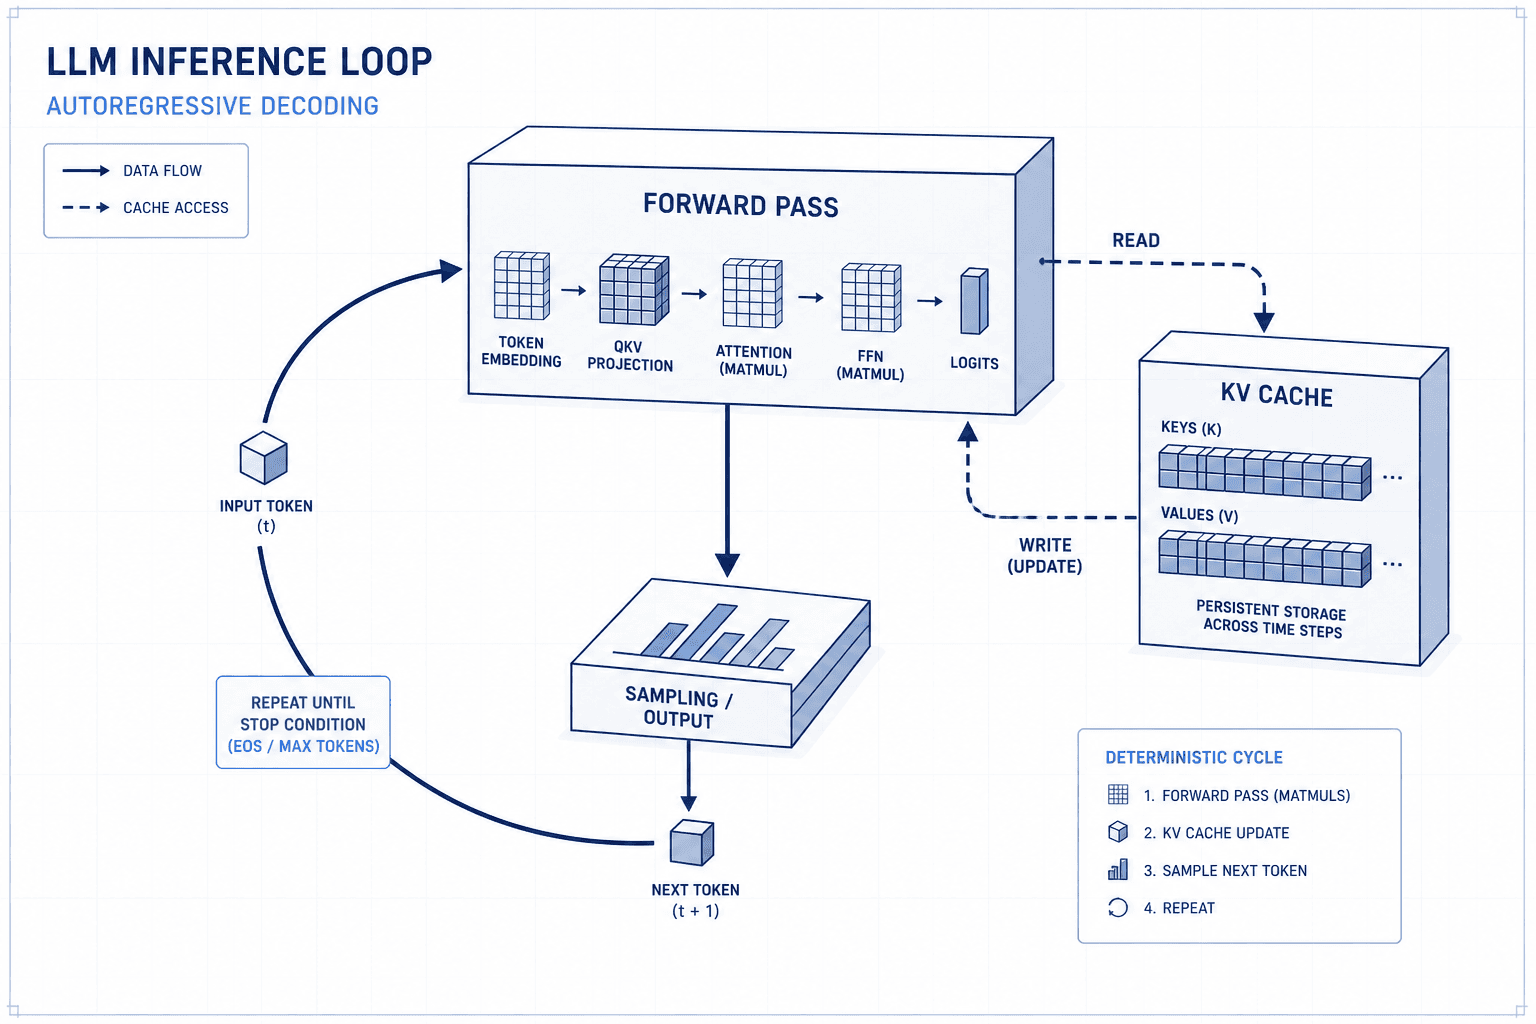
Part 3 · LLM Inference from ScratchUnderstand how LLMs generate text token by token. This guide breaks down the inference process, forward pass mechanics, and autoregressive logic for backend developers.
Part 1 · LLM Inference from Scratch