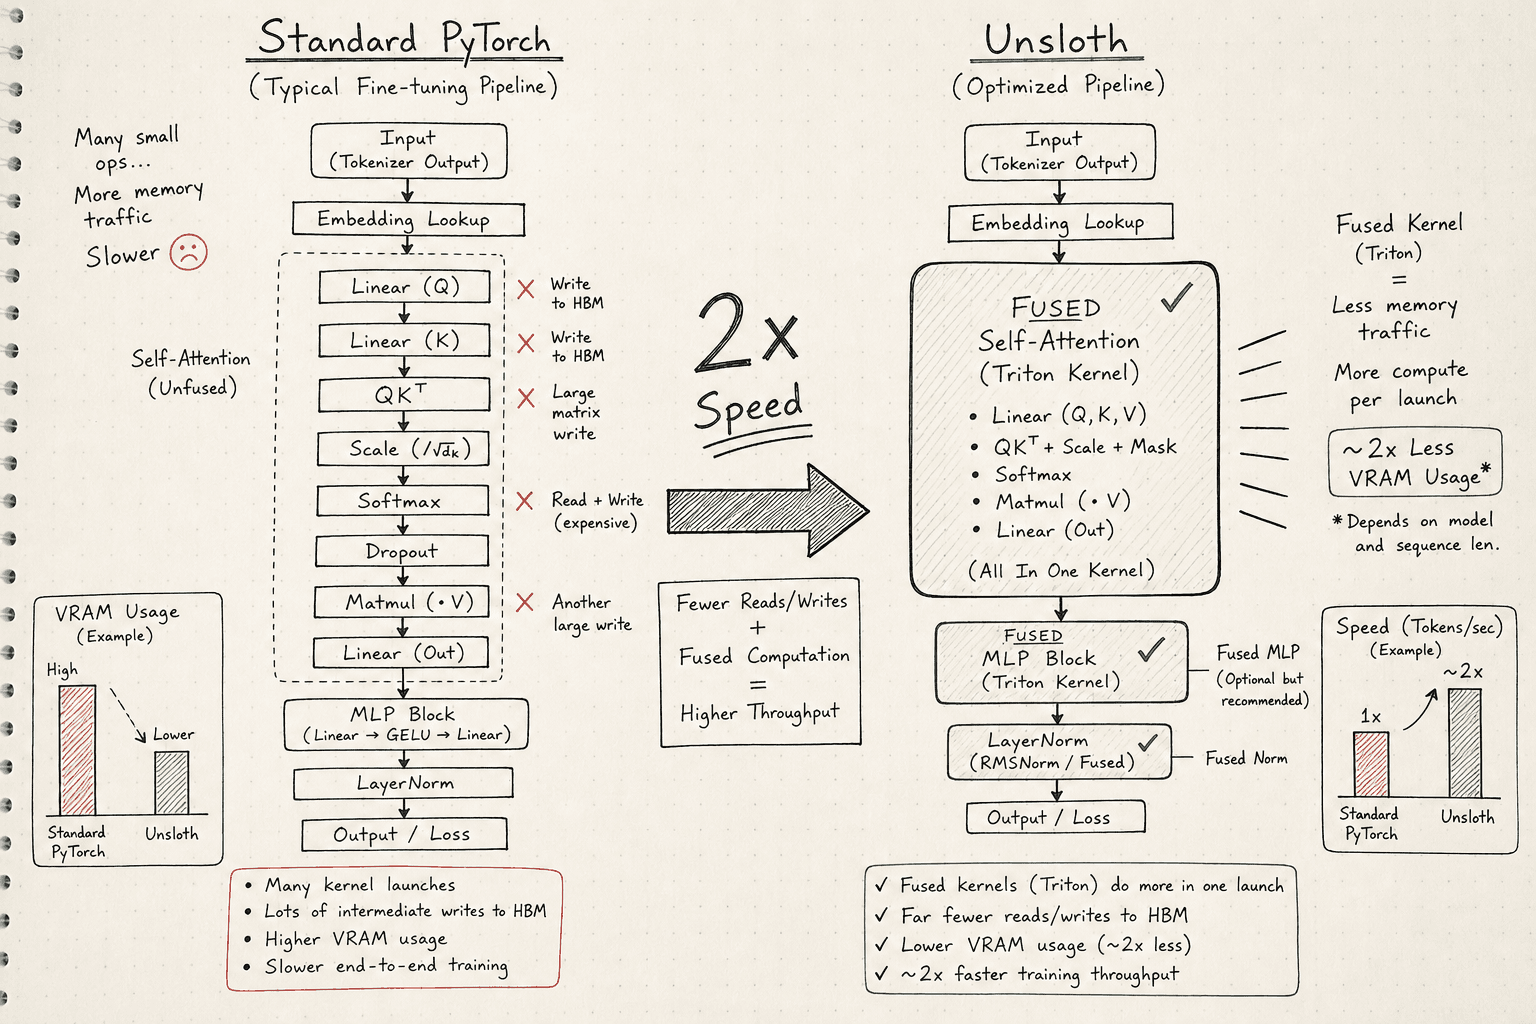
Unsloth: Fine-Tuning 2x Faster on One GPU
Discover how Unsloth leverages Triton kernels and LoRA to double fine-tuning speed, making advanced model training accessible on a single GPU.
Part 10 · Fine-Tuning LLMs Hands-OnTag
Read 6 articles on Optimization by Ashish Srivastava — practical guides covering implementation patterns, security, and production lessons.
6 posts
Discover how Unsloth leverages Triton kernels and LoRA to double fine-tuning speed, making advanced model training accessible on a single GPU.
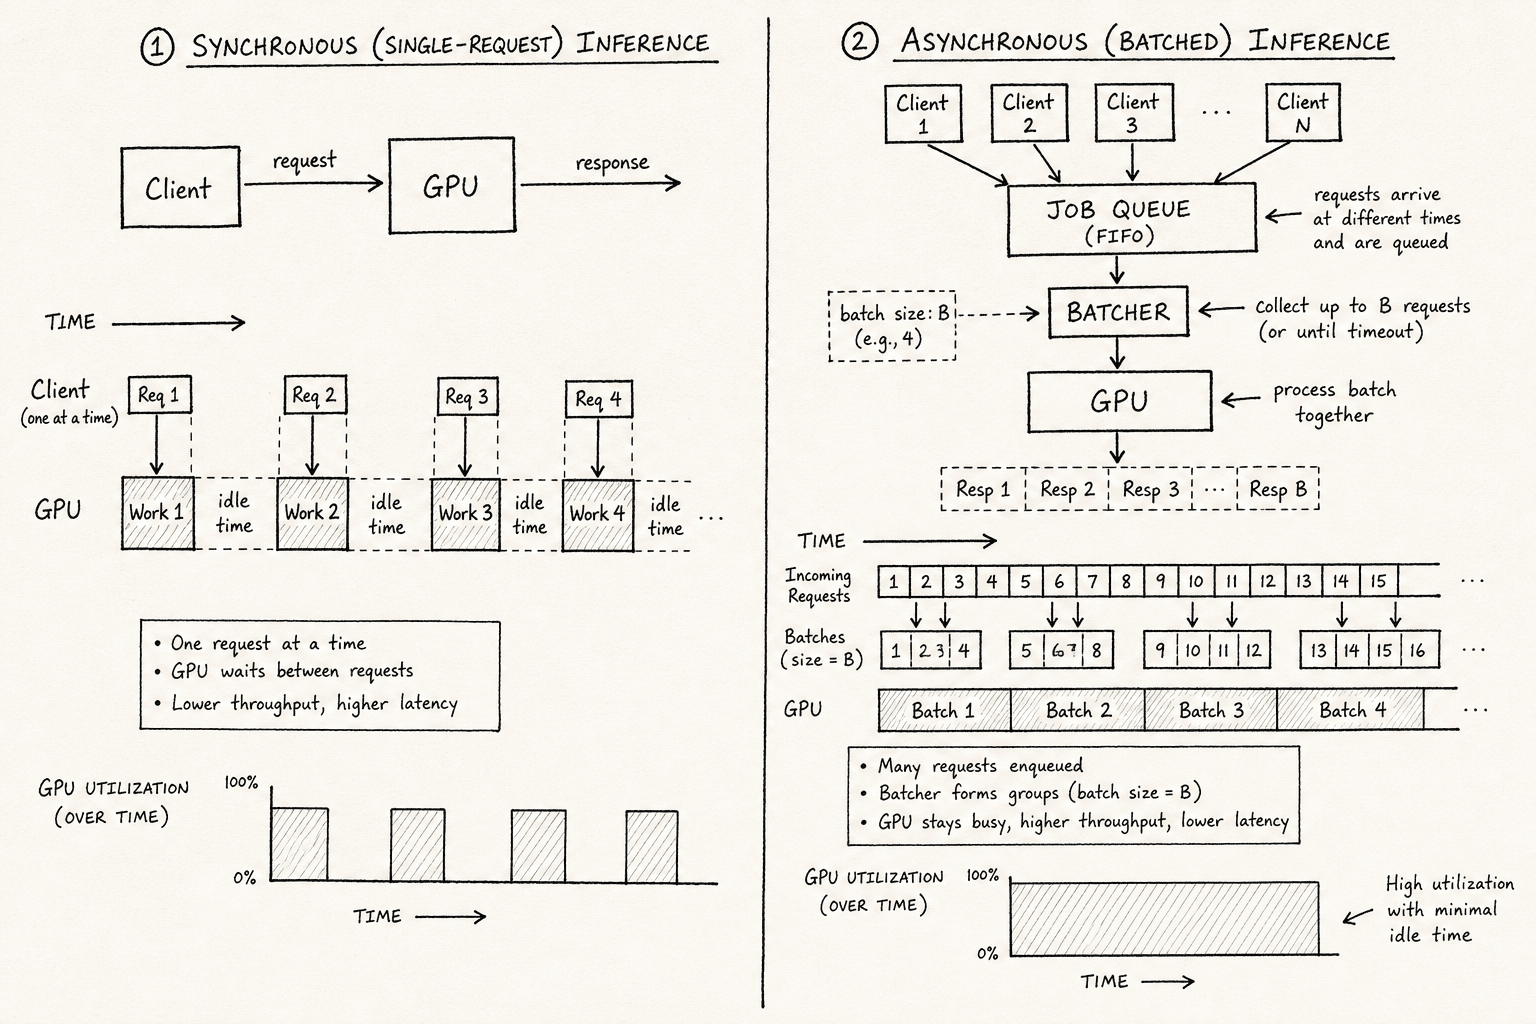
Part 10 · Fine-Tuning LLMs Hands-OnLearn how leveraging batch APIs and asynchronous inference can halve your infrastructure costs while maintaining performance for offline workloads.
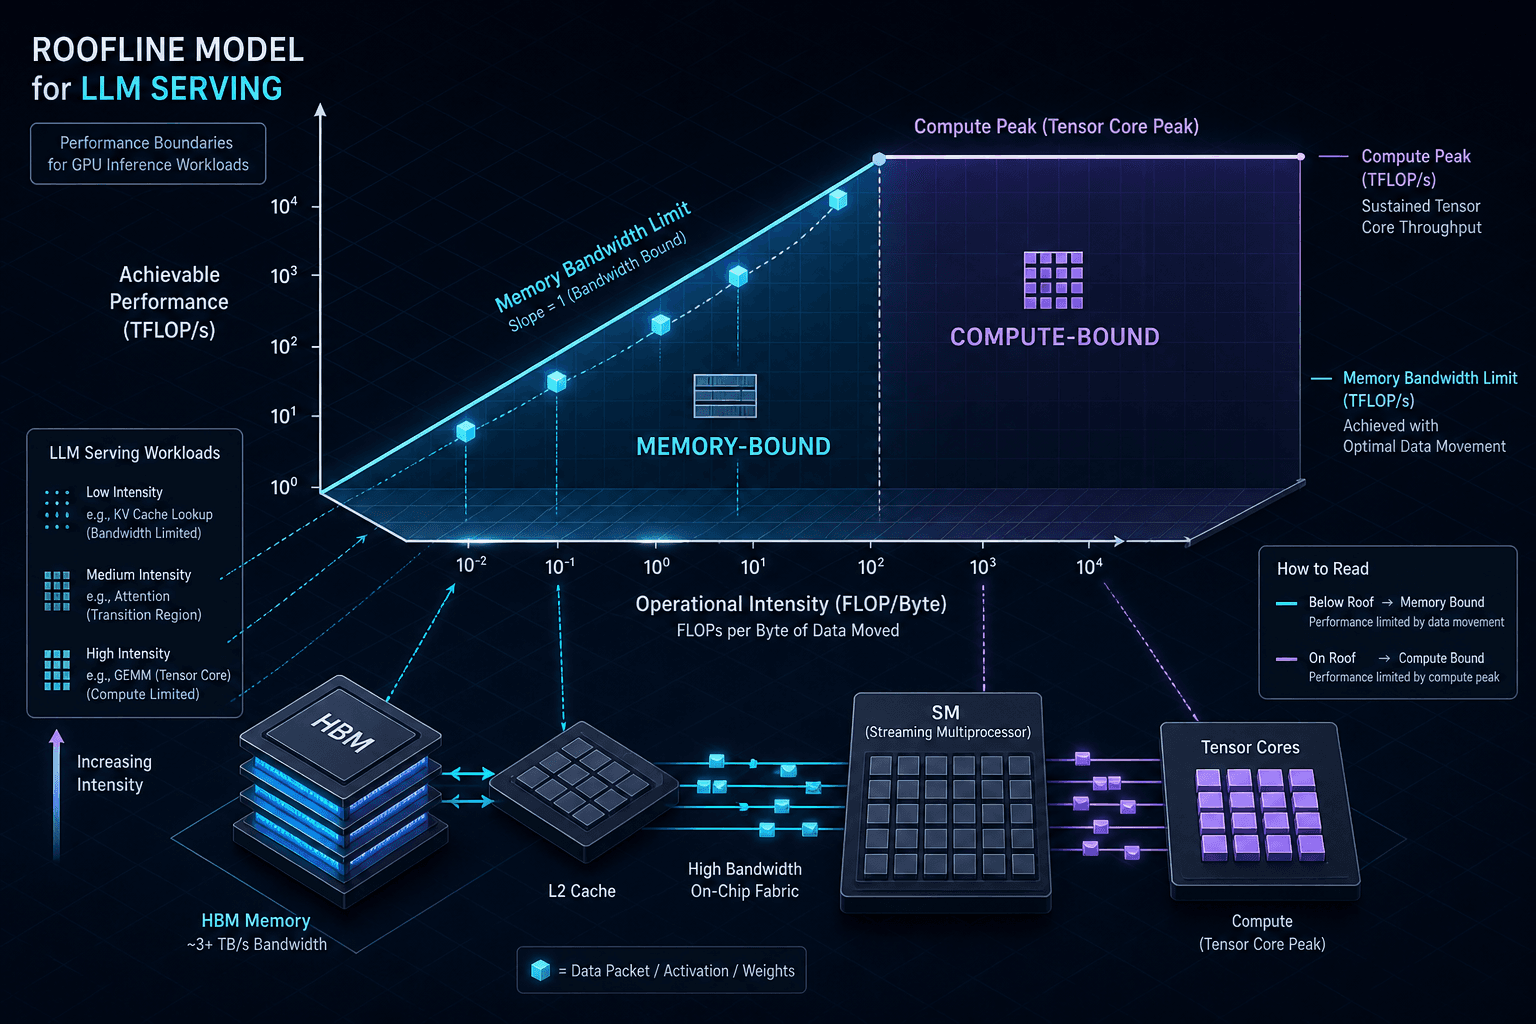
Learn how to use roofline analysis to optimize GPU utilization and measure MFU effectively in LLM serving pipelines.
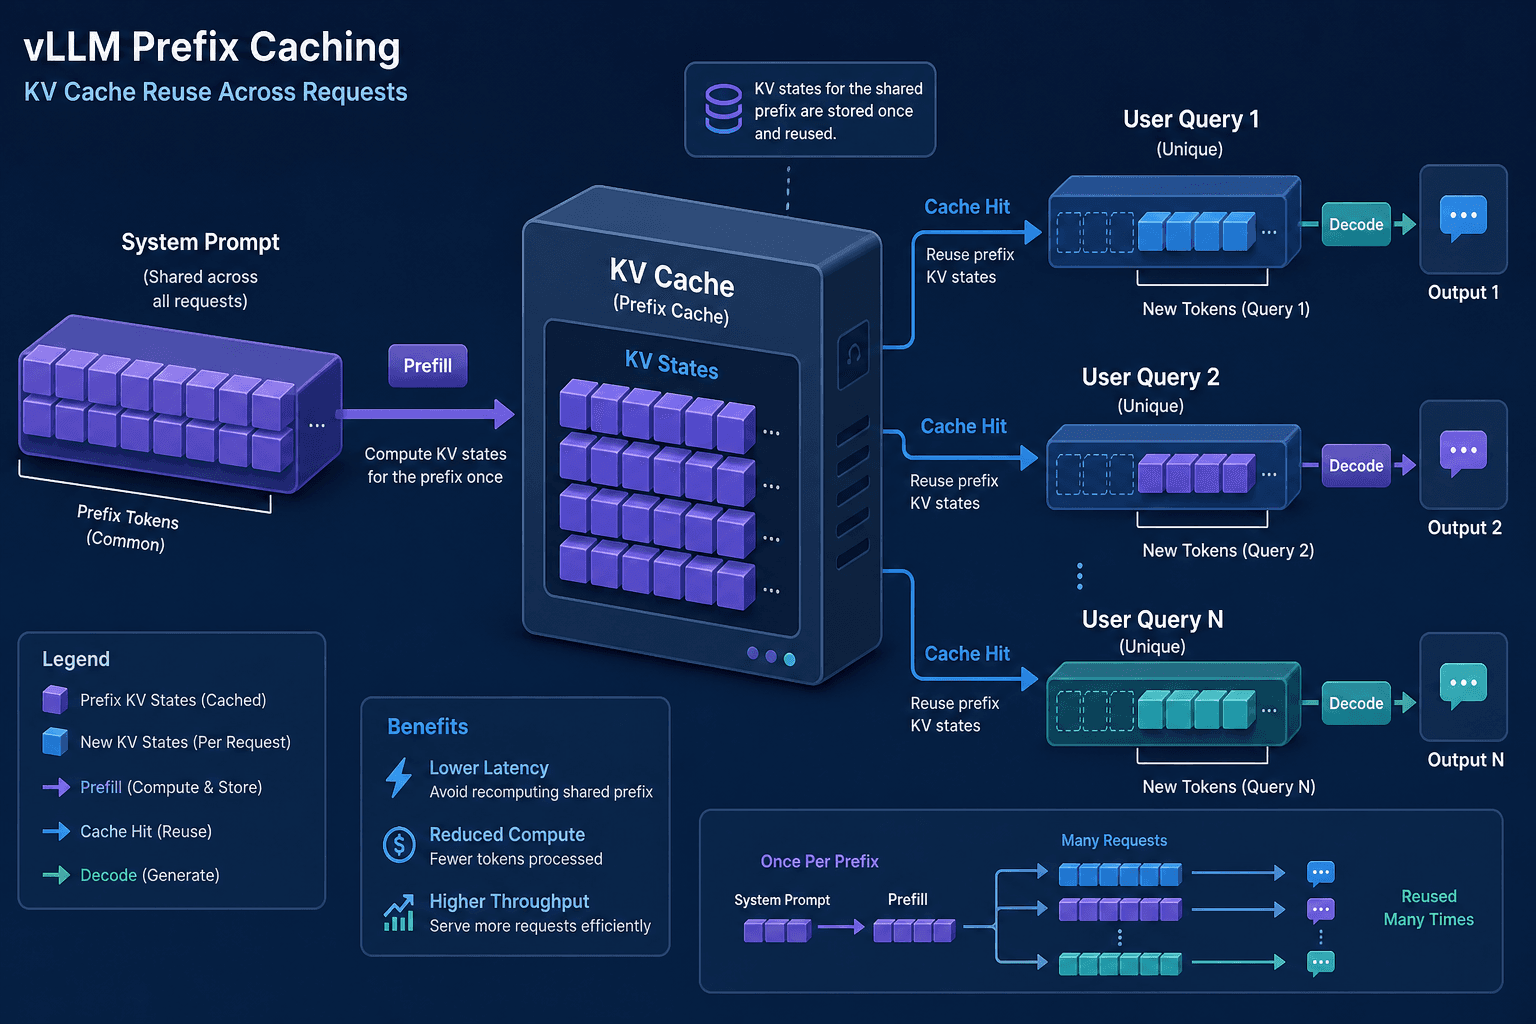
Part 2 · GPU Economics for AI TeamsExplore the nuances of prefix caching in vLLM. Learn when automatic prefix caching boosts TTFT and cache hit rates, and identify scenarios where it offers little value.
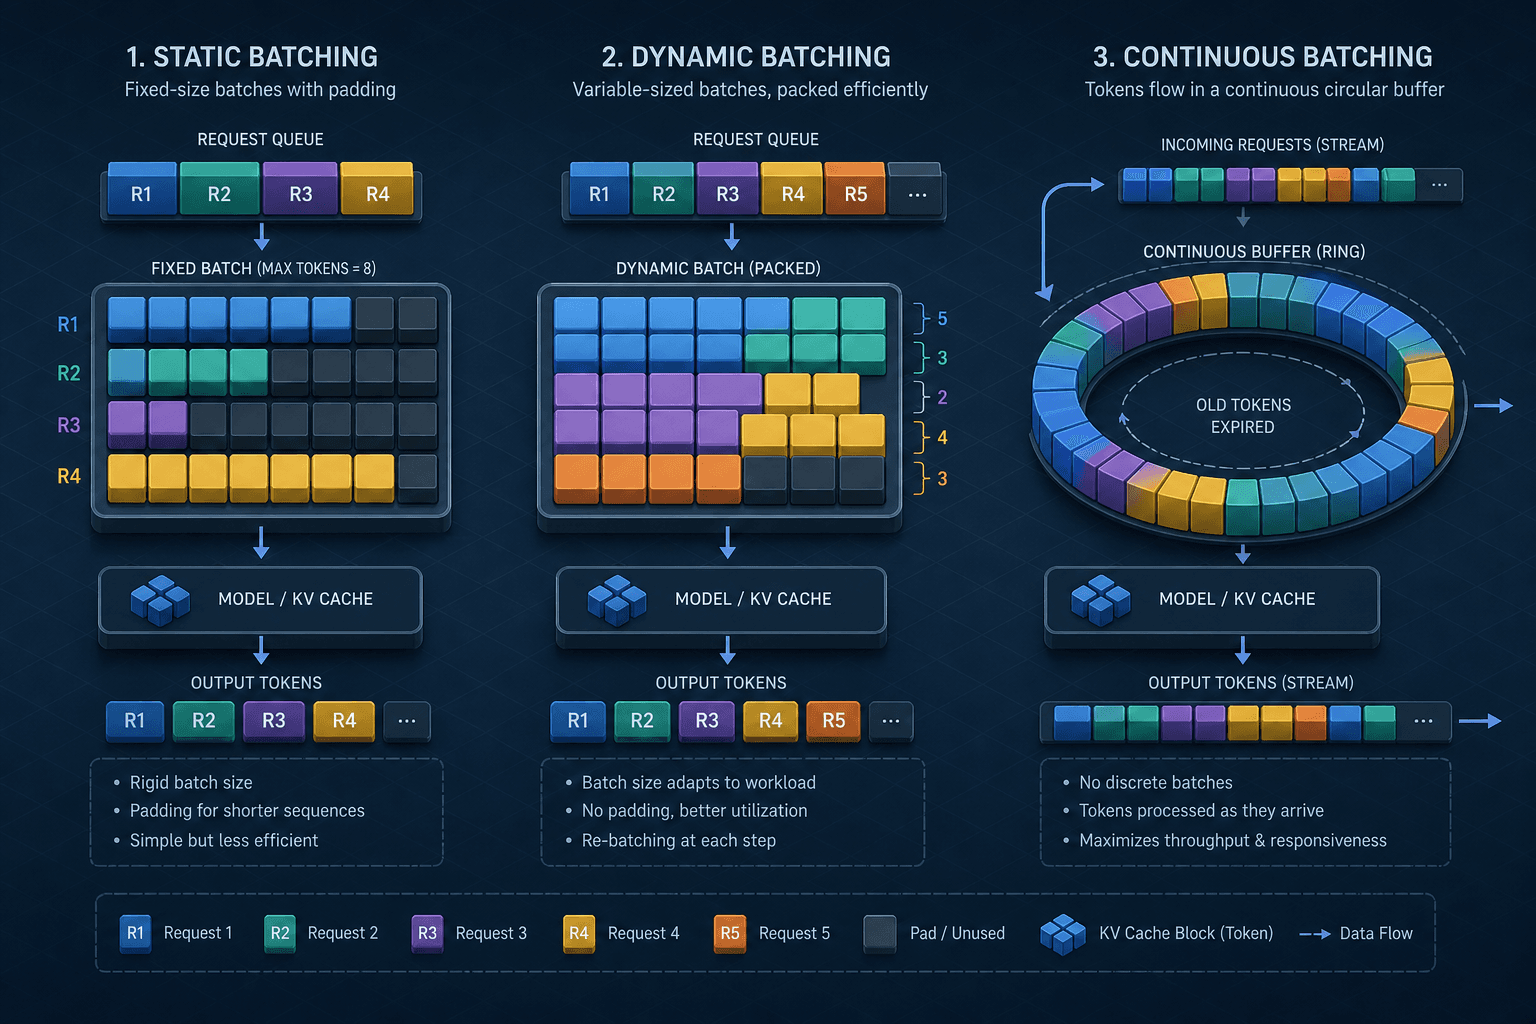
Part 4 · Production vLLMExplore how static, dynamic, and continuous batching strategies impact LLM inference performance, focusing on throughput optimization and latency reduction.
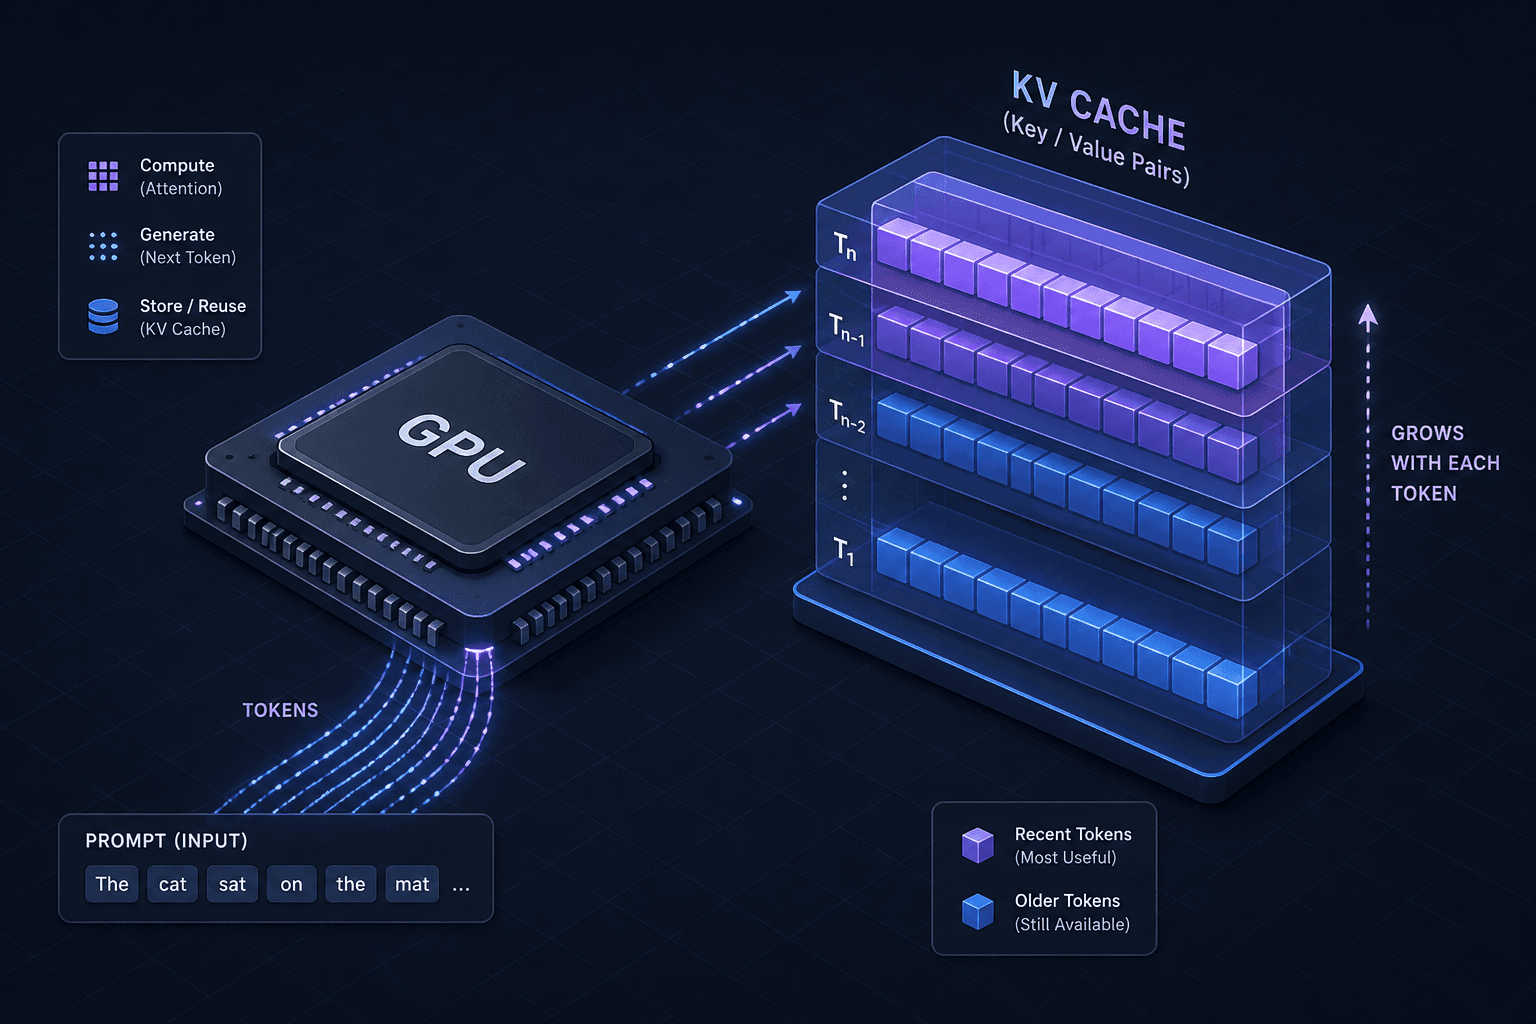
Part 5 · LLM Inference from ScratchUnderstand how the KV cache accelerates LLM inference by storing attention states, reducing redundant computation, and boosting concurrency efficiency.
Part 4 · LLM Inference from Scratch