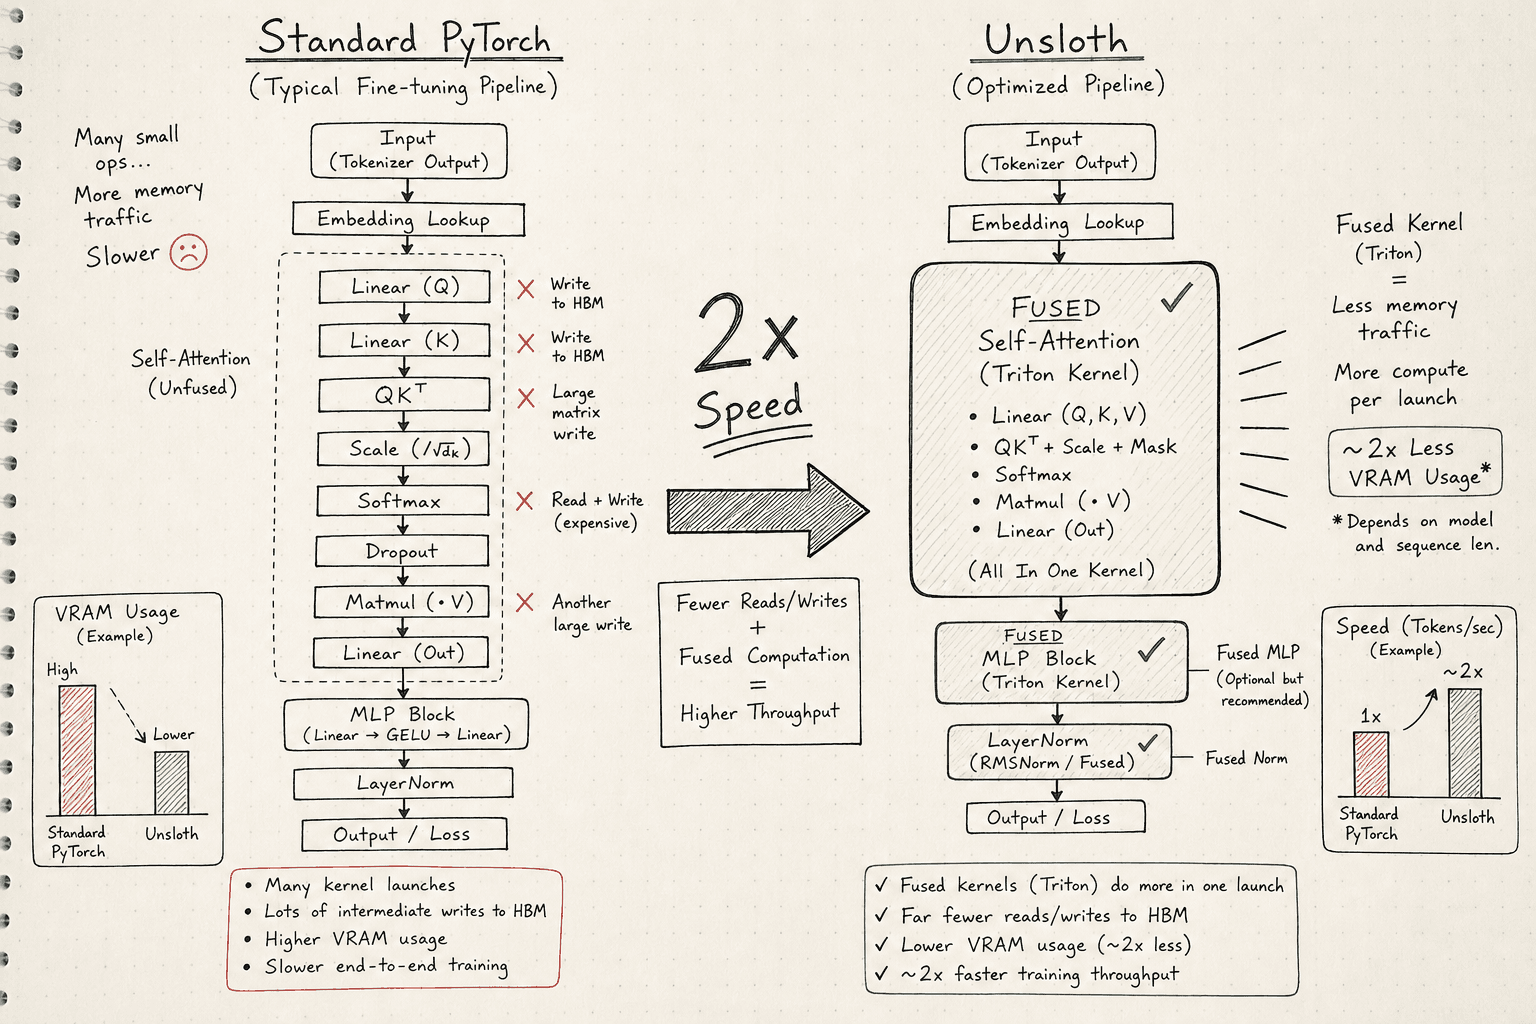
Unsloth: Fine-Tuning 2x Faster on One GPU
Discover how Unsloth leverages Triton kernels and LoRA to double fine-tuning speed, making advanced model training accessible on a single GPU.
Part 10 · Fine-Tuning LLMs Hands-OnTag
Read 6 articles on Gpu by Ashish Srivastava — practical guides covering implementation patterns, security, and production lessons.
6 posts
Discover how Unsloth leverages Triton kernels and LoRA to double fine-tuning speed, making advanced model training accessible on a single GPU.
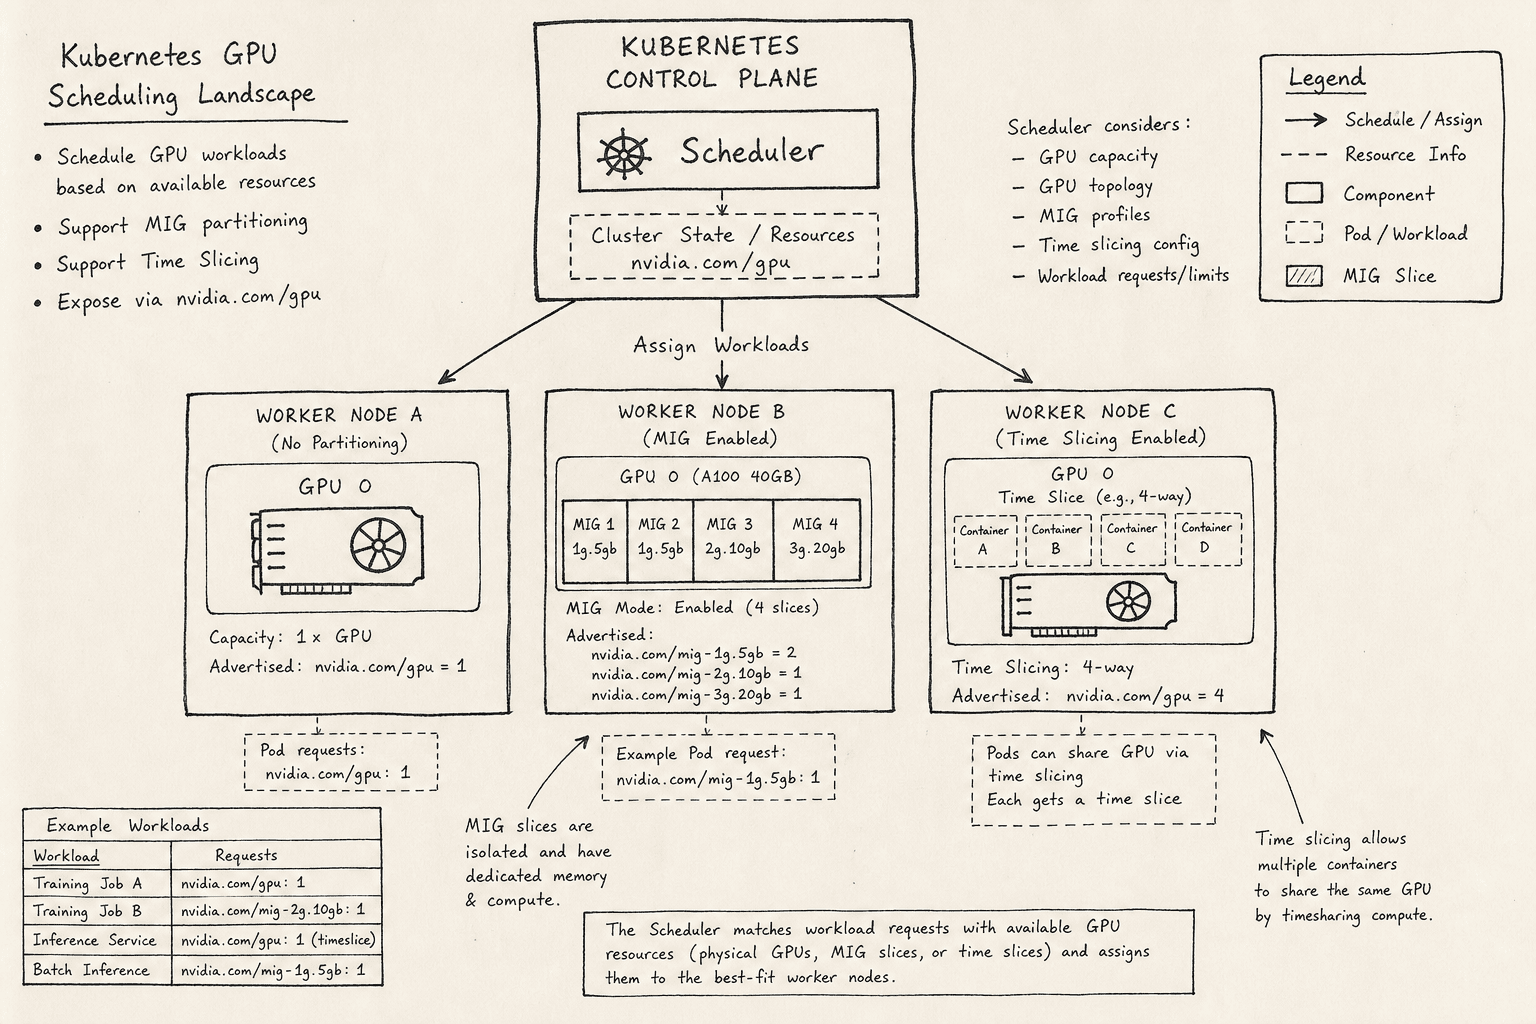
Part 10 · Fine-Tuning LLMs Hands-OnA technical guide to managing GPU workloads in Kubernetes, covering scheduling strategies, MIG, and time slicing for efficient resource utilization.
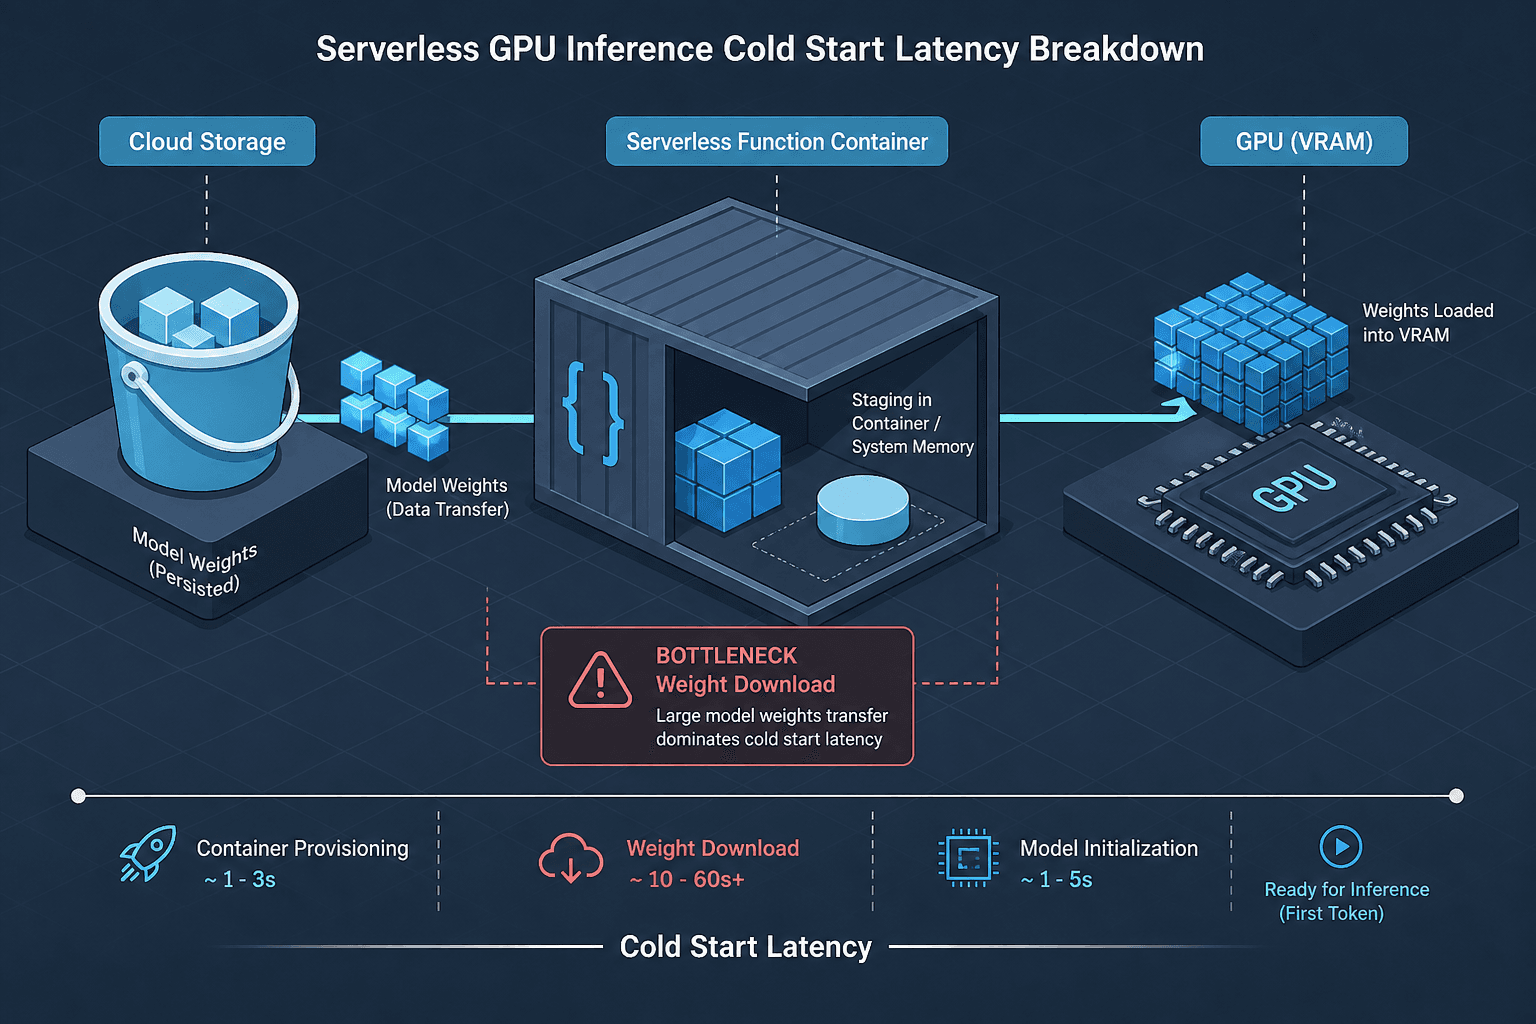
Serverless GPU inference often suffers from high latency during initialization. This article examines methods to reduce cold start times using snapshots and model streaming.
A practical comparison of spot, reserved, and serverless GPU pricing models to help platform engineers optimize AI infrastructure costs.
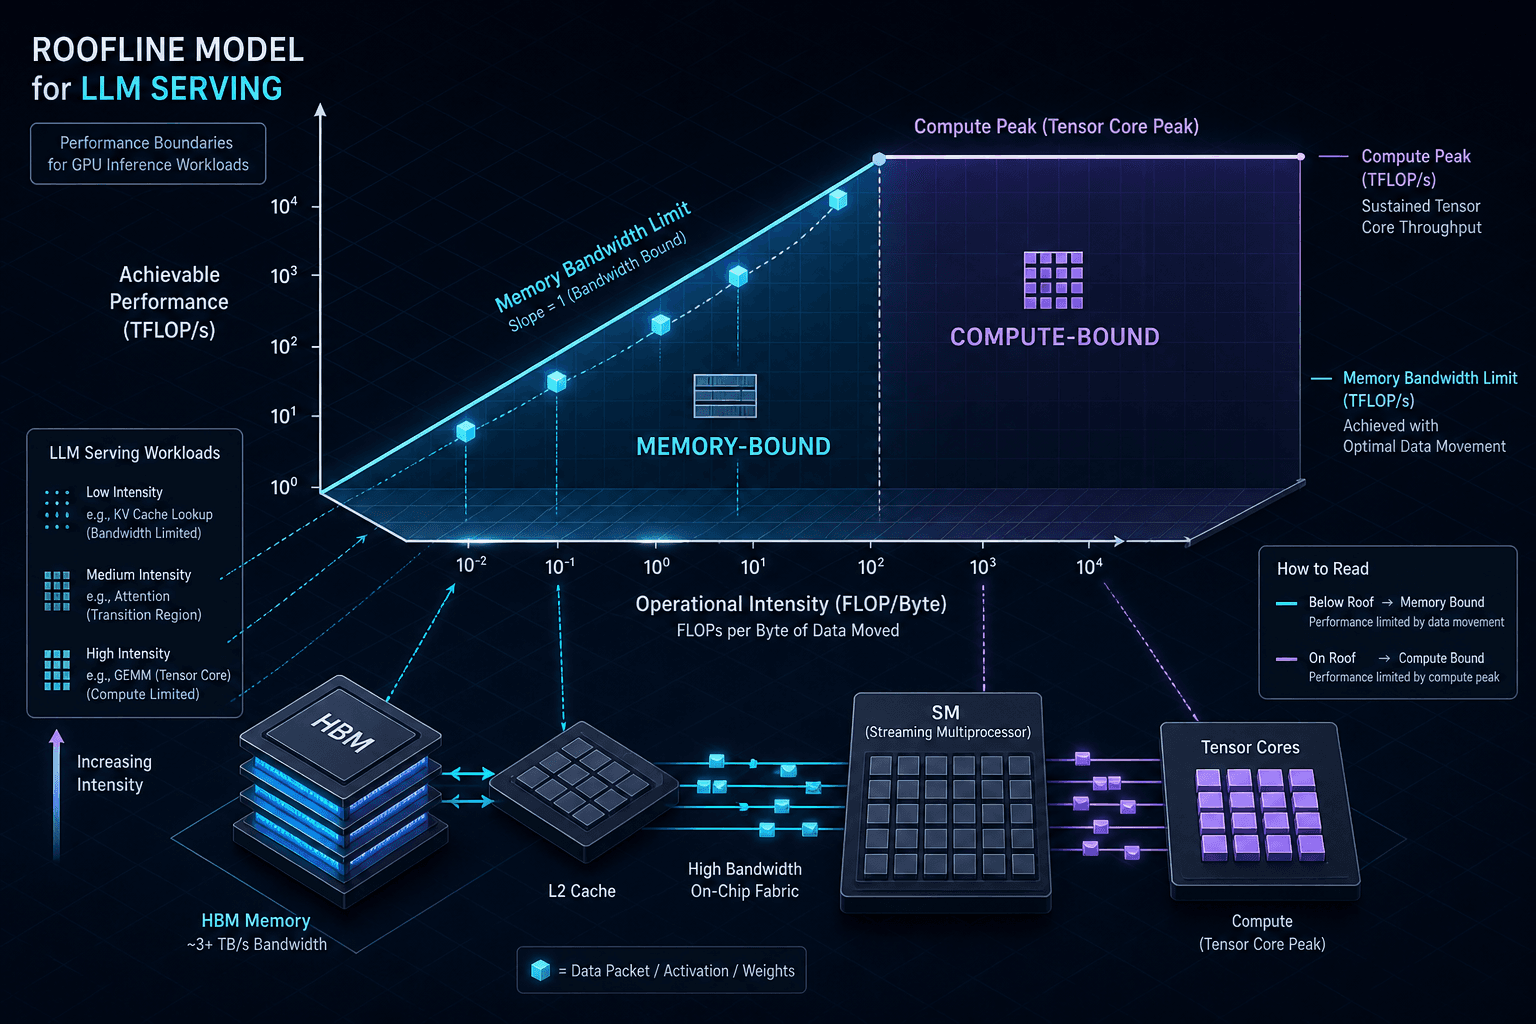
Part 4 · GPU Economics for AI TeamsLearn how to use roofline analysis to optimize GPU utilization and measure MFU effectively in LLM serving pipelines.
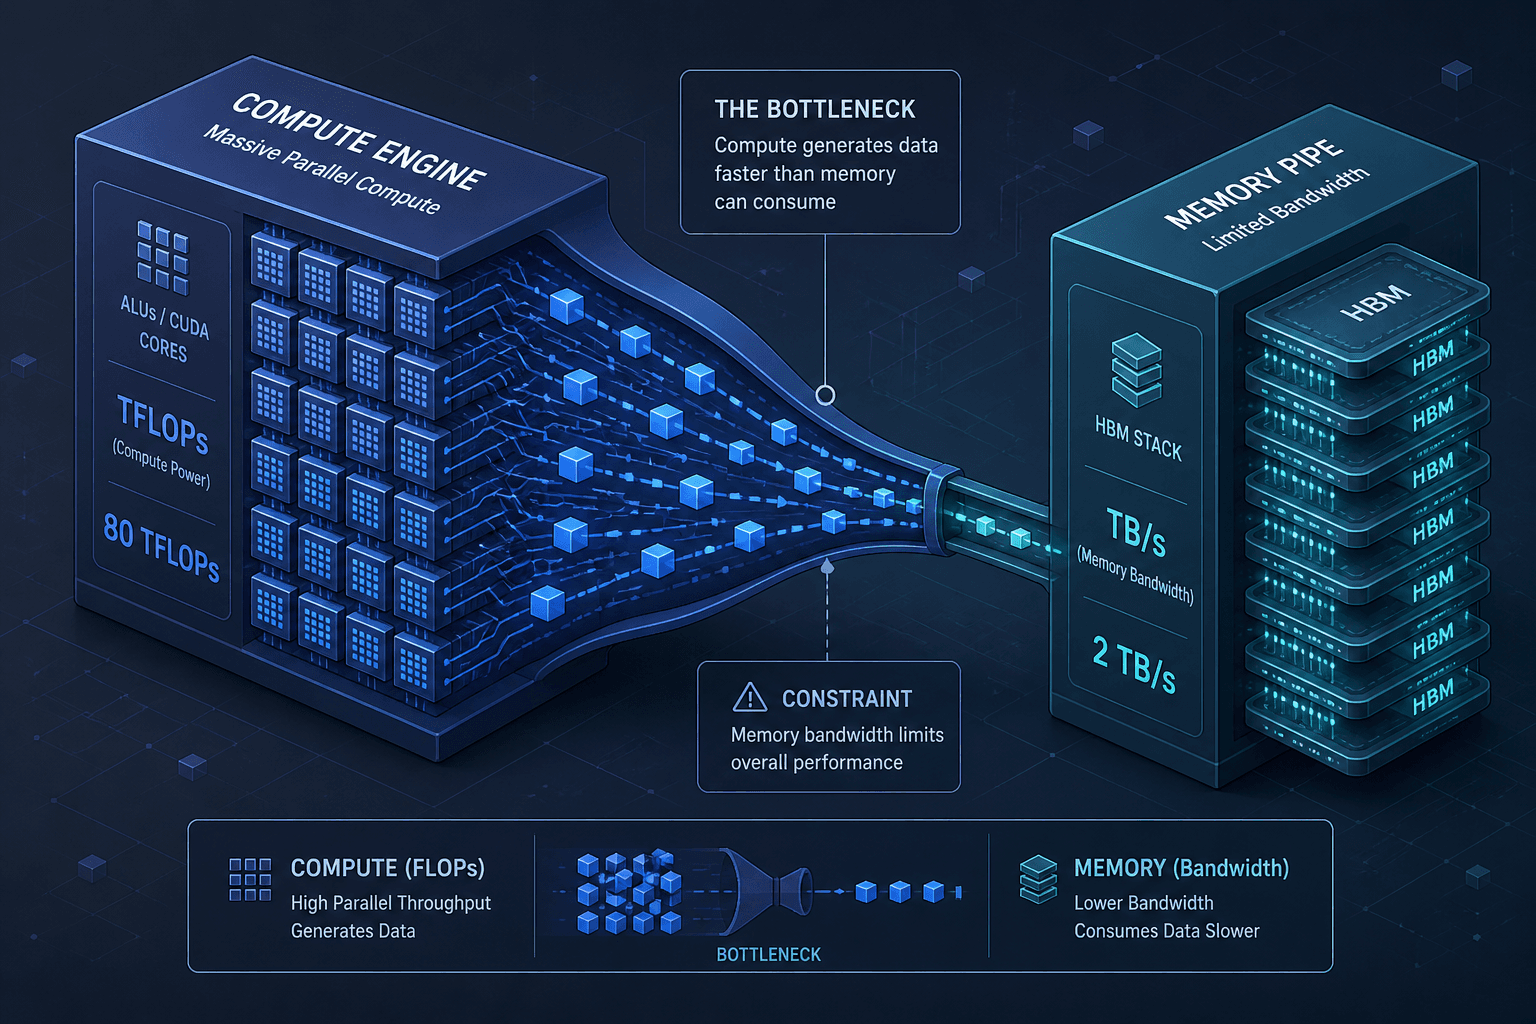
Part 2 · GPU Economics for AI TeamsStop guessing which GPU fits your workload. Learn to read spec sheets by understanding the relationship between compute power, memory bandwidth, and arithmetic intensity.
Part 1 · GPU Economics for AI Teams