Reading a GPU Spec Sheet: FLOPs, Bandwidth, and What Binds You
A practical guide to interpreting GPU spec sheets, focusing on FLOPs, HBM bandwidth, and arithmetic intensity to identify performance bottlenecks.
When an AI infrastructure engineer picks a GPU, the most common mistake is looking at the first number on a gpu spec sheet: TFLOPs. It is intuitive. If Model A offers 1000 TFLOPs and Model B offers 500 TFLOPs, Model A should be twice as fast, right?
This intuition is fundamentally flawed because it ignores the physical reality of data movement. Modern GPUs are not just calculators; they are complex systems where moving data from memory to compute units often costs more time than the calculation itself. To choose correctly, you must stop thinking in terms of raw speed and start thinking in terms of bottlenecks.
The Illusion of Peak FLOPs
Let’s look at a hypothetical spec sheet. A GPU lists "FP16 Precision: 1000 TFLOPs." This number represents the theoretical maximum number of floating-point operations the hardware can perform per second if every single core is active, every instruction is perfectly pipelined, and no time is wasted waiting for data.
In practice, this peak is a mirage.
Consider the mechanism of a single Streaming Multiprocessor (SM) in an NVIDIA GPU. It contains multiple CUDA cores, tensor cores, and registers. To achieve peak FLOPs, the SM must have a continuous stream of instructions ready to execute. However, two things regularly interrupt this flow:
- Instruction Latency: If a thread waits for a branch prediction or a complex instruction, the SM must switch to another thread (warp scheduling) to hide the latency. If there are no other threads ready, the cores sit idle.
- Cache Misses: If the data needed for a calculation isn’t in the fast L1/L2 cache, the SM must wait for it to arrive from global memory. This stall can last hundreds of cycles.
Therefore, peak FLOPs is only relevant for "Compute-Bound" workloads—tasks where the algorithm is so mathematically dense that the GPU spends all its time calculating, never waiting. Most modern AI workloads, particularly inference, are not compute-bound. They are bound by something else entirely.
For a deeper dive into SM architecture and warp scheduling, refer to the NVIDIA CUDA C++ Programming Guide.
The Memory Wall: HBM Bandwidth
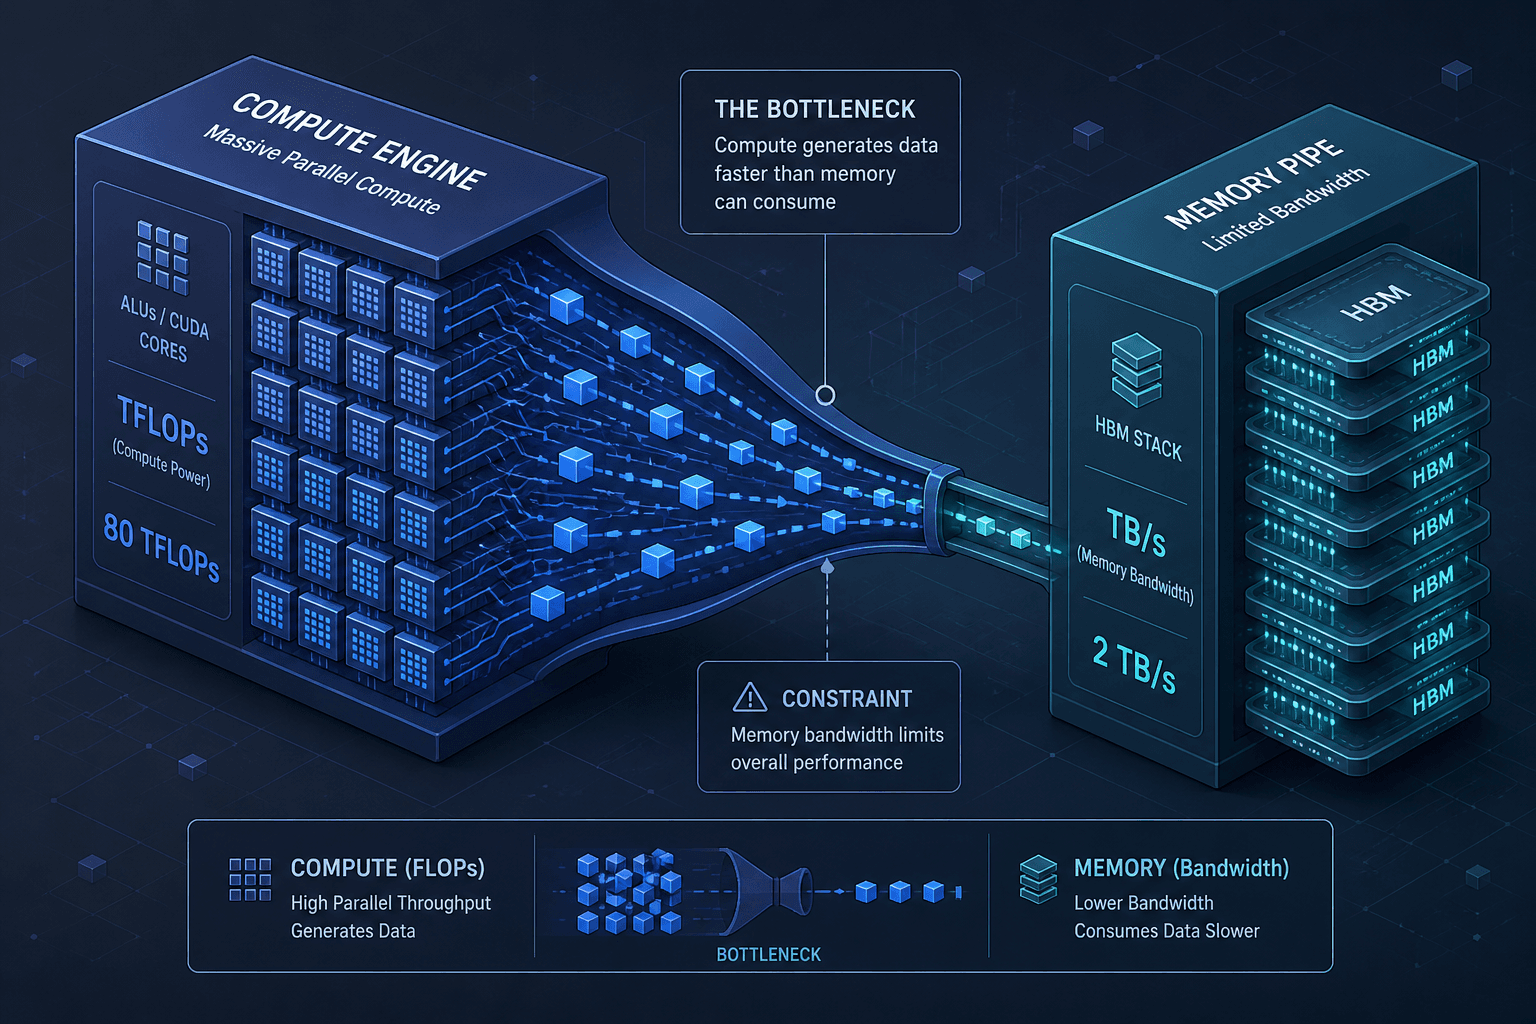
If FLOPs represent the speed of the engine, Memory Bandwidth represents the size of the fuel line. For Large Language Models (LLMs) and massive datasets, the fuel line is almost always too narrow.
High-End GPUs use HBM (High Bandwidth Memory), stacked vertically next to the GPU die. This reduces the physical distance data must travel. Let’s compare two architectures:
- GPU A: 1000 TFLOPs FP16, 2 TB/s Bandwidth.
- GPU B: 500 TFLOPs FP16, 4 TB/s Bandwidth.
Which is faster for loading a 10GB model checkpoint? GPU B. Even though it has half the compute power, it can move the data twice as fast. If your model weights fit in memory but are too large to compute instantly, the time spent reading the weights dominates the total execution time.
This is the "Memory Wall." As model sizes grow (70B, 175B, 1T parameters), the time required to fetch weights from HBM to the tensor cores exceeds the time required to multiply them. When this happens, increasing FLOPs yields zero performance gain. You are "Memory Bound."
For technical specifications on HBM3 and HBM3e, see the JEDEC JESD239C standard and NVIDIA's A100/Tensor Core Technical Whitepaper.
Arithmetic Intensity: The Diagnostic Tool
So, how do you know if your workload is Compute-Bound or Memory-Bound? You calculate Arithmetic Intensity.
Arithmetic Intensity (AI) is defined as the ratio of floating-point operations performed per byte of data moved from memory.
Let’s build a concrete scenario. Imagine you are performing a matrix multiplication for a Transformer layer.
Scenario: A Single Forward Pass
- Input Matrix Size: 4096 x 4096 (FP16, 2 bytes per element)
- Weight Matrix Size: 4096 x 4096 (FP16, 2 bytes per element)
- Output Matrix Size: 4096 x 4096 (FP16, 2 bytes per element)
- Total Data Moved: We read Input and Weights, we write Output.
- Read: bytes + bytes = $67,108,864$ bytes (~64 MB)
- Write: bytes = $33,554,432$ bytes (~32 MB)
- Total Bytes: ~96 MB
- Total Operations: A standard GEMM (General Matrix Multiply) performs 2 FLOPs per element pair (one multiply, one add). For an matrix, this is FLOPs.
- FLOPs (~137 GFLOPs)
Now, look at the hardware.
-
GPU A: 2 TB/s Bandwidth, 1000 TFLOPs Compute.
- Peak AI Limit (Bandwidth Bound): FLOPs/Byte.
- Peak AI Limit (Compute Bound): Infinite (theoretically).
- Since our workload AI (1431) > Hardware Peak AI (500), this GPU is Compute Bound. Memory bandwidth can supply data faster than the cores can consume it, so the GPU can approach its full 1000 TFLOPs.
-
GPU C (Consumer Card): 0.5 TB/s Bandwidth, 50 TFLOPs Compute.
- Peak AI Limit: $50 / 0.5 = 100$ FLOPs/Byte.
- Since our workload AI (1431) > Hardware Peak AI (100), this GPU is also Compute Bound. It will be limited by its lower compute throughput rather than by memory bandwidth.
This mechanism explains why a dense, large-batch matrix multiplication like this one is compute-bound on both cards, whereas workloads with much lower arithmetic intensity — such as single-token LLM decoding, which reuses weights across only one example at a time — remain memory-bound even on the highest-bandwidth cards.
Practical Application: Choosing the Right Silicon
When evaluating spec sheets, apply this filter:
- Estimate your Arithmetic Intensity. For LLM inference, the arithmetic intensity is extremely low because you are primarily loading weights and doing a single pass of addition/multiplication. The AI is often < 10 FLOPs/Byte for very small batches, but even at larger batch sizes, it rarely exceeds the bandwidth limits of consumer cards.
- Check the Bandwidth. If your AI is low, you need high bandwidth. Look for HBM3 or HBM3e. Ignore the TFLOPs rating; it is irrelevant if the memory pipe is clogged.
- Check the Compute. If you are doing heavy pre-training or fine-tuning with large batch sizes, your arithmetic intensity increases. Here, TFLOPs matter more. However, even in training, memory bandwidth remains critical for feeding the compute units.
The Trade-off Opinion: It is tempting to buy the GPU with the highest TFLOPs because marketing drives this number. But in 2024, for most production LLM workloads, memory bandwidth is the harder constraint. A GPU with 2000 TFLOPs but only 1 TB/s bandwidth will perform worse than a GPU with 1000 TFLOPs and 3 TB/s bandwidth for any model larger than the L2 cache.
Stop guessing. Calculate your FLOPs/Byte. Match the bottleneck. That is how you engineer for efficiency.
Conclusion
Understanding the relationship between FLOPs and memory bandwidth is critical for selecting the right hardware for your AI workload. By calculating arithmetic intensity, you can determine whether your application is compute-bound or memory-bound, allowing you to make informed decisions that optimize performance and cost.
Common Pitfalls
- Confusing peak FLOPs with sustained performance: Peak FLOPs are measured under ideal laboratory conditions. Real-world performance is often 10-30% of peak due to memory latency, kernel launch overhead, and non-optimal code.
- Ignoring memory bandwidth for large models: As model sizes exceed GPU memory capacity, swapping becomes necessary, but even when models fit, the sheer volume of weight data makes bandwidth the primary bottleneck for inference.
- Assuming higher TFLOPs always means faster inference: Higher compute power does not help if the GPU is starved of data. A lower-TFLOP card with significantly higher bandwidth will outperform a high-TFLOP card in memory-bound scenarios.
Practical Takeaways
- Calculate AI before buying: Don't rely on marketing numbers. Estimate your workload's arithmetic intensity and compare it to the hardware's peak bandwidth limit.
- Bandwidth > FLOPs for inference: For most LLM inference tasks, prioritize GPUs with HBM3/HBM3e over those with slightly higher FP16 TFLOPs but lower bandwidth.
- Check HBM generation: HBM2e, HBM3, and HBM3e offer vastly different bandwidth profiles. Ensure the GPU generation matches your bandwidth requirements.
FAQ
What is arithmetic intensity? Arithmetic intensity is the ratio of floating-point operations (FLOPs) performed per byte of data moved from memory. It is the key metric for determining whether a workload is compute-bound or memory-bound.
Why is bandwidth more important than FLOPs for LLMs? LLM inference involves loading large weight matrices and performing relatively simple mathematical operations (matmul/add) per token. This results in low arithmetic intensity, meaning the GPU spends most of its time waiting for data rather than computing. Therefore, memory bandwidth becomes the limiting factor.
How do I calculate my workload's AI? To calculate arithmetic intensity, determine the total number of FLOPs performed during a forward pass and divide by the total bytes of data read from and written to memory during that pass. For standard matrix multiplication, this is FLOPs divided by the memory footprint of the input, weight, and output matrices.
Related posts
Spot, Reserved, or Serverless GPUs: Picking a Capacity Strategy
Compare spot, reserved, and serverless GPU options to build an effective capacity planning strategy for AI teams.
Unsloth: Fine-Tuning 2x Faster on One GPU
Learn how Unsloth accelerates fine-tuning by 2x using Triton kernels and LoRA, enabling efficient model training on a single GPU.
Kubernetes GPU Management: Beyond Passthrough
Explore Kubernetes GPU scheduling, MIG, and time slicing to optimize resource sharing for platform engineers and SREs.
