6 min readDevelopmentFeatured
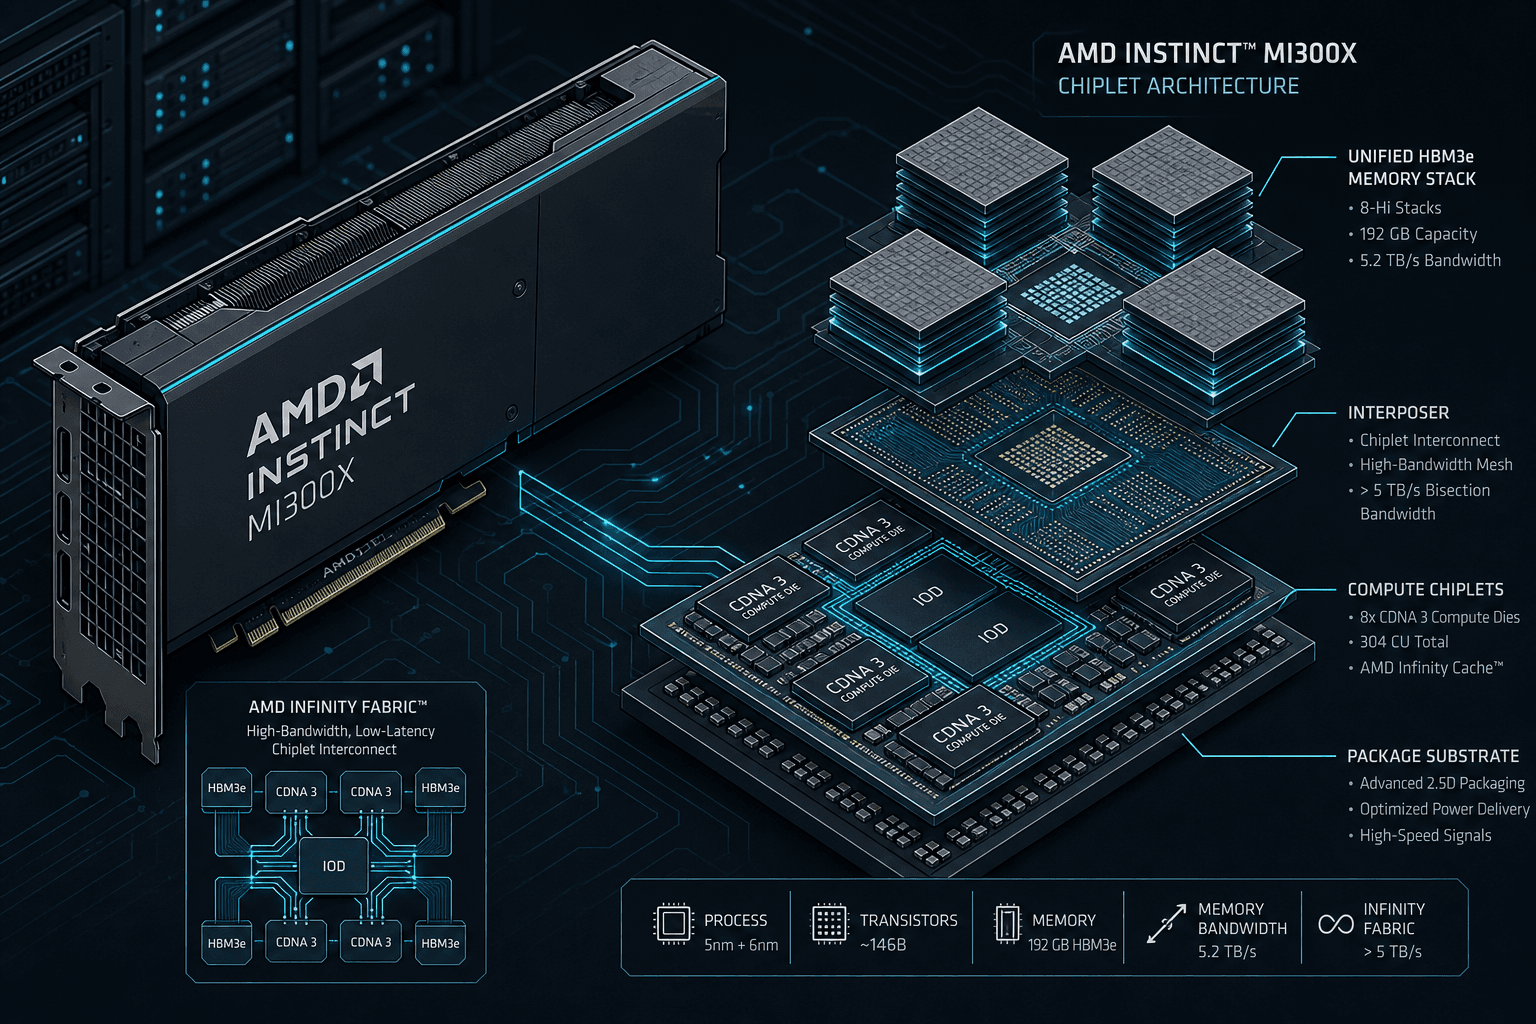
Running LLM Inference on AMD MI300X: A Field Report
An in-depth look at deploying large language models on AMD's MI300X hardware using ROCm and vLLM, with benchmark results.
Tag
Read 2 articles on Hardware by Ashish Srivastava — practical guides covering implementation patterns, security, and production lessons.
2 posts
An in-depth look at deploying large language models on AMD's MI300X hardware using ROCm and vLLM, with benchmark results.
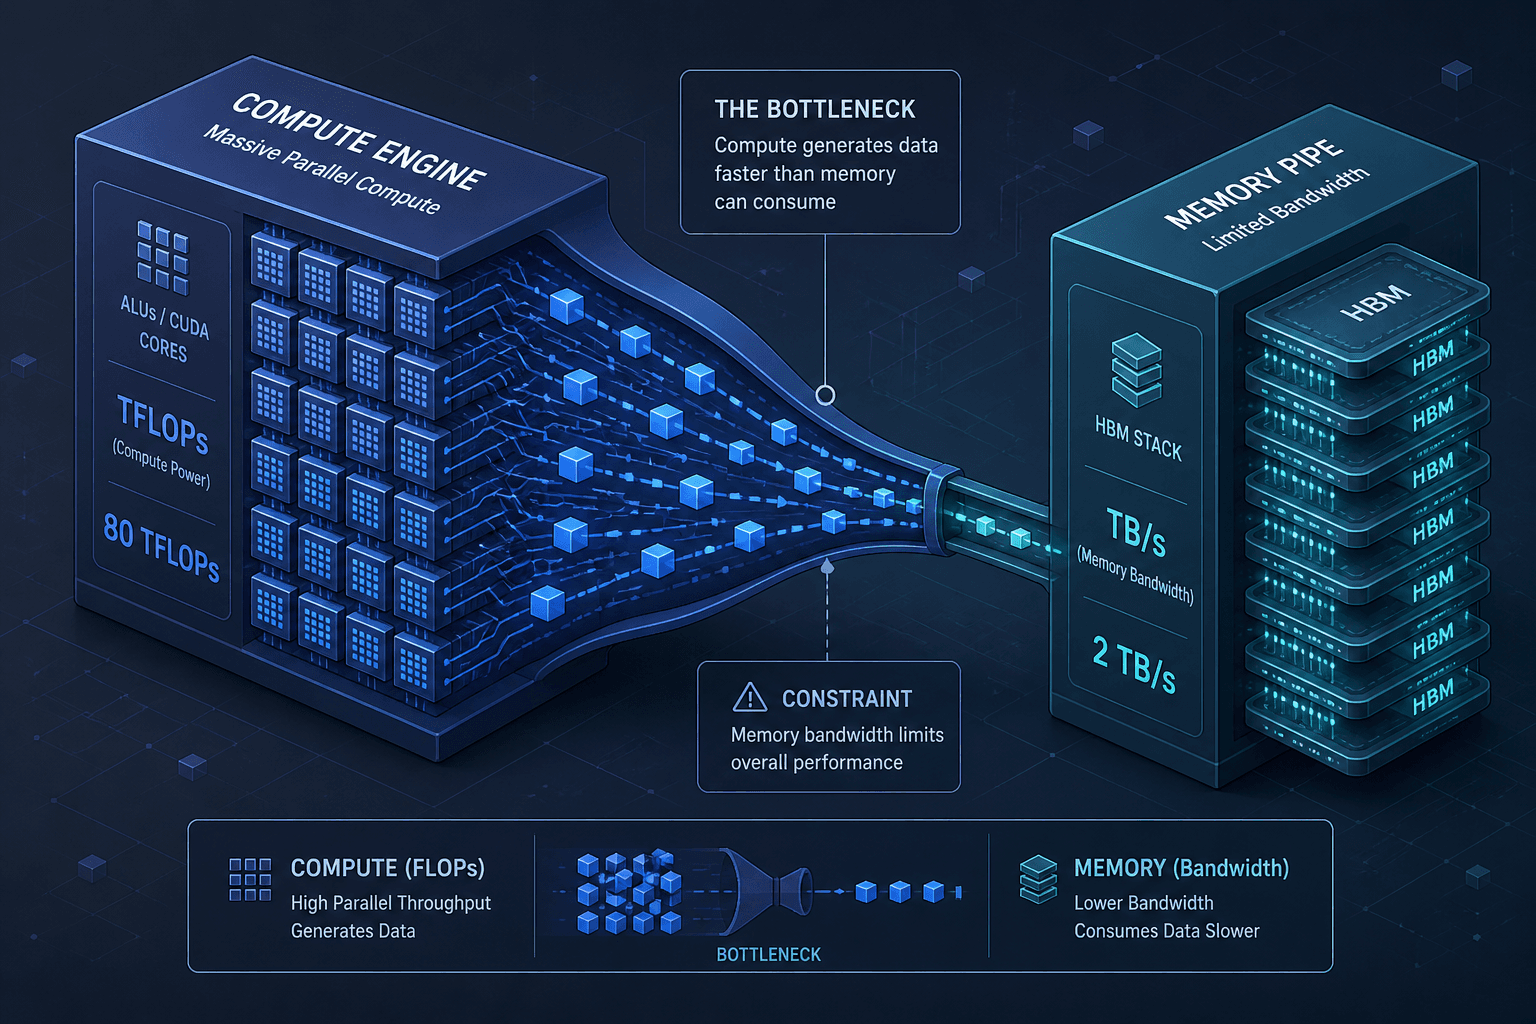
Stop guessing which GPU fits your workload. Learn to read spec sheets by understanding the relationship between compute power, memory bandwidth, and arithmetic intensity.
Part 1 · GPU Economics for AI Teams