6 min readDevelopment
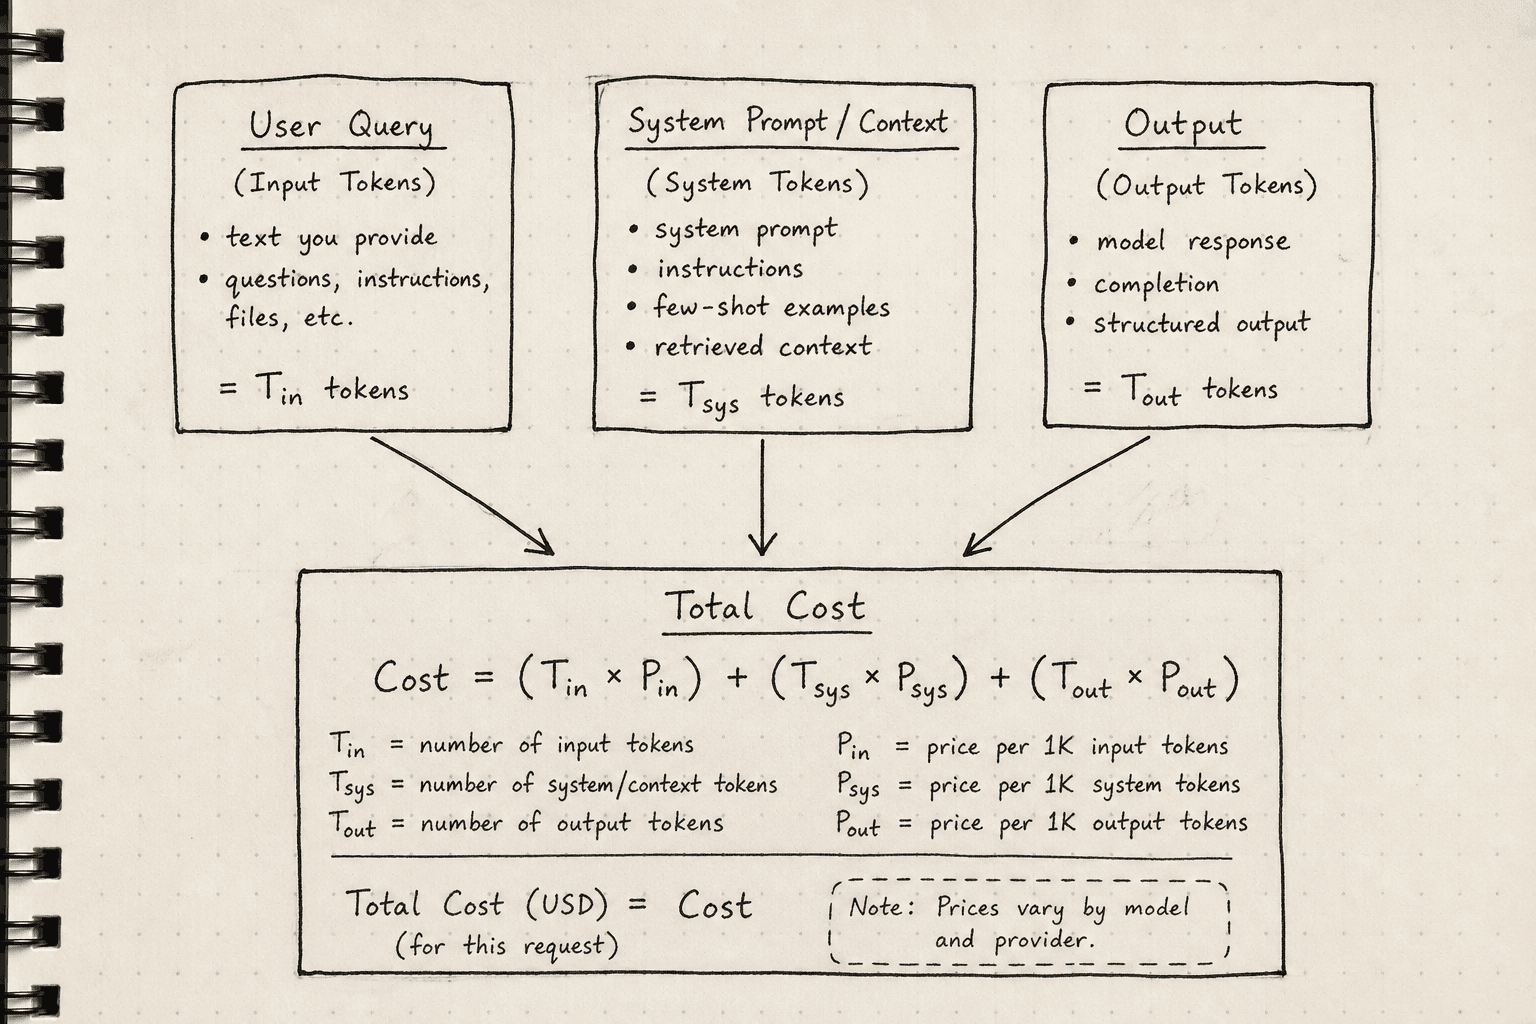
Estimating LLM Costs Before You Build
Learn how to accurately forecast LLM expenses before development begins. This guide covers unit economics, token forecasting, and sensitivity analysis for engineering leaders.
Tag
Read 9 articles on Ai Infrastructure by Ashish Srivastava — practical guides covering implementation patterns, security, and production lessons.
9 posts
Learn how to accurately forecast LLM expenses before development begins. This guide covers unit economics, token forecasting, and sensitivity analysis for engineering leaders.
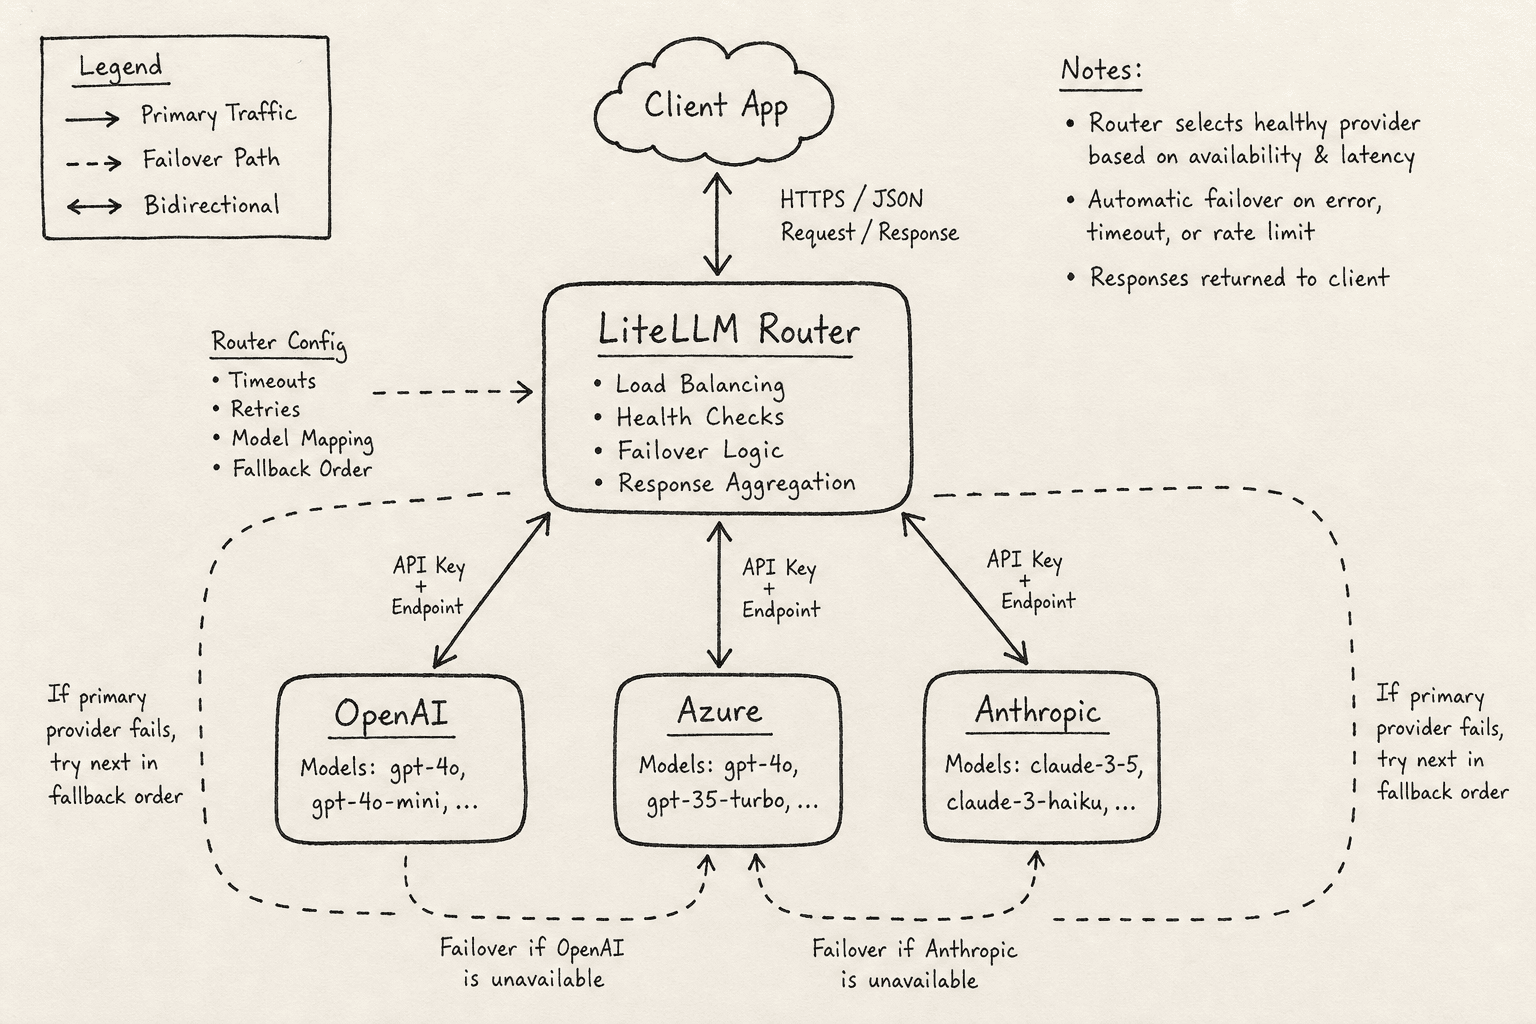
Learn how to configure LiteLLM's router for automatic failover across multiple AI providers, ensuring high availability and resilience for your backend applications.
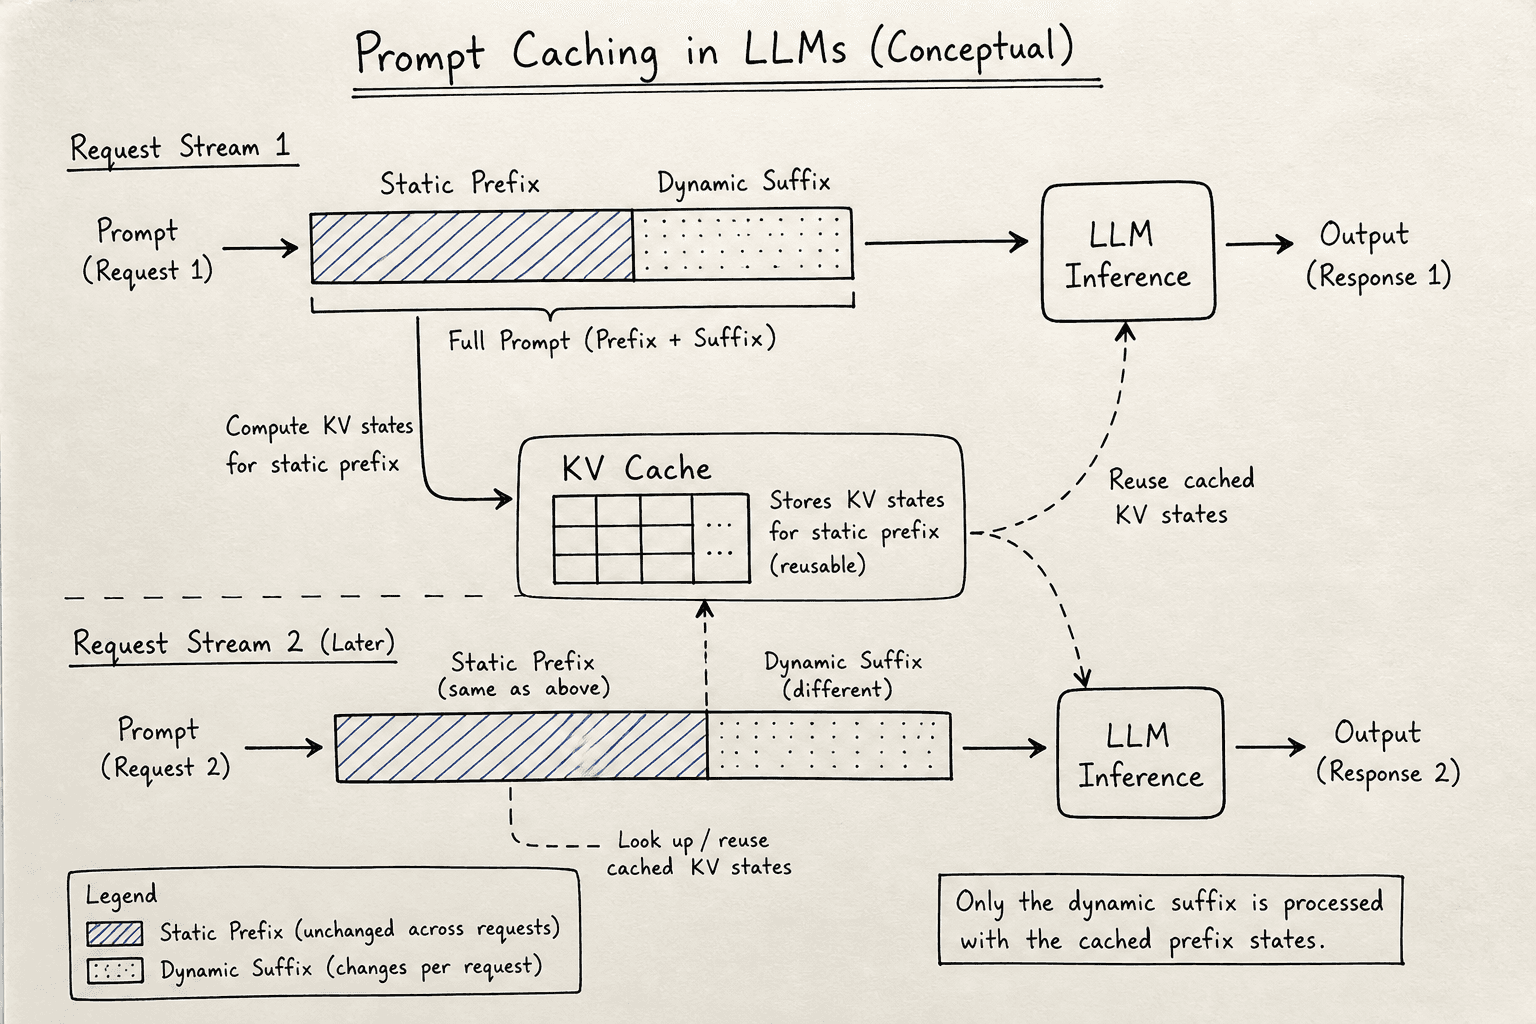
Explore how different AI providers handle prompt caching, including cache TTL limits, cost implications, and prefix matching techniques to optimize API usage.
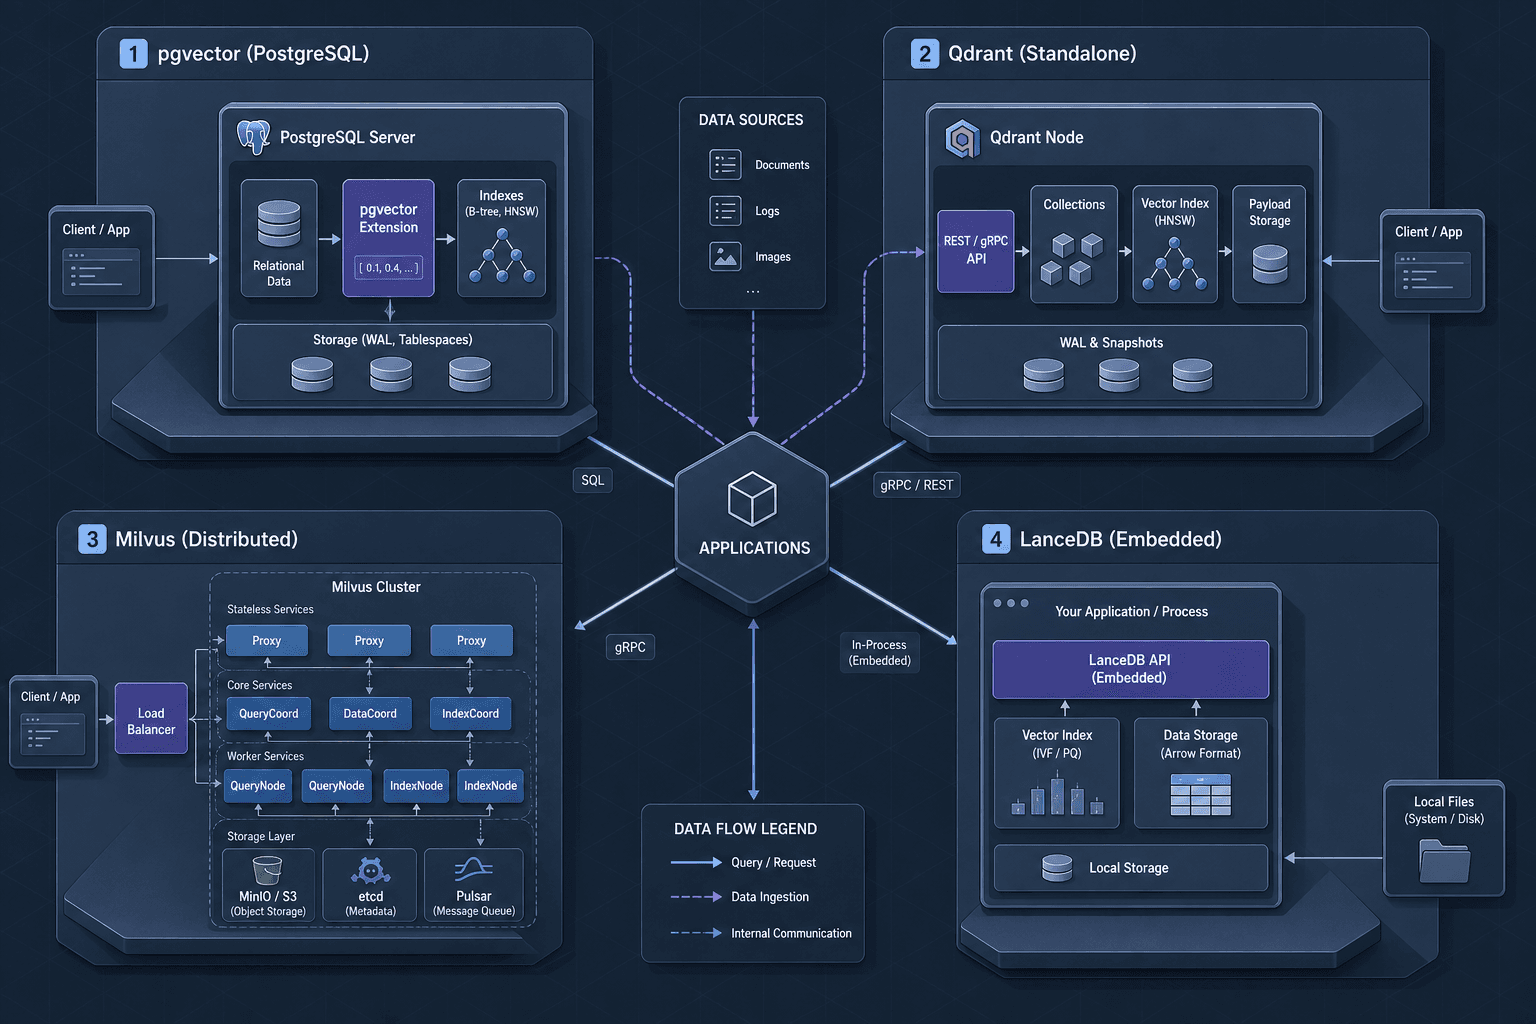
Analyze the strengths and trade-offs of pgvector, Qdrant, Milvus, and LanceDB to select the right vector database for your RAG architecture.
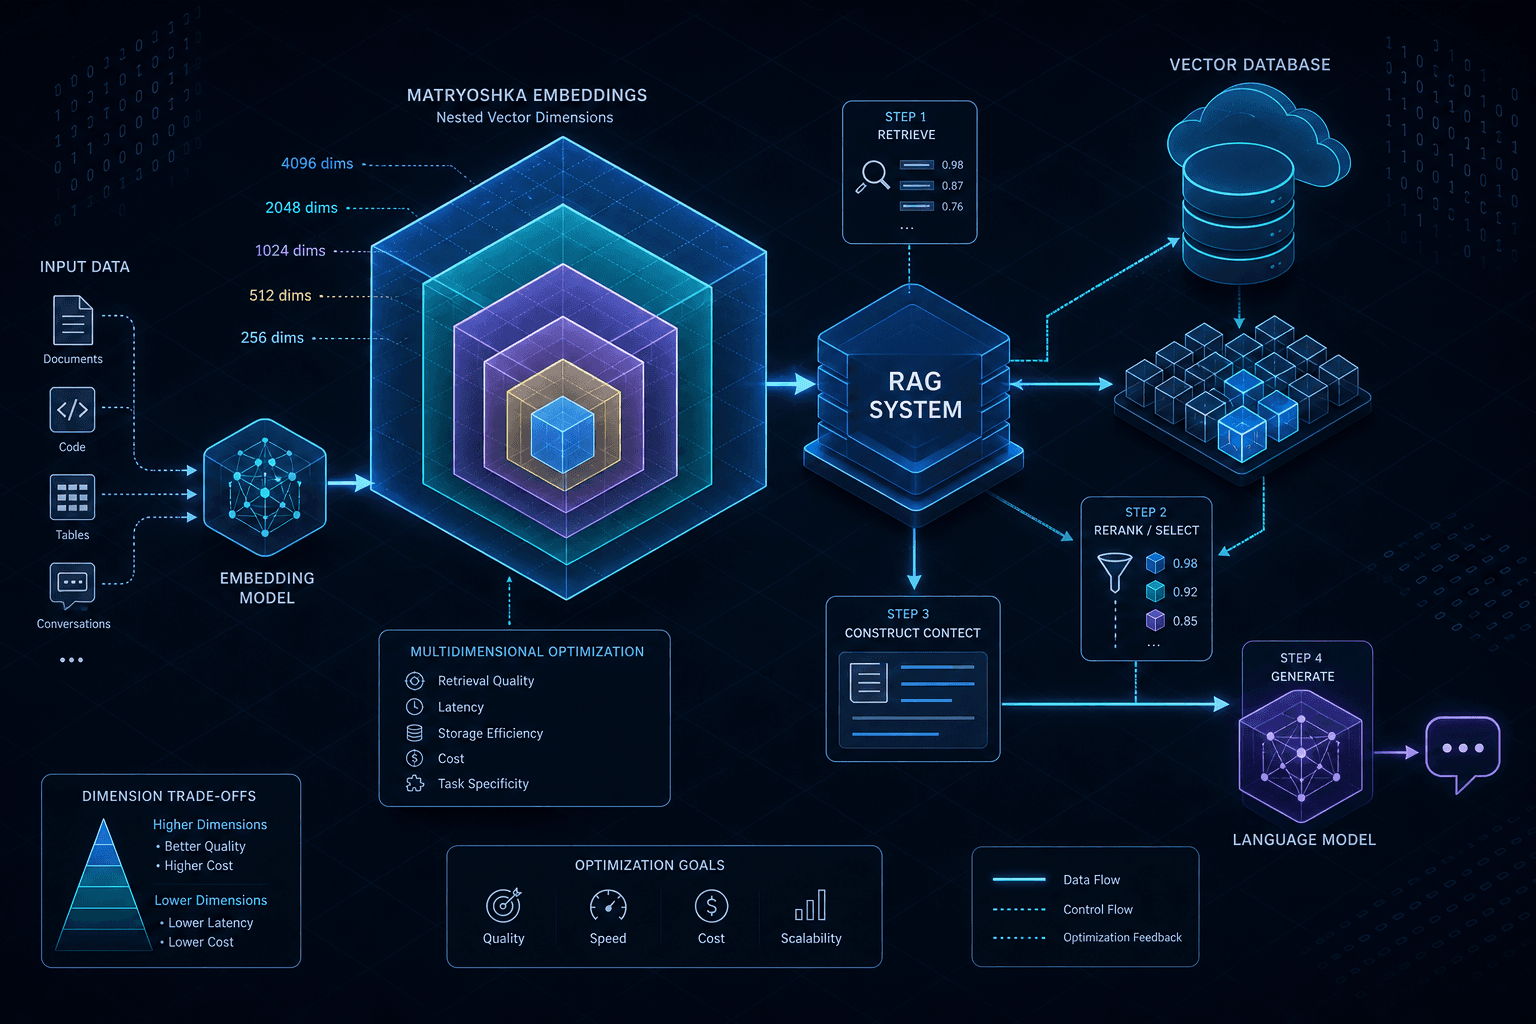
Part 4 · RAG from Zero to ProductionNavigate the 2026 landscape of embedding models. Learn how to evaluate MTEB scores, leverage Matryoshka dimensions, and handle multilingual data for production RAG.
Part 3 · RAG from Zero to ProductionA practical comparison of spot, reserved, and serverless GPU pricing models to help platform engineers optimize AI infrastructure costs.
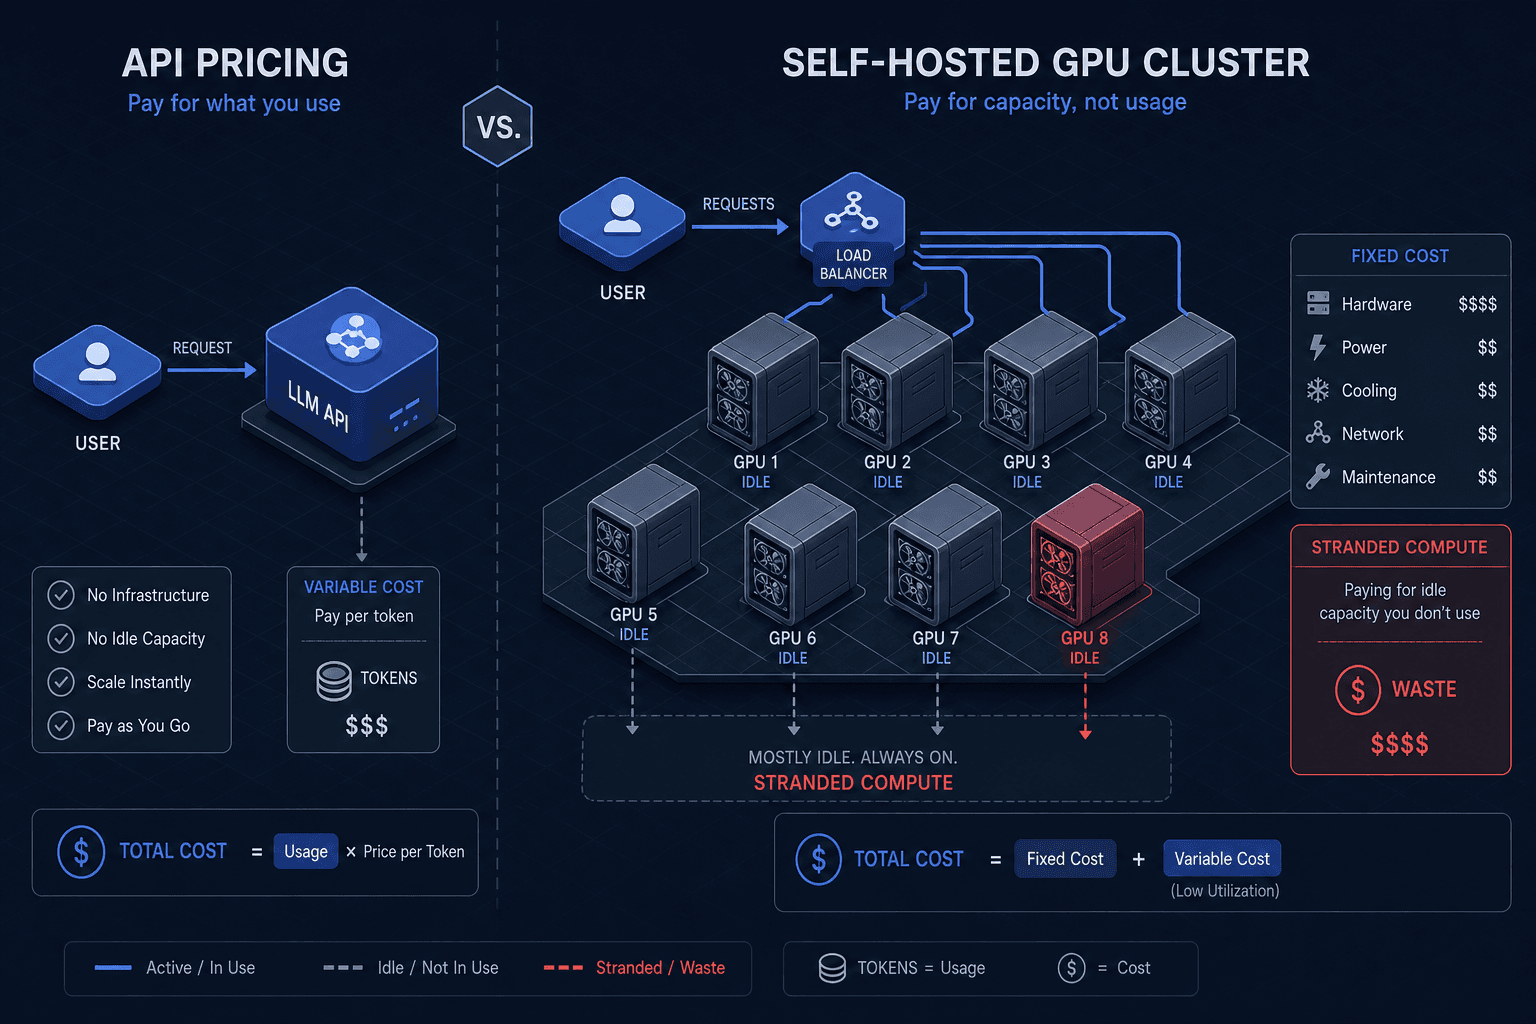
Part 4 · GPU Economics for AI TeamsStop guessing your AI infrastructure spend. This guide breaks down the real math behind cost per million tokens, GPU efficiency, and total cost of ownership for self-hosted models.
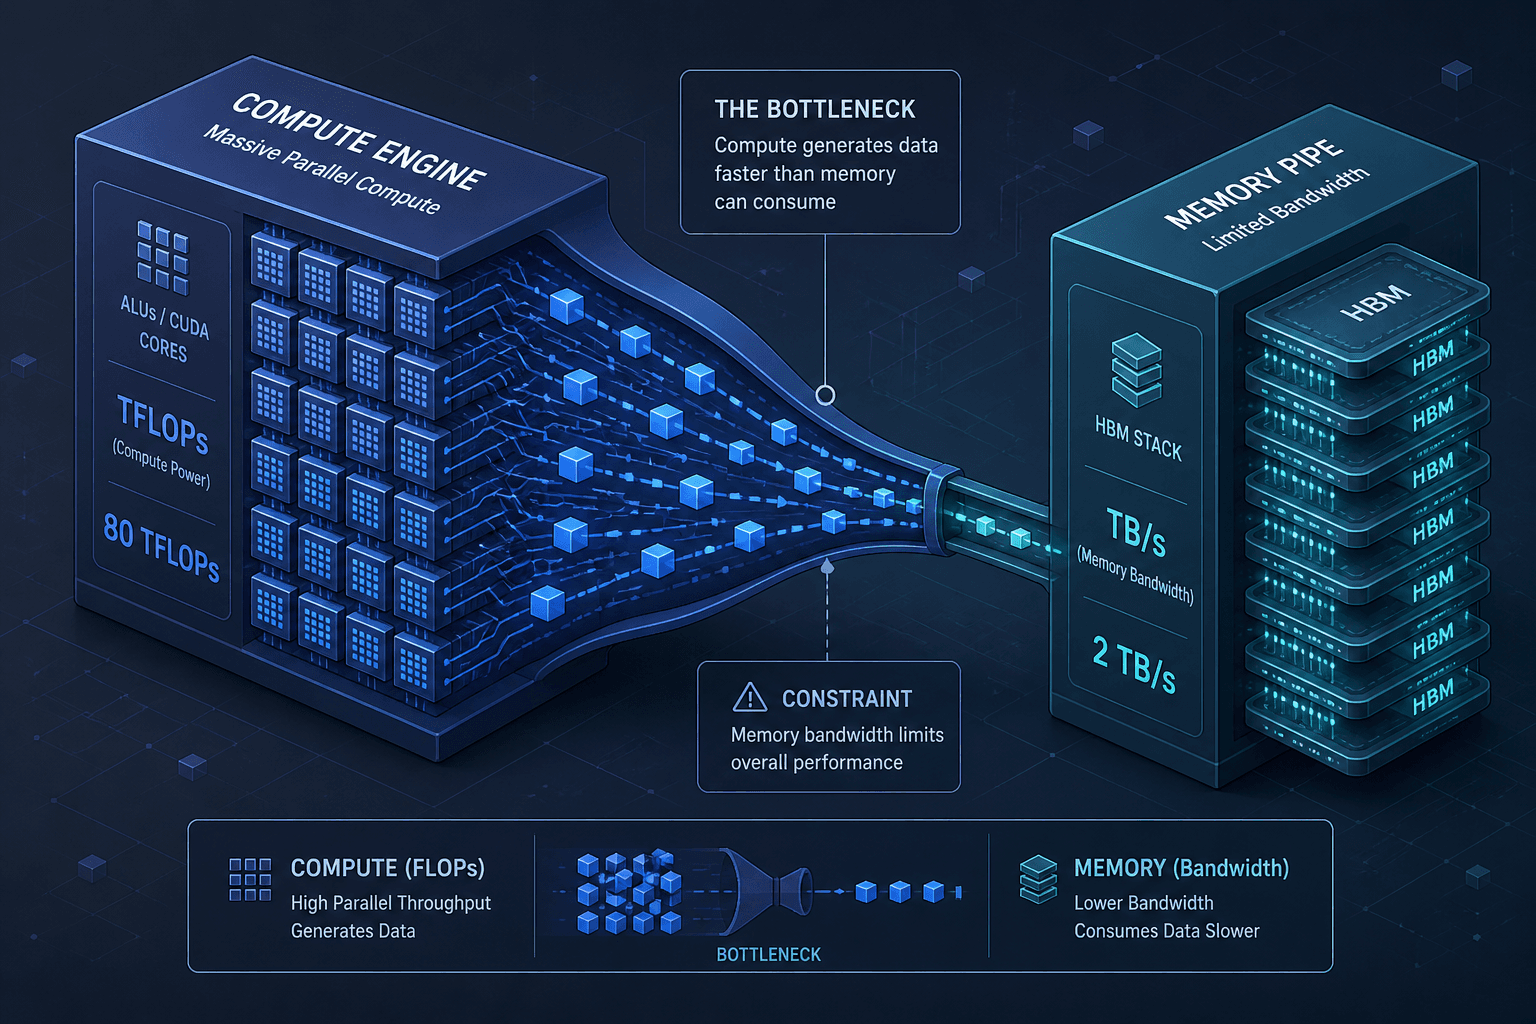
Part 3 · GPU Economics for AI TeamsStop guessing which GPU fits your workload. Learn to read spec sheets by understanding the relationship between compute power, memory bandwidth, and arithmetic intensity.
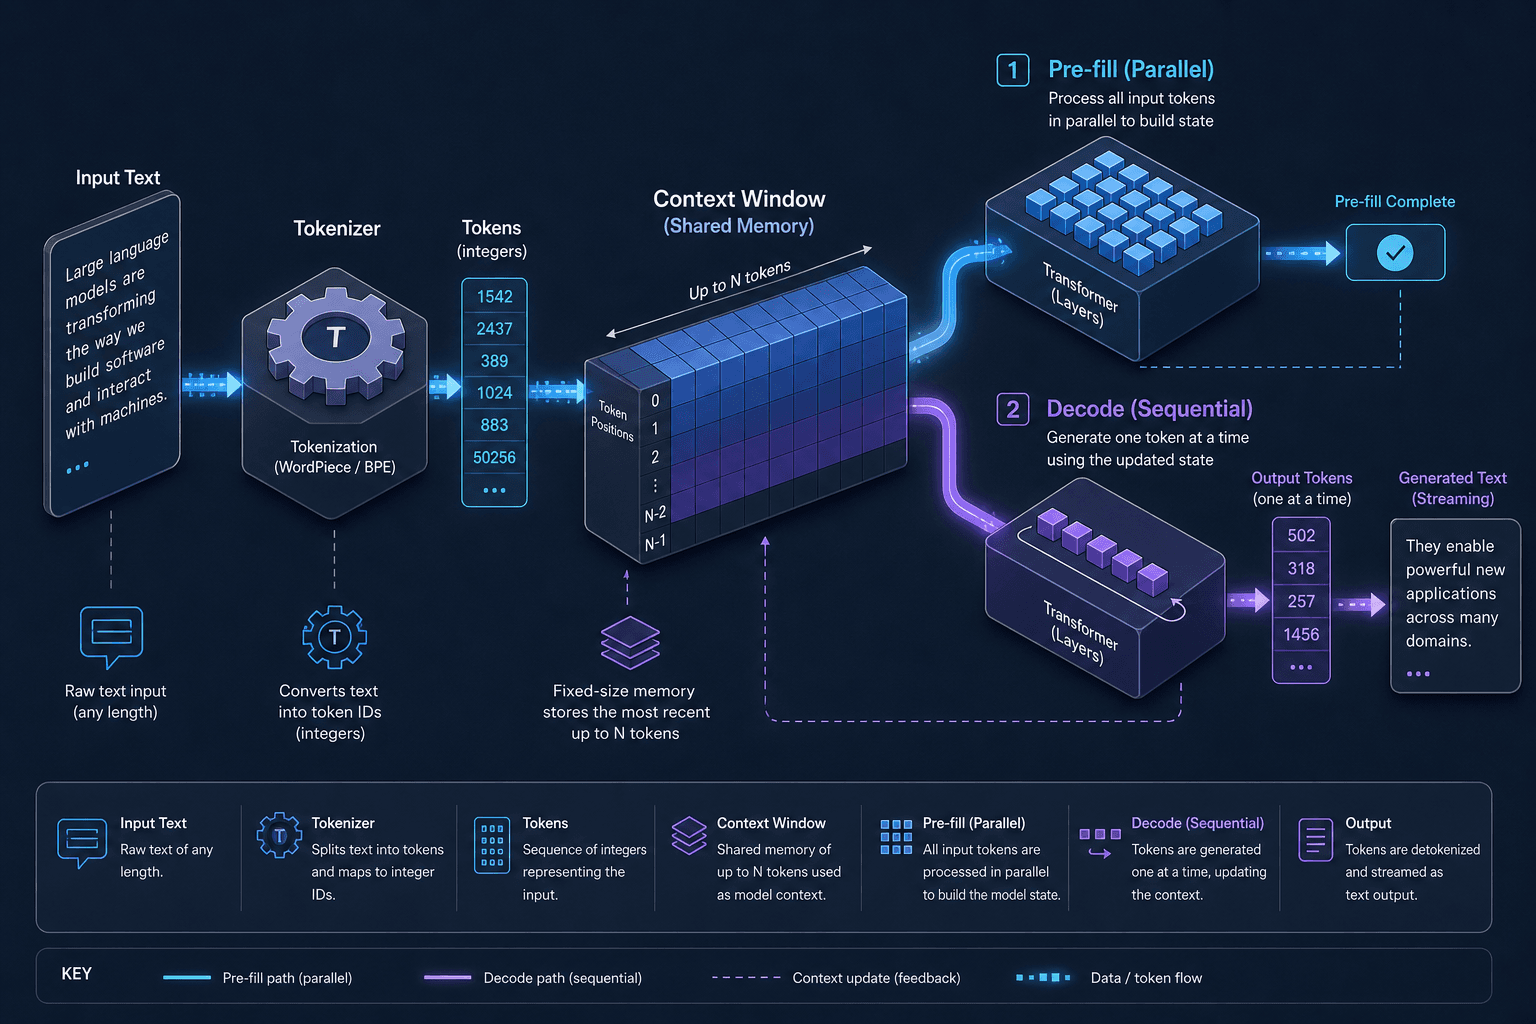
Part 1 · GPU Economics for AI TeamsA technical breakdown of tokens, context windows, and tokenizer mechanics to explain LLM pricing structures.
Part 2 · LLM Inference from Scratch