6 min readDevelopmentFeatured
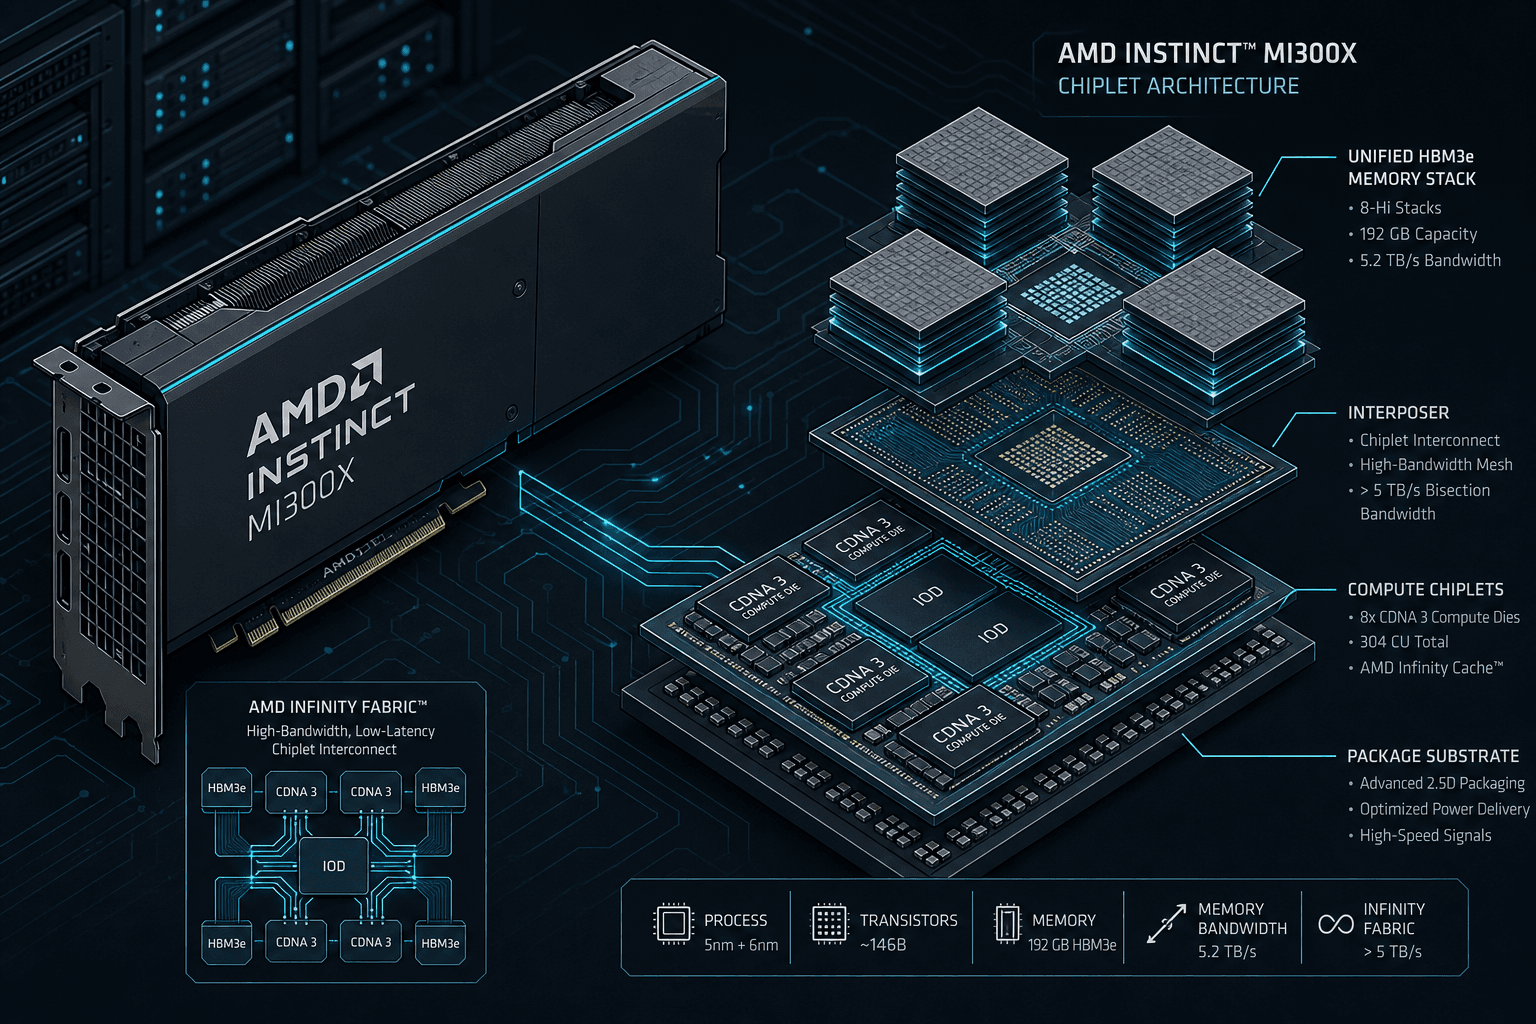
Running LLM Inference on AMD MI300X: A Field Report
An in-depth look at deploying large language models on AMD's MI300X hardware using ROCm and vLLM, with benchmark results.
Tag
Read 9 articles on Vllm by Ashish Srivastava — practical guides covering implementation patterns, security, and production lessons.
9 posts
An in-depth look at deploying large language models on AMD's MI300X hardware using ROCm and vLLM, with benchmark results.
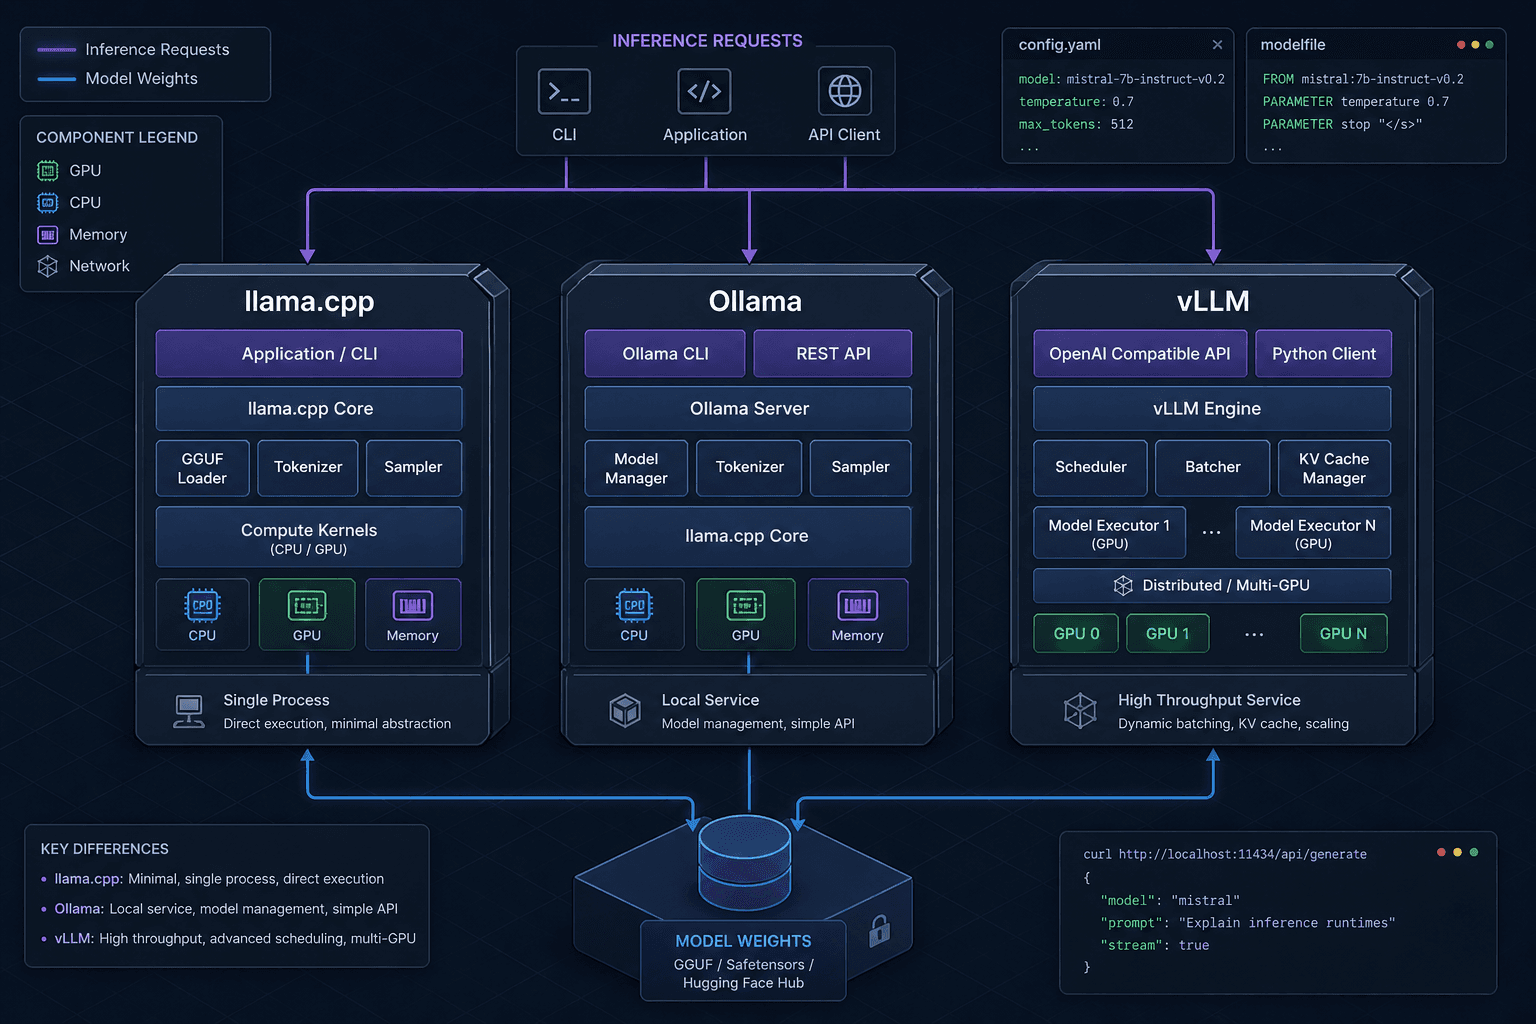
Compare Ollama, vLLM, and llama.cpp to choose the best inference runtime for your specific development or engineering needs.
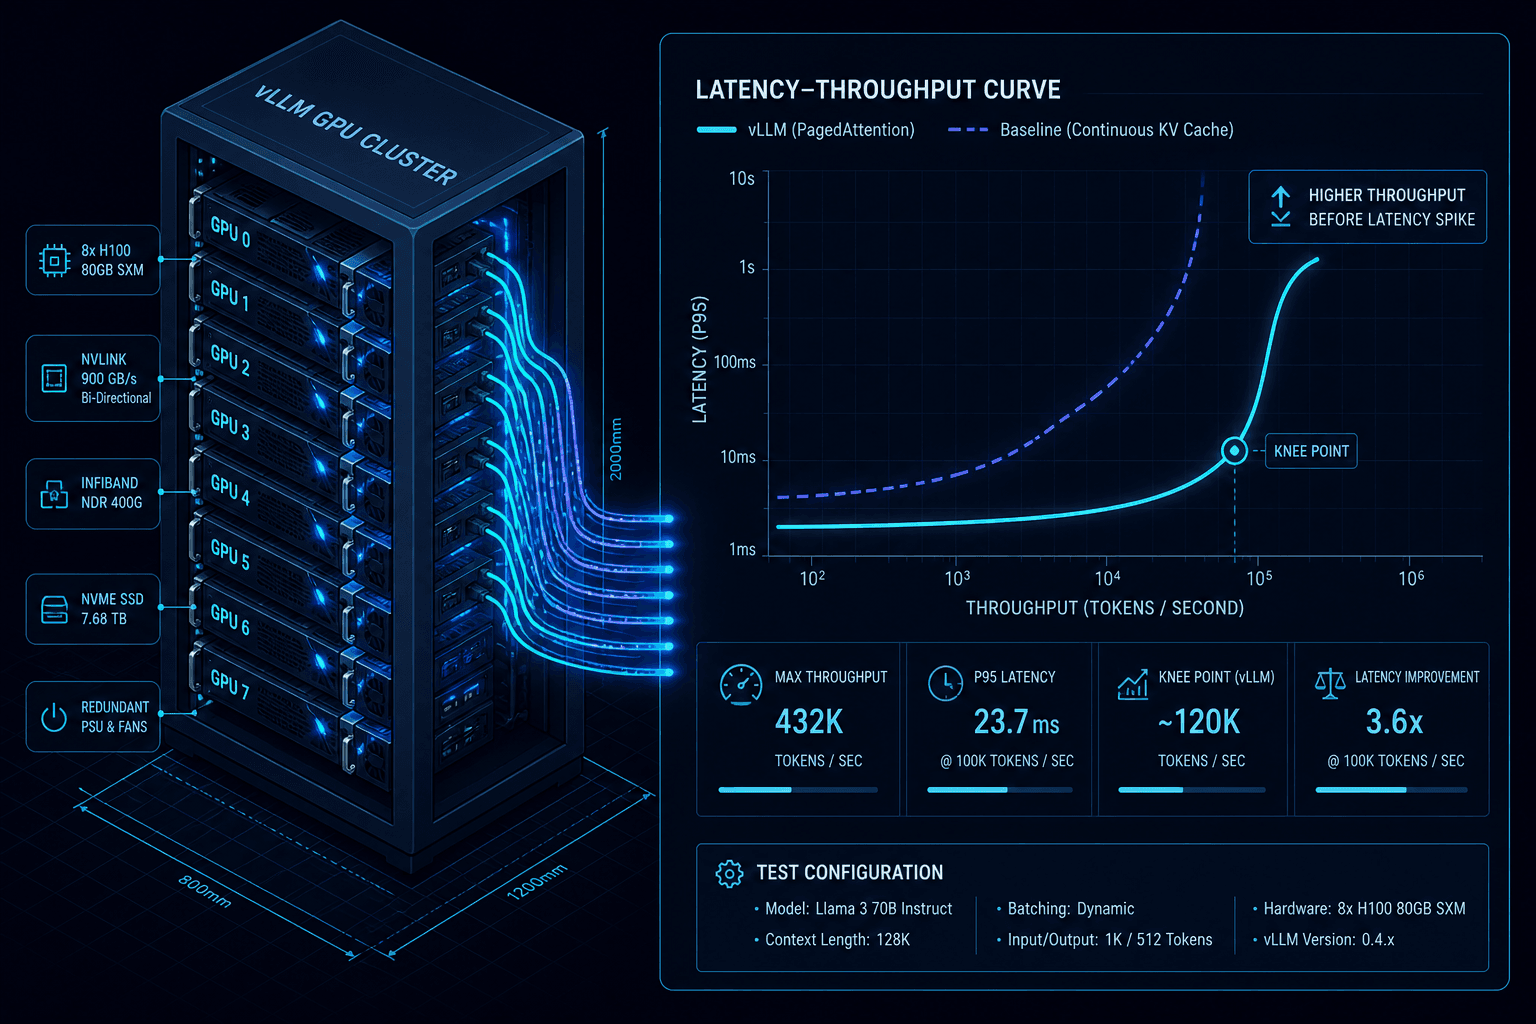
Learn how to effectively benchmark and load-test your vLLM deployment. This guide covers throughput, latency curves, and capacity planning strategies.
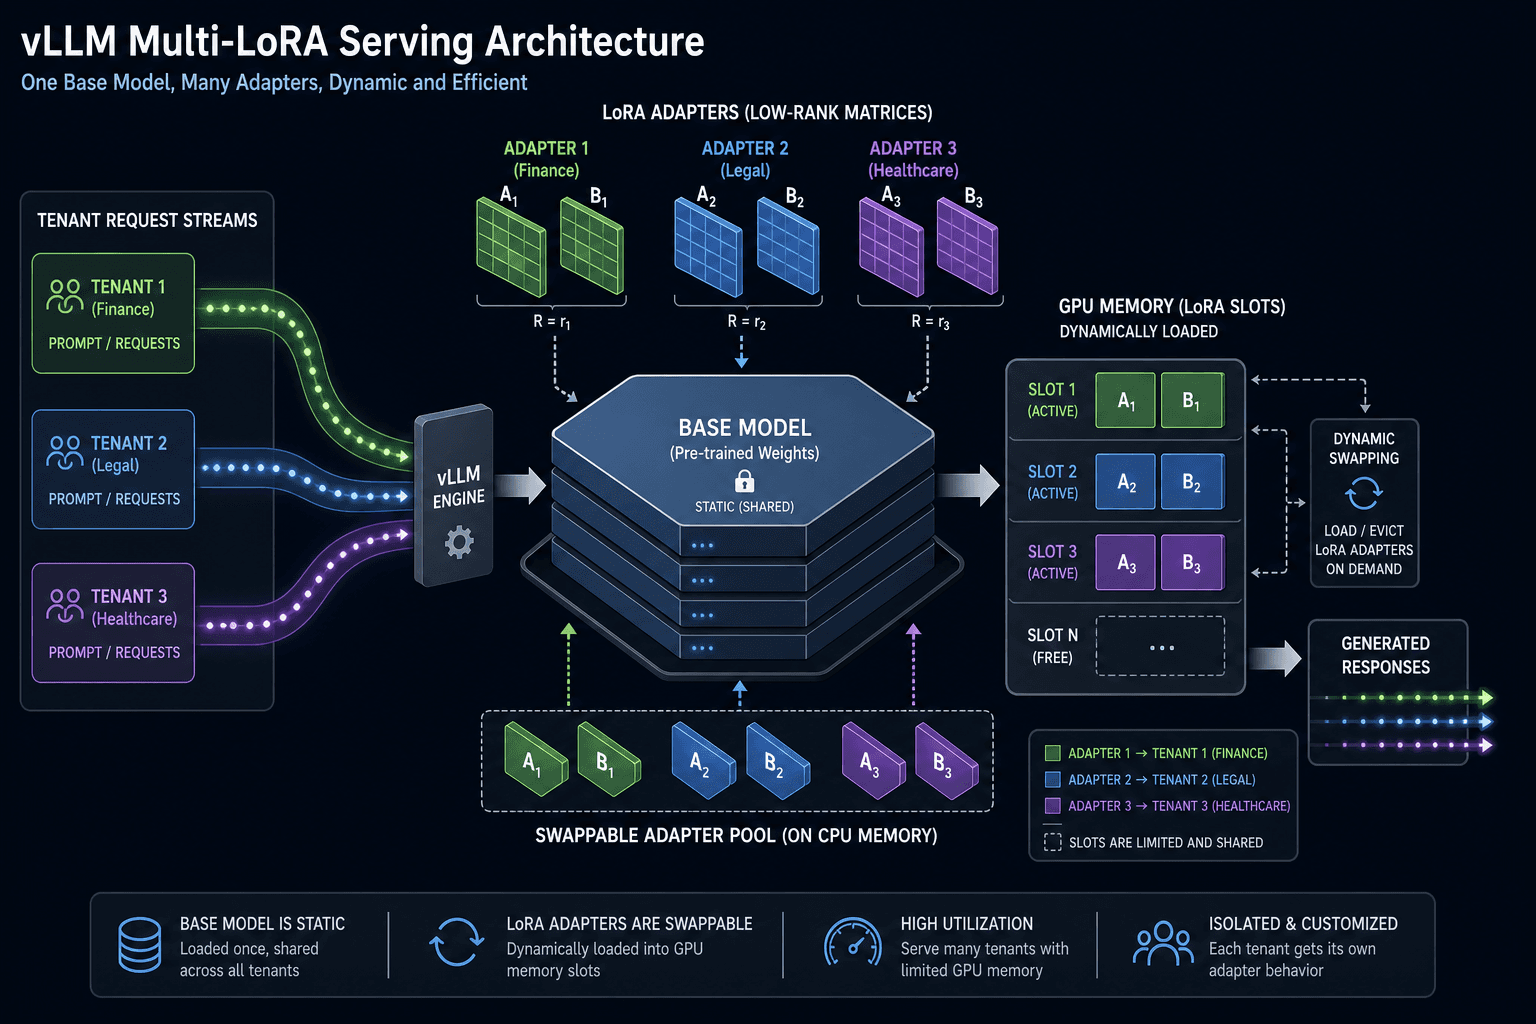
Part 8 · Production vLLMA technical walkthrough on configuring vLLM to handle multiple LoRA adapters at serve time, optimizing for multi-tenant ML workloads.
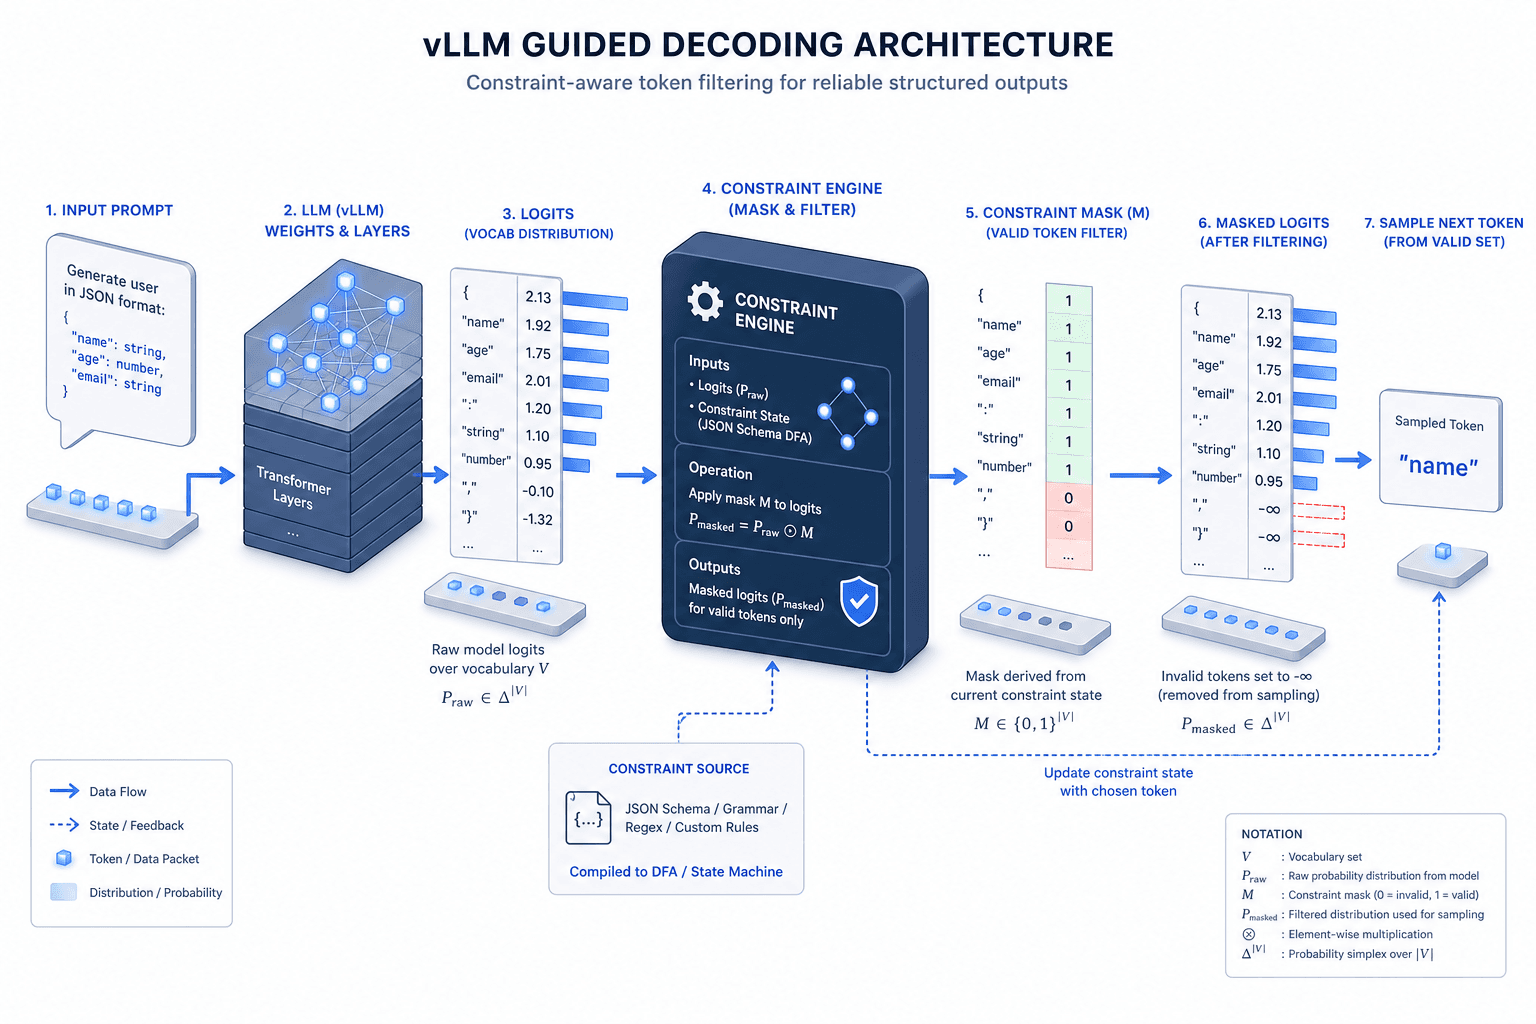
Part 7 · Production vLLMLearn how to enforce strict output formats in vLLM using guided decoding, JSON schemas, and grammar constraints for production-grade reliability.
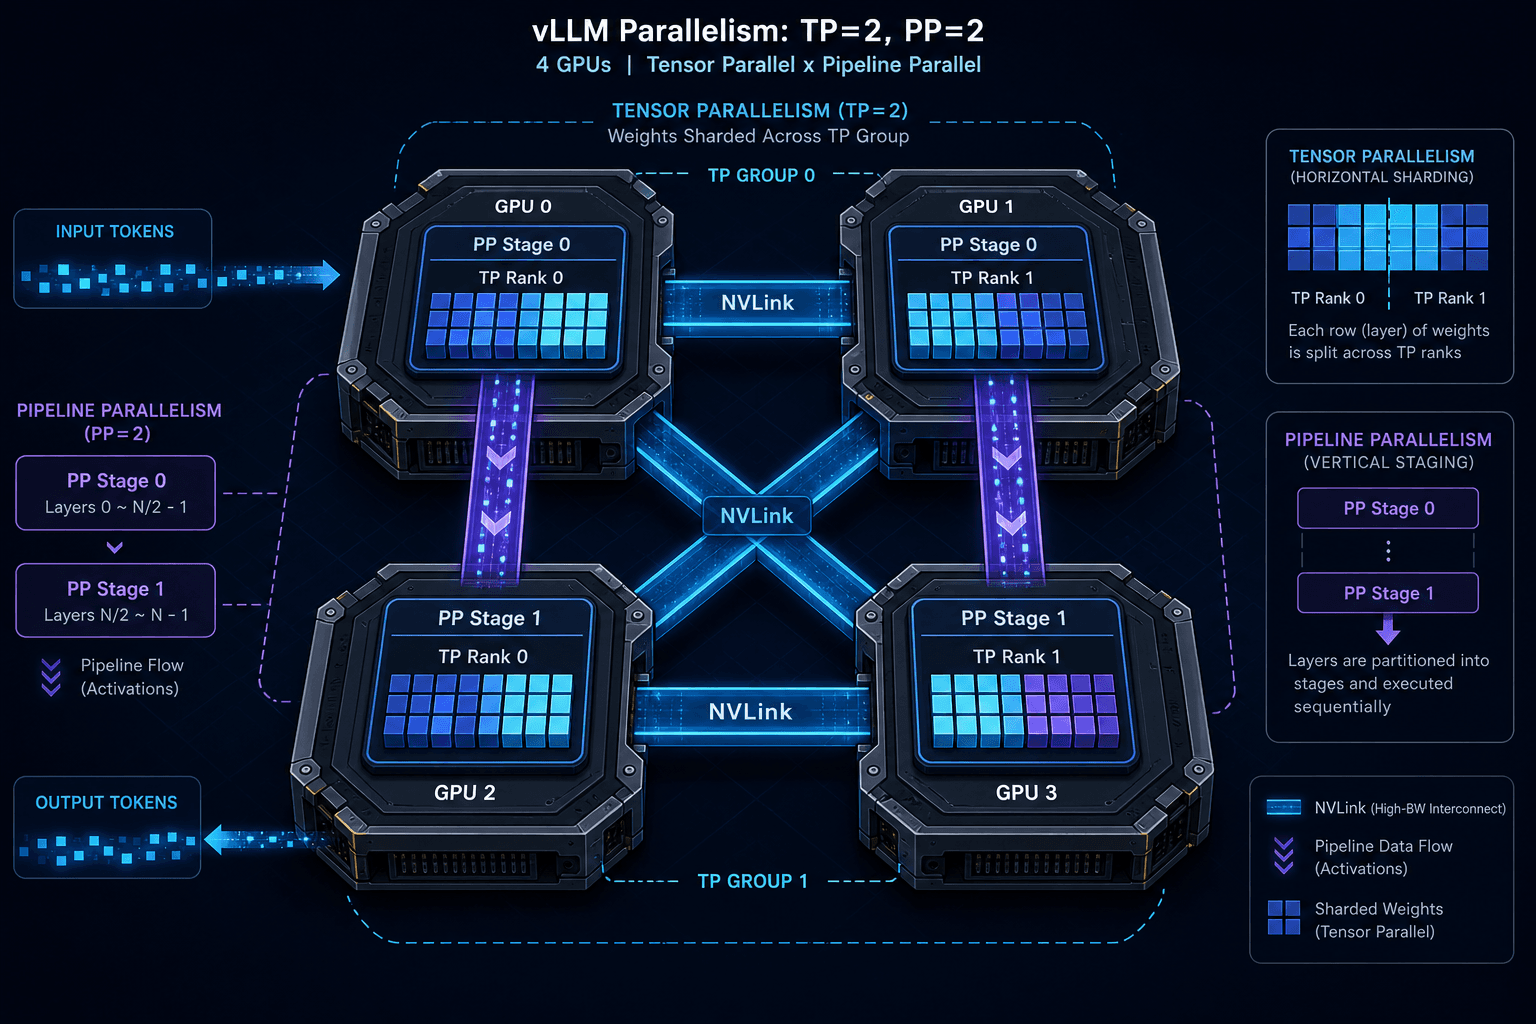
Part 6 · Production vLLMA technical breakdown of tensor and pipeline parallelism strategies in vLLM for infrastructure and ML engineers deploying large language models.
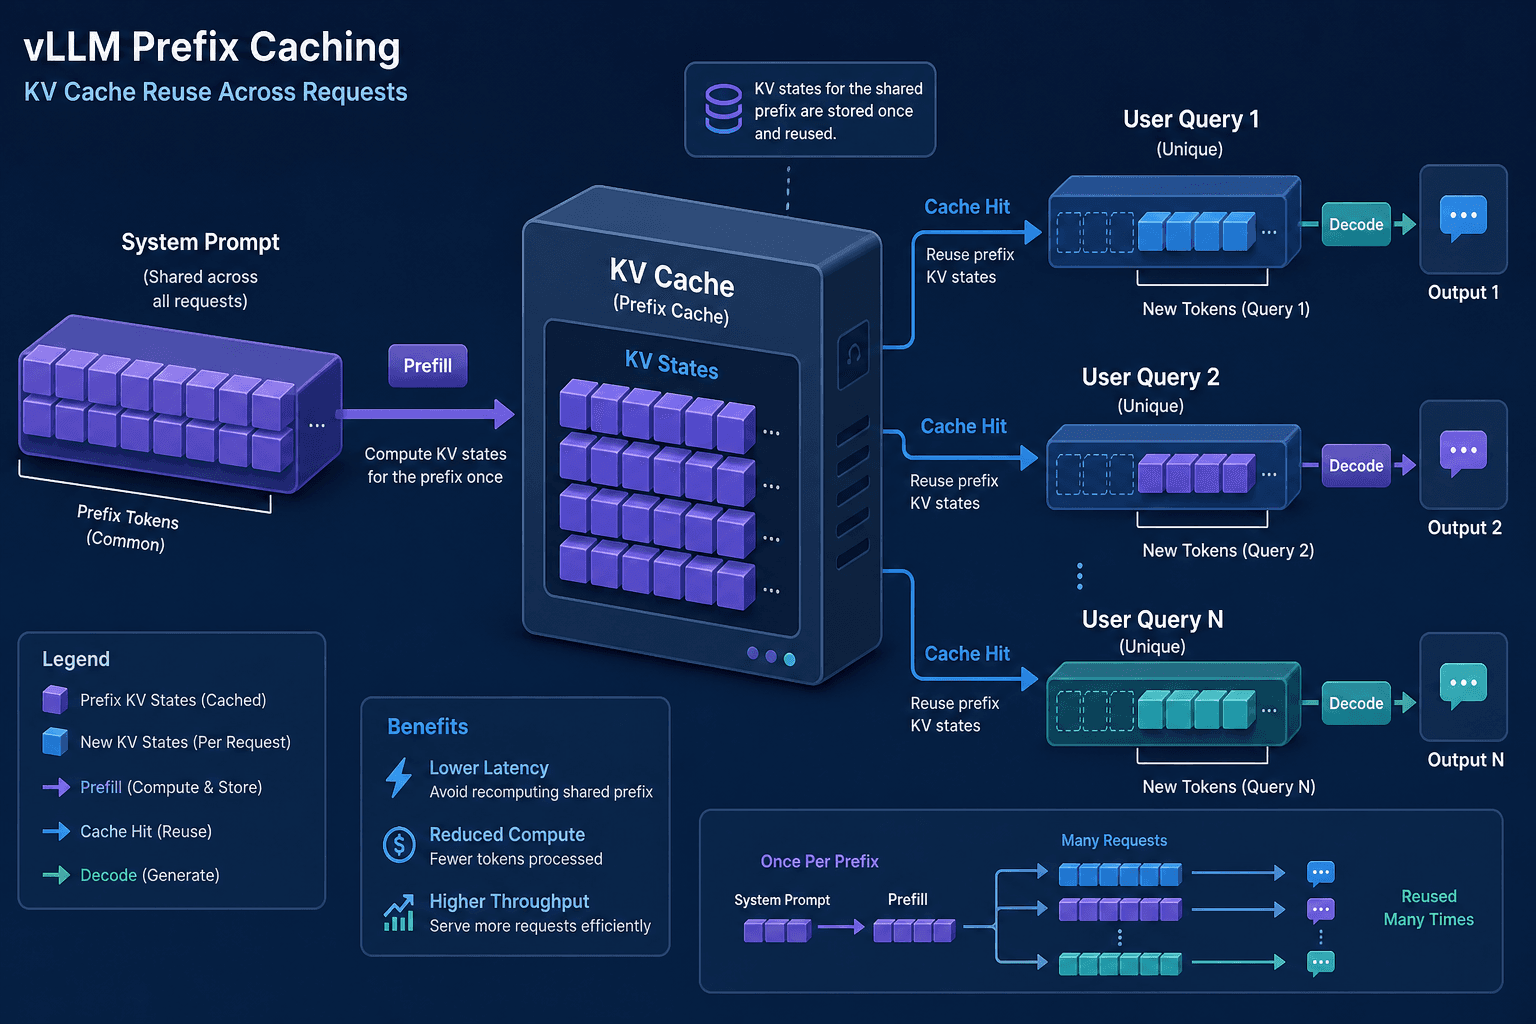
Part 5 · Production vLLMExplore the nuances of prefix caching in vLLM. Learn when automatic prefix caching boosts TTFT and cache hit rates, and identify scenarios where it offers little value.
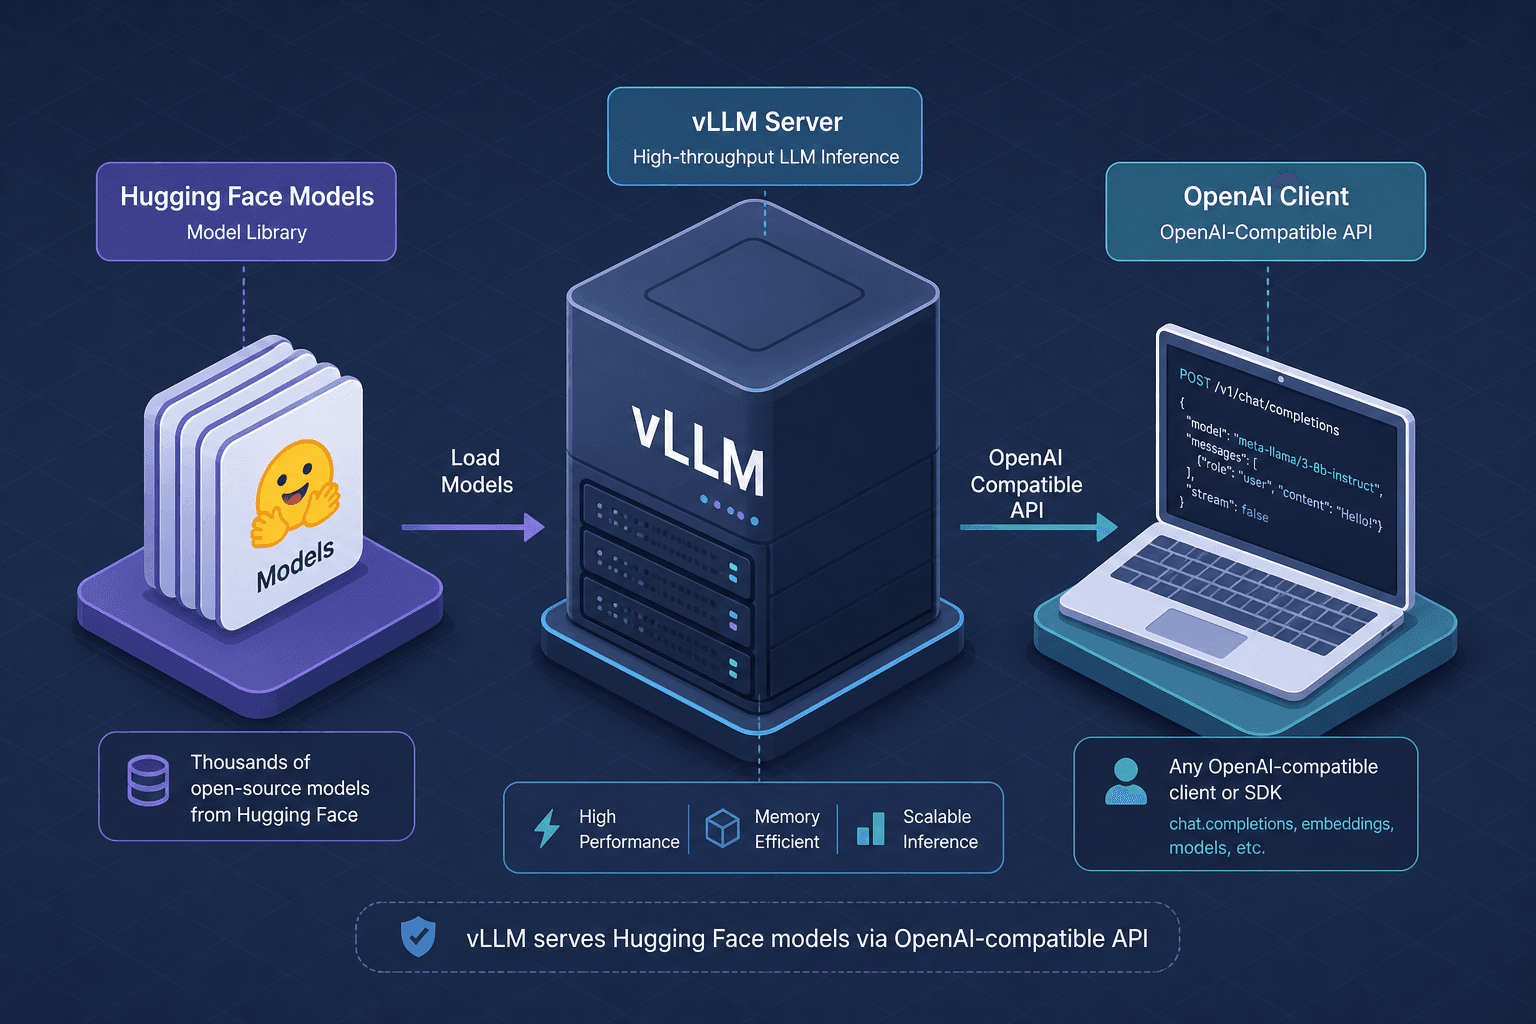
Part 4 · Production vLLMA practical guide to deploying Hugging Face models via vLLM's OpenAI-compatible API, enabling high-throughput inference with minimal setup.
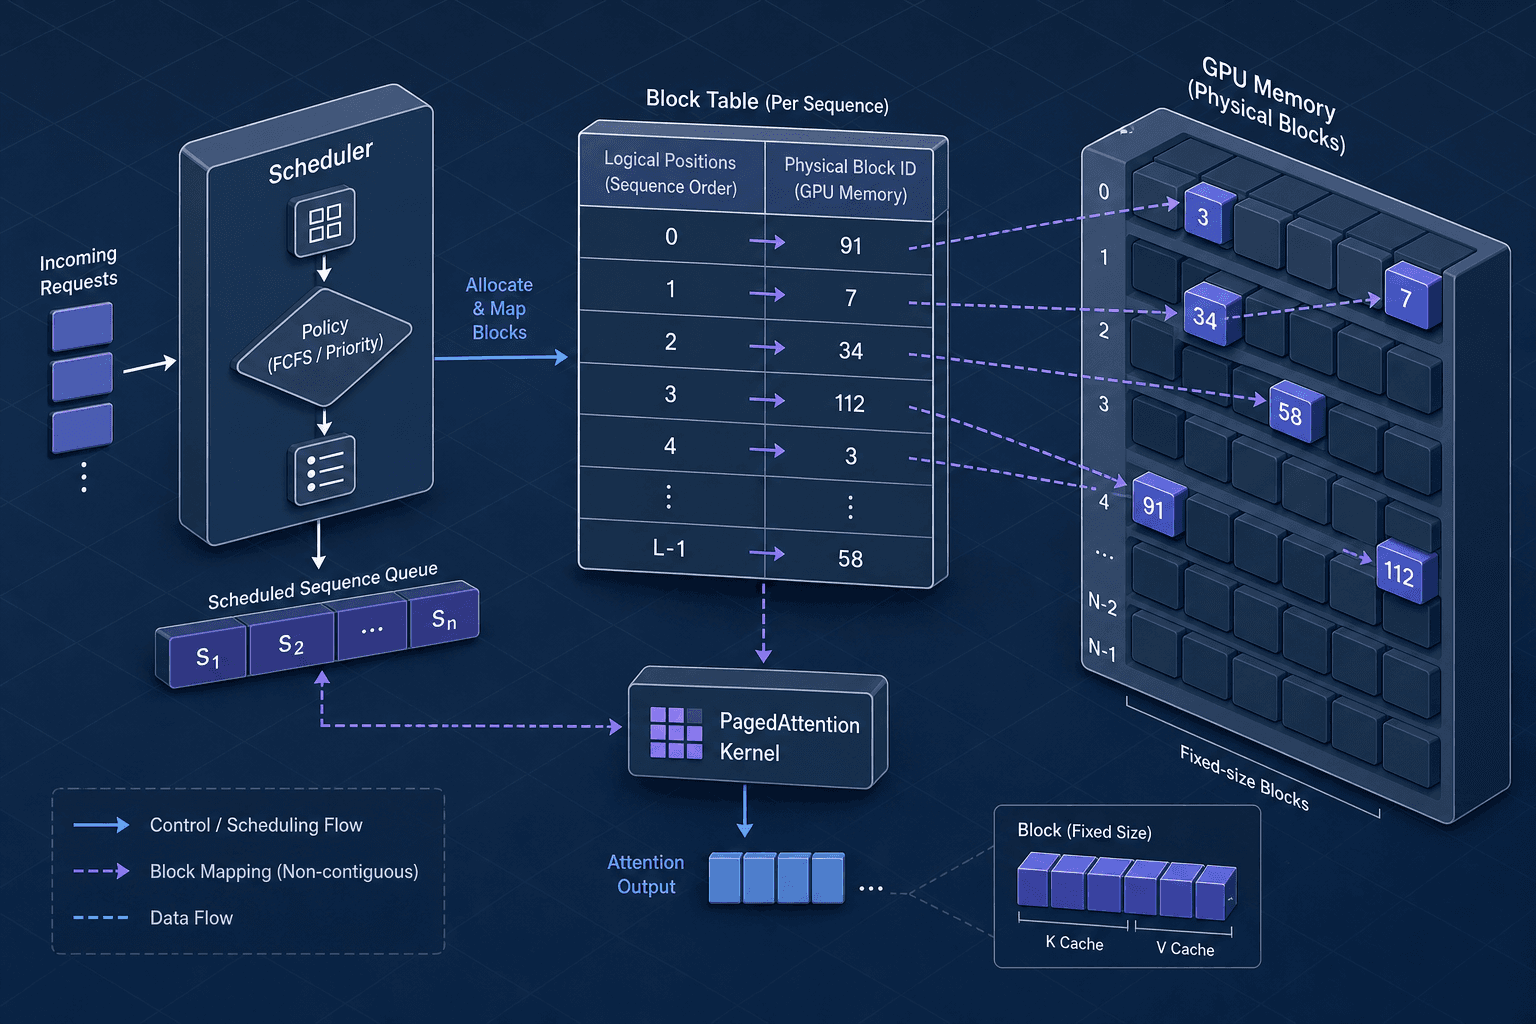
Part 2 · Production vLLMExplore how vLLM uses PagedAttention and a scheduler to optimize memory usage and throughput for large language models.
Part 1 · Production vLLM