6 min readDevelopmentFeatured
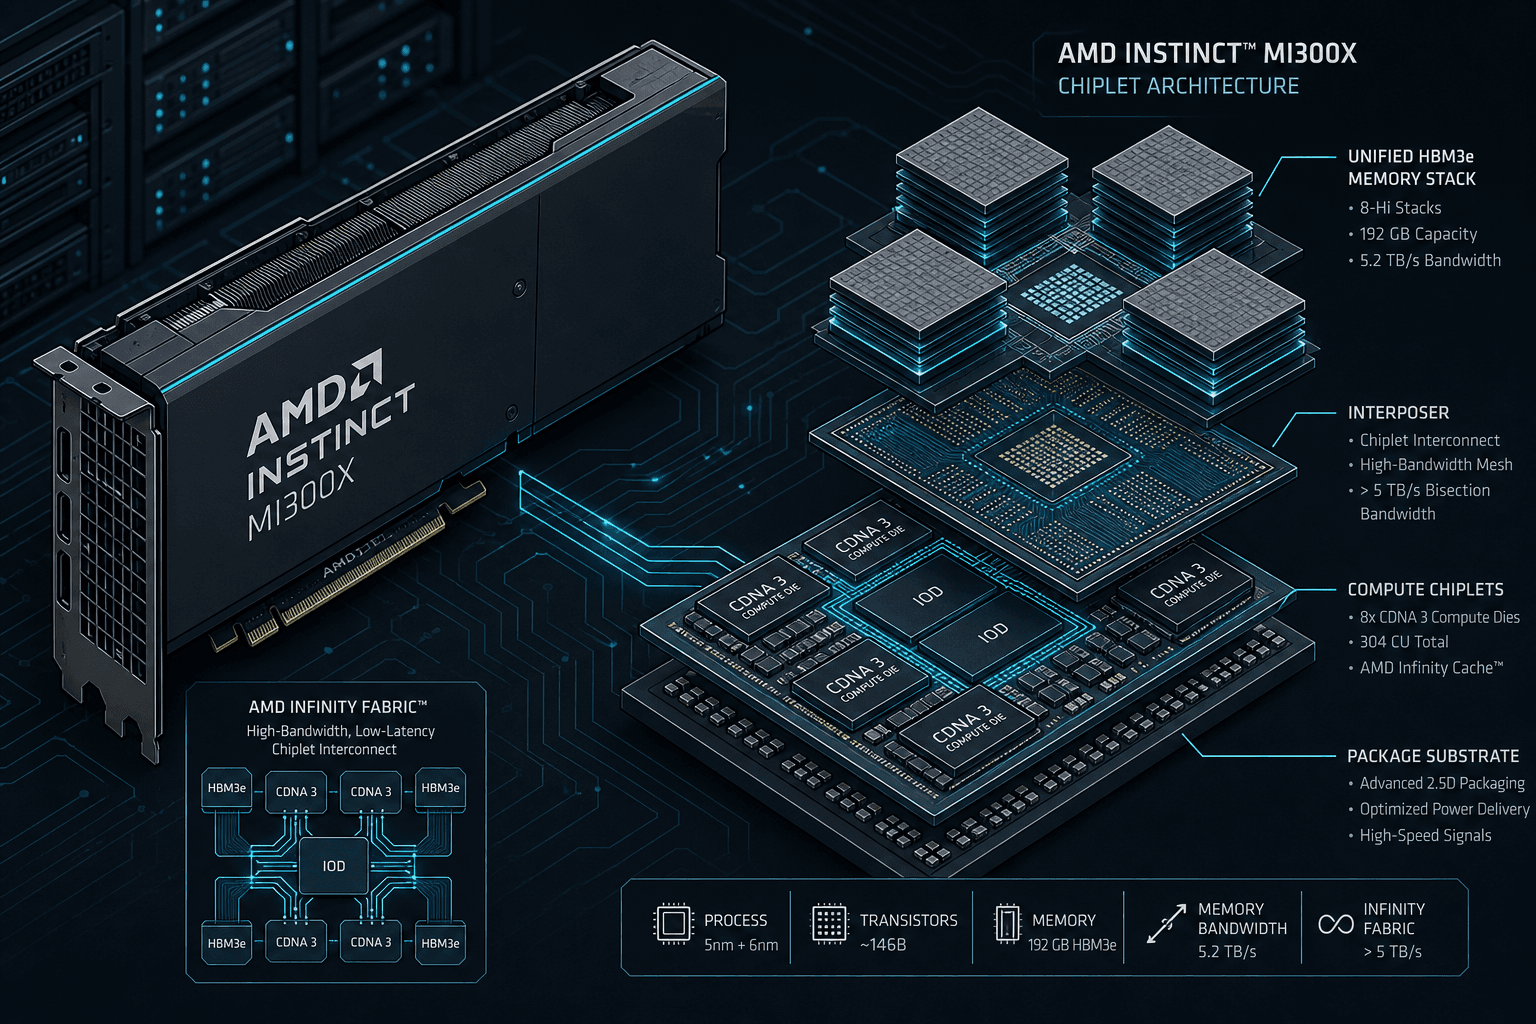
Running LLM Inference on AMD MI300X: A Field Report
An in-depth look at deploying large language models on AMD's MI300X hardware using ROCm and vLLM, with benchmark results.
Tag
Read 5 articles on Llm Inference by Ashish Srivastava — practical guides covering implementation patterns, security, and production lessons.
5 posts
An in-depth look at deploying large language models on AMD's MI300X hardware using ROCm and vLLM, with benchmark results.
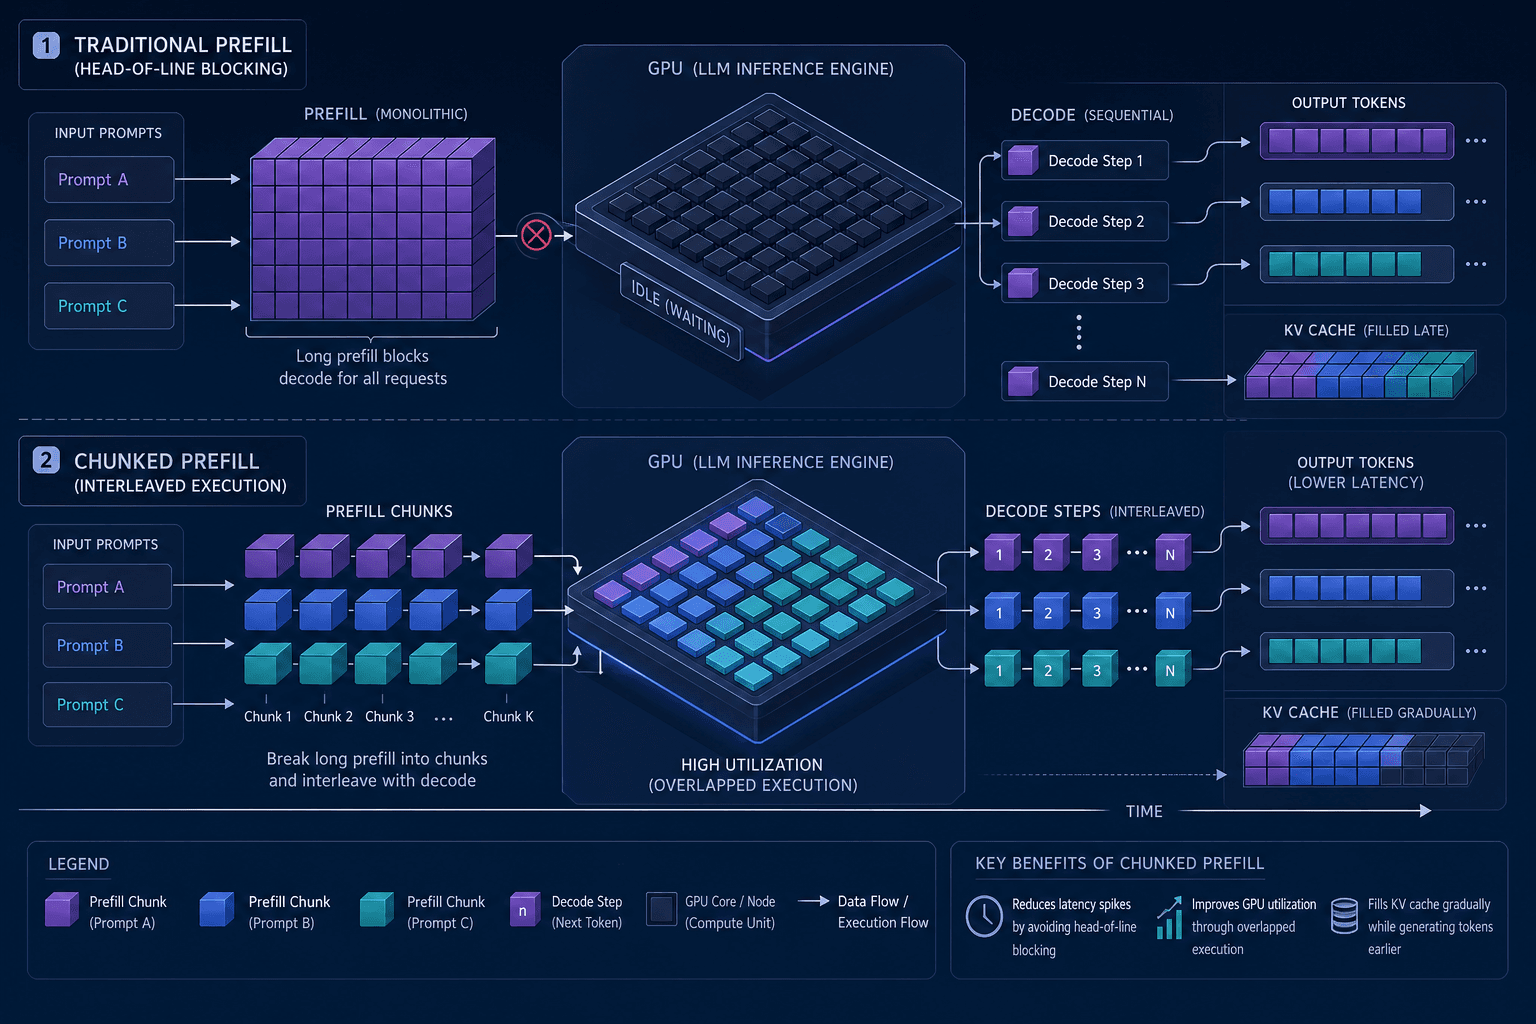
Learn how chunked prefill mitigates head-of-line blocking to smooth out p99 latency spikes in large language model serving.
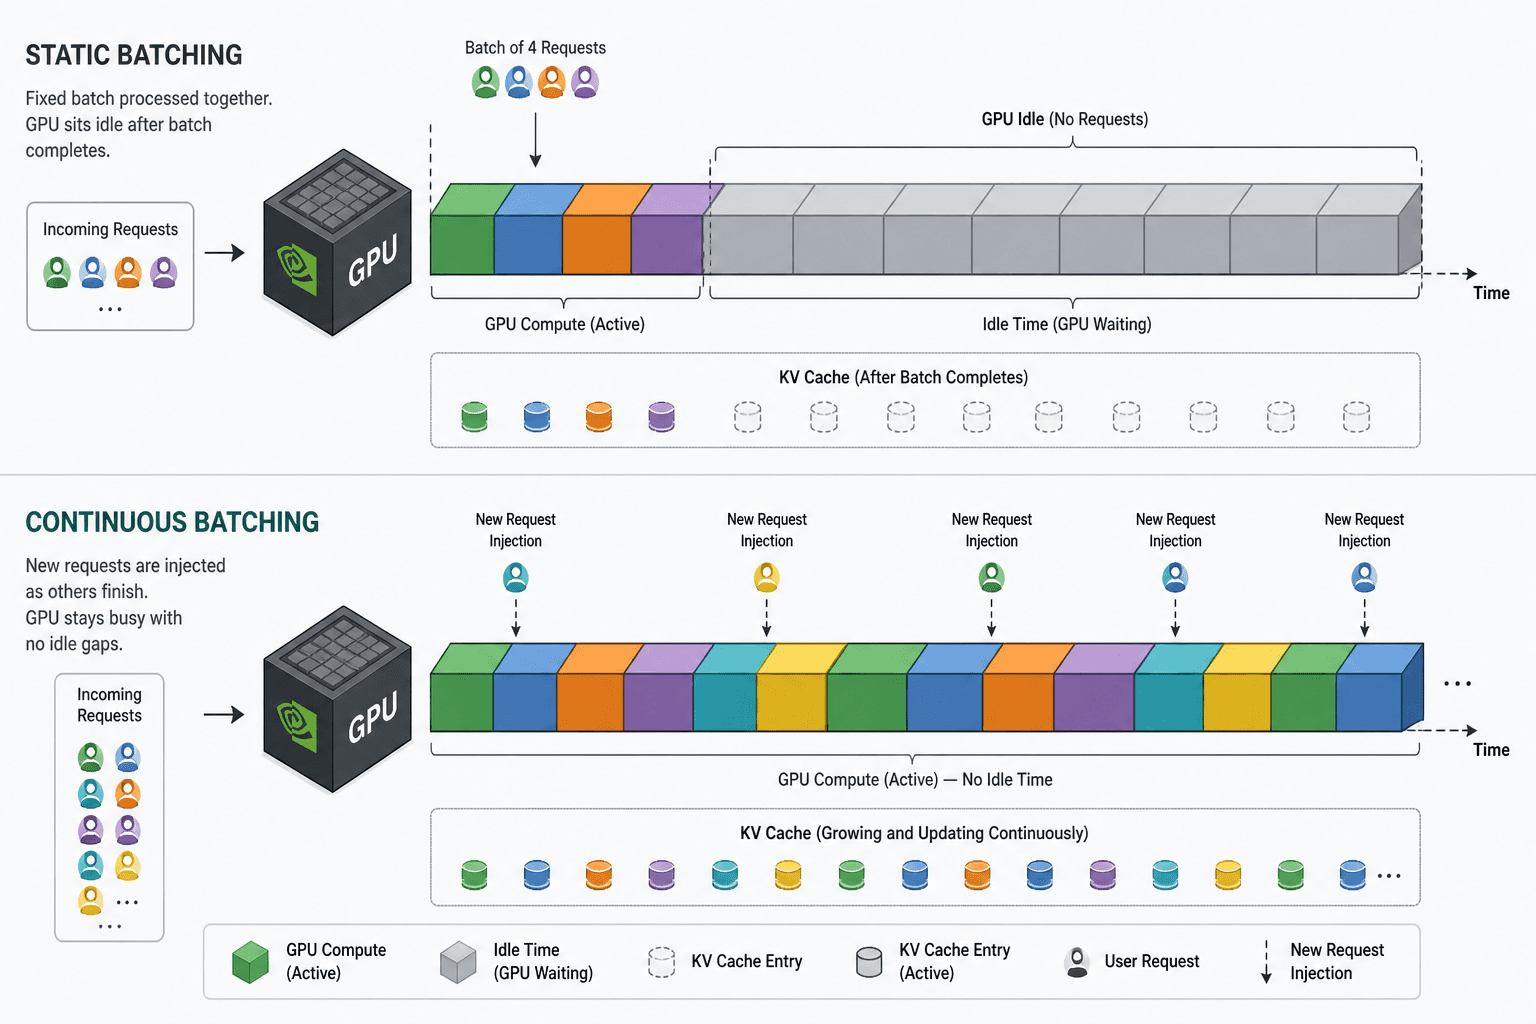
Visualizing how continuous batching improves inference throughput through iteration-level scheduling, with a focus on Orca.
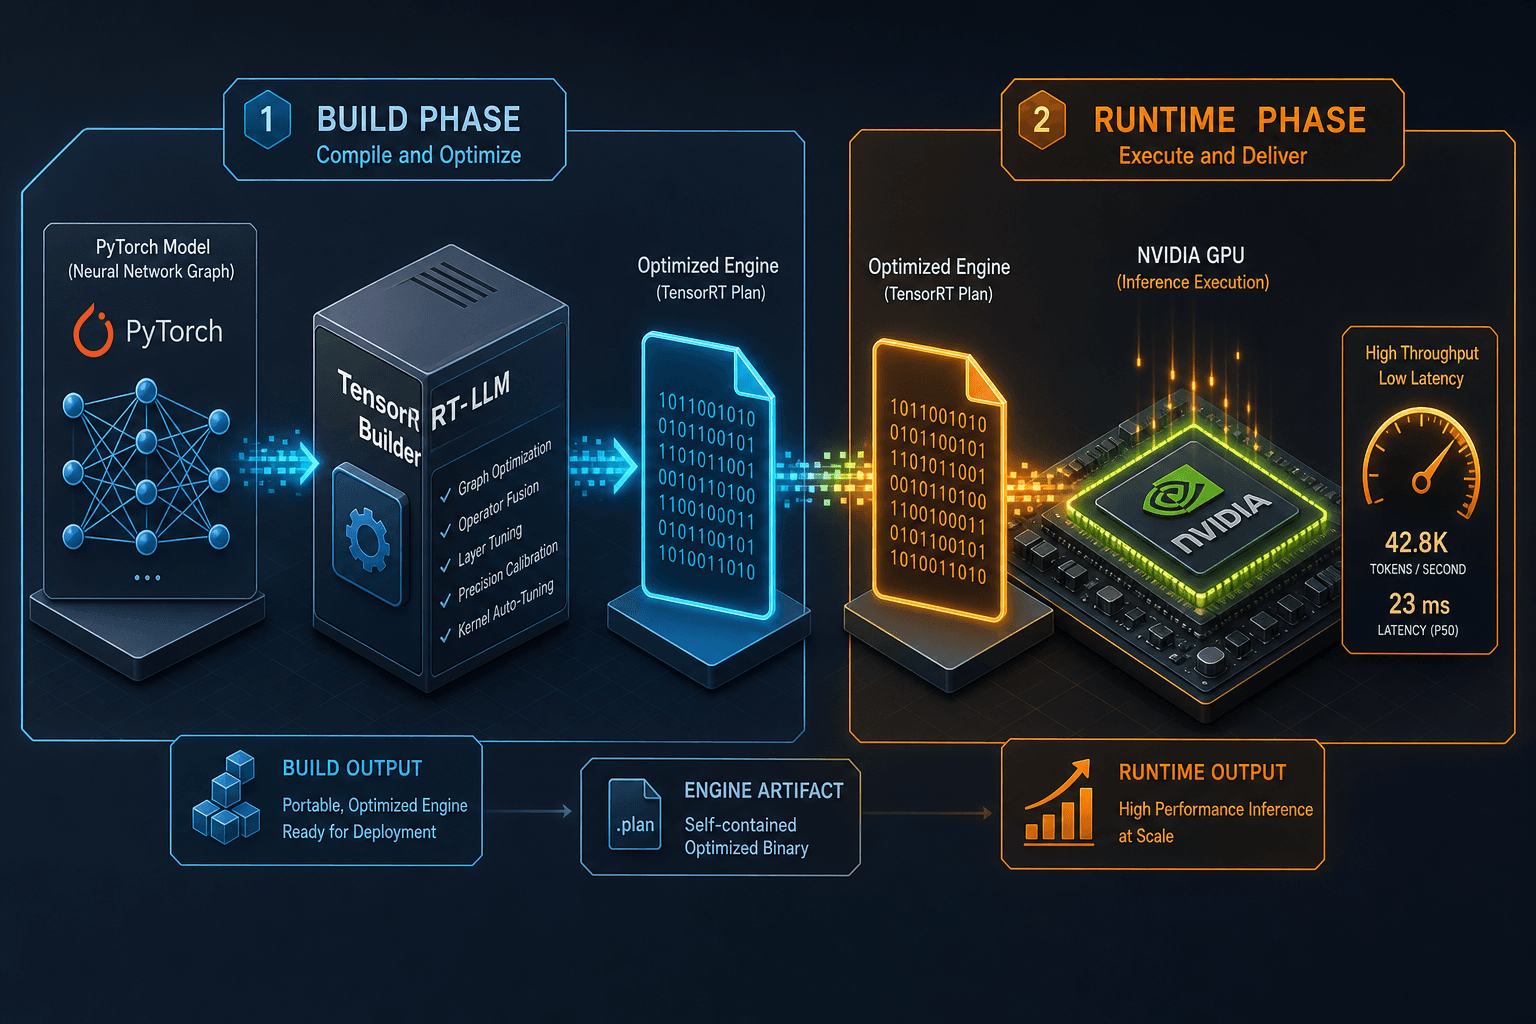
Explore why the extra steps in building TensorRT-LLM engines are justified by the substantial performance improvements they bring to inference workloads.
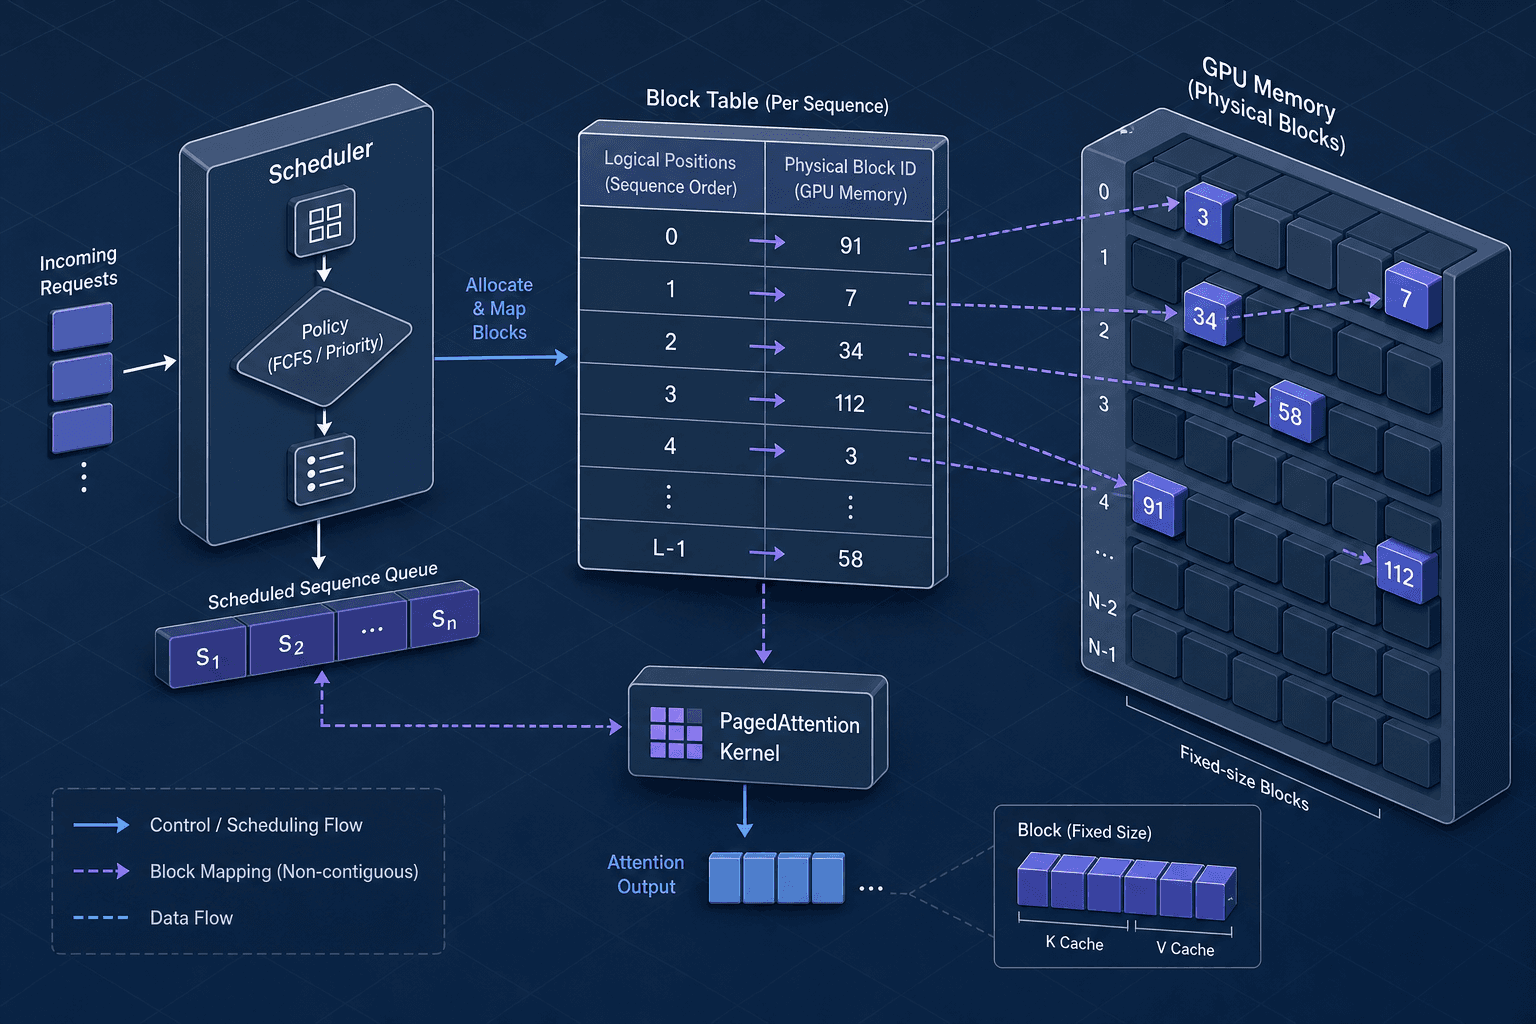
Explore how vLLM uses PagedAttention and a scheduler to optimize memory usage and throughput for large language models.
Part 1 · Production vLLM