6 min readDevelopment
SGLang's RadixAttention, Explained
Explore how SGLang uses RadixAttention and prefix caching to significantly boost throughput and efficiency in large language model serving.
Tag
Read 5 articles on Throughput by Ashish Srivastava — practical guides covering implementation patterns, security, and production lessons.
5 posts
Explore how SGLang uses RadixAttention and prefix caching to significantly boost throughput and efficiency in large language model serving.
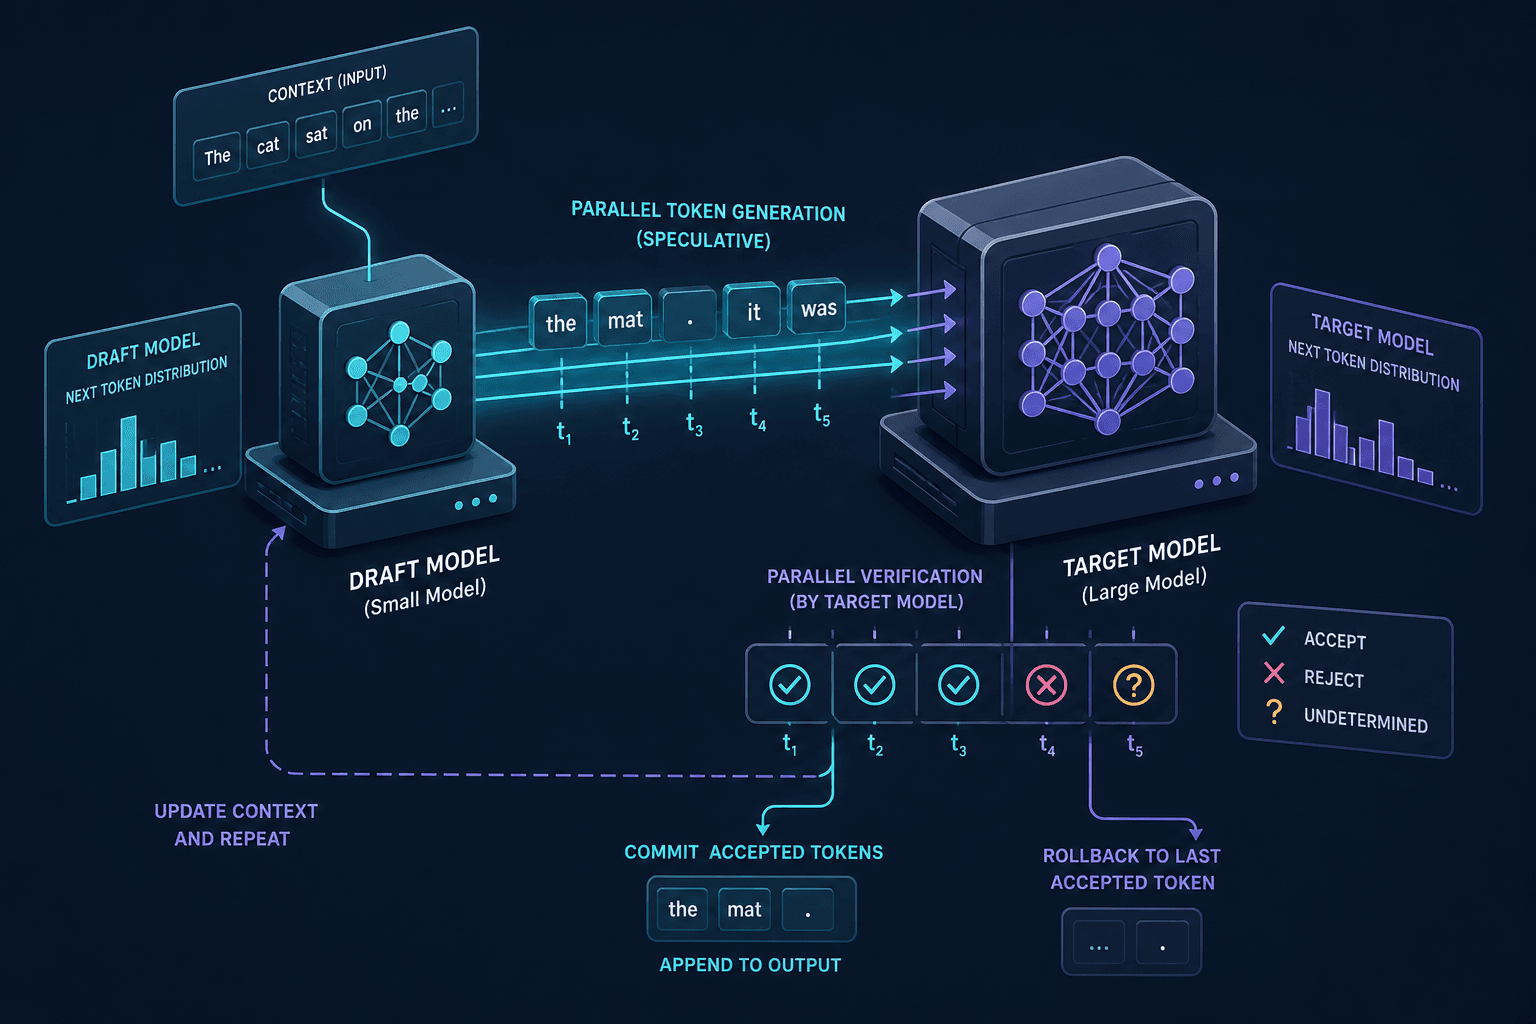
Explore how speculative decoding accelerates LLM inference by using smaller draft models to predict tokens, achieving significant throughput gains without compromising quality.
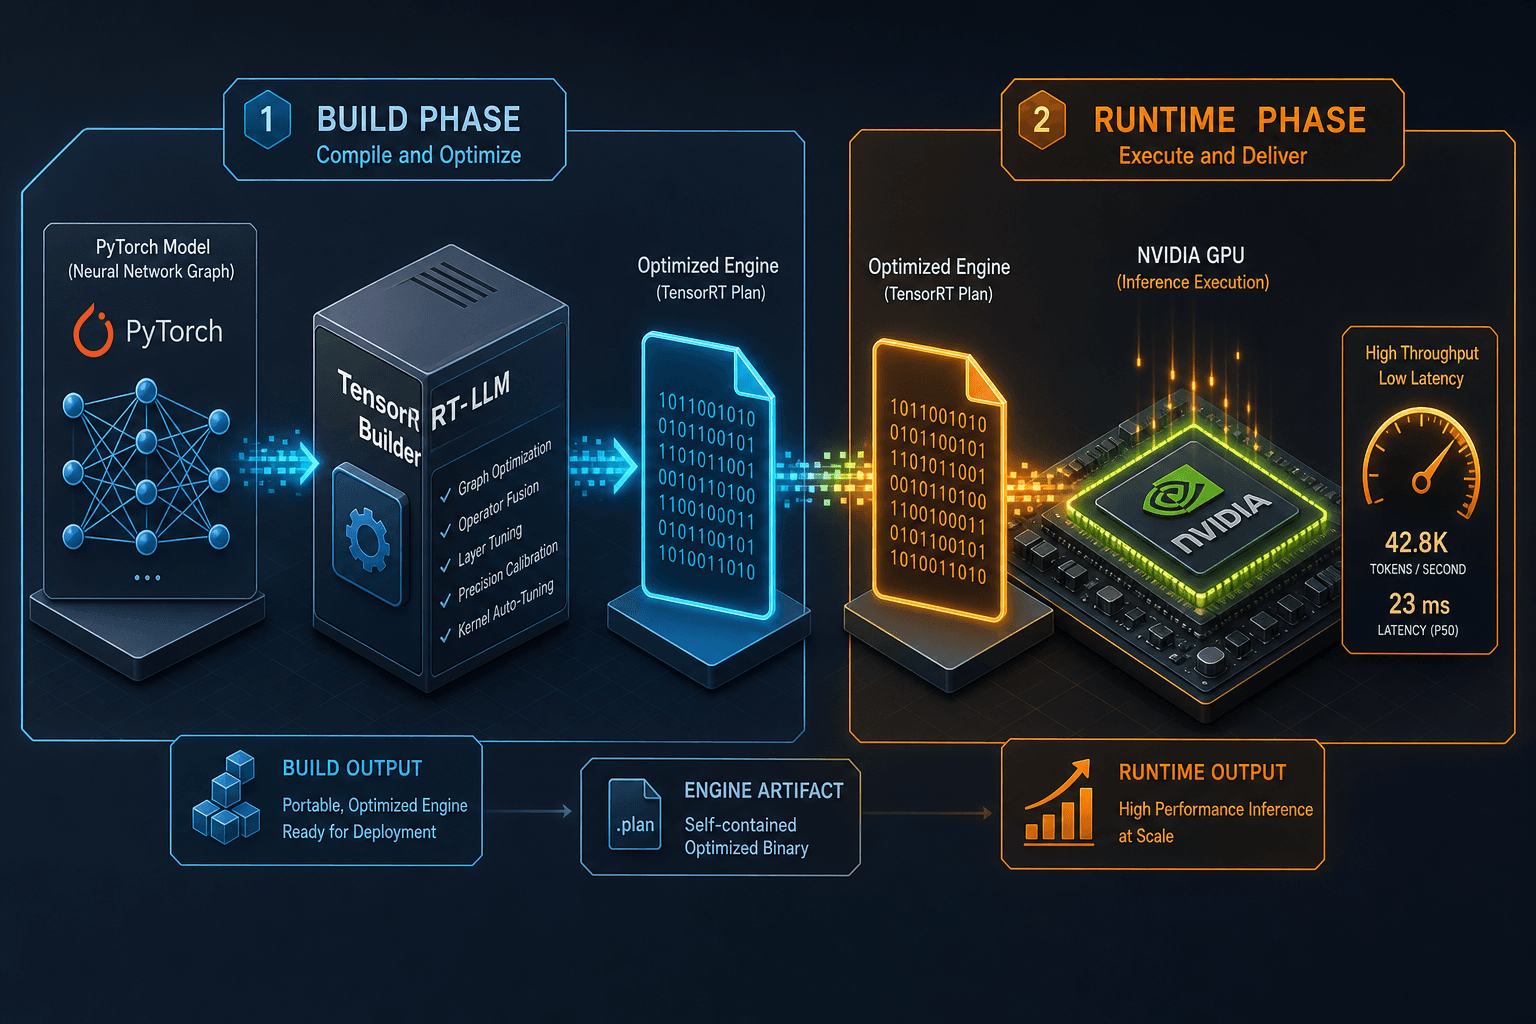
Explore why the extra steps in building TensorRT-LLM engines are justified by the substantial performance improvements they bring to inference workloads.
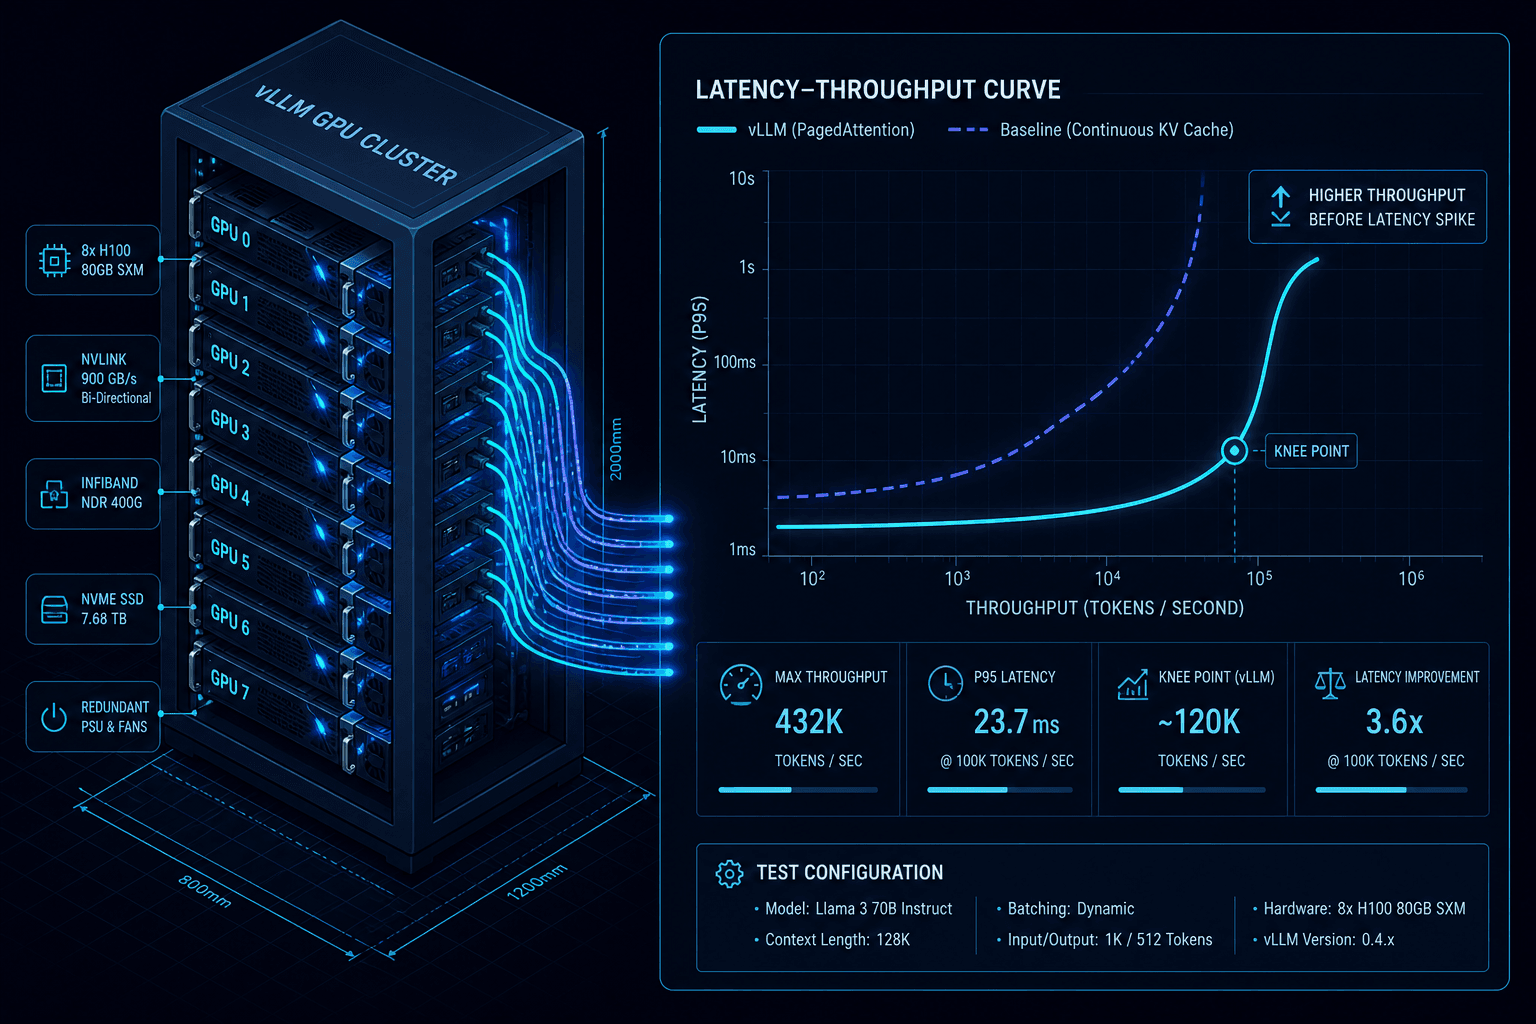
Learn how to effectively benchmark and load-test your vLLM deployment. This guide covers throughput, latency curves, and capacity planning strategies.
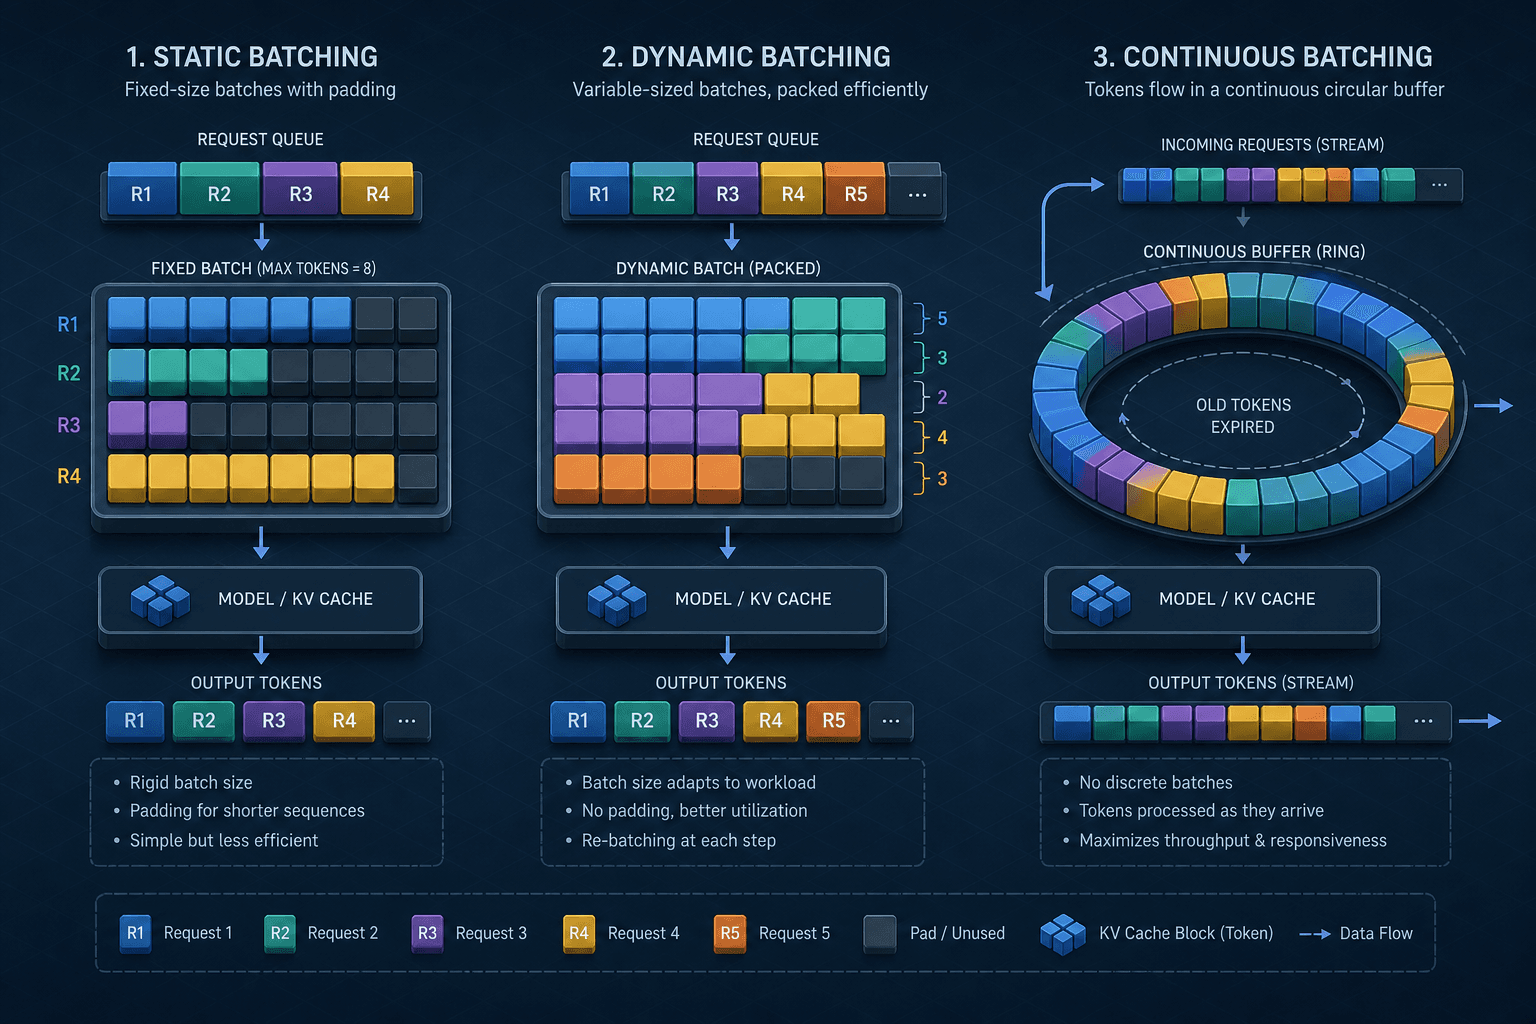
Part 8 · Production vLLMExplore how static, dynamic, and continuous batching strategies impact LLM inference performance, focusing on throughput optimization and latency reduction.
Part 5 · LLM Inference from Scratch