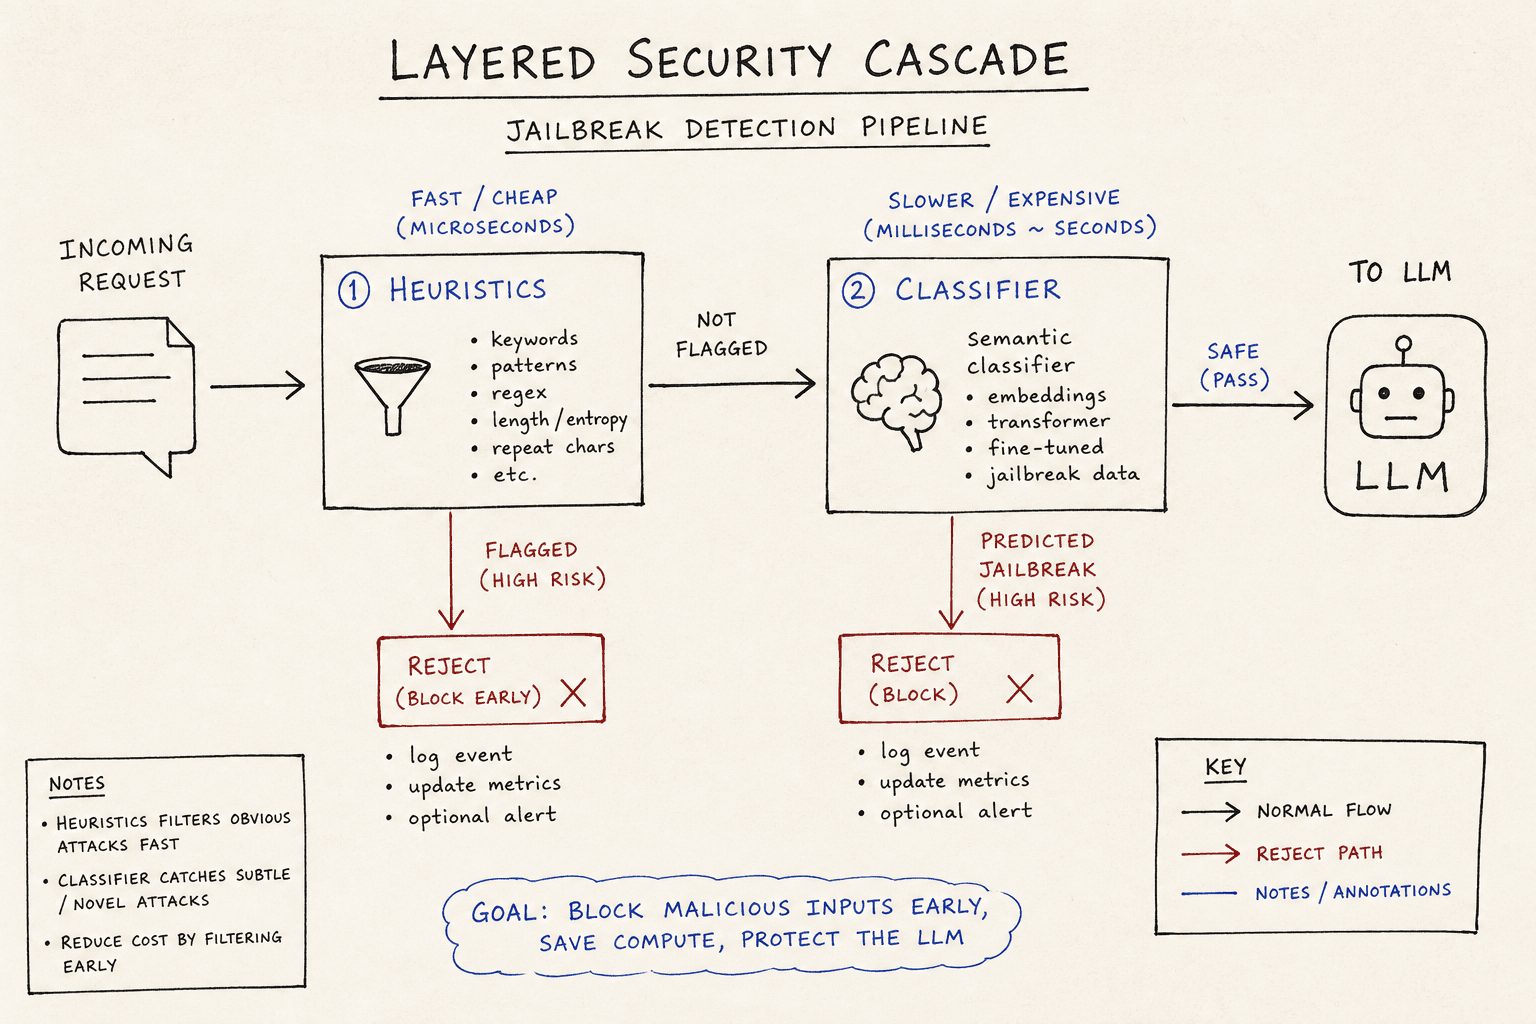
Jailbreak Detection: Classifiers, Heuristics, and Cost
A technical look at jailbreak detection strategies, balancing classifier accuracy and heuristic speed against latency and operational costs.
Part 5 · AI Security & GuardrailsTag
Read 7 articles on Latency by Ashish Srivastava — practical guides covering implementation patterns, security, and production lessons.
7 posts
A technical look at jailbreak detection strategies, balancing classifier accuracy and heuristic speed against latency and operational costs.
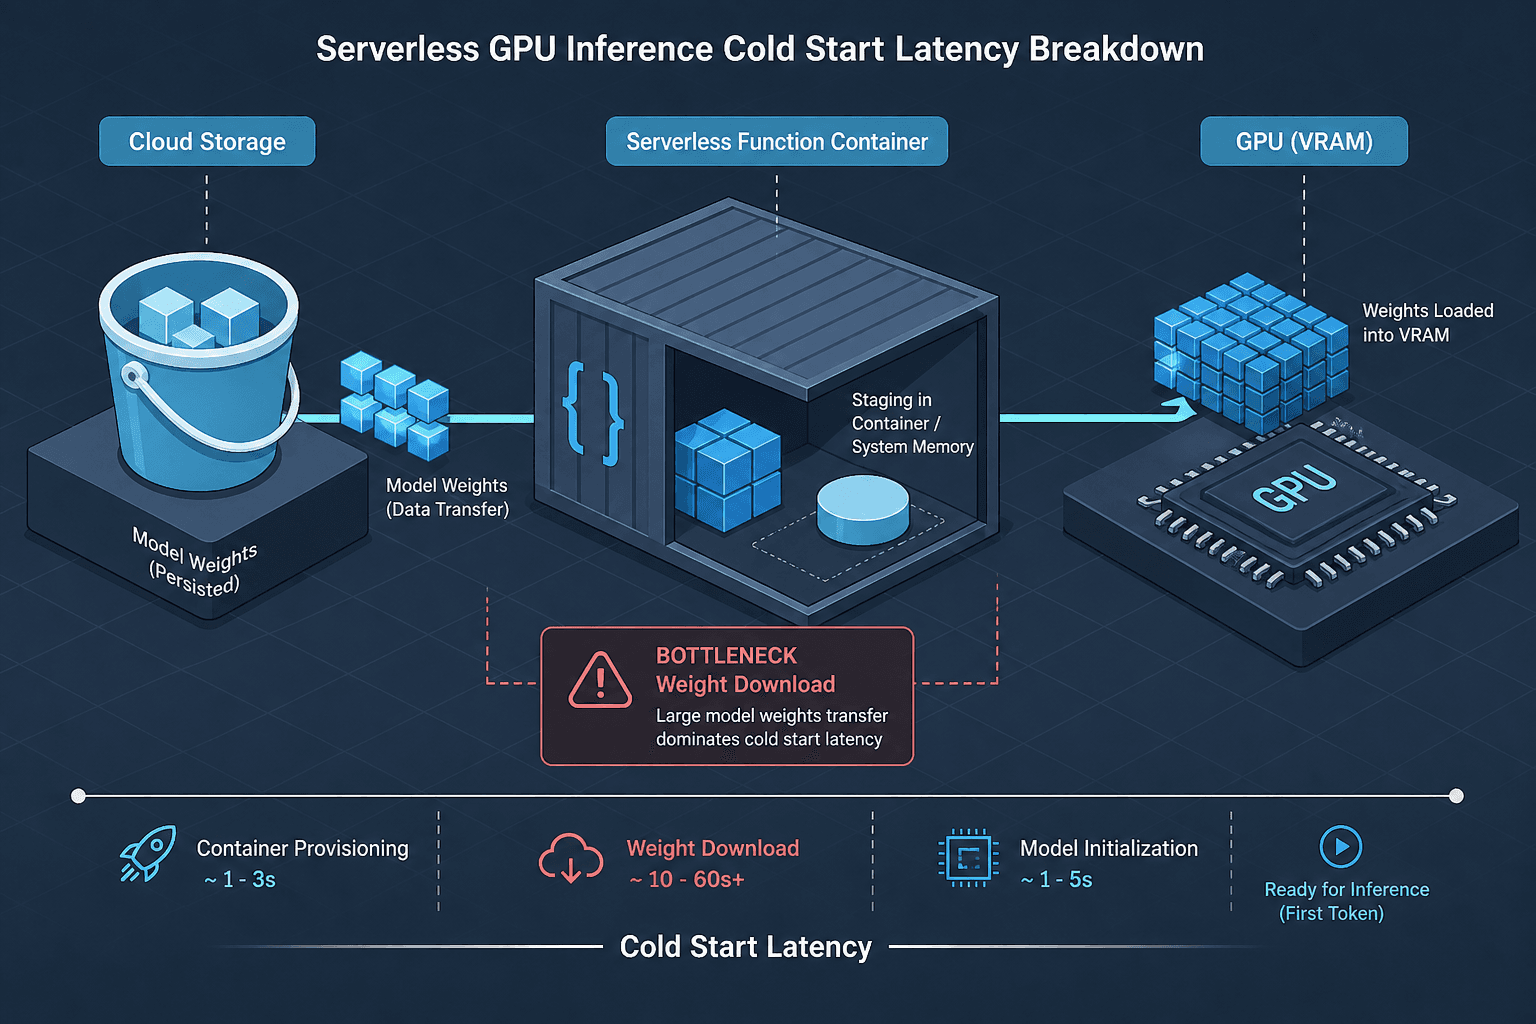
Part 5 · AI Security & GuardrailsServerless GPU inference often suffers from high latency during initialization. This article examines methods to reduce cold start times using snapshots and model streaming.
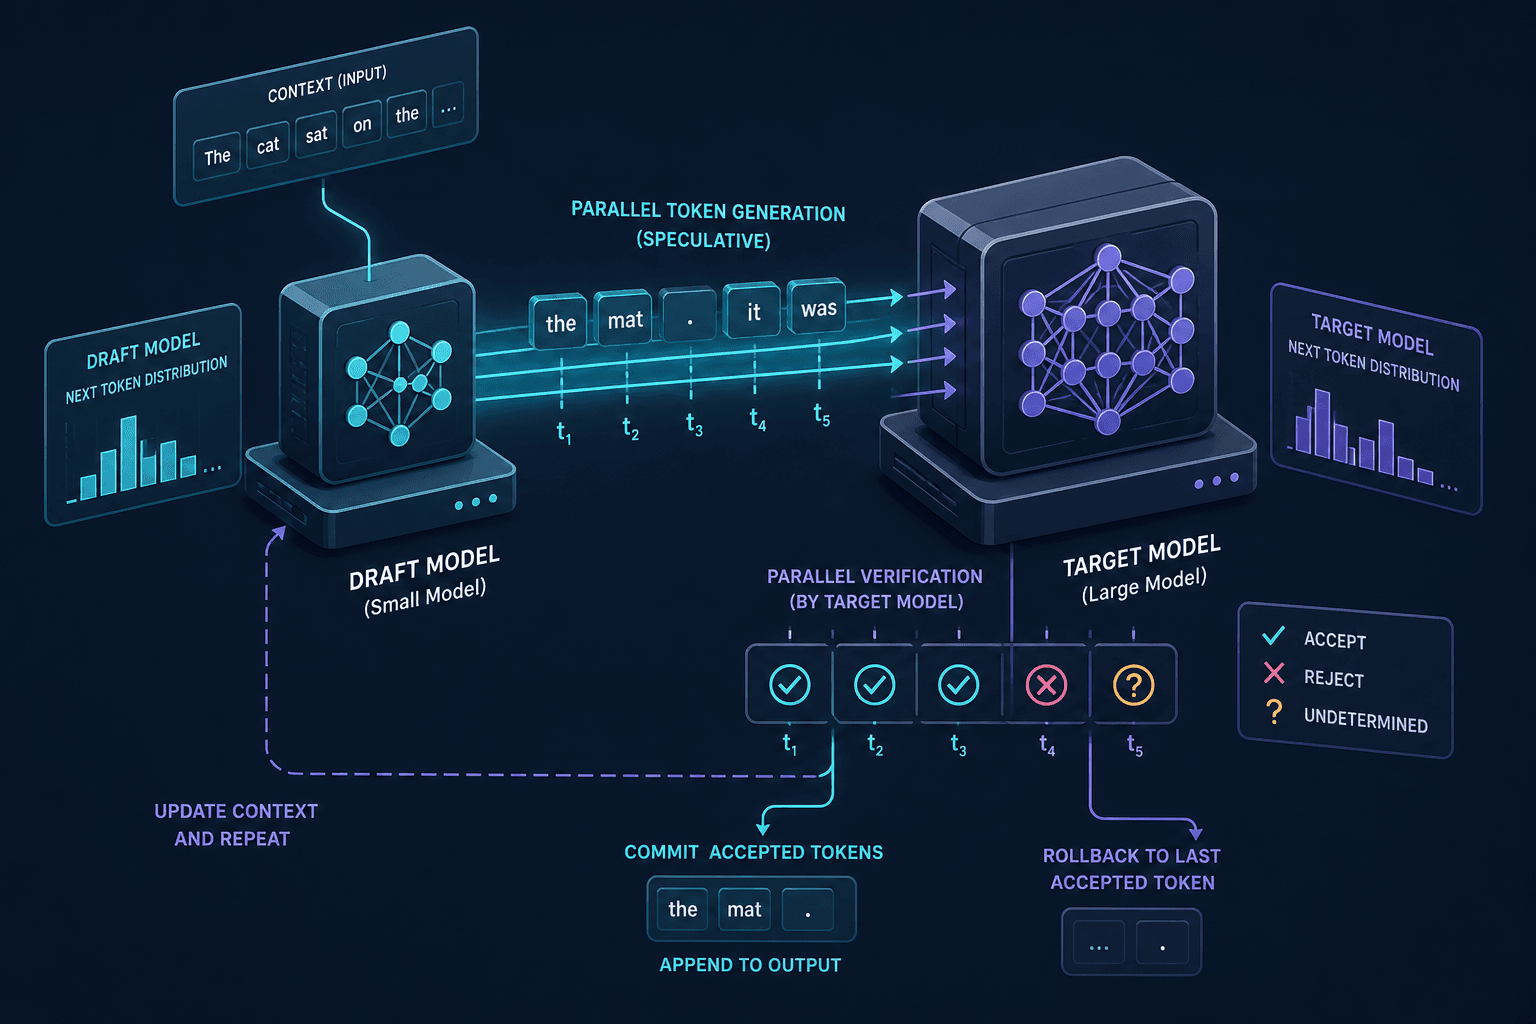
Explore how speculative decoding accelerates LLM inference by using smaller draft models to predict tokens, achieving significant throughput gains without compromising quality.
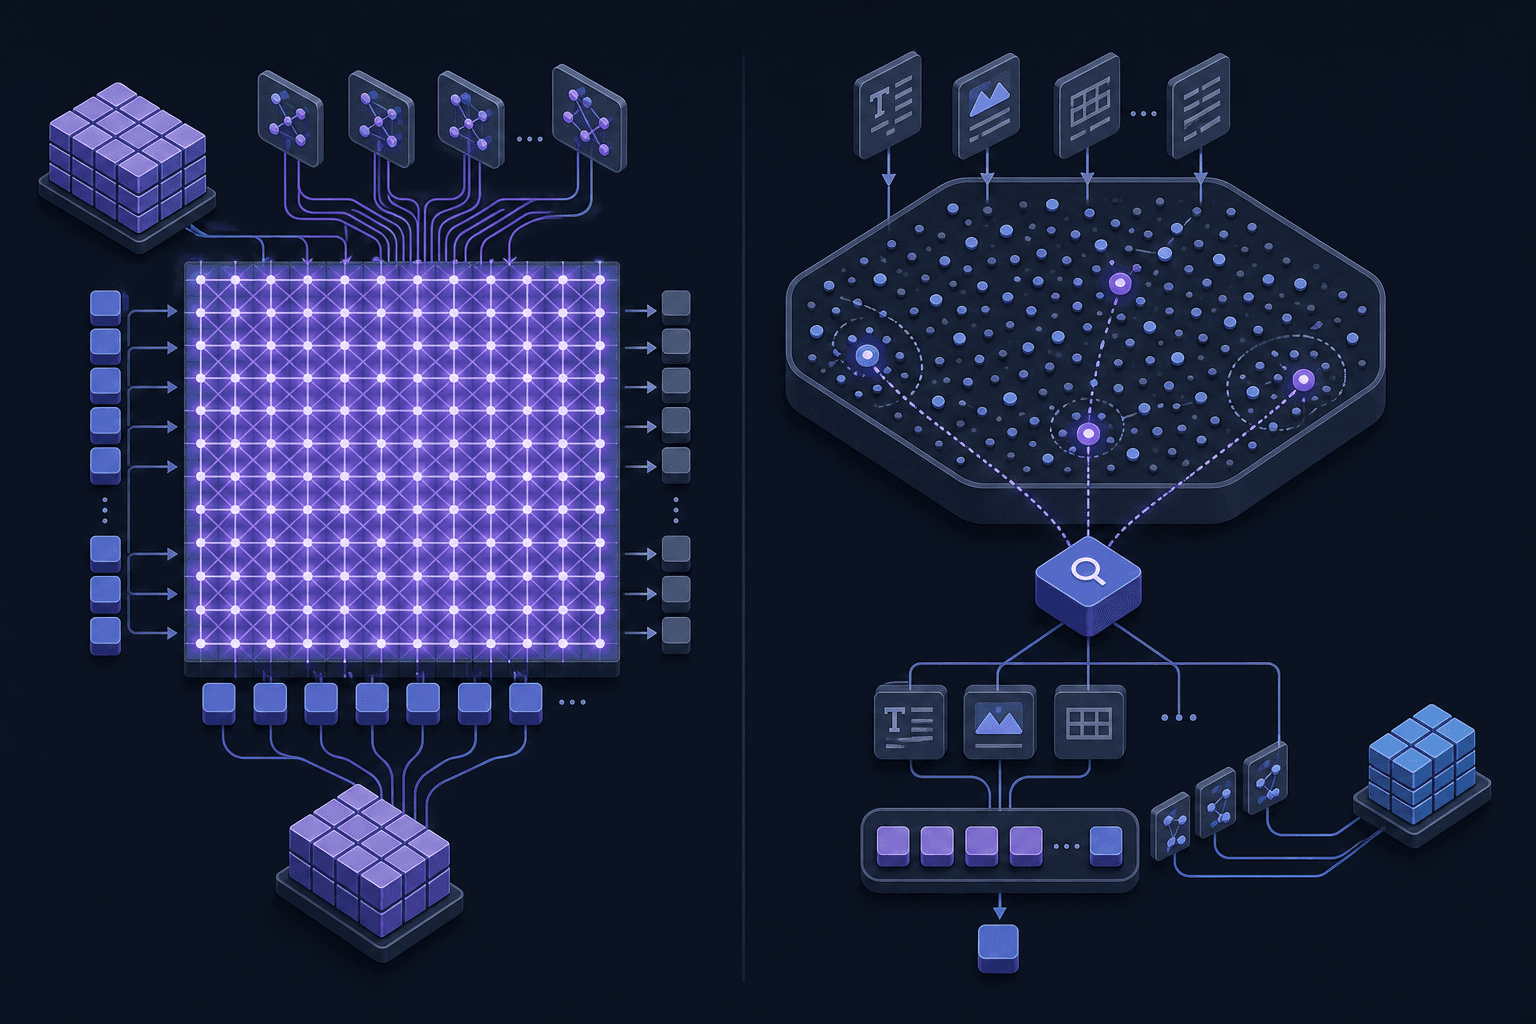
Should you use long-context windows or retrieval-augmented generation? We compare cost, latency, and accuracy for million-token scenarios.
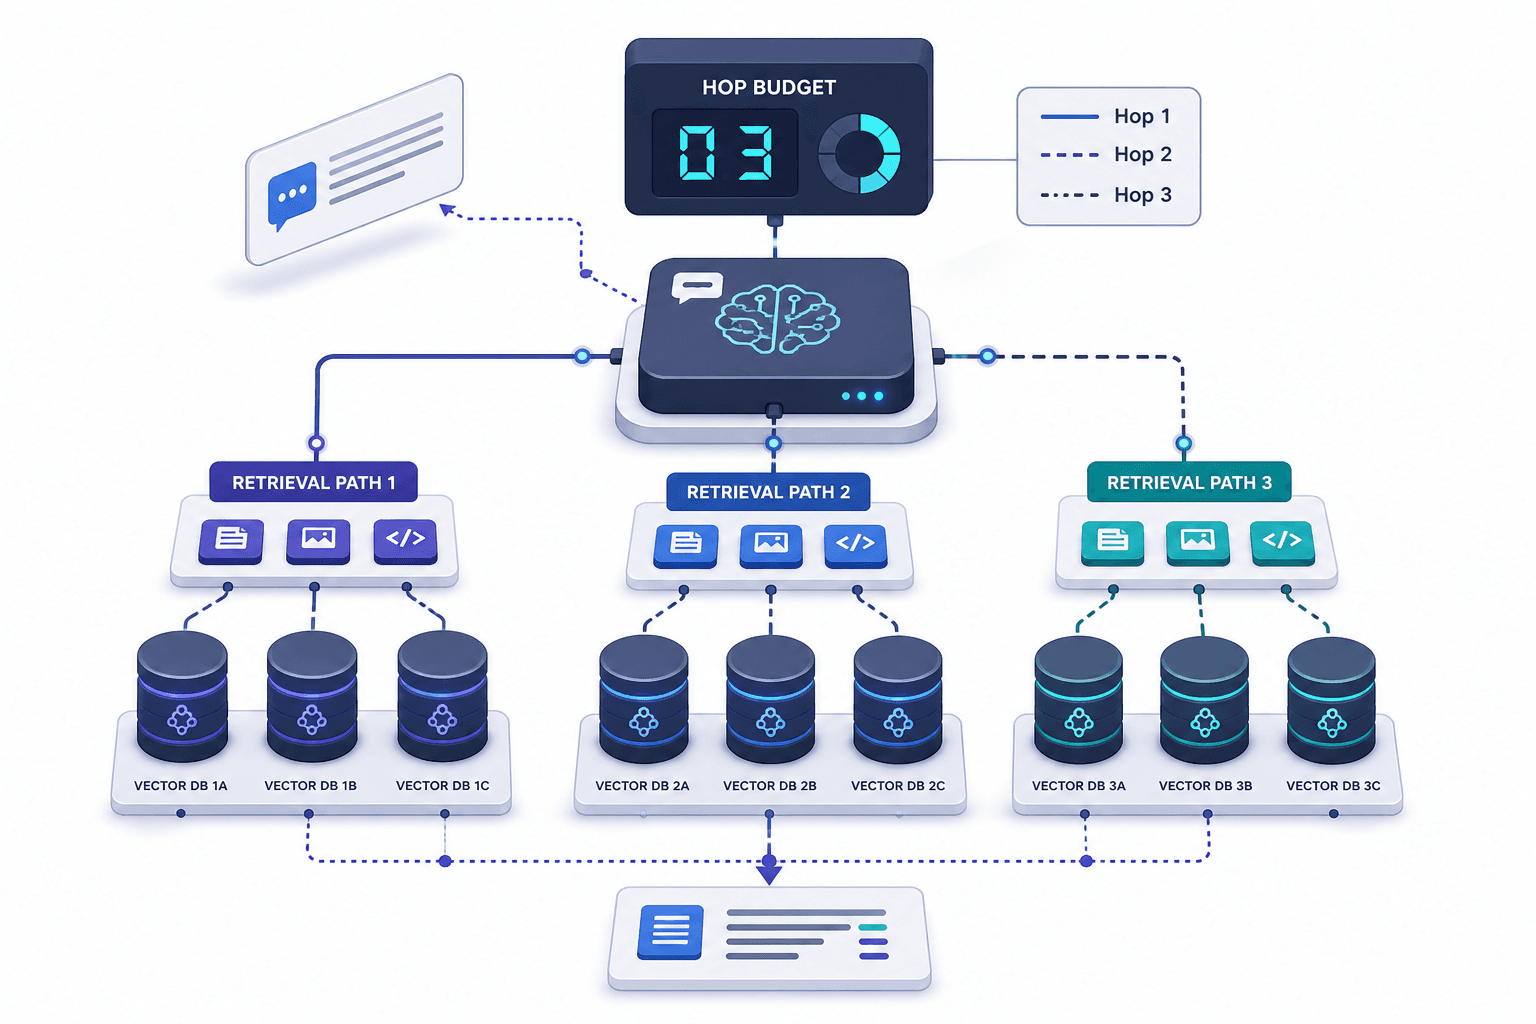
Part 5 · Context EngineeringLearn how to control latency in multi-hop retrieval by implementing hop budgets, parallel execution, and streaming responses.
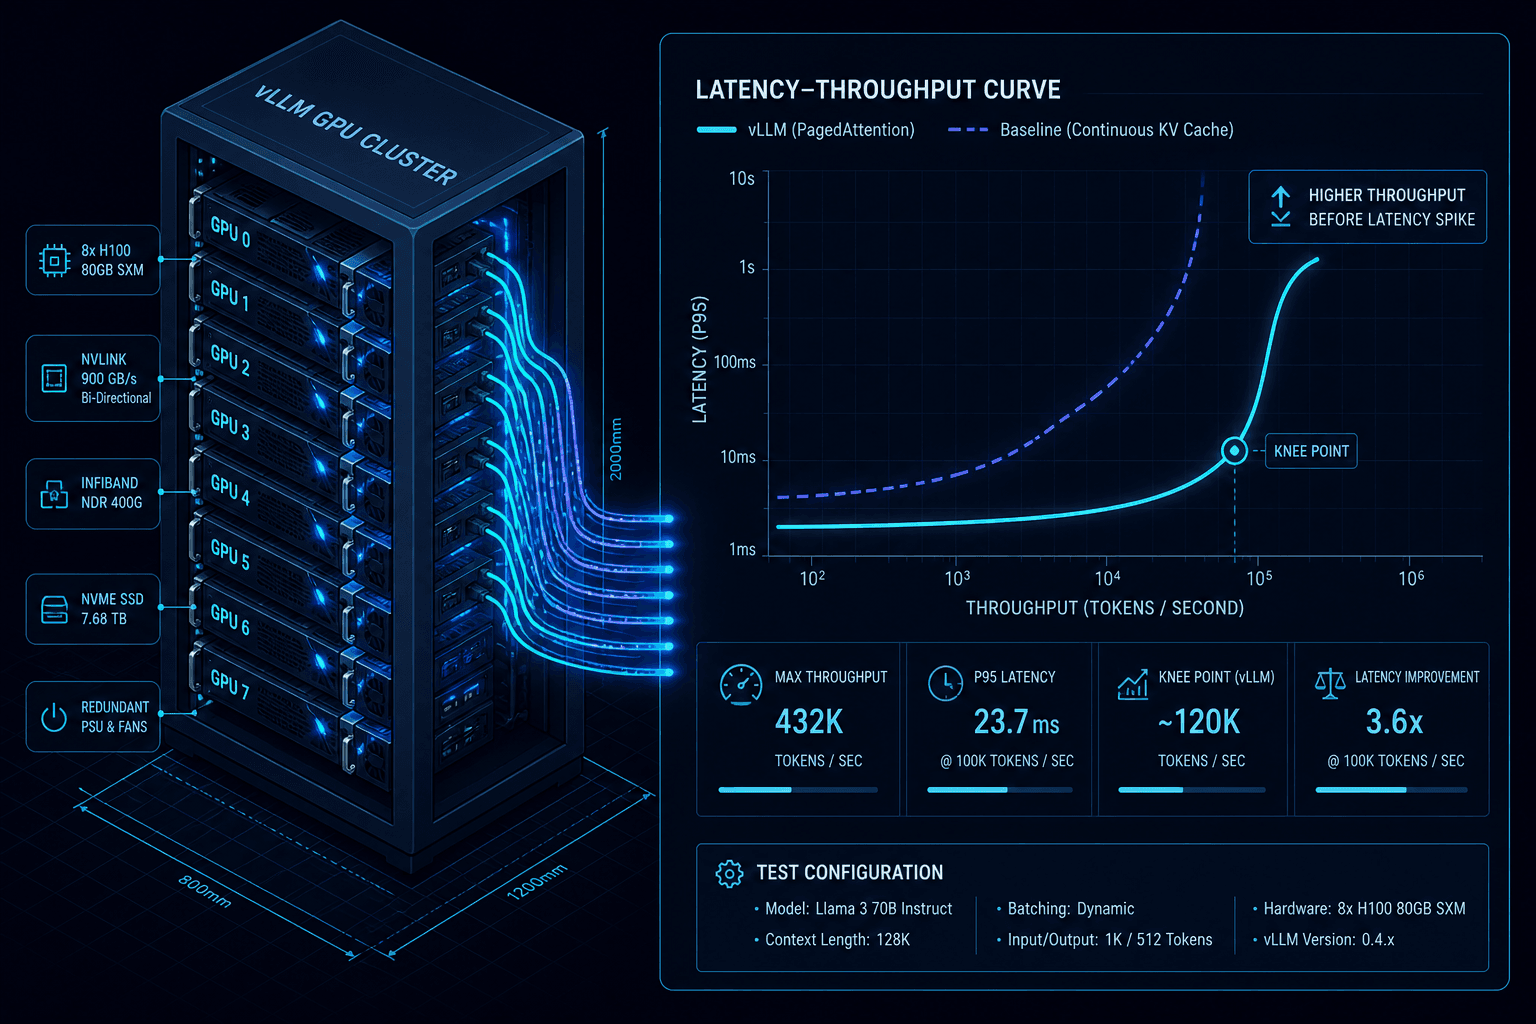
Part 5 · Agentic RAG PatternsLearn how to effectively benchmark and load-test your vLLM deployment. This guide covers throughput, latency curves, and capacity planning strategies.
Part 8 · Production vLLMUnderstanding TTFT, TPOT, and p99 is essential for optimizing LLM inference. This guide breaks down these metrics for SREs and backend developers.
Part 6 · LLM Inference from Scratch