6 min readDevelopment
SGLang's RadixAttention, Explained
Explore how SGLang uses RadixAttention and prefix caching to significantly boost throughput and efficiency in large language model serving.
Tag
Read 2 articles on Radixattention by Ashish Srivastava — practical guides covering implementation patterns, security, and production lessons.
2 posts
Explore how SGLang uses RadixAttention and prefix caching to significantly boost throughput and efficiency in large language model serving.
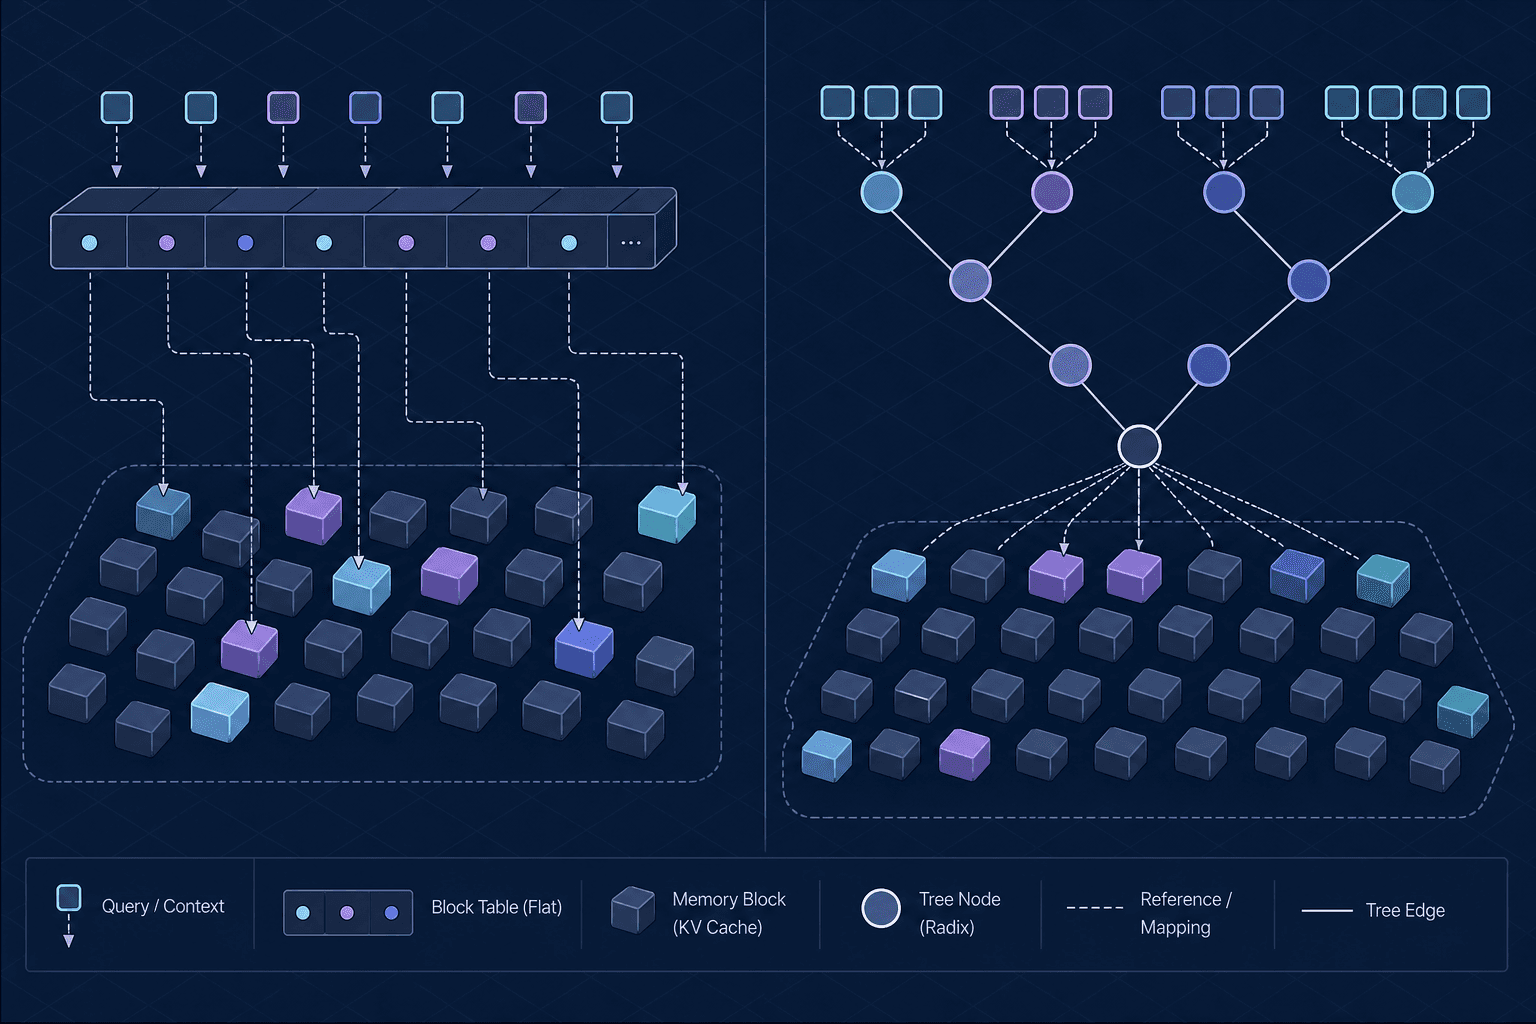
An examination of PagedAttention and RadixAttention mechanisms. We explore how they handle KV cache memory fragmentation and enable efficient context sharing in large language models.
Part 3 · Production vLLM