6 min readDevelopmentFeatured
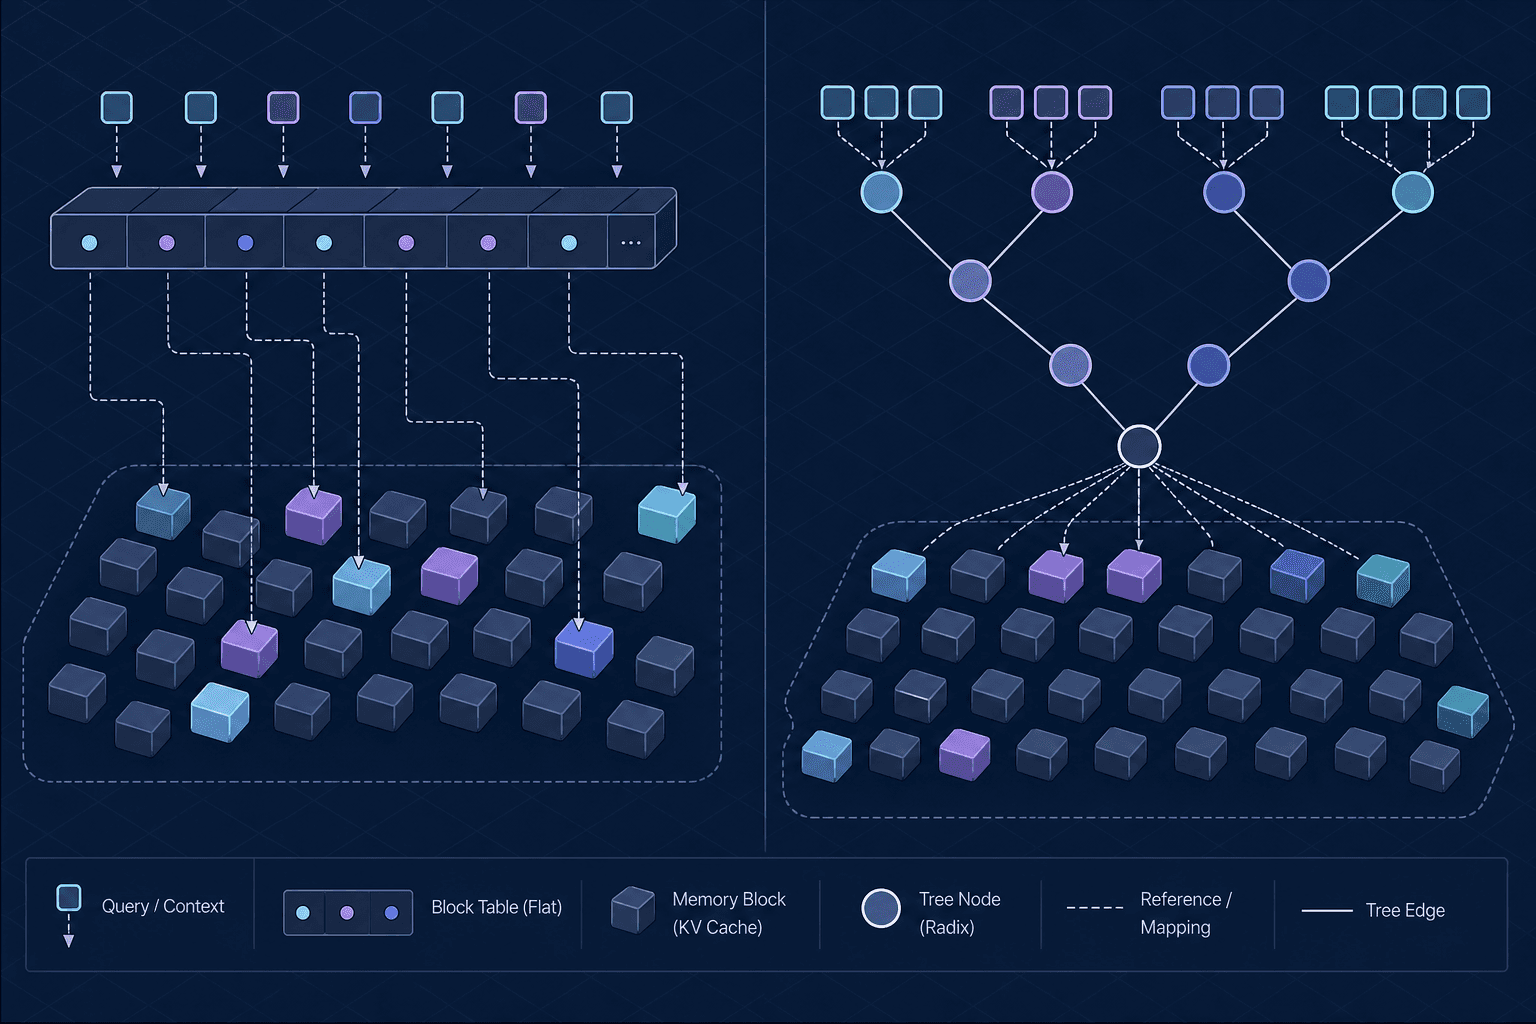
PagedAttention vs RadixAttention: Solving KV Cache Fragmentation and Redundancy
An examination of PagedAttention and RadixAttention mechanisms. We explore how they handle KV cache memory fragmentation and enable efficient context sharing in large language models.
Part 3 · Production vLLM