Unsloth: Fine-Tuning 2x Faster on One GPU
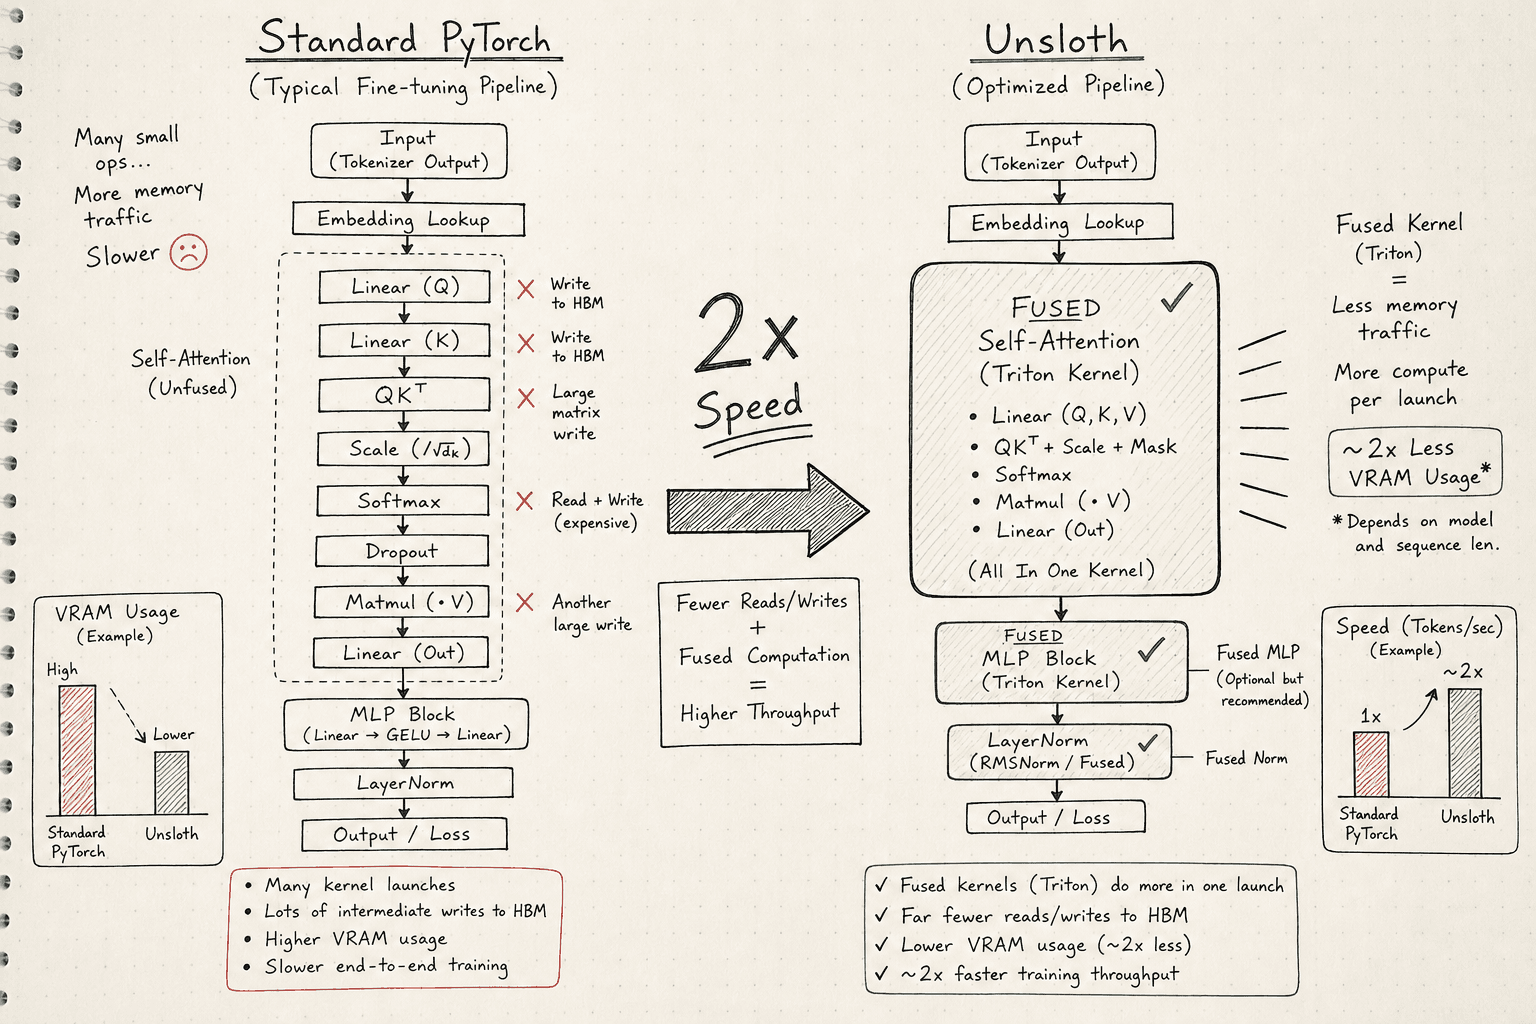
Discover how Unsloth leverages Triton kernels and LoRA to double fine-tuning speed, making advanced model training accessible on a single GPU.
Part 10 · Fine-Tuning LLMs Hands-OnTag
Read 9 articles on Fine Tuning by Ashish Srivastava — practical guides covering implementation patterns, security, and production lessons.
9 posts
Discover how Unsloth leverages Triton kernels and LoRA to double fine-tuning speed, making advanced model training accessible on a single GPU.
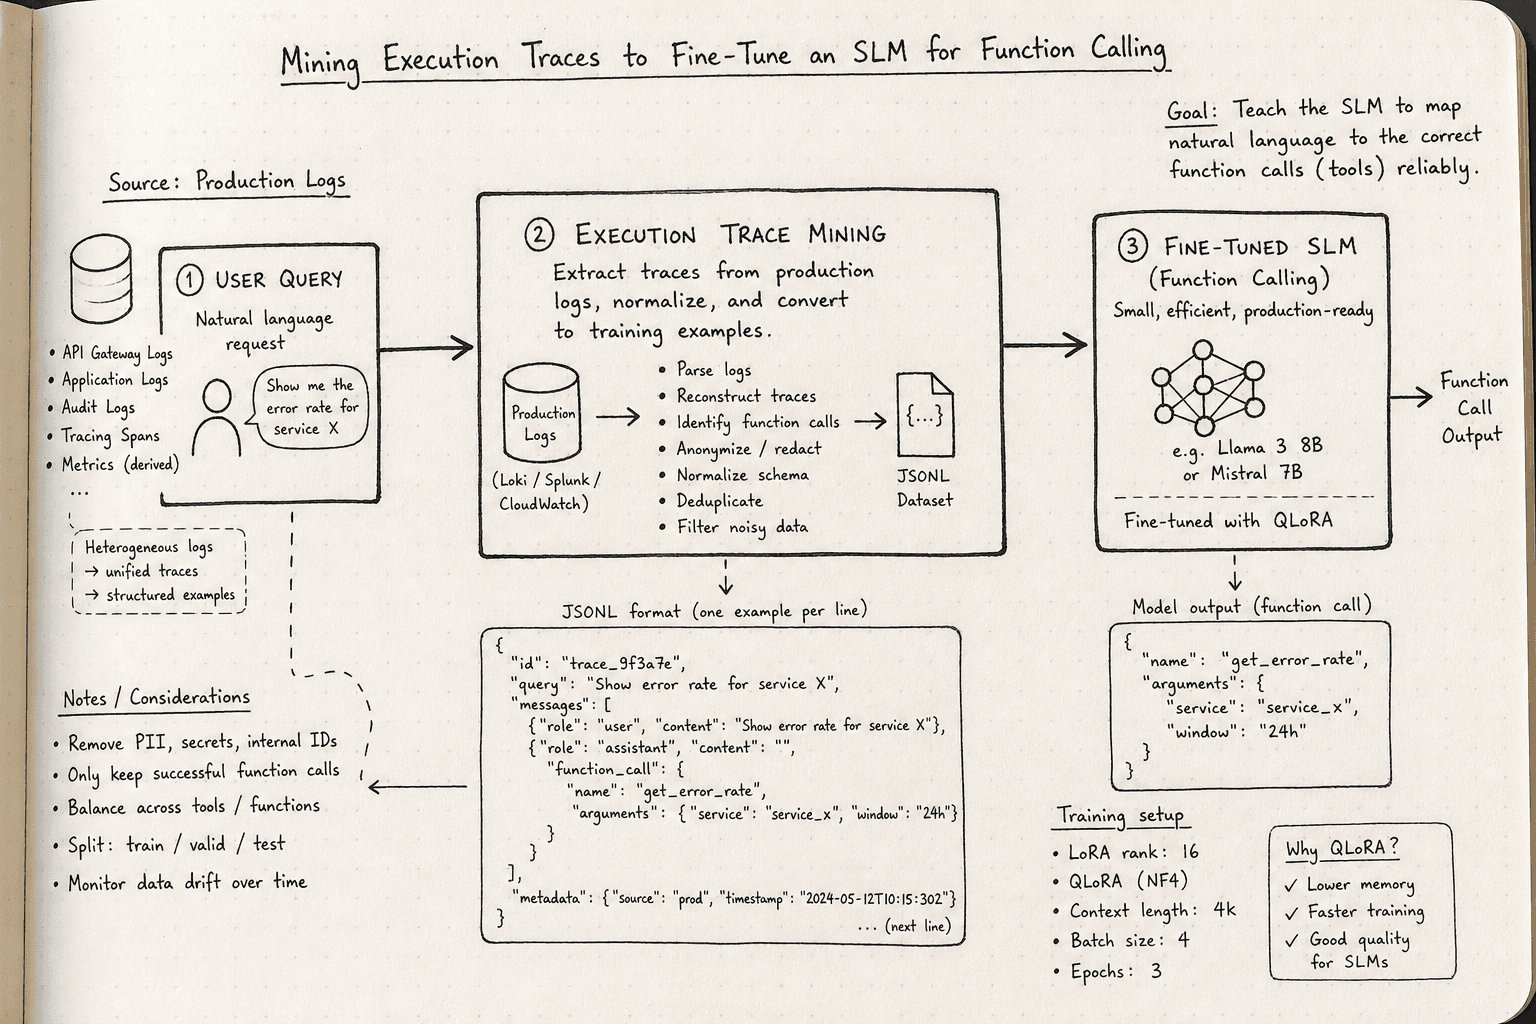
Part 10 · Fine-Tuning LLMs Hands-OnA practical guide to improving tool-use reliability in small models through function-calling fine-tuning and trace mining techniques.
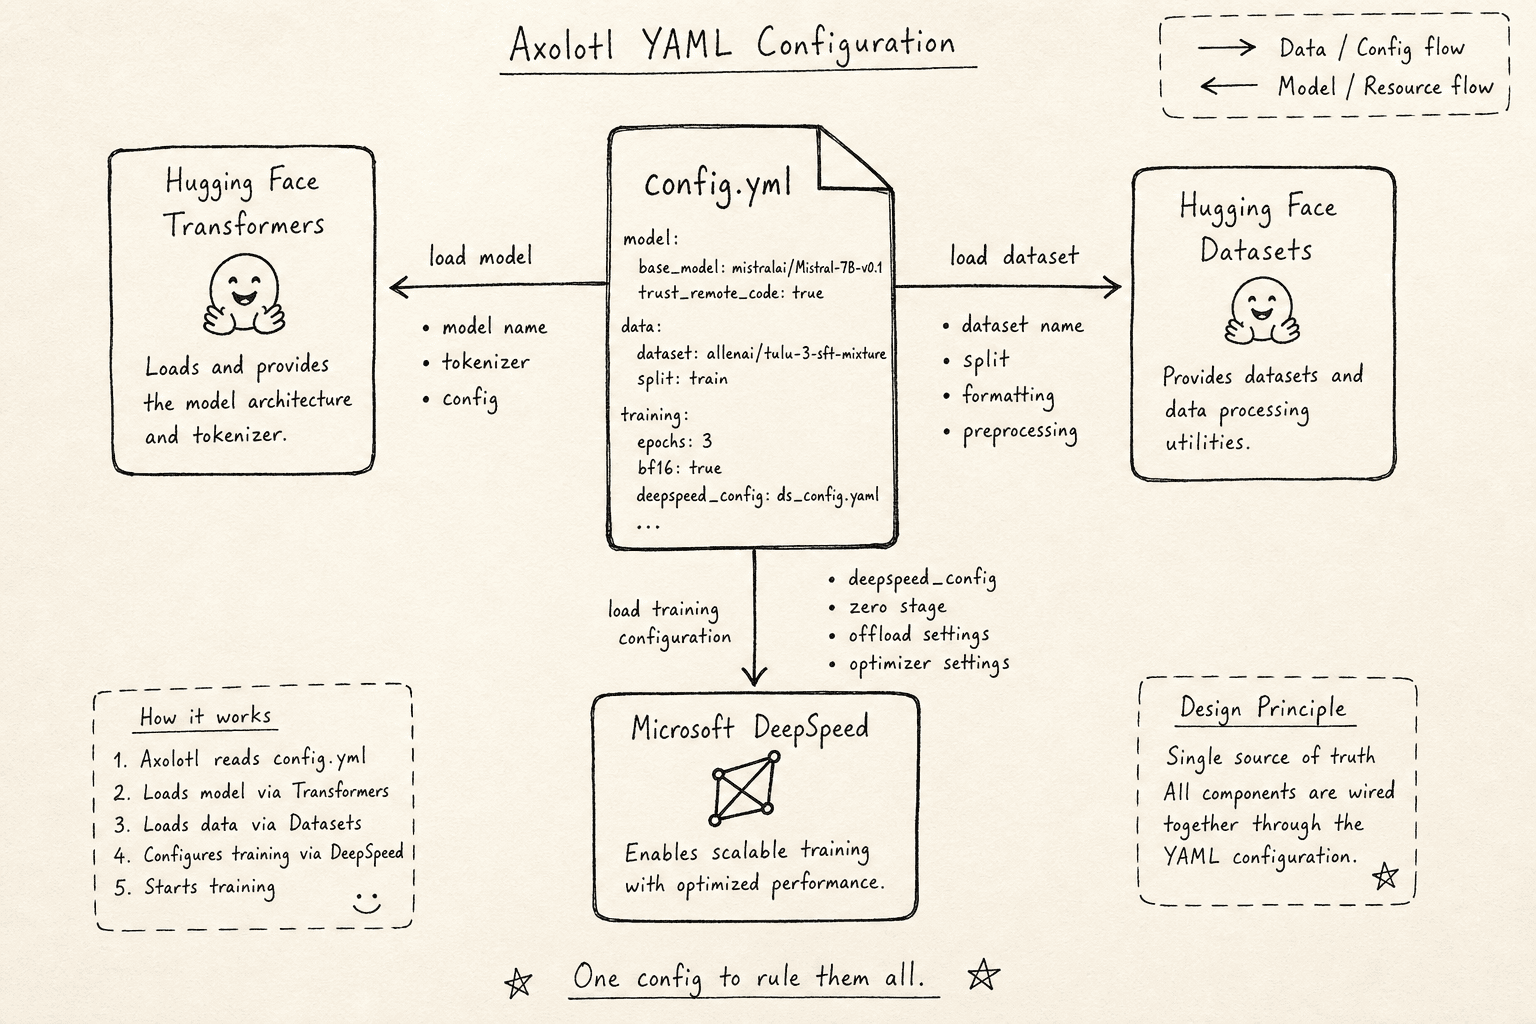
Understand every line of an Axolotl config file. Learn how to structure YAML for fine-tuning, DeepSpeed integration, and dataset formatting.
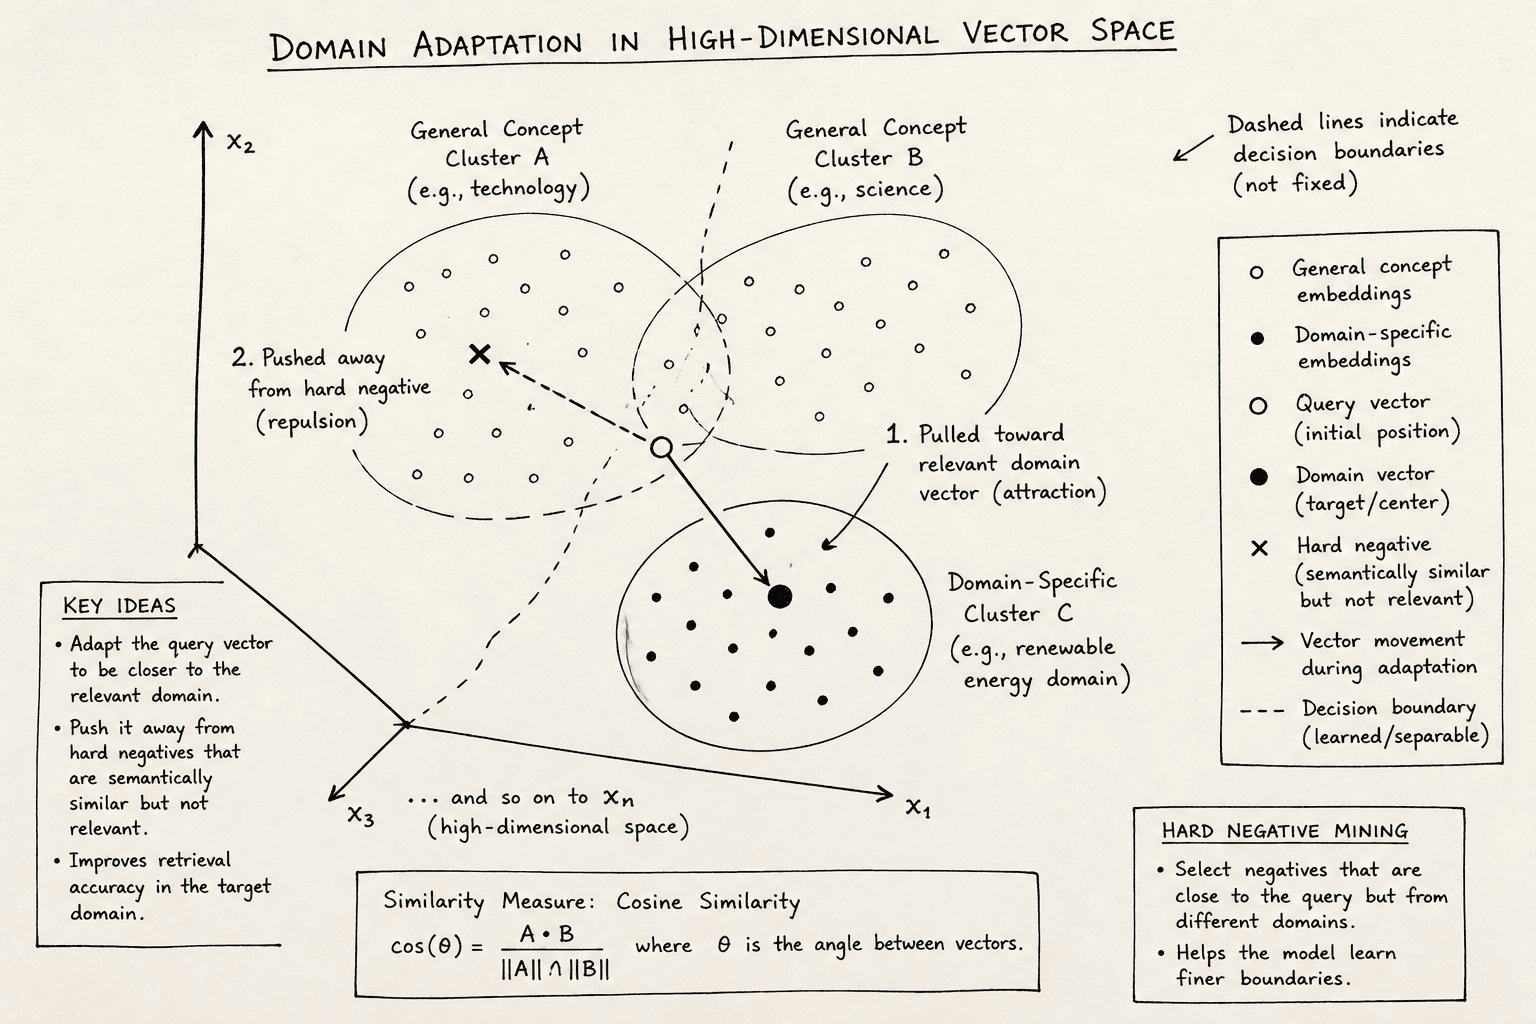
Part 9 · Fine-Tuning LLMs Hands-OnLearn how to adapt pre-trained sentence transformers to specific domains by leveraging hard negatives and contrastive loss functions for better retrieval accuracy.
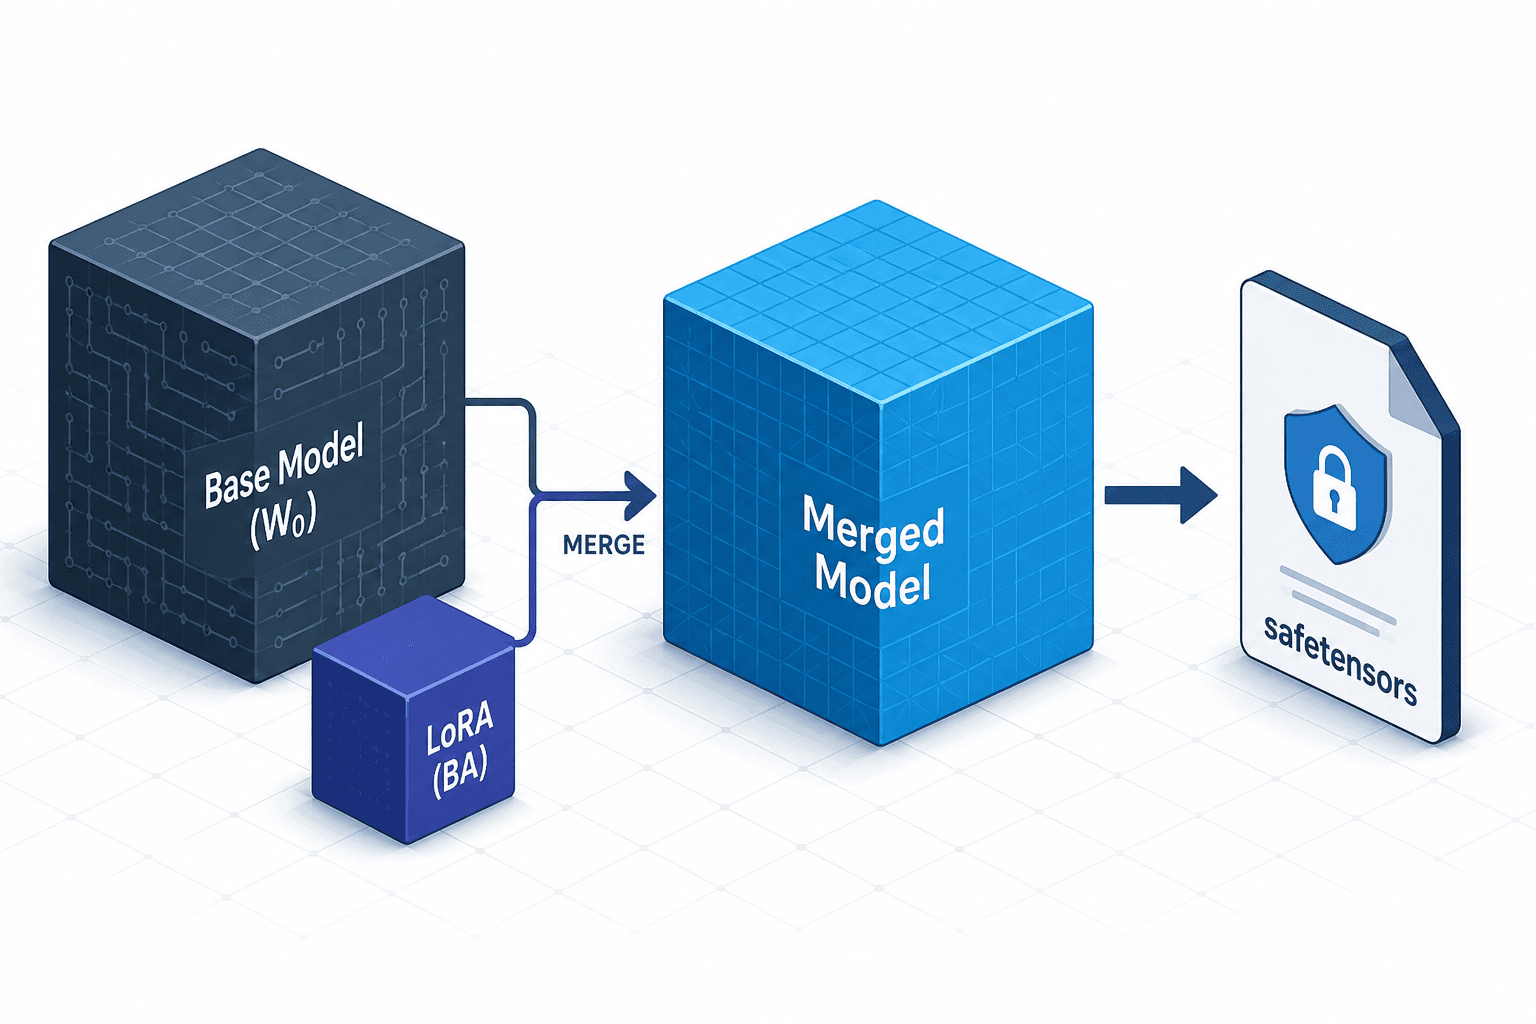
Learn how to merge LoRA adapters, export weights to safetensors, and configure serving environments with appropriate dtypes for production deployment.
Part 8 · Fine-Tuning LLMs Hands-OnLearn how to rigorously evaluate fine-tuned LLMs against their base counterparts using held-out datasets and regression testing strategies.
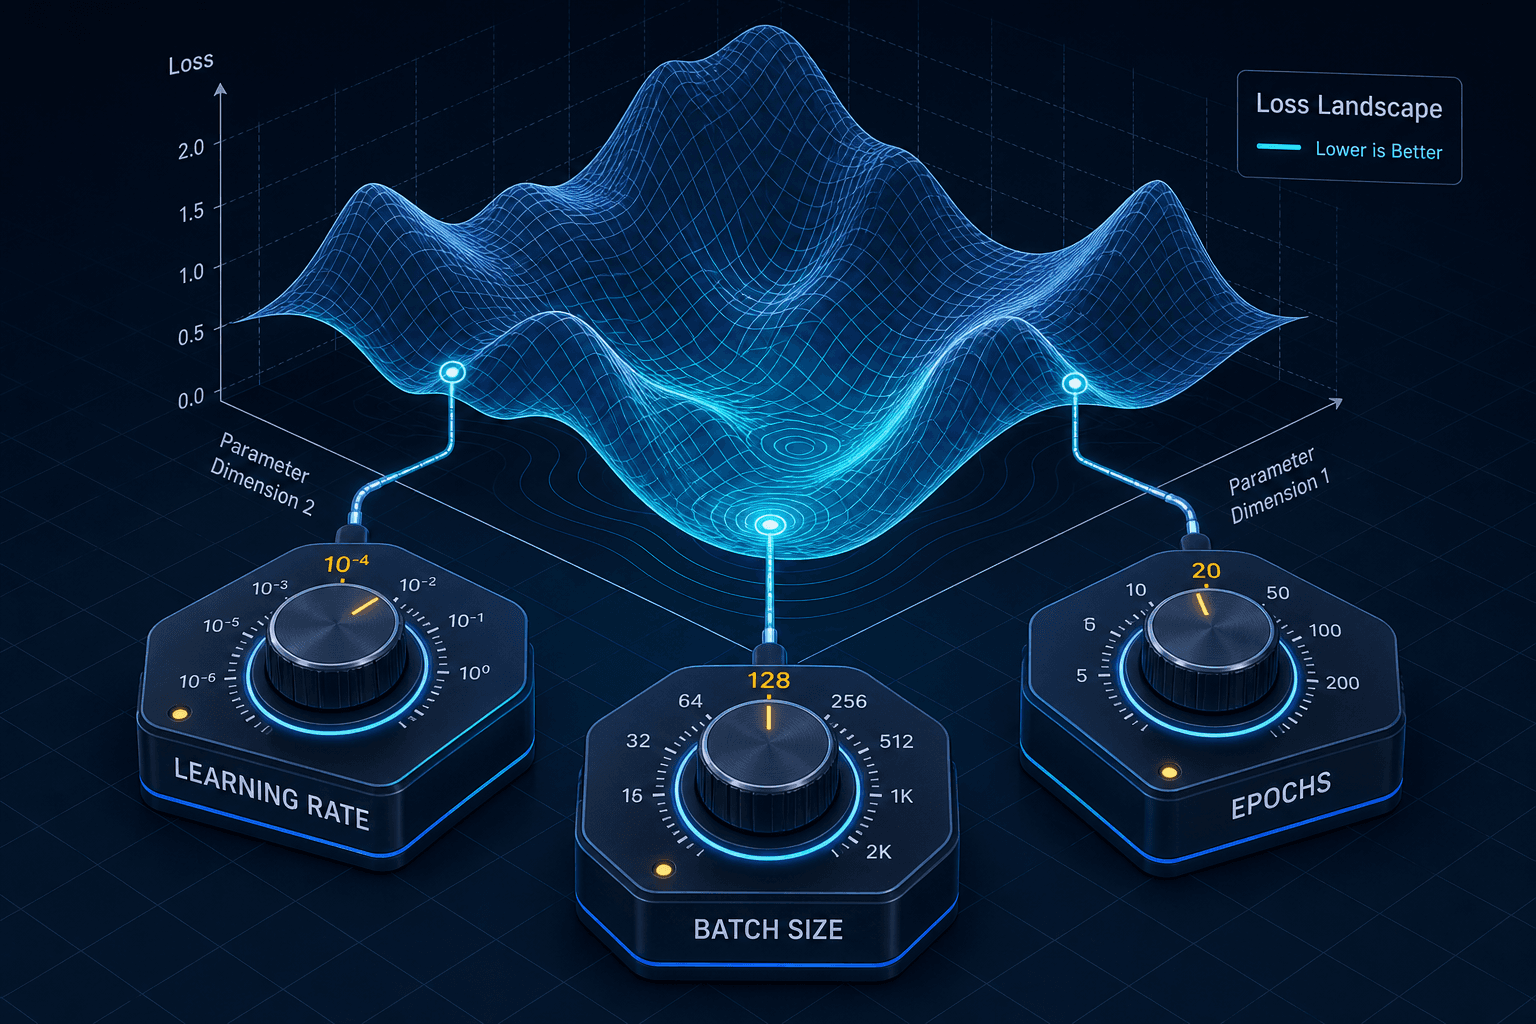
Part 7 · Fine-Tuning LLMs Hands-OnFocus on the hyperparameters that drive model performance: learning rate, batch size, and epochs. A guide for ML engineers.
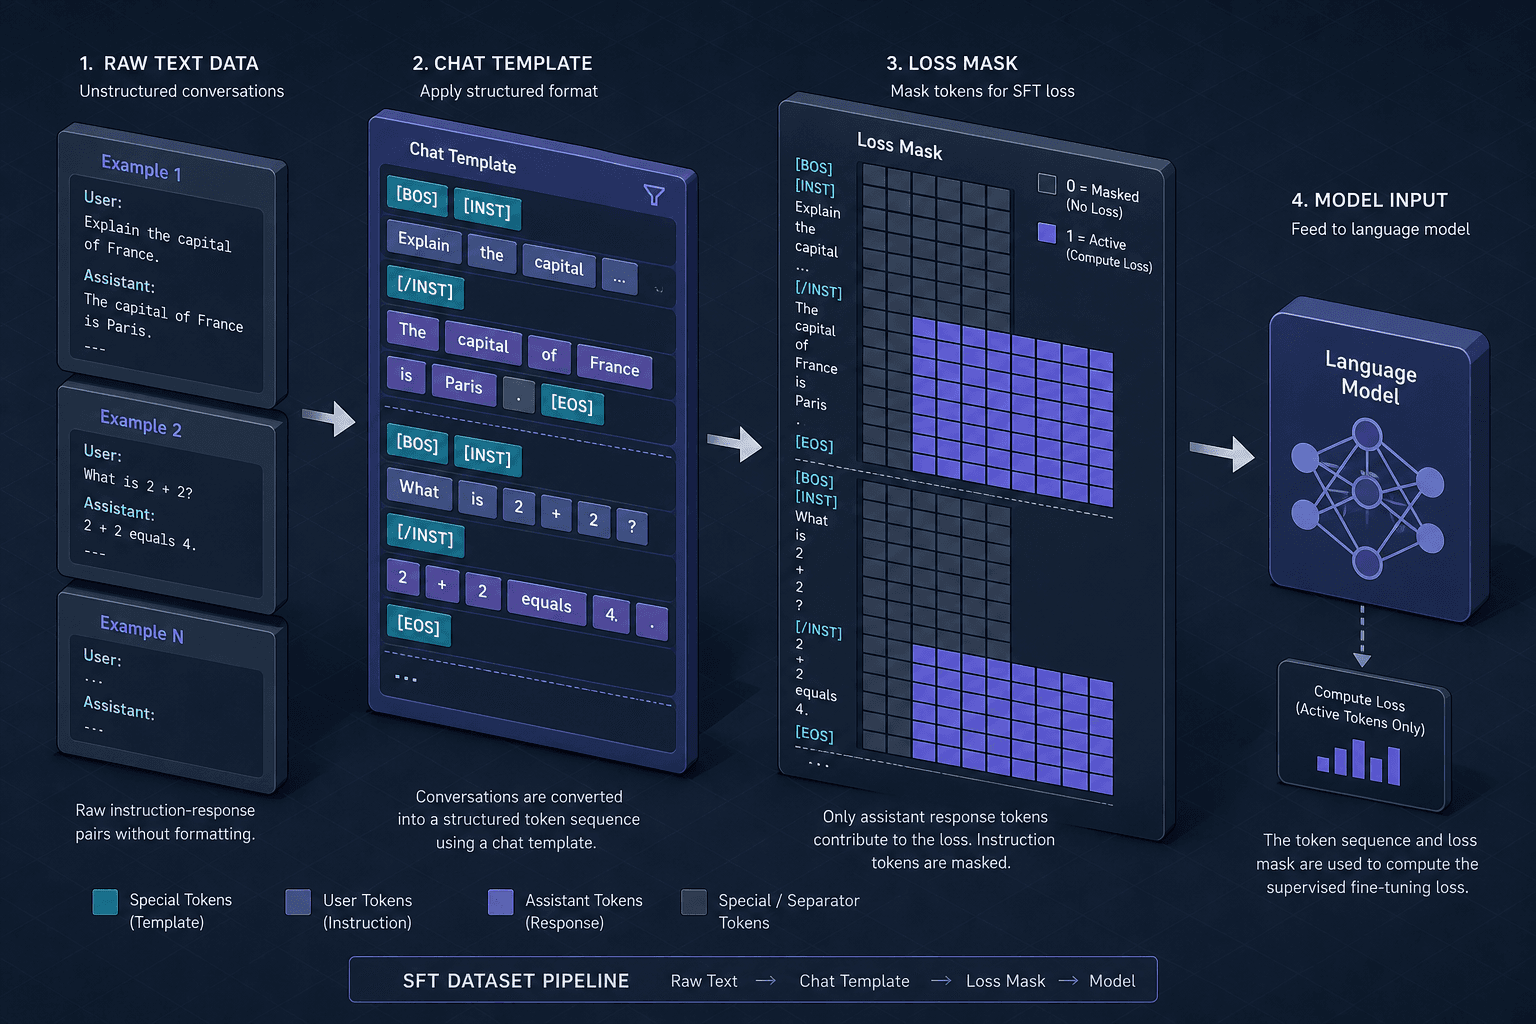
Part 6 · Fine-Tuning LLMs Hands-OnLearn how to build effective supervised fine-tuning datasets. This guide covers instruction formatting, chat templates, loss masking techniques, and ensuring data quality for LLM training.
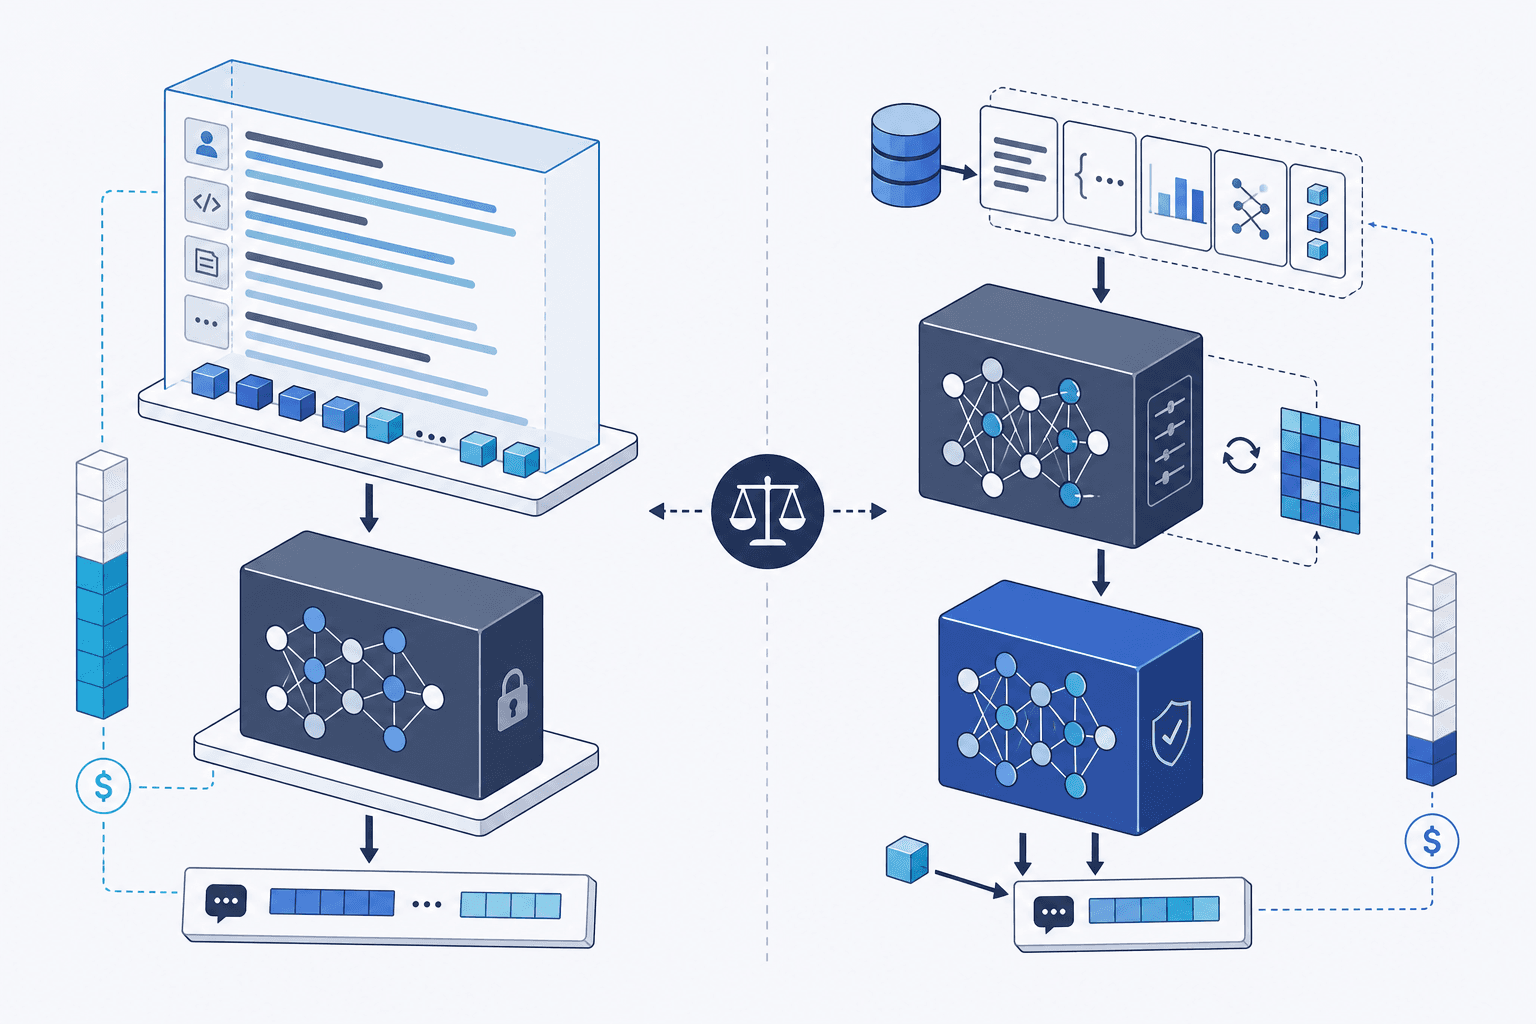
Part 5 · Fine-Tuning LLMs Hands-OnShould you fine-tune? This decision framework helps ML engineers and engineering managers choose between fine-tuning and prompting based on cost, data, and performance needs.
Part 1 · Fine-Tuning LLMs Hands-On