6 min readDevelopmentFeatured
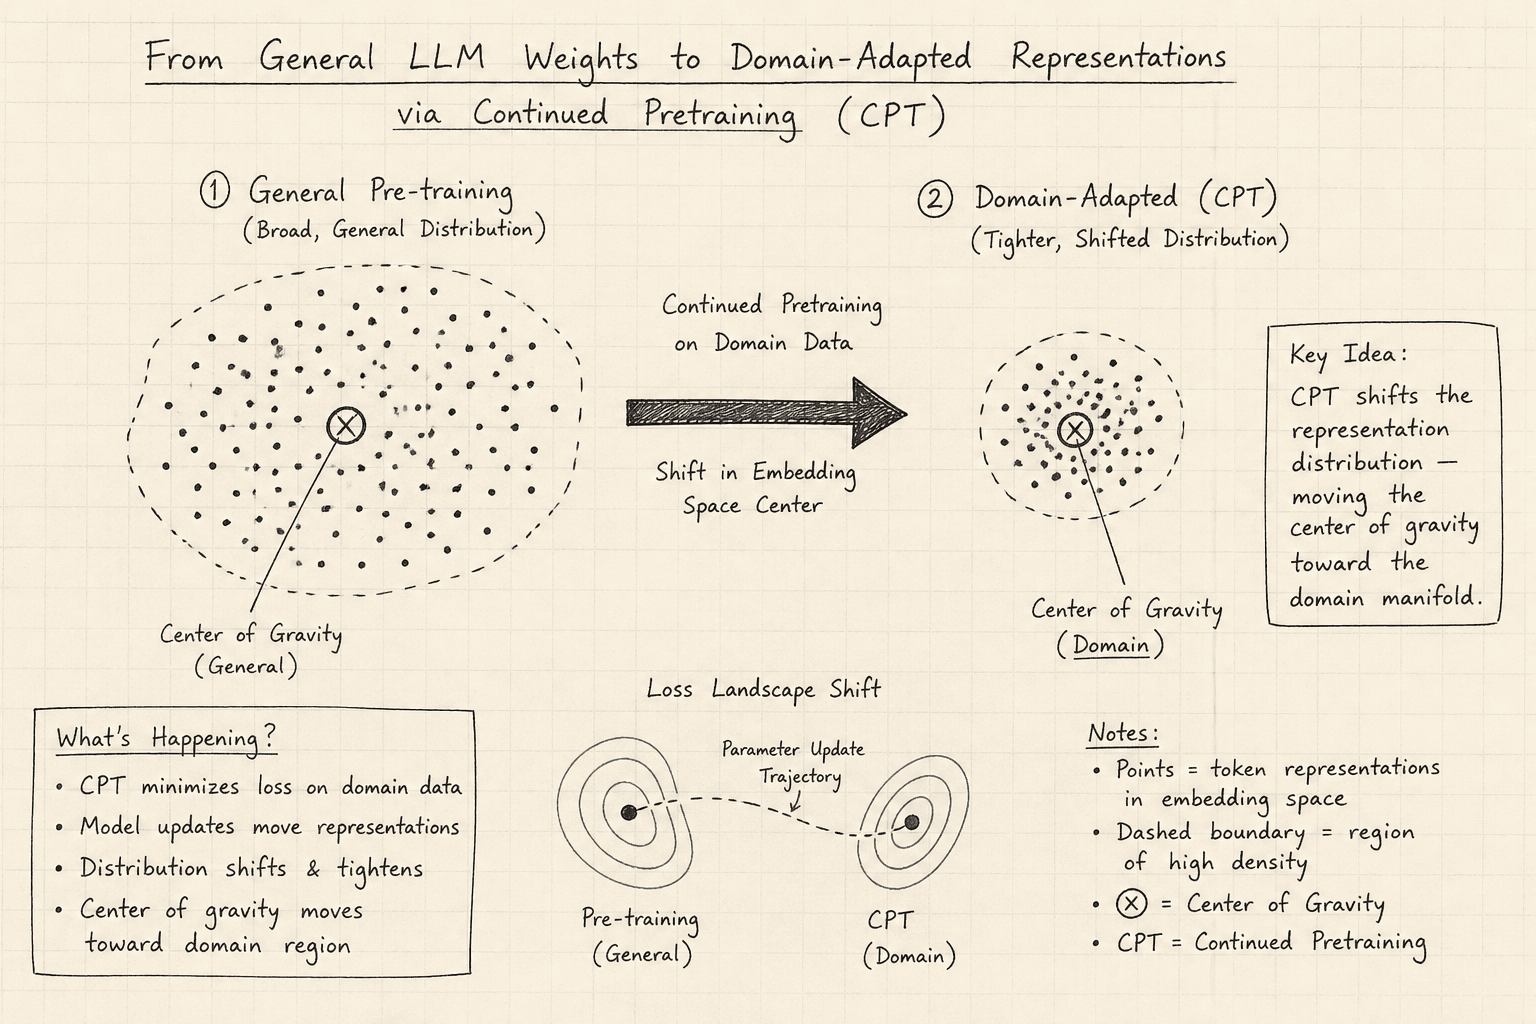
Continued Pretraining for Domain Adaptation
A technical overview of continued pretraining strategies for domain adaptation, covering corpus mixing, CPT, and drift mitigation.
Tag
Read 13 articles on Nlp by Ashish Srivastava — practical guides covering implementation patterns, security, and production lessons.
13 posts
A technical overview of continued pretraining strategies for domain adaptation, covering corpus mixing, CPT, and drift mitigation.
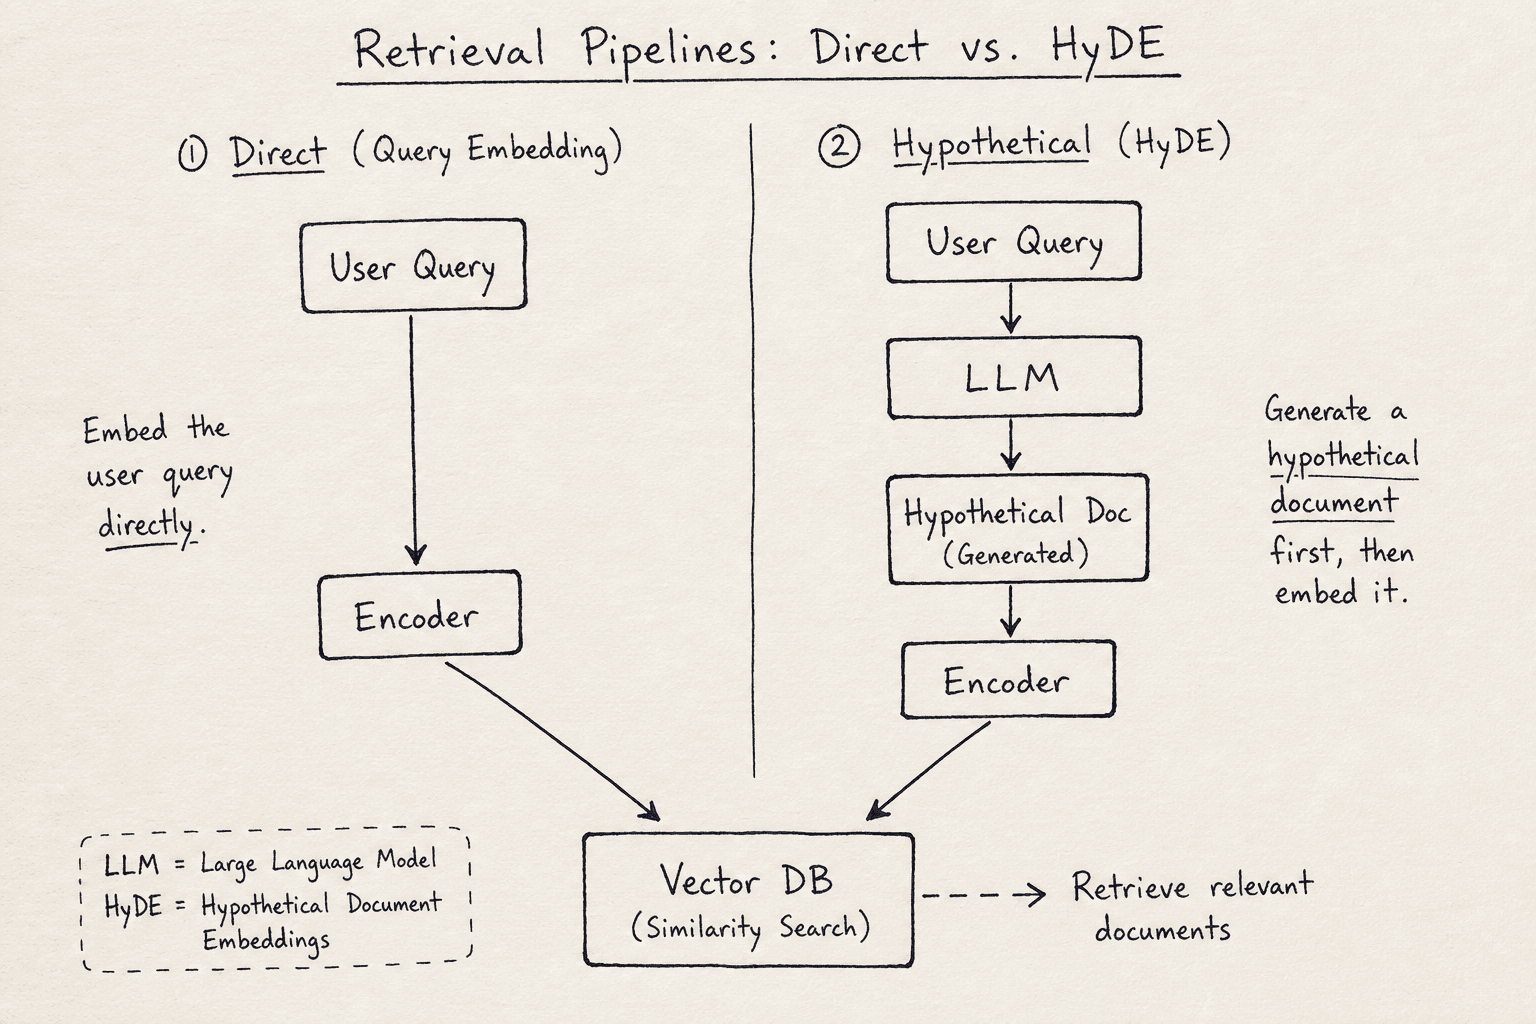
We test HyDE and query expansion against current baselines to see if these methods still provide a significant boost to retrieval accuracy.
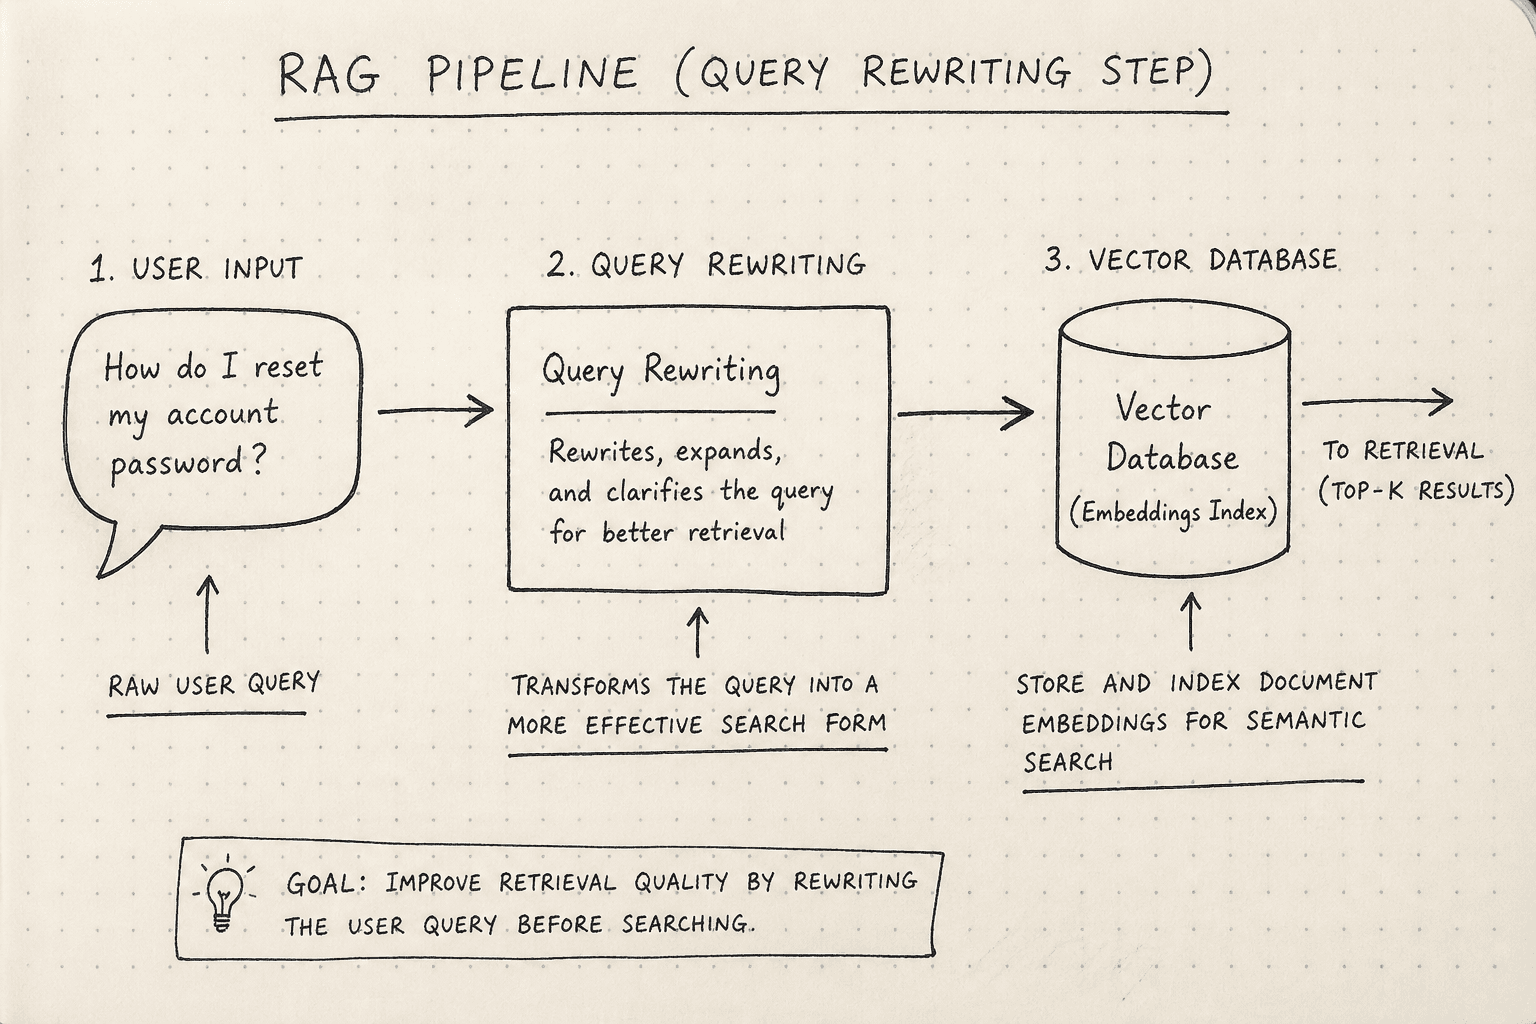
Query rewriting is a critical yet often overlooked step in RAG pipelines. Learn how to boost recall and handle conversational context effectively.
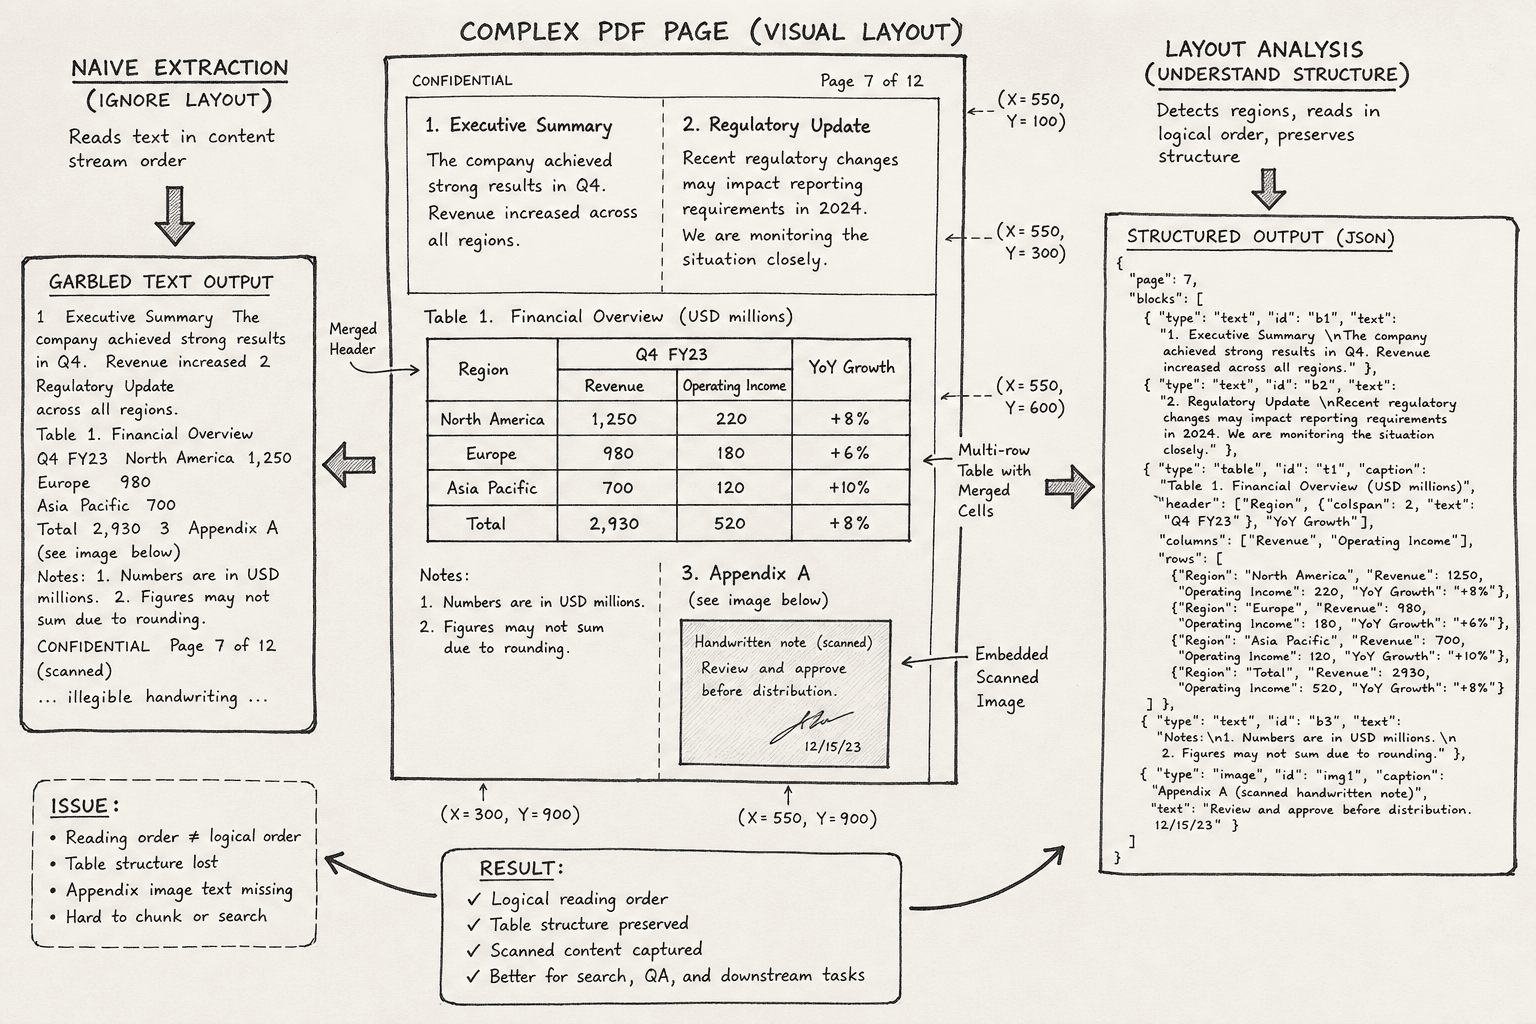
Part 9 · RAG from Zero to ProductionLearn how to handle difficult PDF structures like tables, multi-column layouts, and scanned documents during the chunking process.
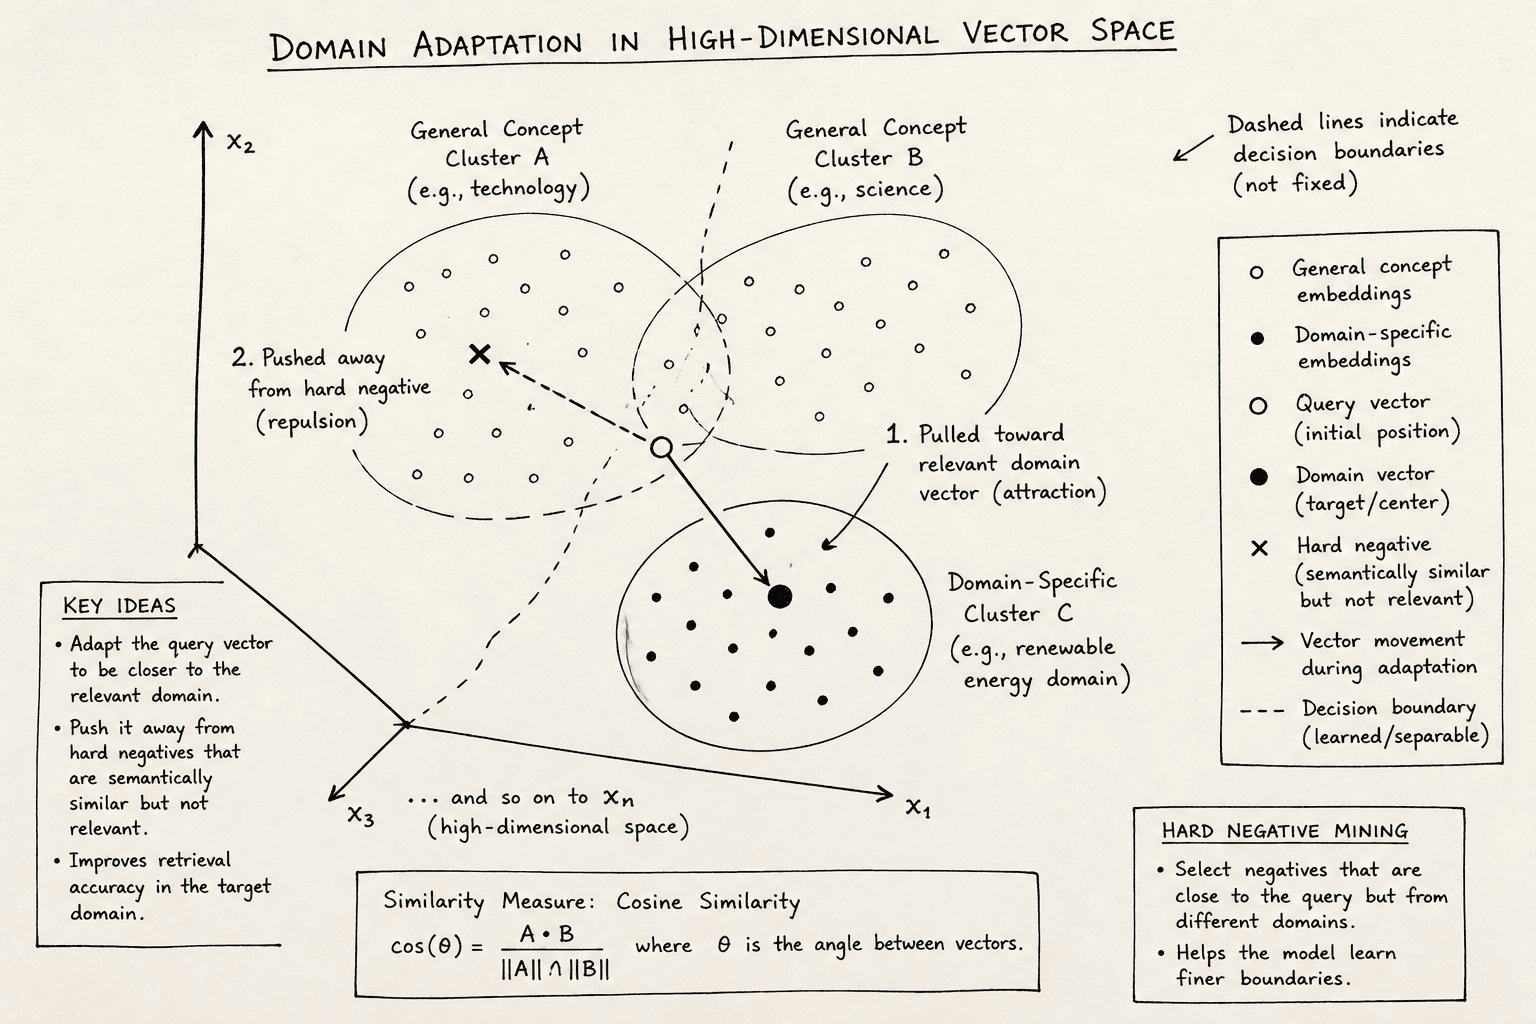
Learn how to adapt pre-trained sentence transformers to specific domains by leveraging hard negatives and contrastive loss functions for better retrieval accuracy.
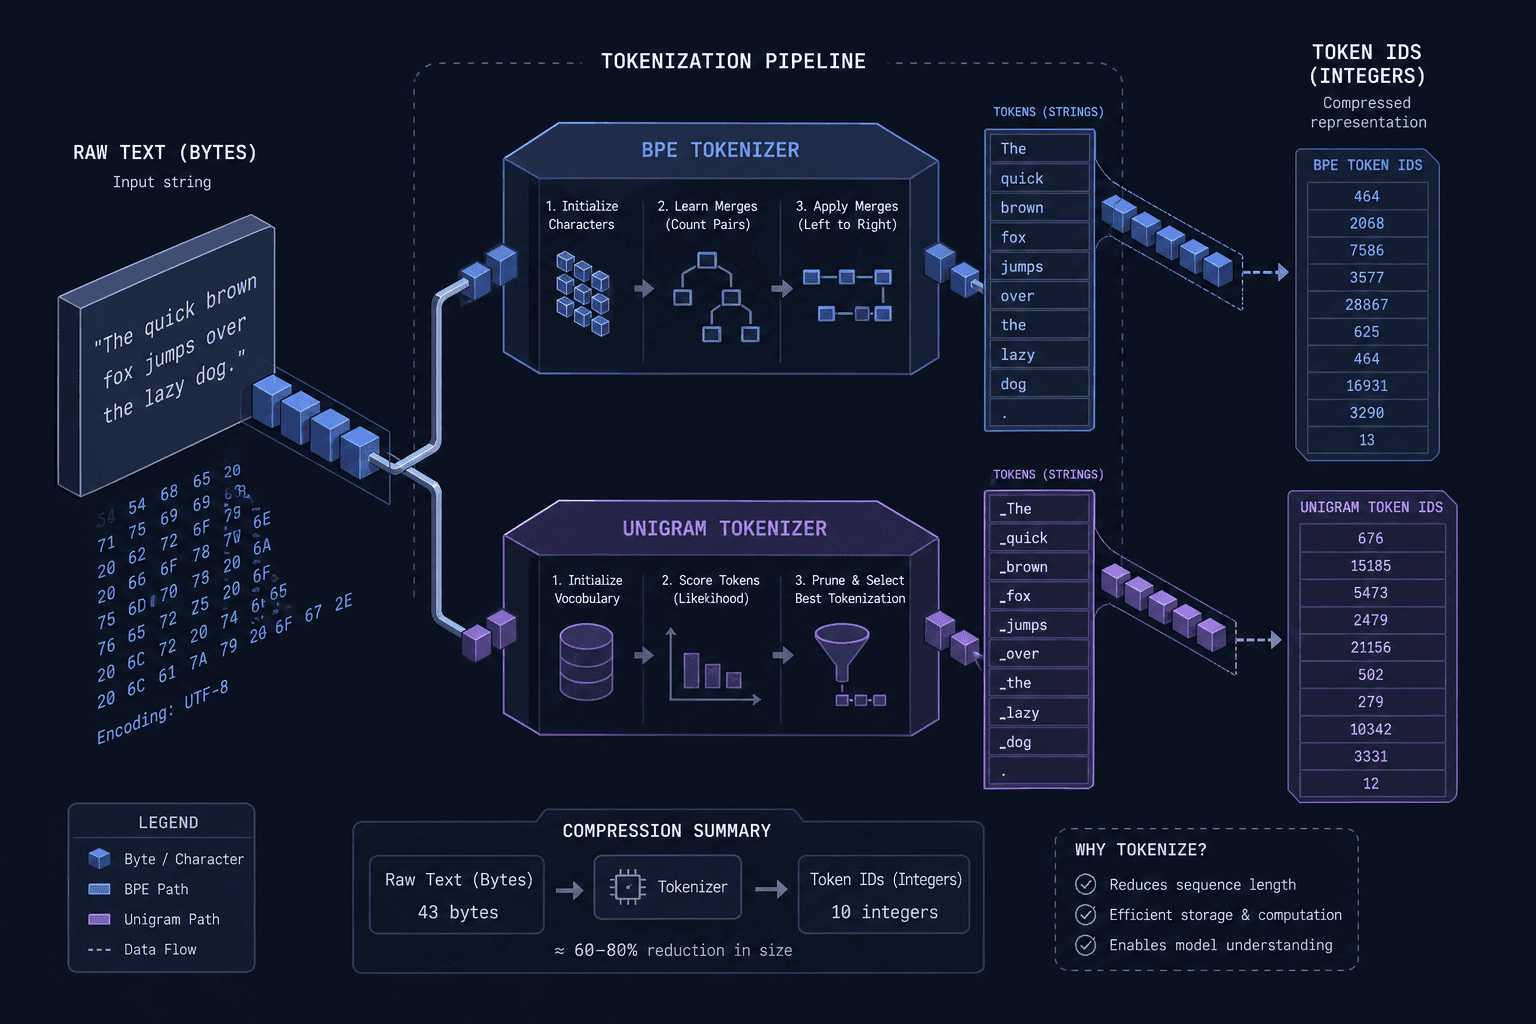
Explore how BPE and Unigram tokenization work in practice, why SentencePiece is popular, and the specific failure modes like glitch tokens that developers need to watch for.
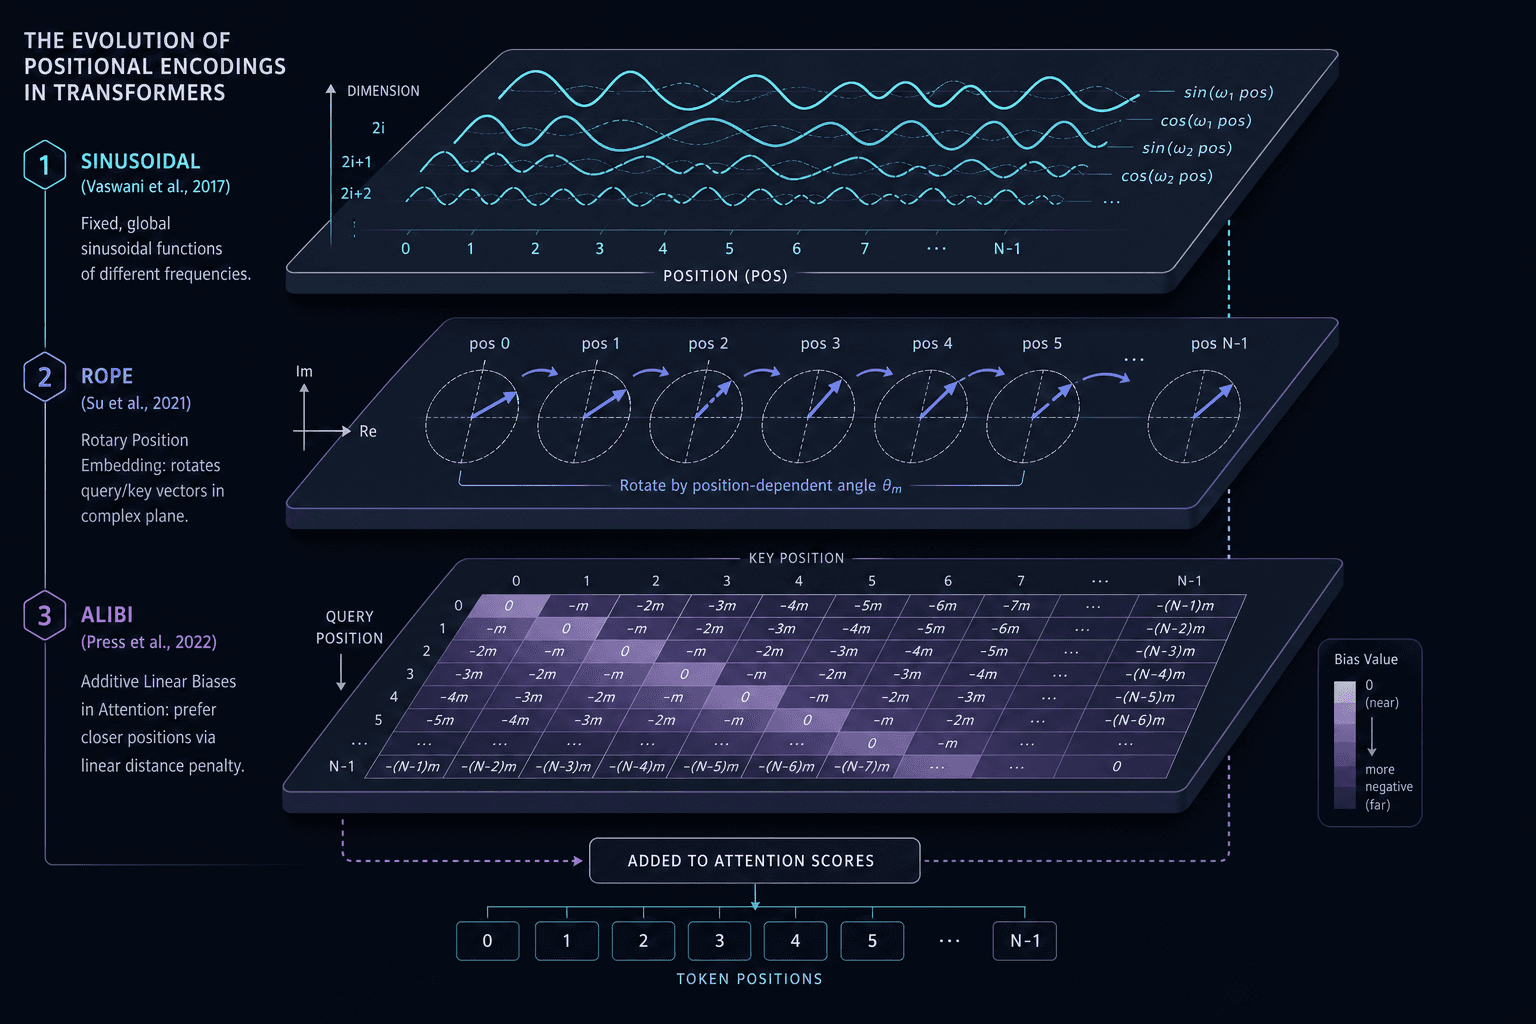
Part 6 · Transformers Under the HoodExplore how Sinusoidal, RoPE, and ALiBi positional encodings enable transformers to handle long contexts and extend sequence lengths effectively.
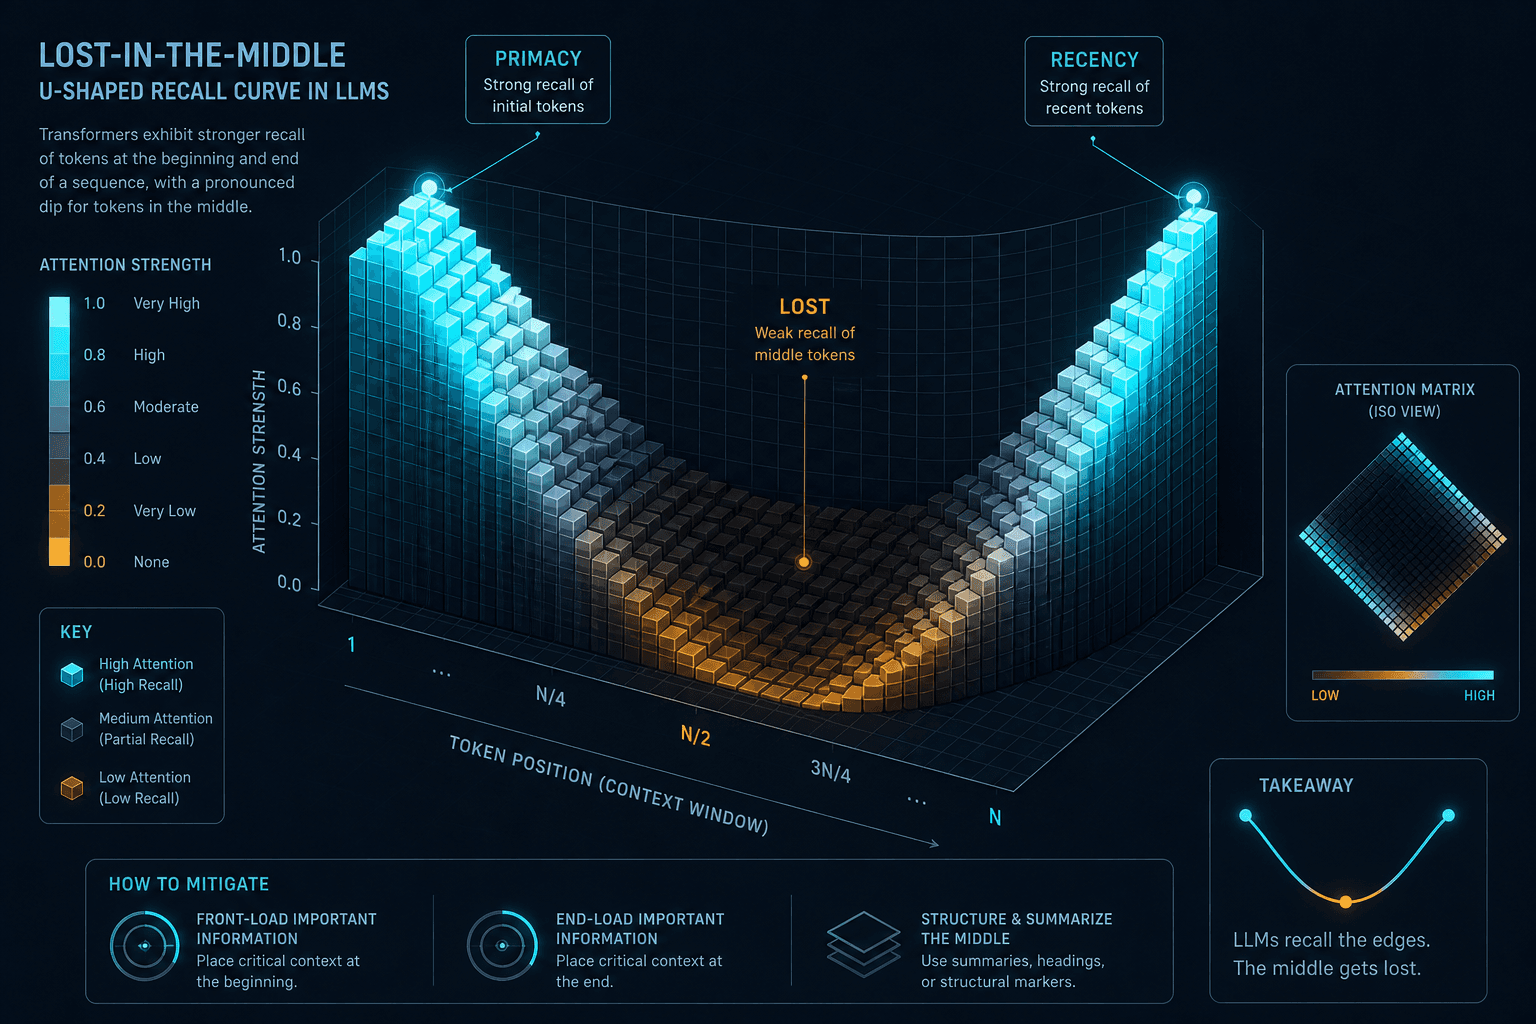
Part 3 · Transformers Under the HoodLarge language models often struggle to retrieve information placed in the middle of long contexts. This article explores position bias and effective workarounds.
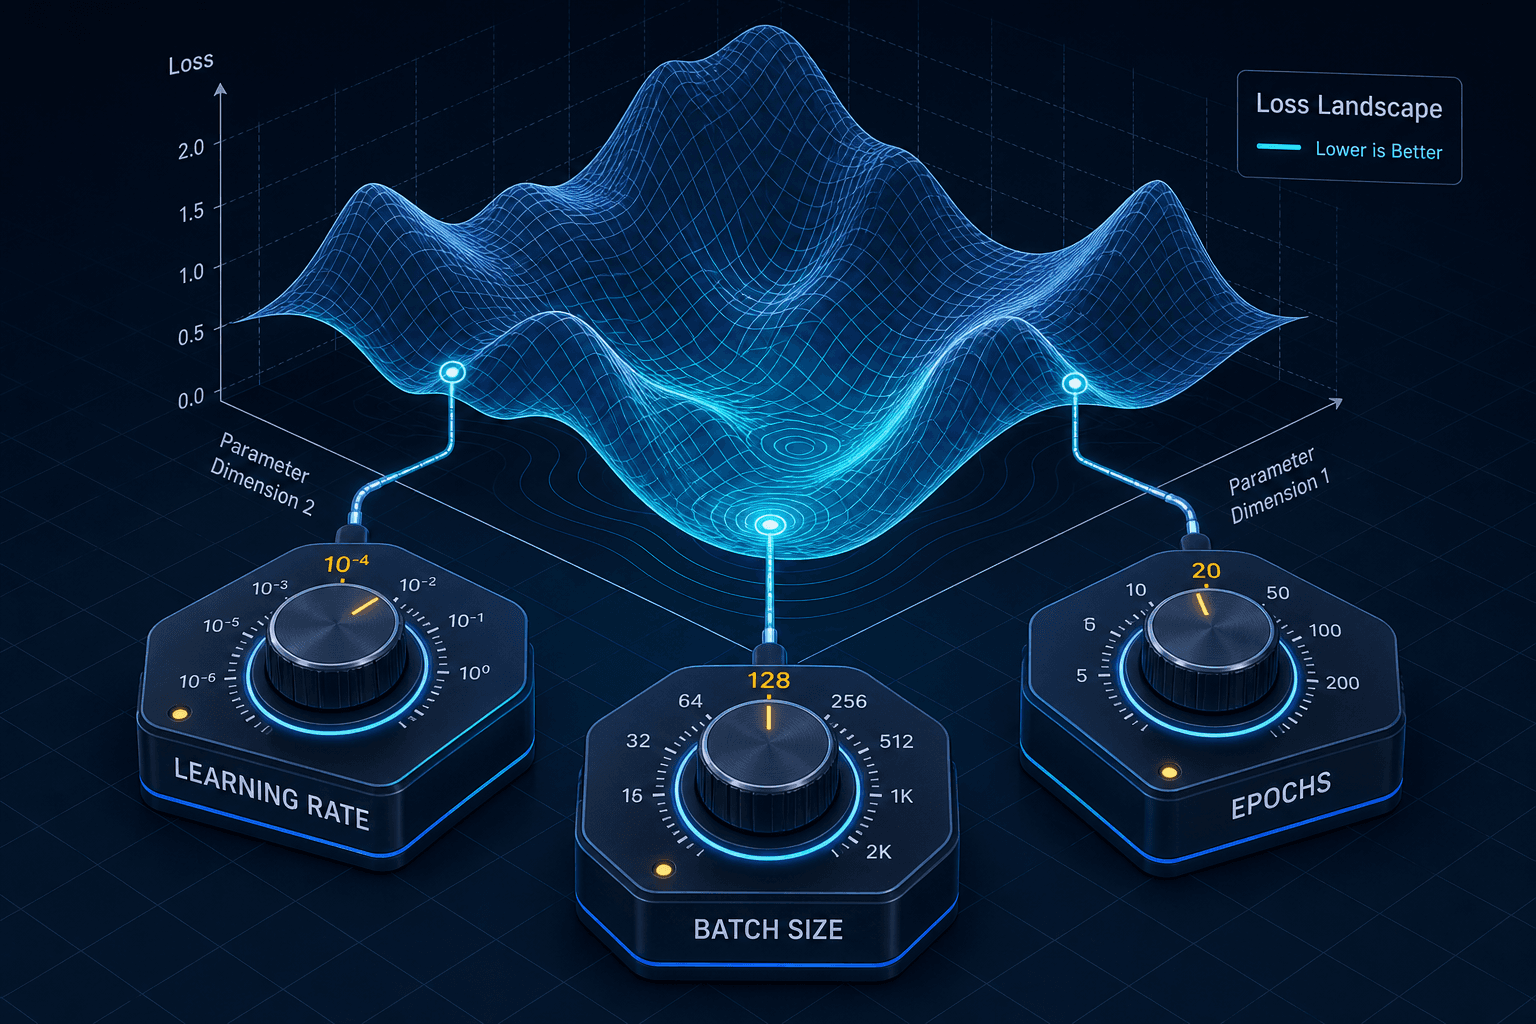
Part 2 · Context EngineeringFocus on the hyperparameters that drive model performance: learning rate, batch size, and epochs. A guide for ML engineers.
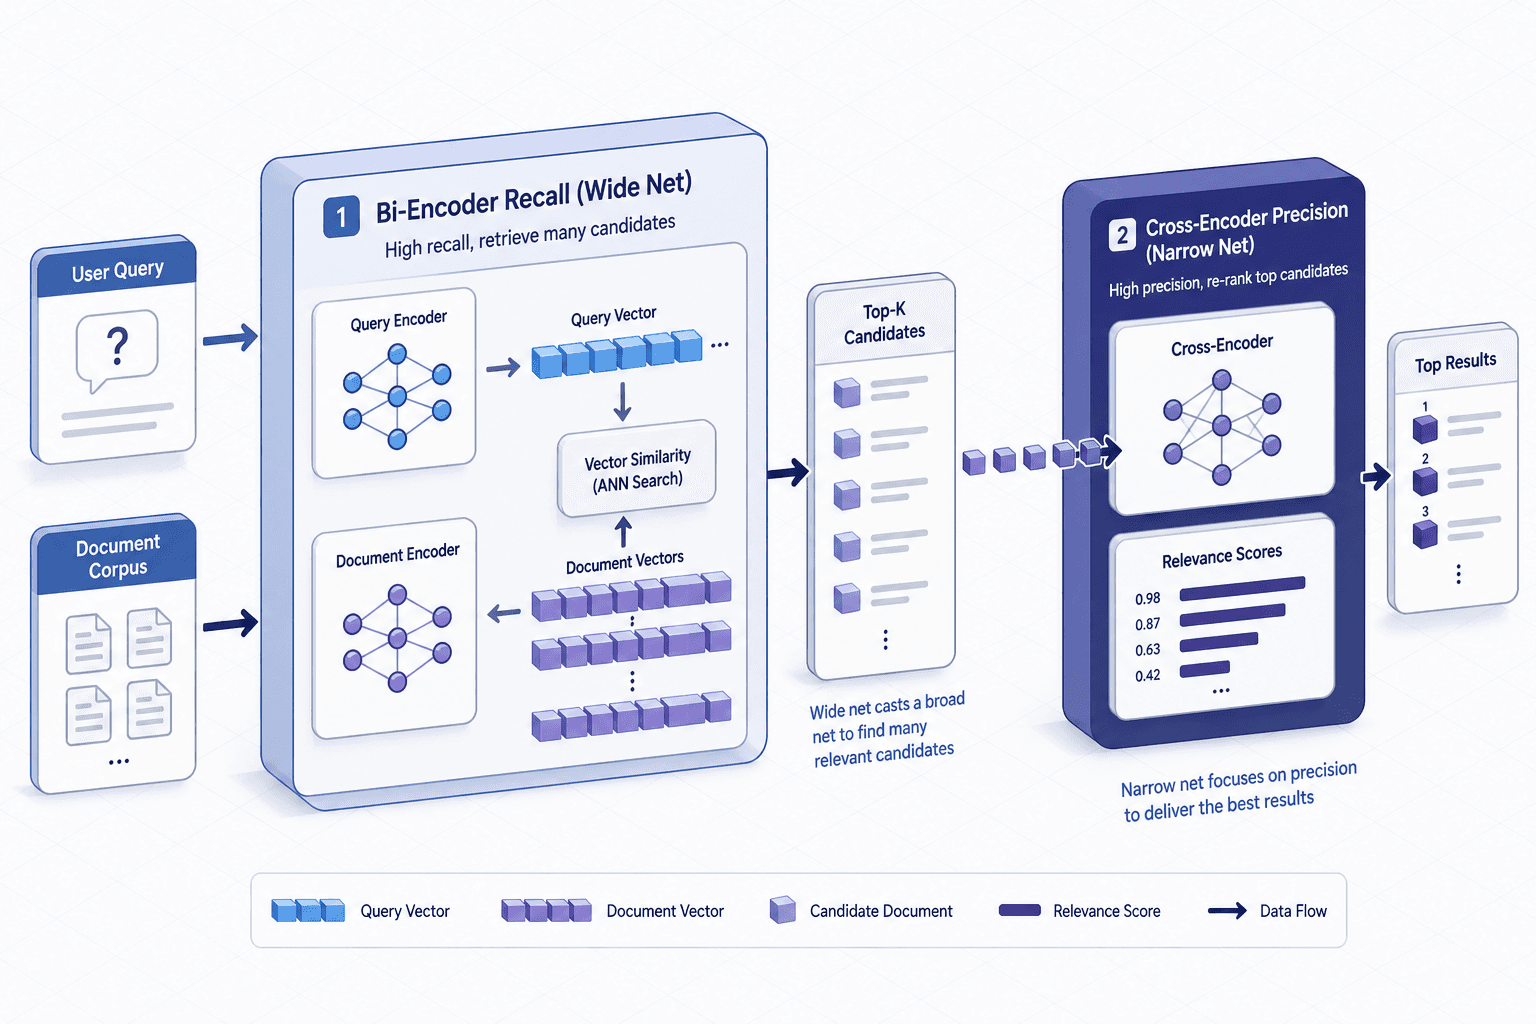
Part 6 · Fine-Tuning LLMs Hands-OnReranking is the most cost-effective way to boost RAG accuracy. Learn how to implement cross-encoders like Cohere and BGE for better retrieval results.
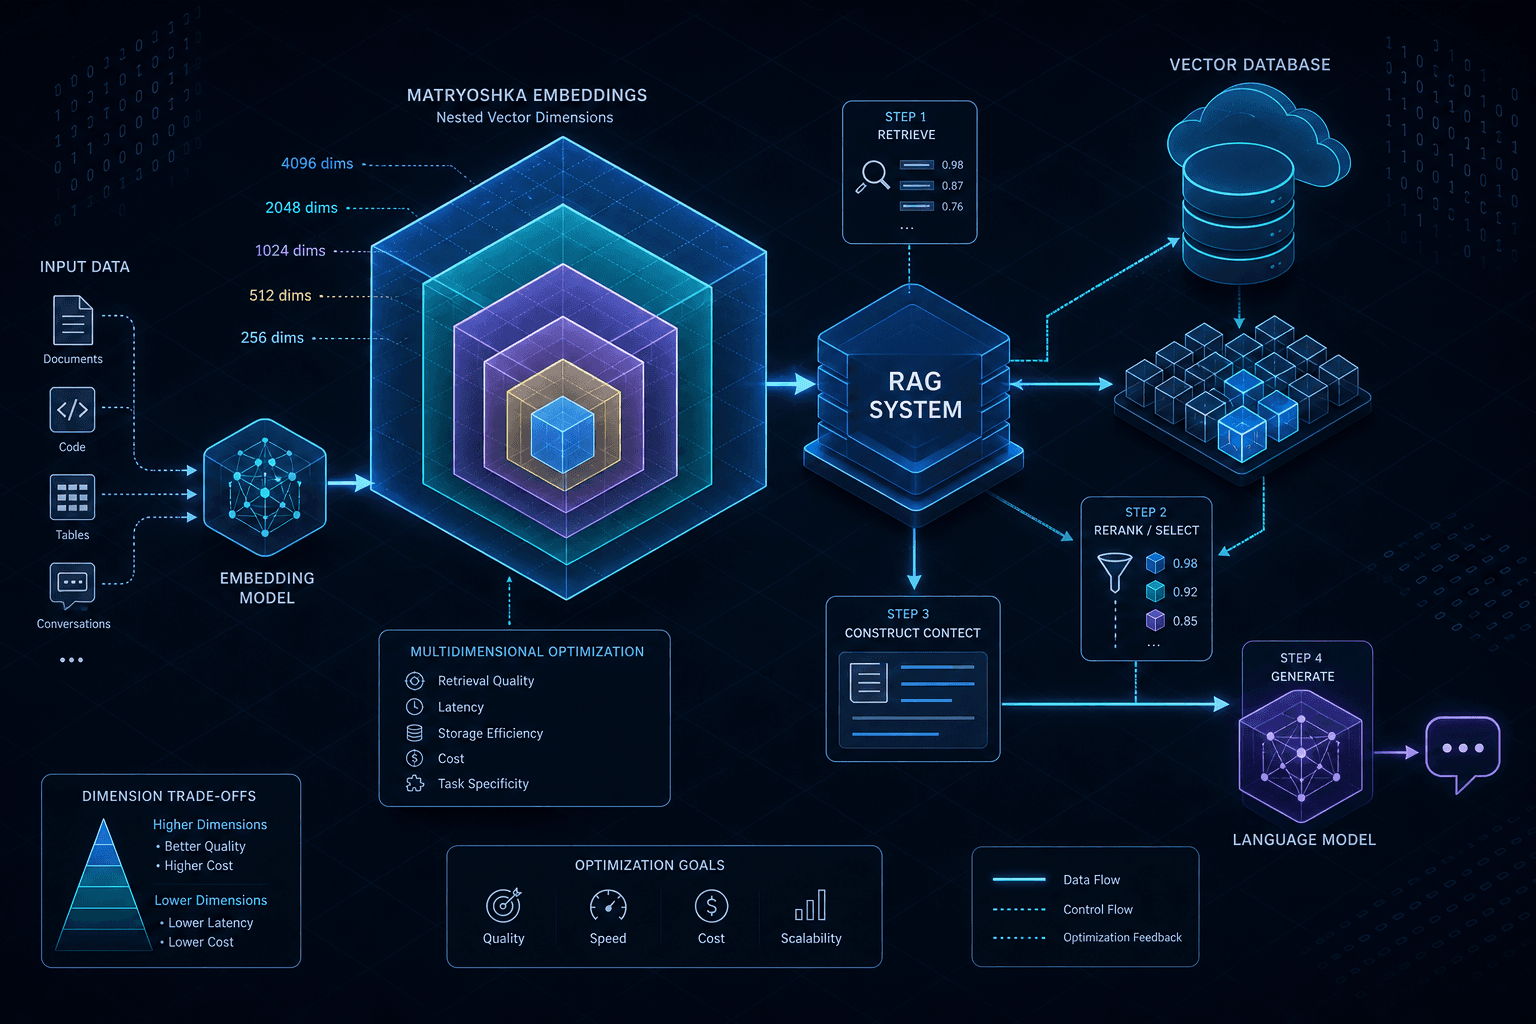
Part 6 · RAG from Zero to ProductionNavigate the 2026 landscape of embedding models. Learn how to evaluate MTEB scores, leverage Matryoshka dimensions, and handle multilingual data for production RAG.
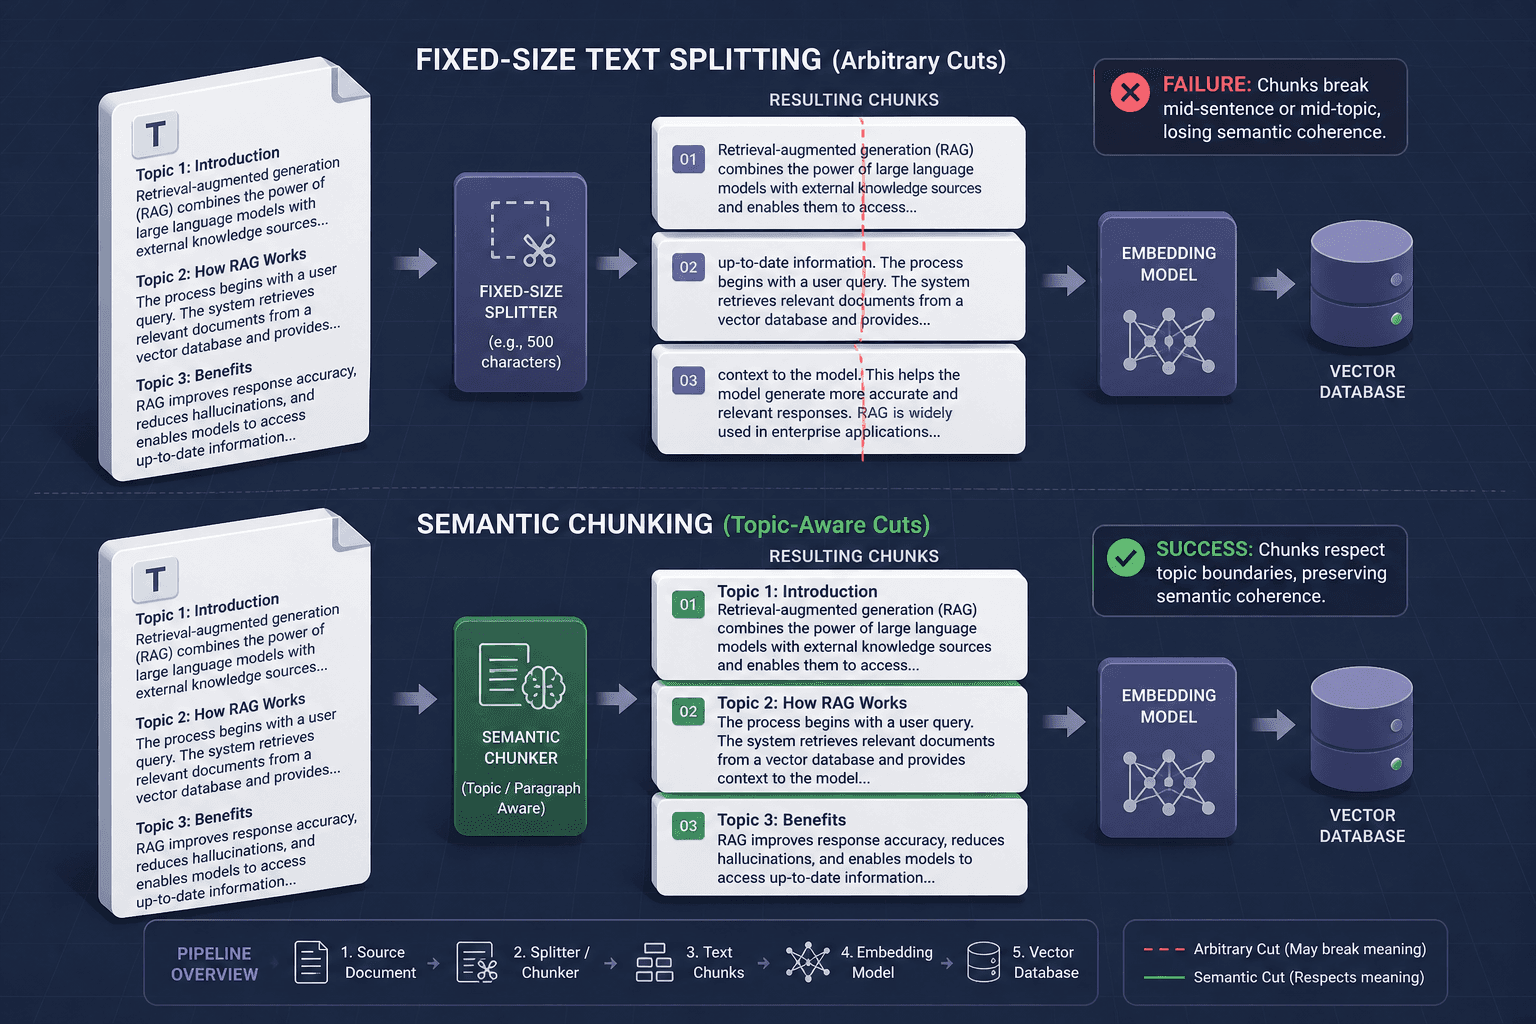
Part 3 · RAG from Zero to ProductionReal documents are messy. Learn how to implement effective chunking strategies, semantic splitting, and overlap techniques to improve RAG retrieval accuracy.
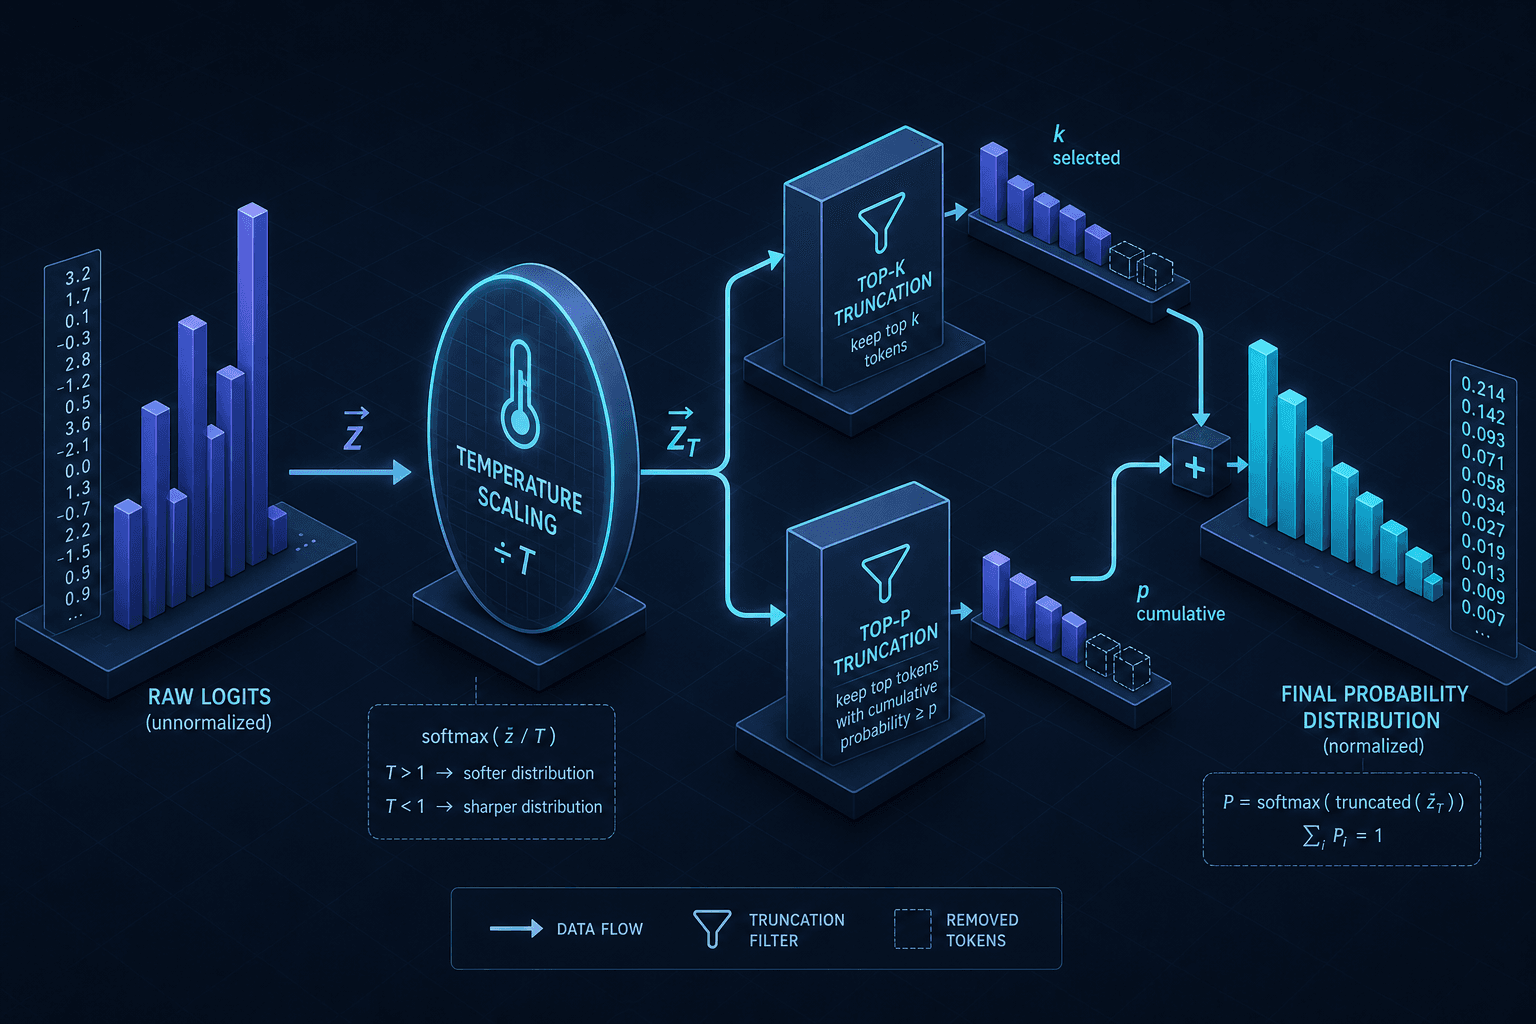
Part 2 · RAG from Zero to ProductionA technical breakdown of sampling parameters like temperature, top-p, top-k, and min-p, explaining how they control the randomness and quality of LLM generation.
Part 7 · LLM Inference from Scratch