6 min readBackendFeatured
Caching Strategies for RAG Pipelines
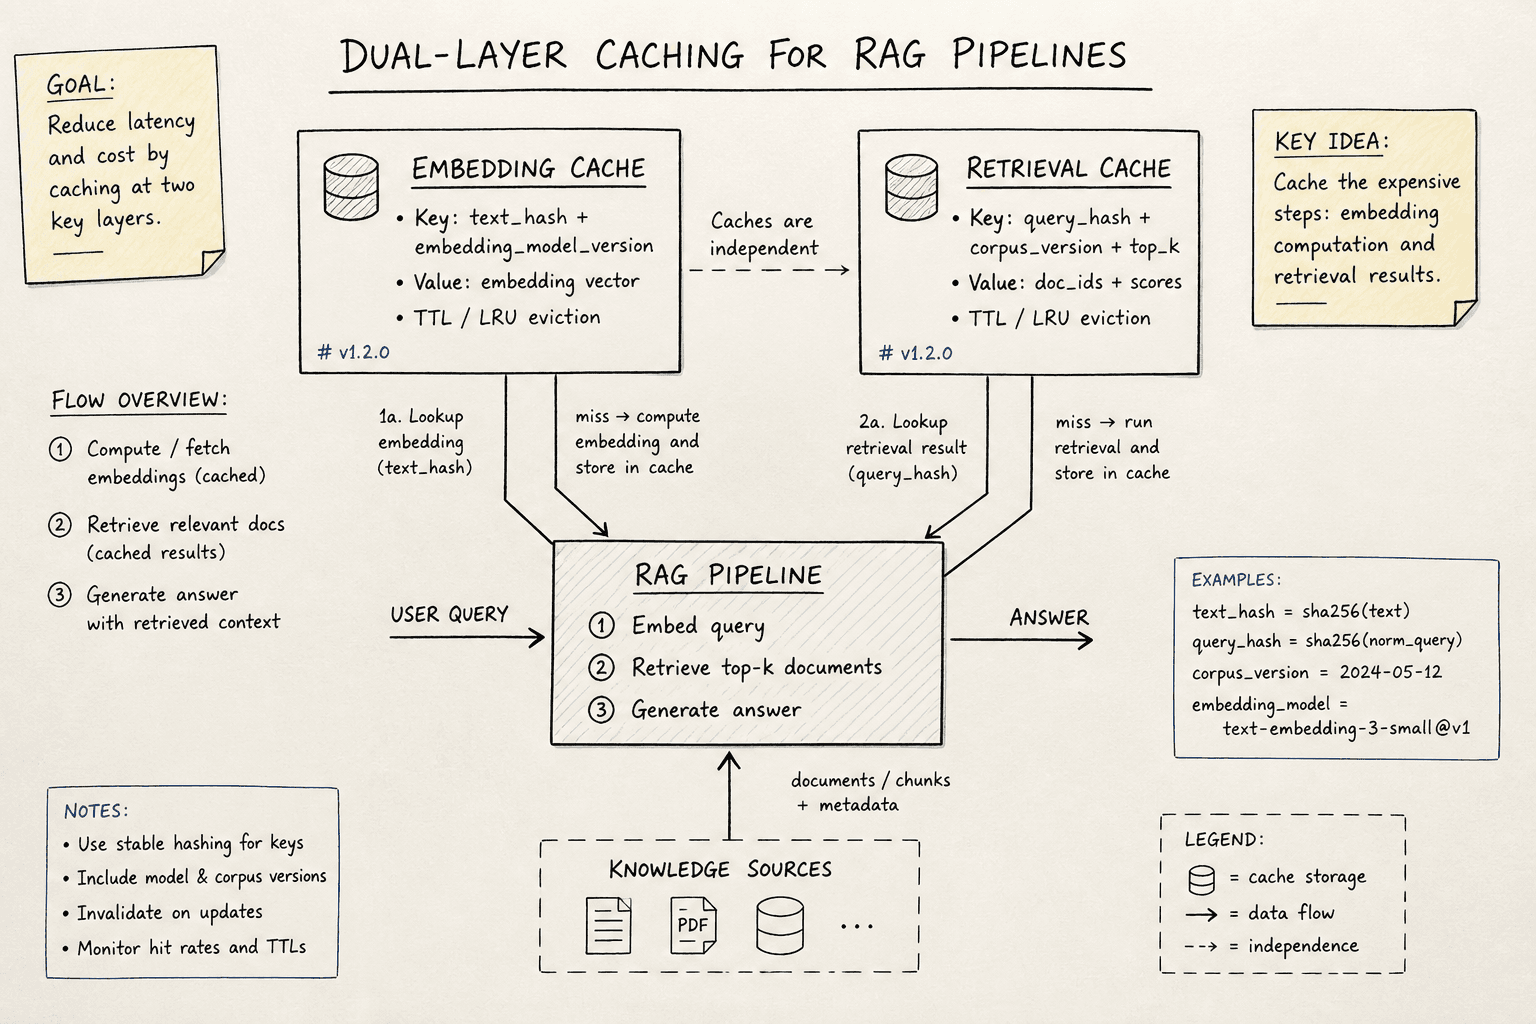
Learn how to implement embedding and retrieval caches in RAG pipelines to boost performance and manage invalidation effectively.
Tag
Read 6 articles on Retrieval by Ashish Srivastava — practical guides covering implementation patterns, security, and production lessons.
6 posts
Learn how to implement embedding and retrieval caches in RAG pipelines to boost performance and manage invalidation effectively.
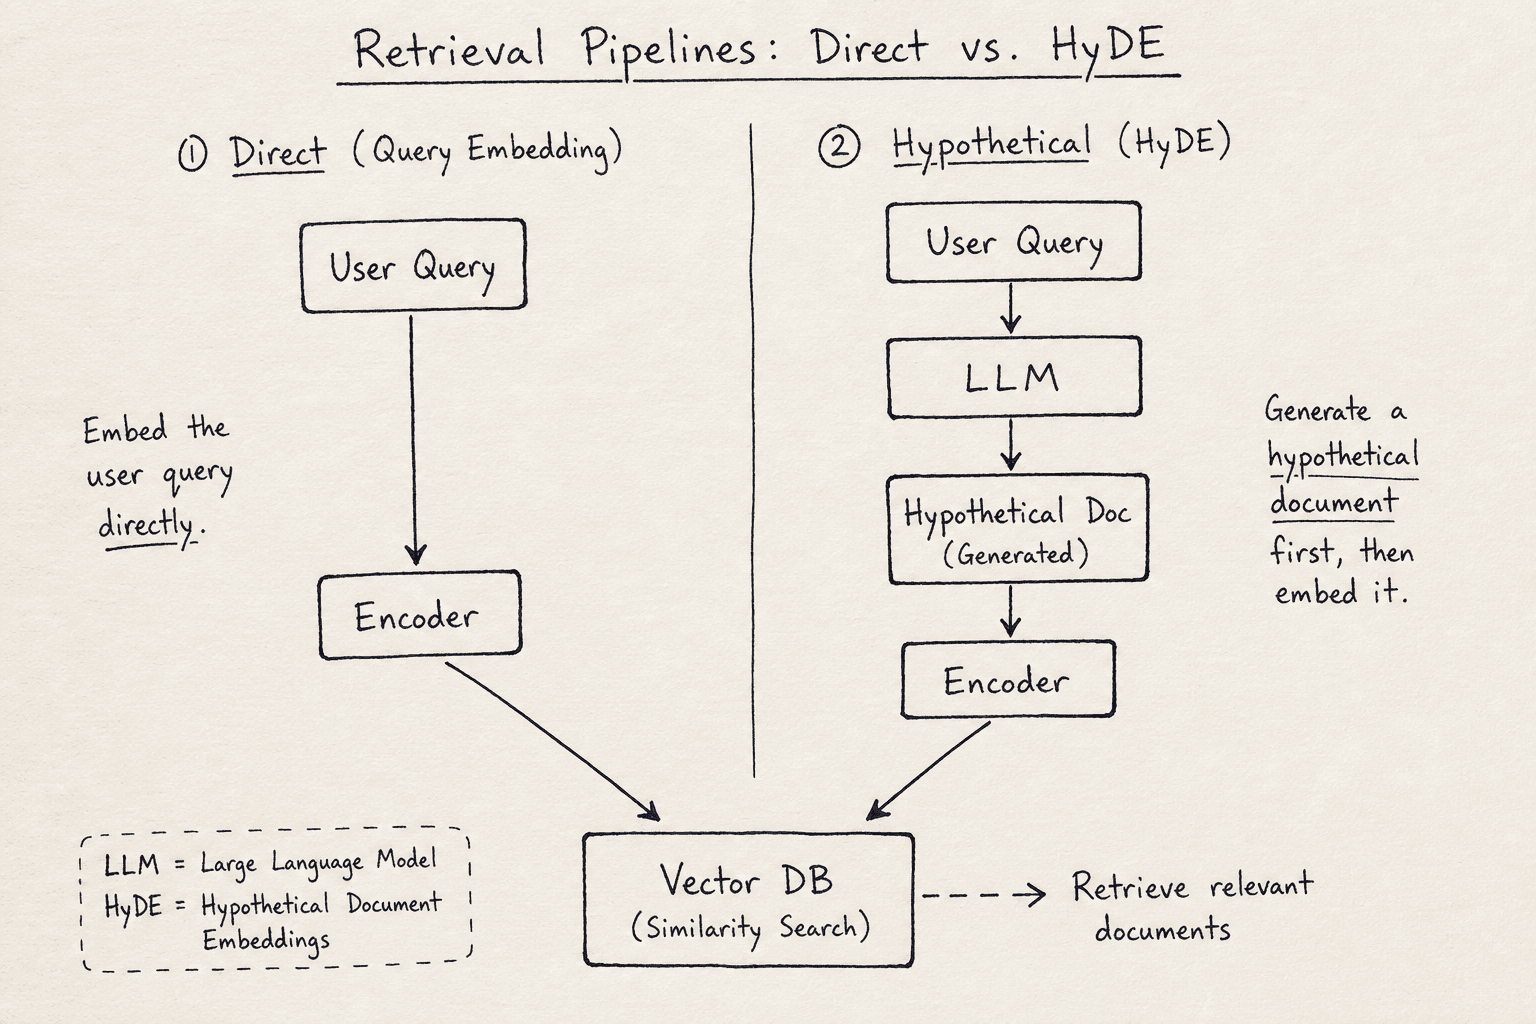
We test HyDE and query expansion against current baselines to see if these methods still provide a significant boost to retrieval accuracy.
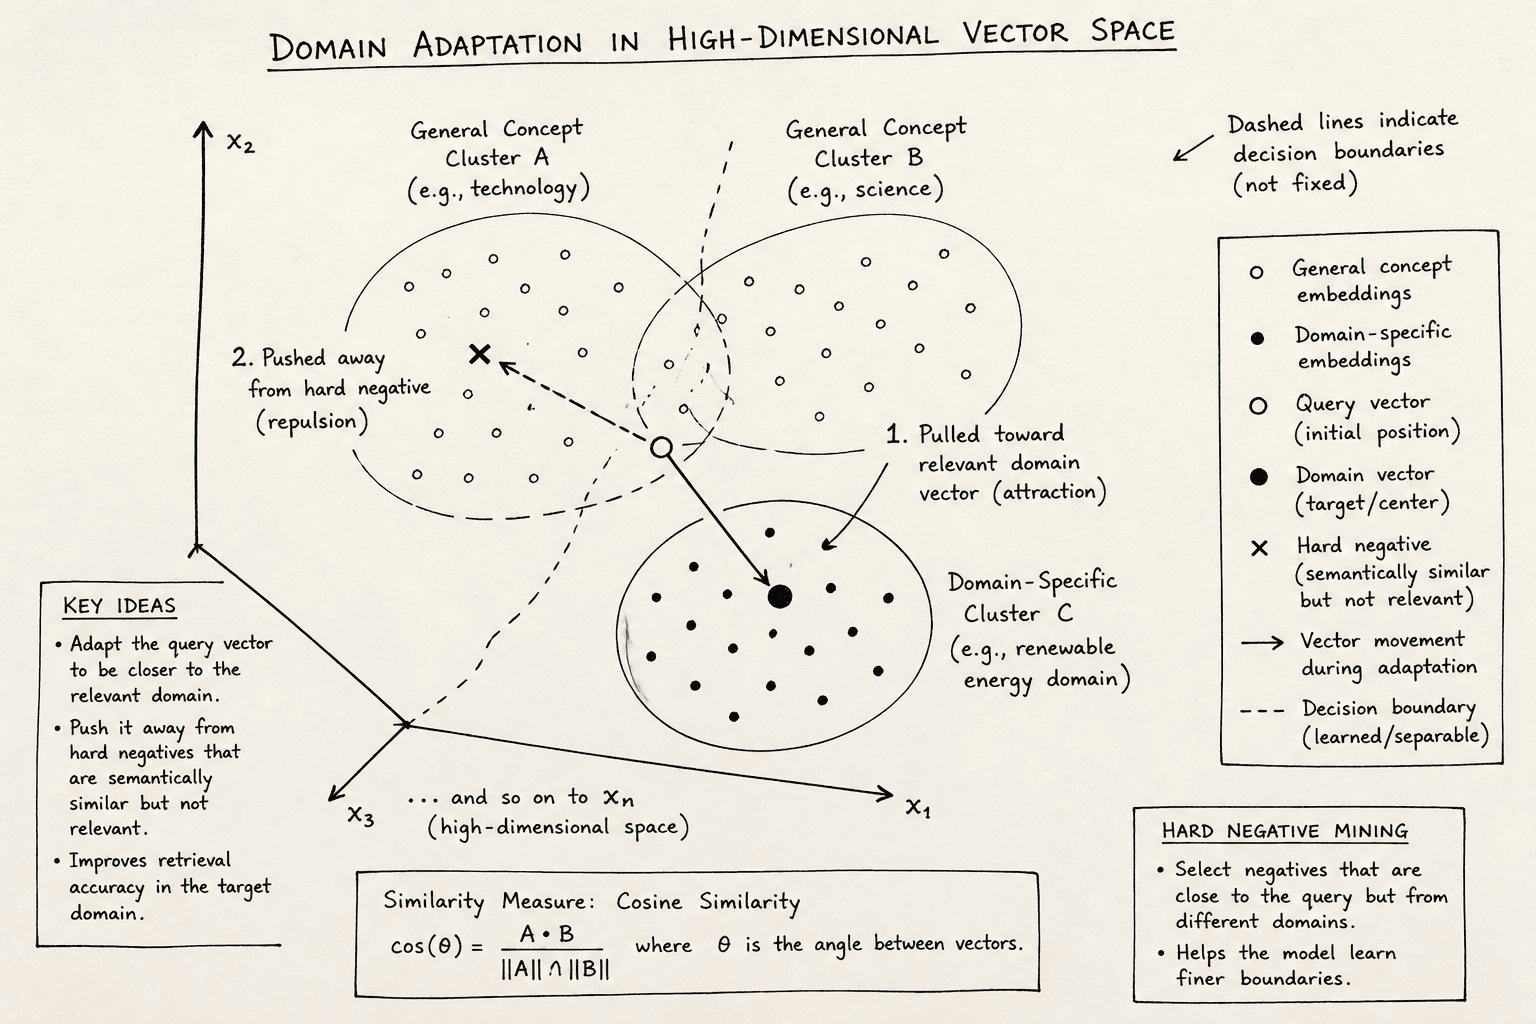
Learn how to adapt pre-trained sentence transformers to specific domains by leveraging hard negatives and contrastive loss functions for better retrieval accuracy.
Should you use long-context windows or retrieval-augmented generation? We compare cost, latency, and accuracy for million-token scenarios.
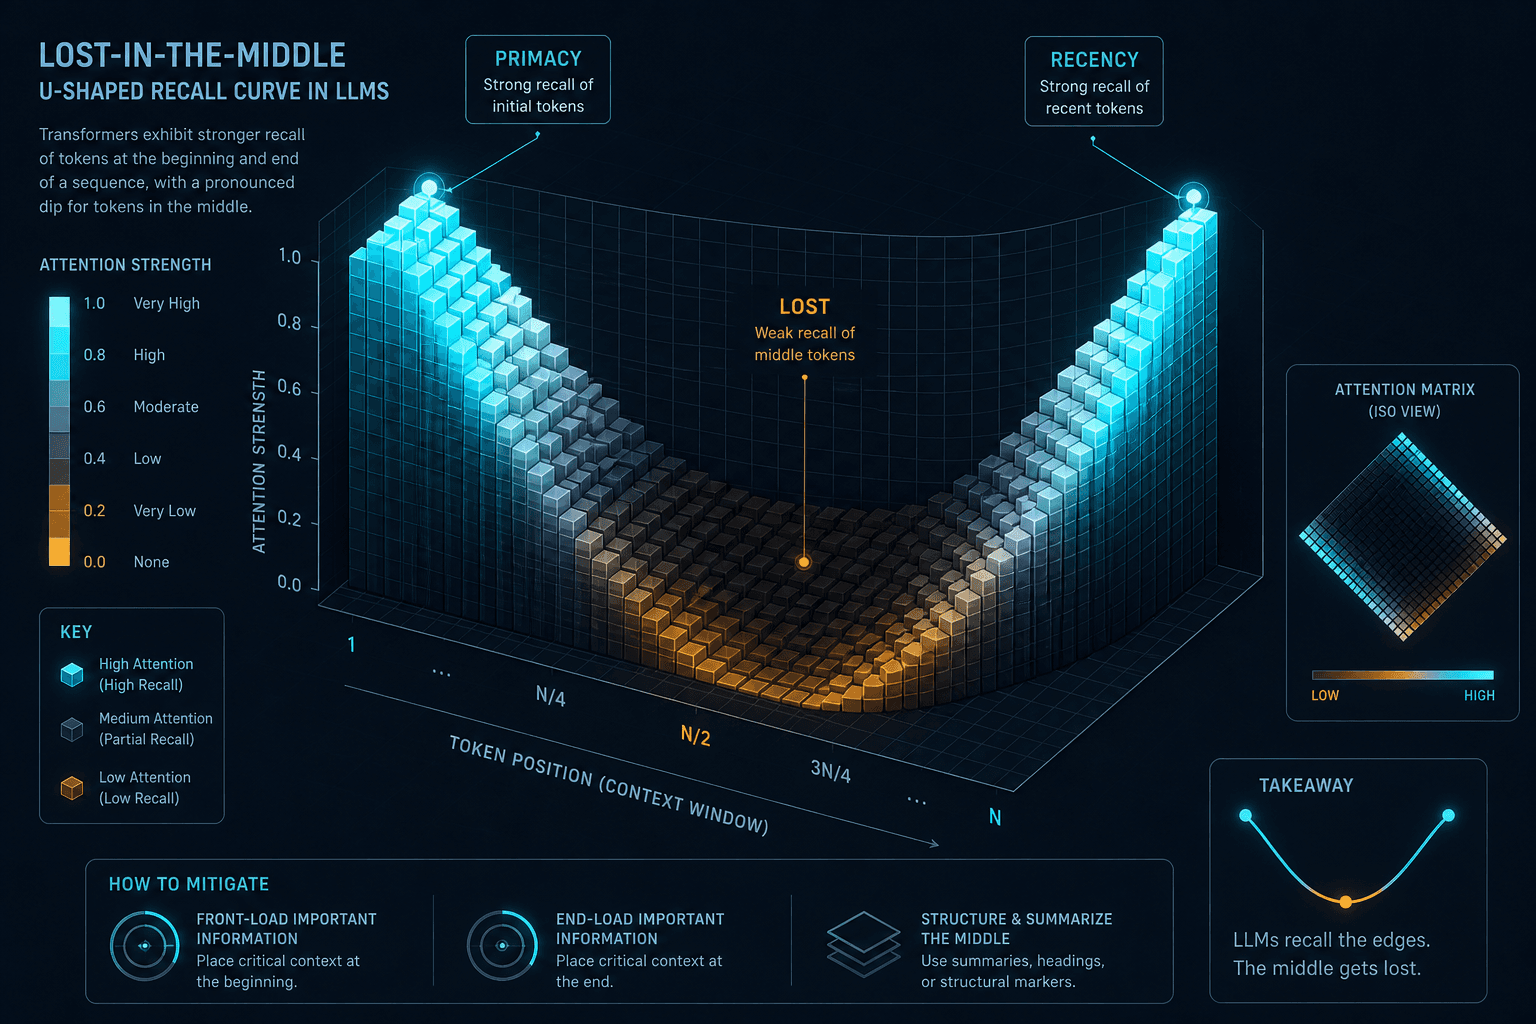
Part 5 · Context EngineeringLarge language models often struggle to retrieve information placed in the middle of long contexts. This article explores position bias and effective workarounds.
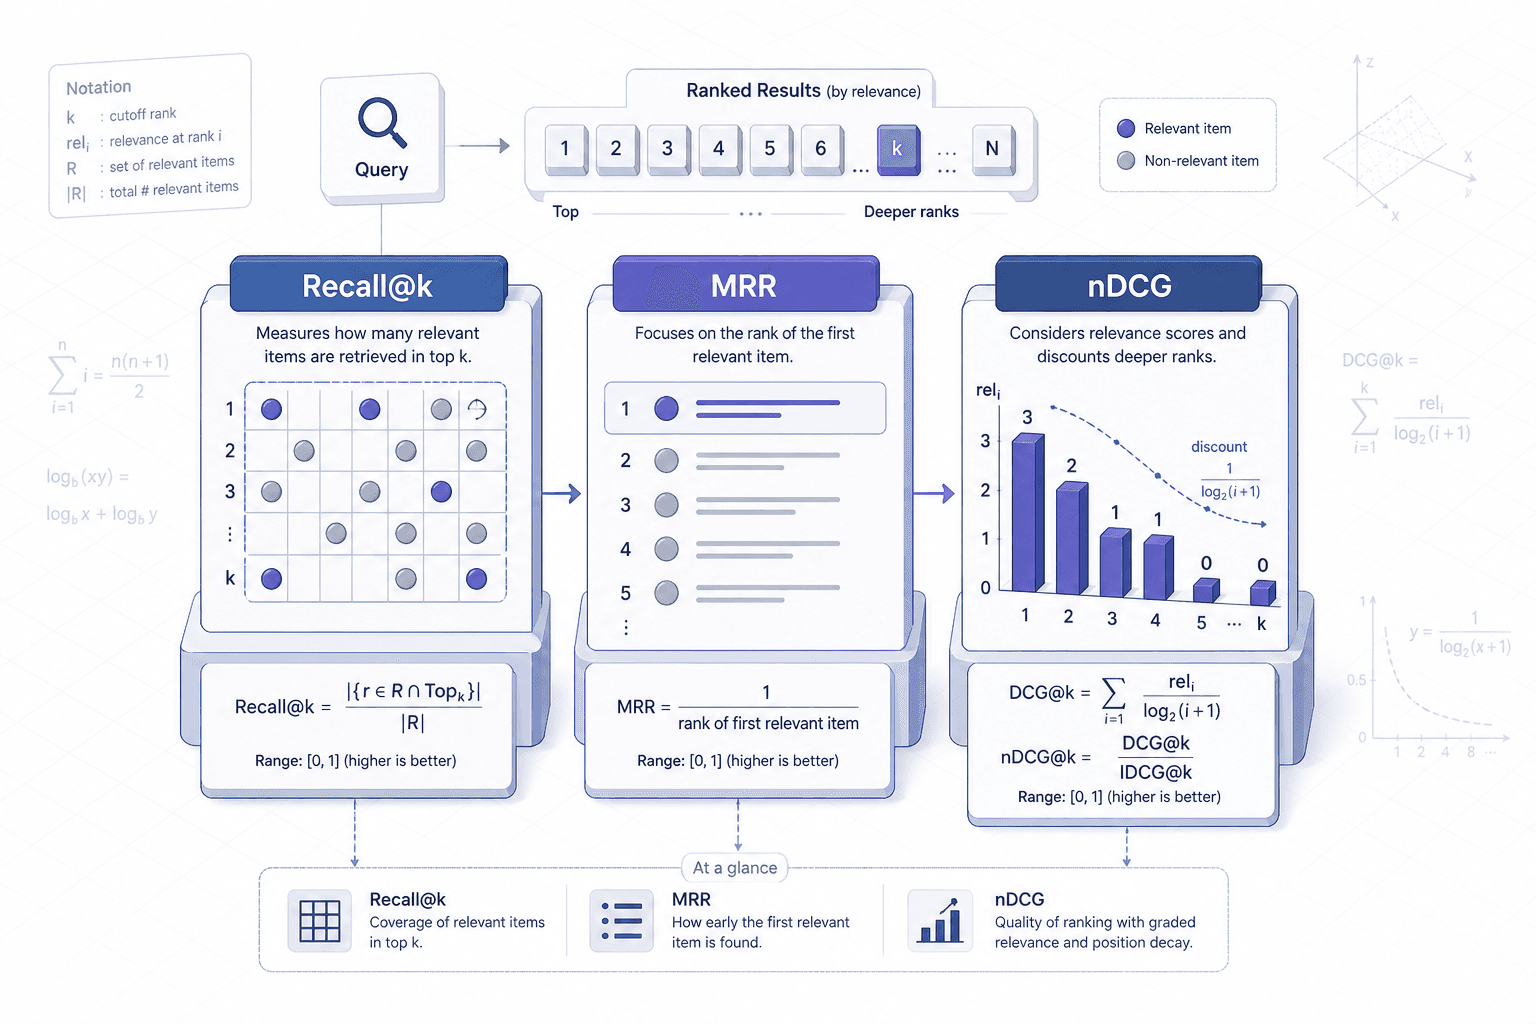
Part 2 · Context EngineeringExplore the core metrics for retrieval system evaluation: Recall@k, nDCG, and MRR. Understand their calculations, use cases, and impact on ranking quality.
Part 6 · Retrieval Engineering