6 min readDevelopmentFeatured
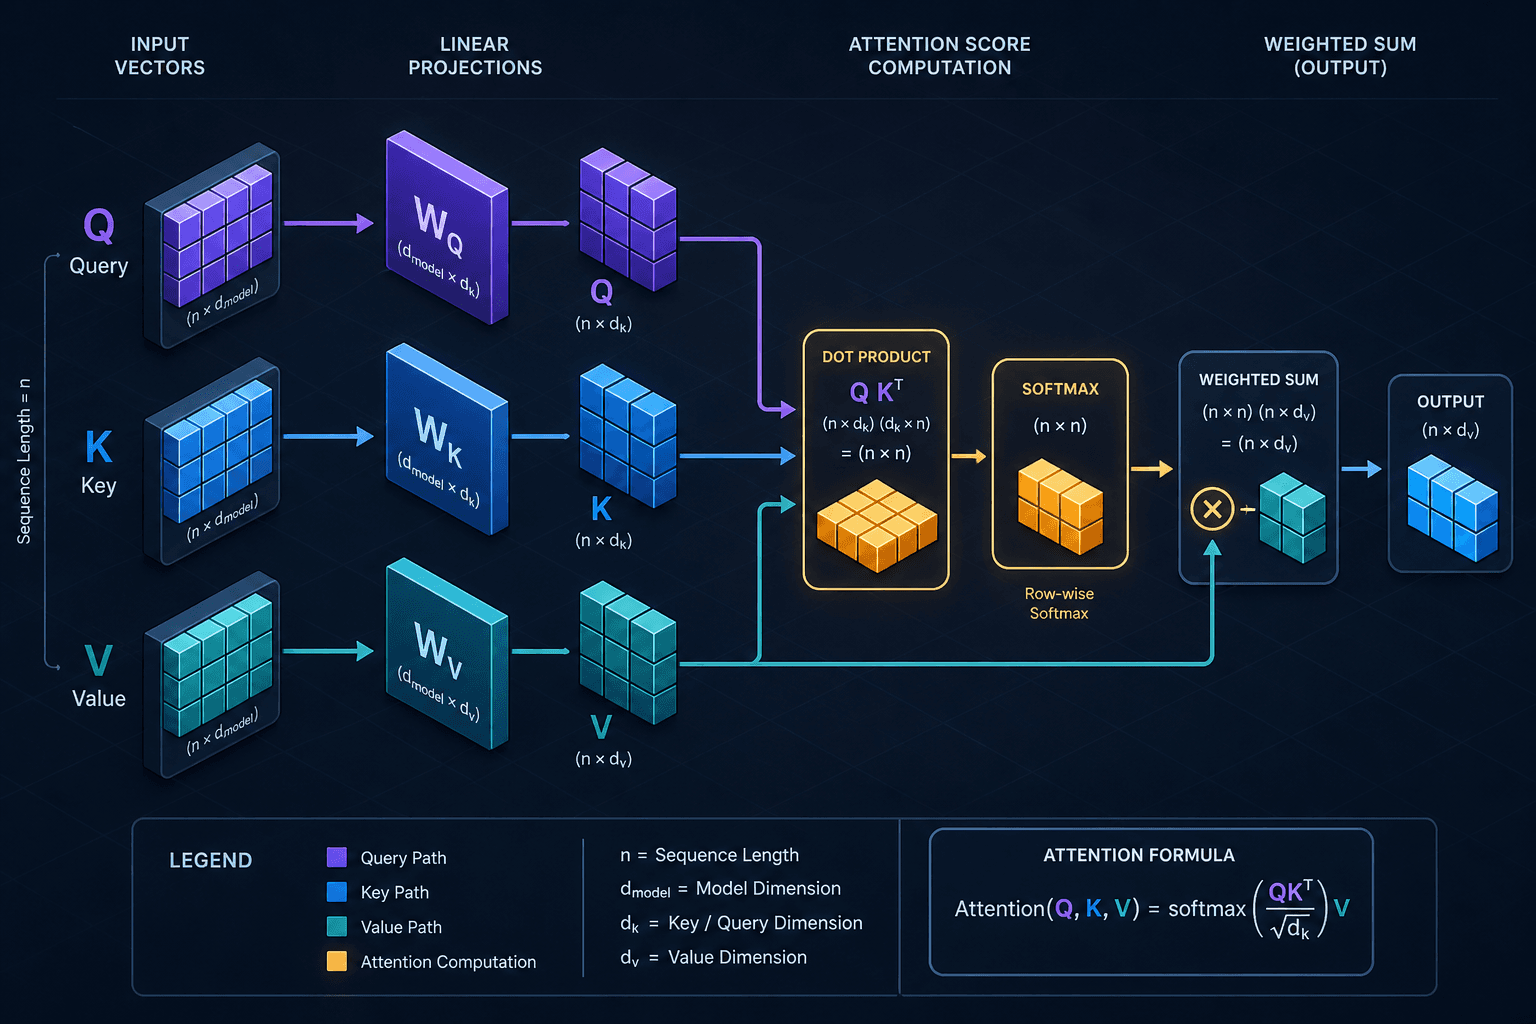
Attention, Derived From First Principles
Explore how attention works by deriving QKV projections and softmax scaling from first principles, tailored for developers and ML engineers.
Part 1 · Transformers Under the HoodTag
Read 1 article on Transformer by Ashish Srivastava — practical guides covering implementation patterns, security, and production lessons.
1 post · thin content (not indexed)
Explore how attention works by deriving QKV projections and softmax scaling from first principles, tailored for developers and ML engineers.
Part 1 · Transformers Under the Hood