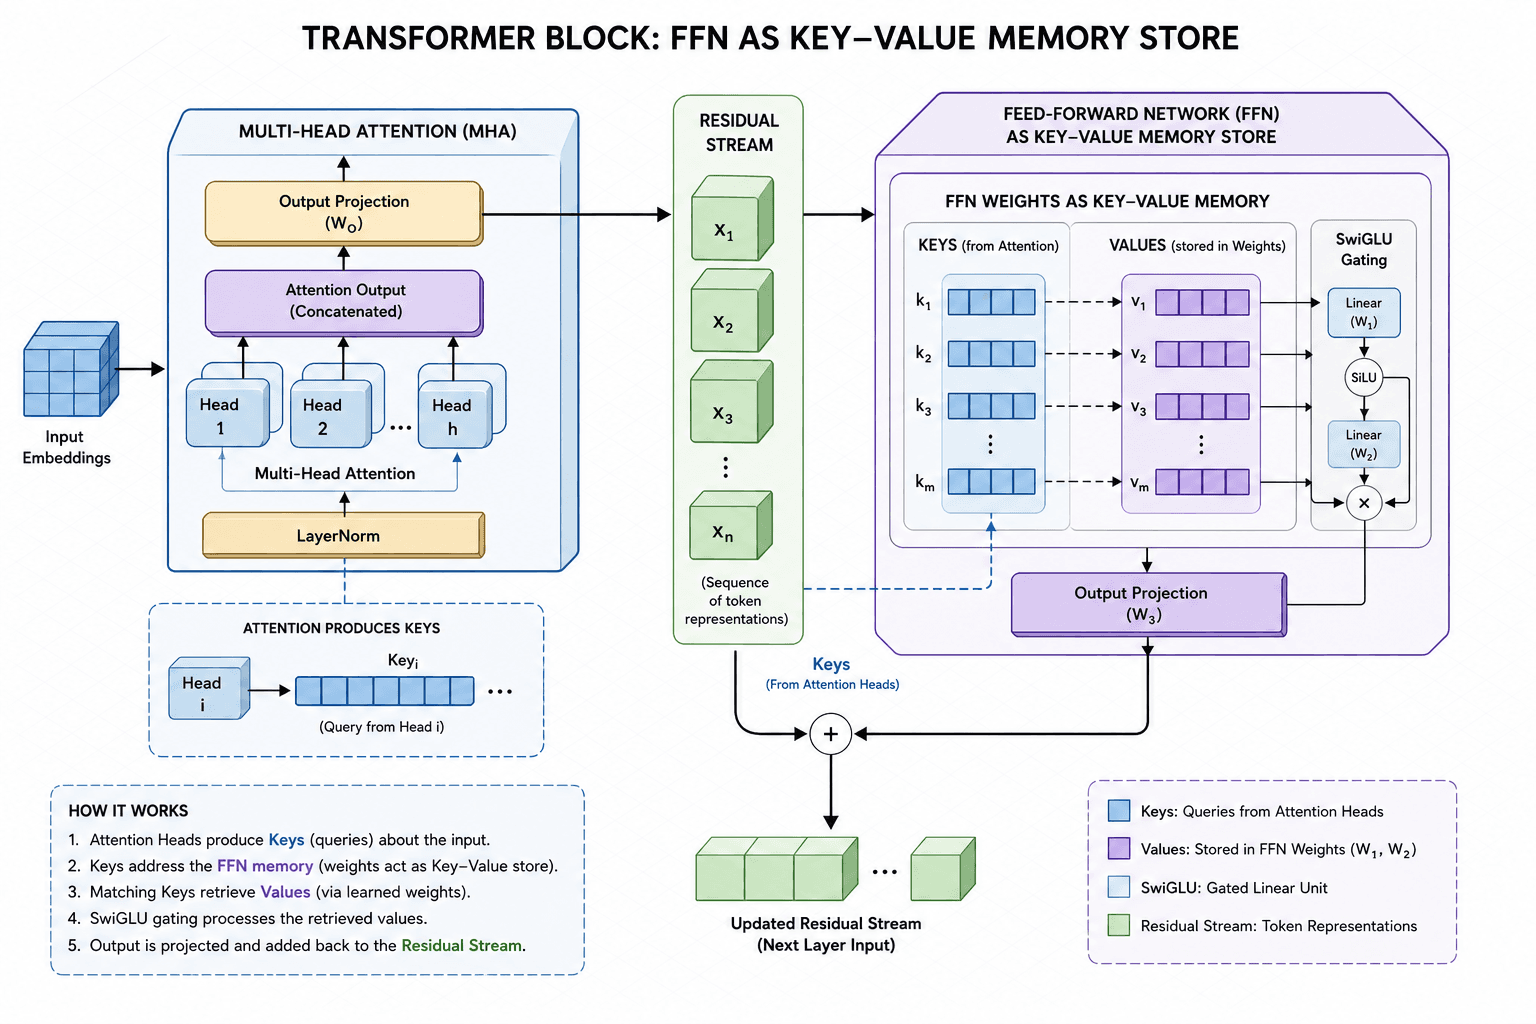
FFN as Key-Value Memory | Transformers Under the Hood
Explore the role of feed-forward networks as key-value memory in transformers, analyzing SwiGLU mechanisms and interpretability for ML engineers.
Part 5 · Transformers Under the HoodTag
Read 6 articles on Deep Learning by Ashish Srivastava — practical guides covering implementation patterns, security, and production lessons.
6 posts
Explore the role of feed-forward networks as key-value memory in transformers, analyzing SwiGLU mechanisms and interpretability for ML engineers.
Part 5 · Transformers Under the HoodExplore how normalization techniques like layernorm and rmsnorm interact with residual streams to ensure stable training in transformer models.
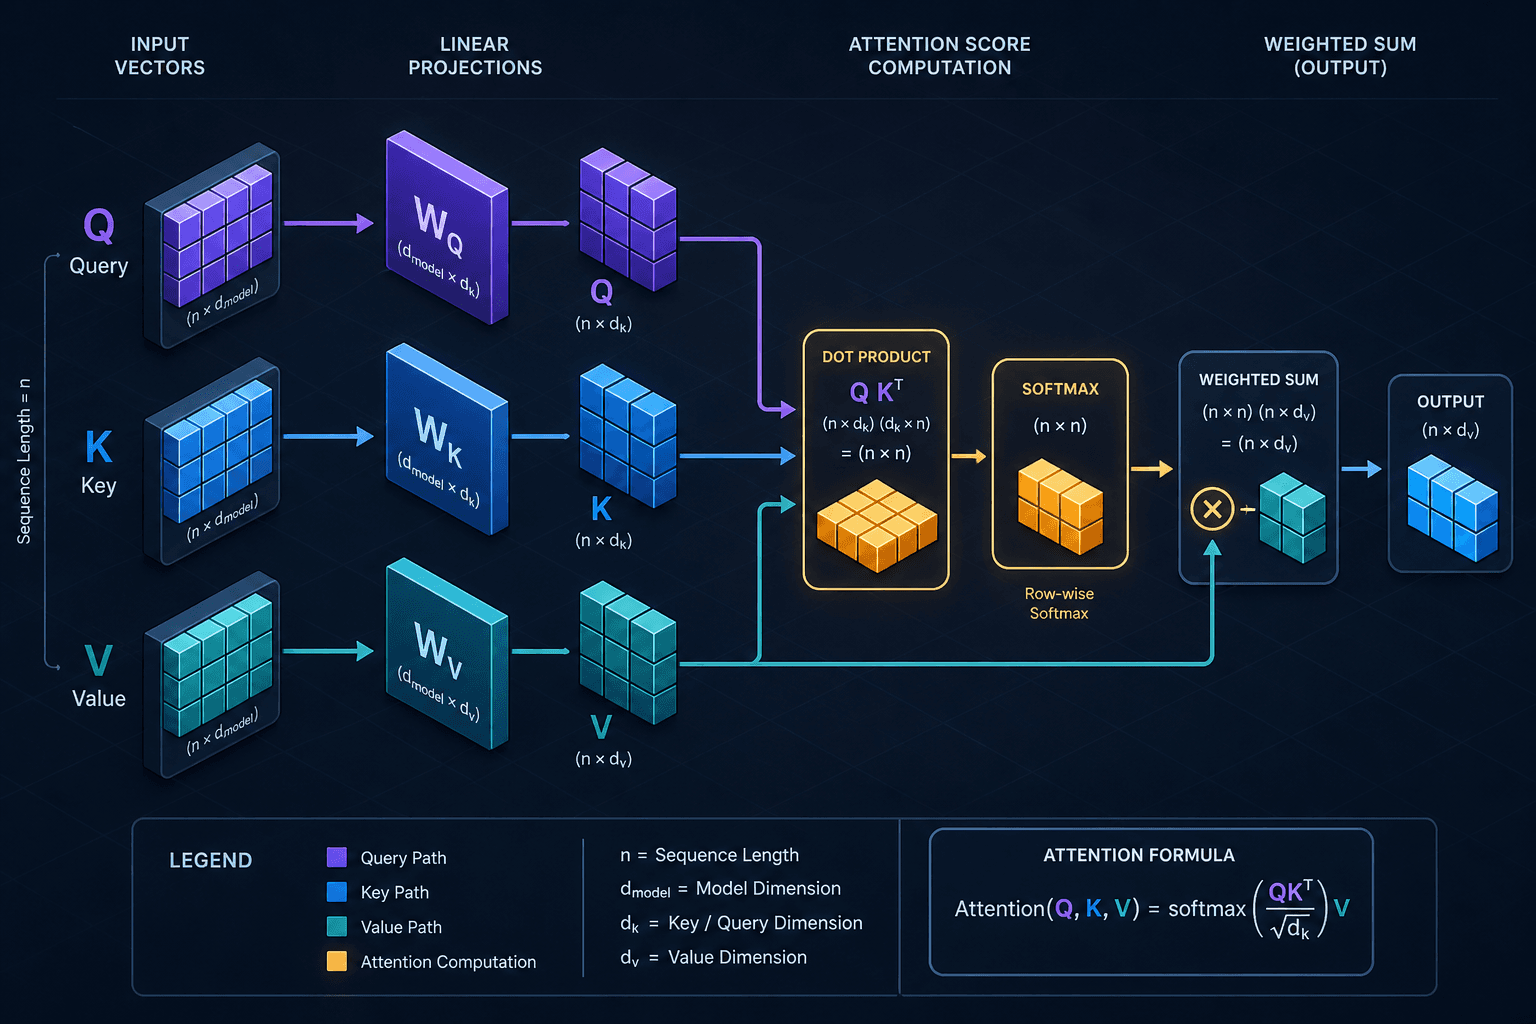
Part 4 · Transformers Under the HoodExplore how attention works by deriving QKV projections and softmax scaling from first principles, tailored for developers and ML engineers.
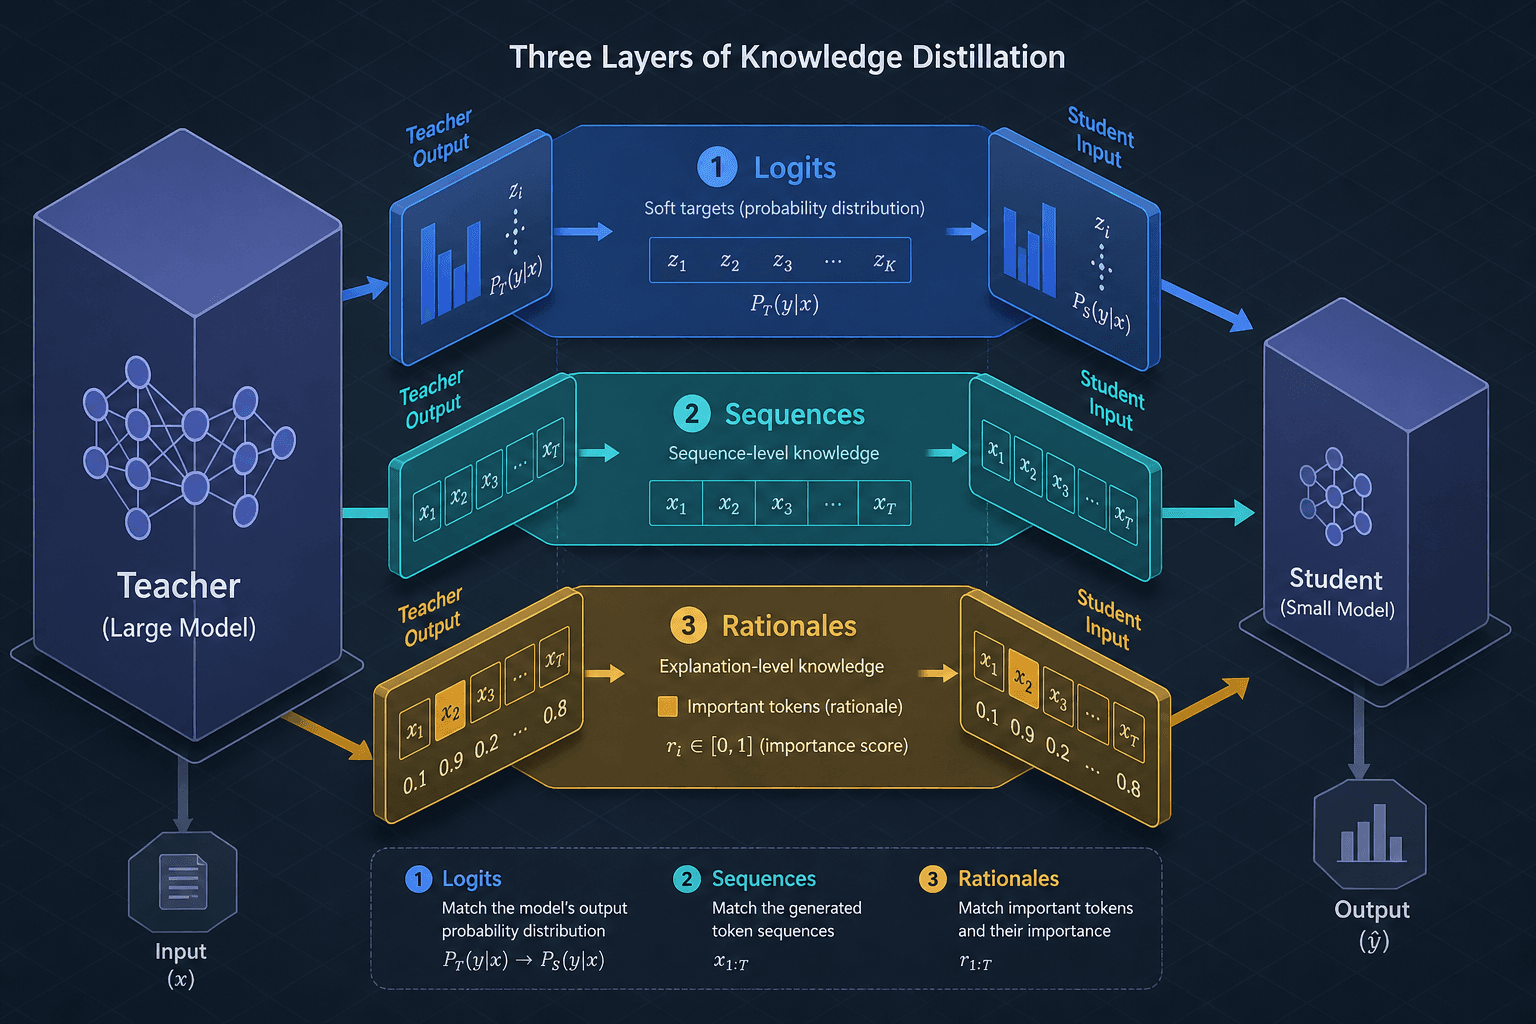
Part 1 · Transformers Under the HoodA technical overview of knowledge distillation methods, covering logits, sequences, and rationales to help ML engineers optimize model performance.
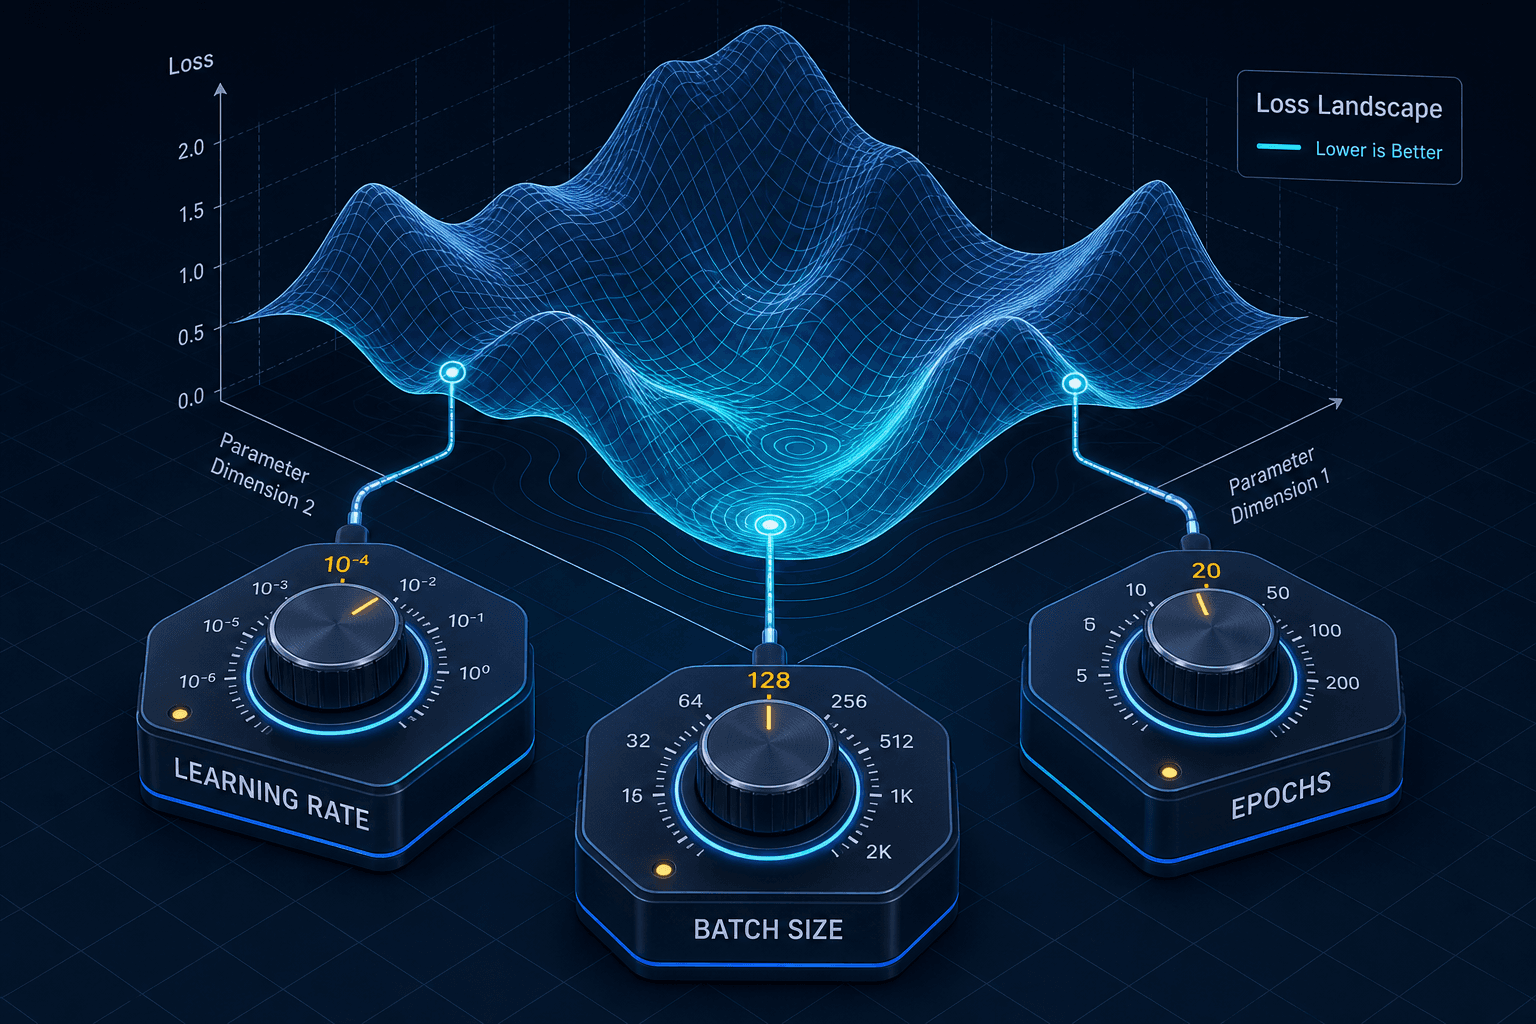
Part 2 · Small Models & DistillationFocus on the hyperparameters that drive model performance: learning rate, batch size, and epochs. A guide for ML engineers.
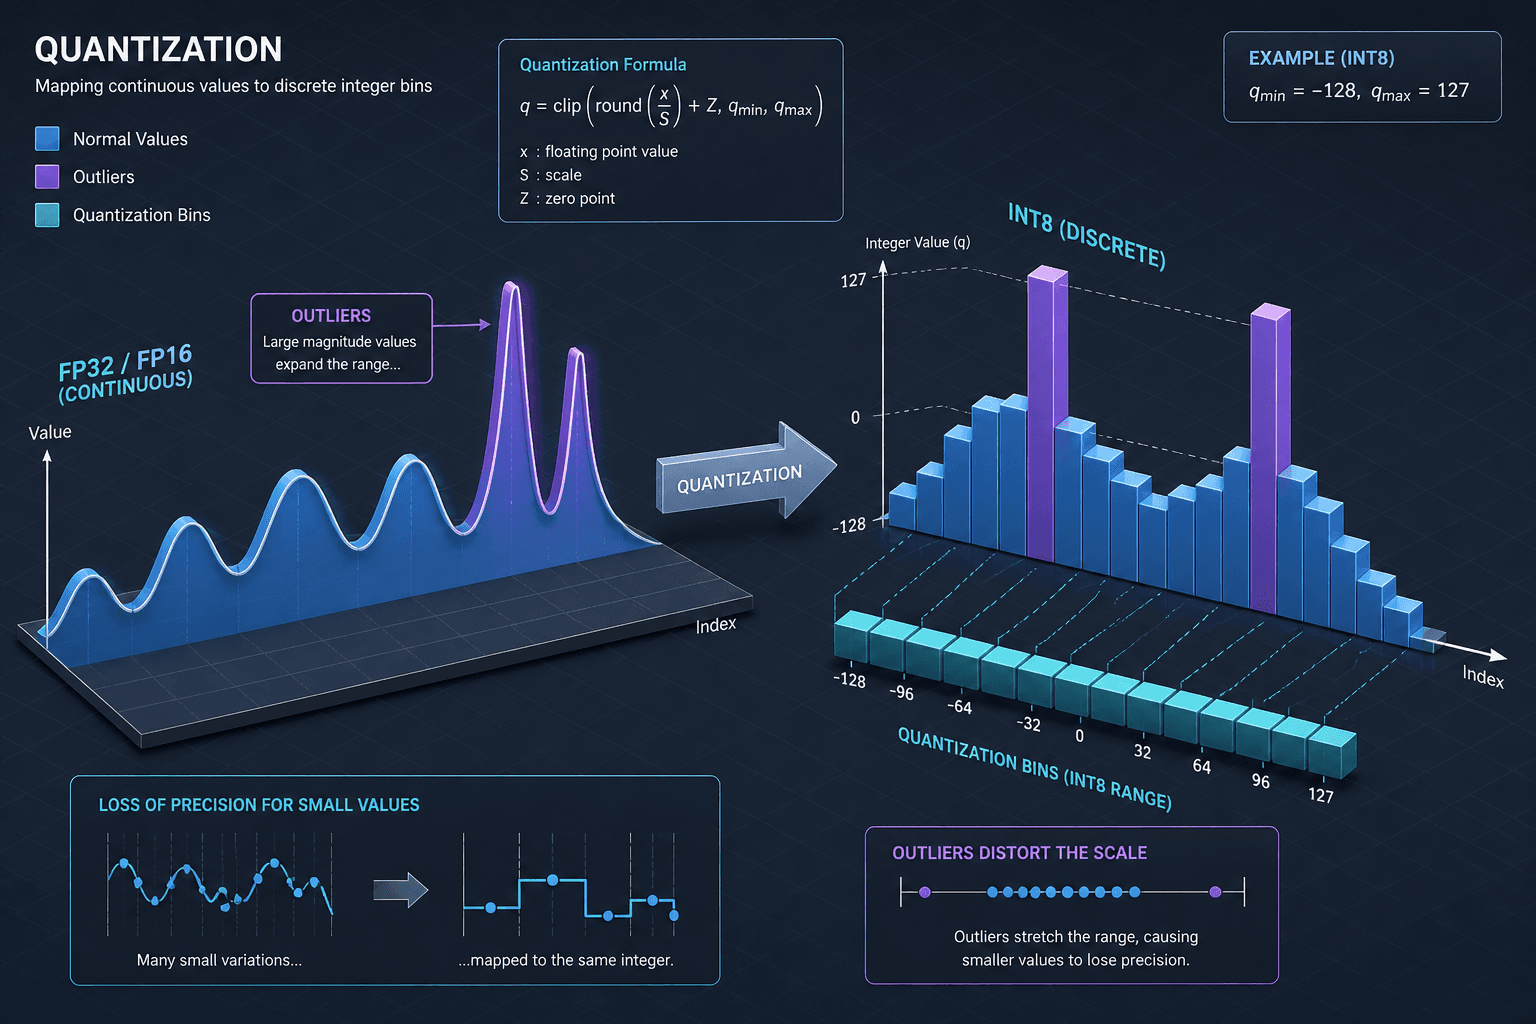
Part 6 · Fine-Tuning LLMs Hands-OnExplore the mechanics of quantization, focusing on precision, dynamic range, and outlier management in fp16 and int8 formats for ML engineers.
Part 1 · Quantization in Practice