6 min readDevelopment
Pruning and Sparsity for Inference
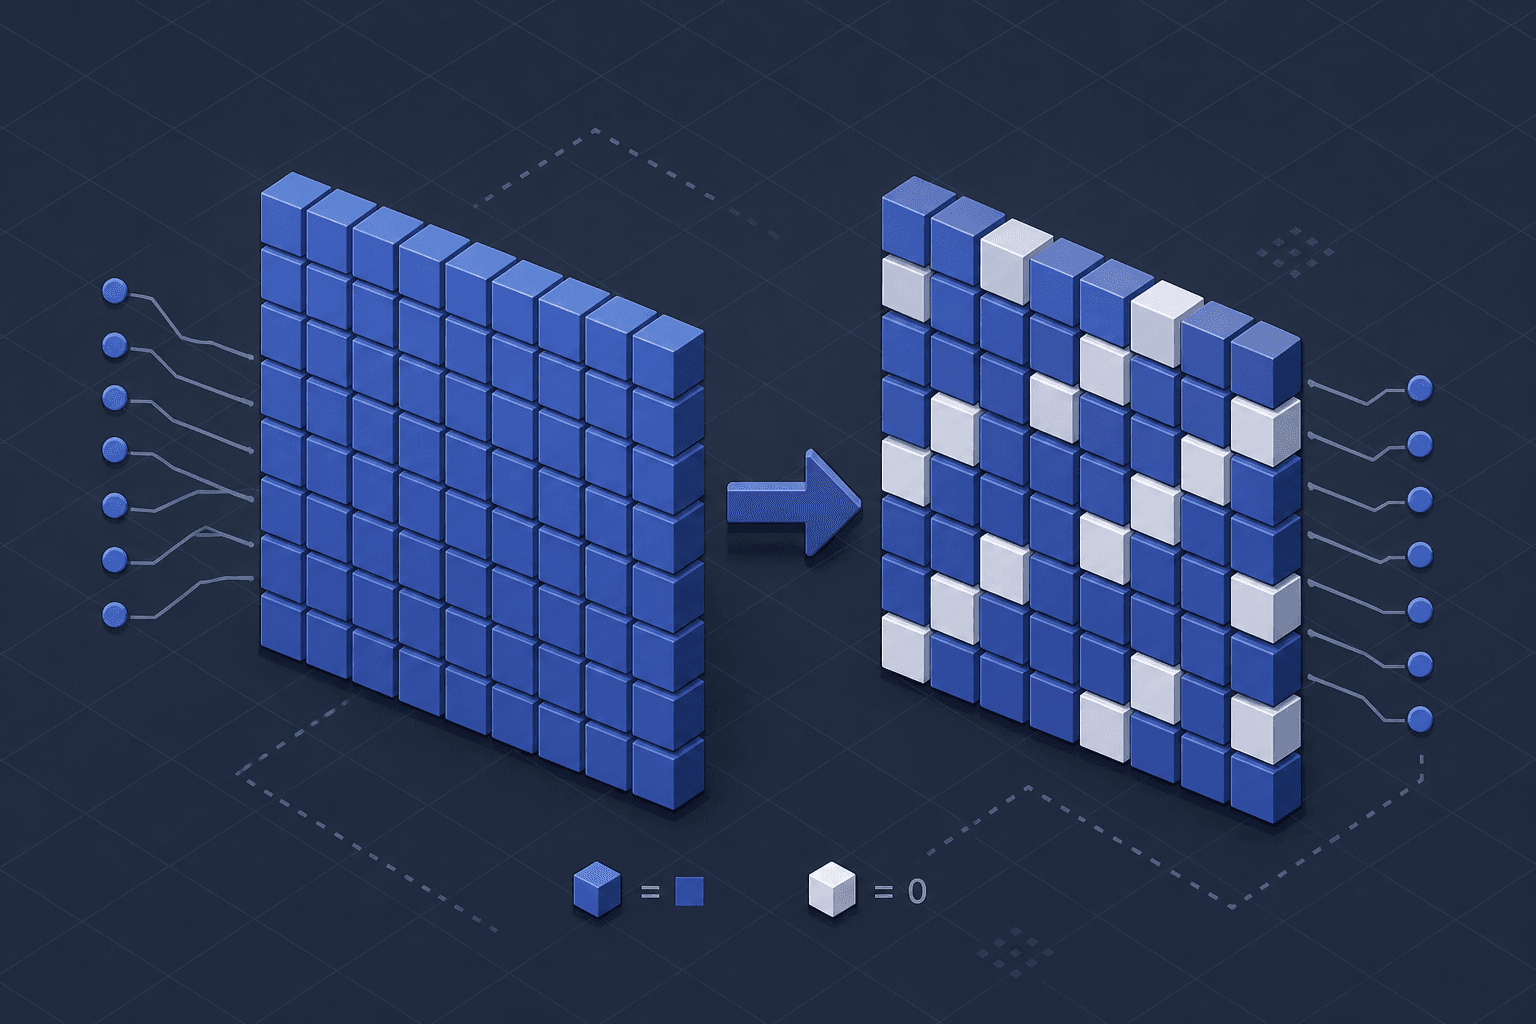
A technical look at pruning and sparsity methods, including structured pruning and 2:4 sparsity, to accelerate model inference.
Part 3 · Small Models & DistillationTag
Read 3 articles on Model Optimization by Ashish Srivastava — practical guides covering implementation patterns, security, and production lessons.
3 posts
A technical look at pruning and sparsity methods, including structured pruning and 2:4 sparsity, to accelerate model inference.
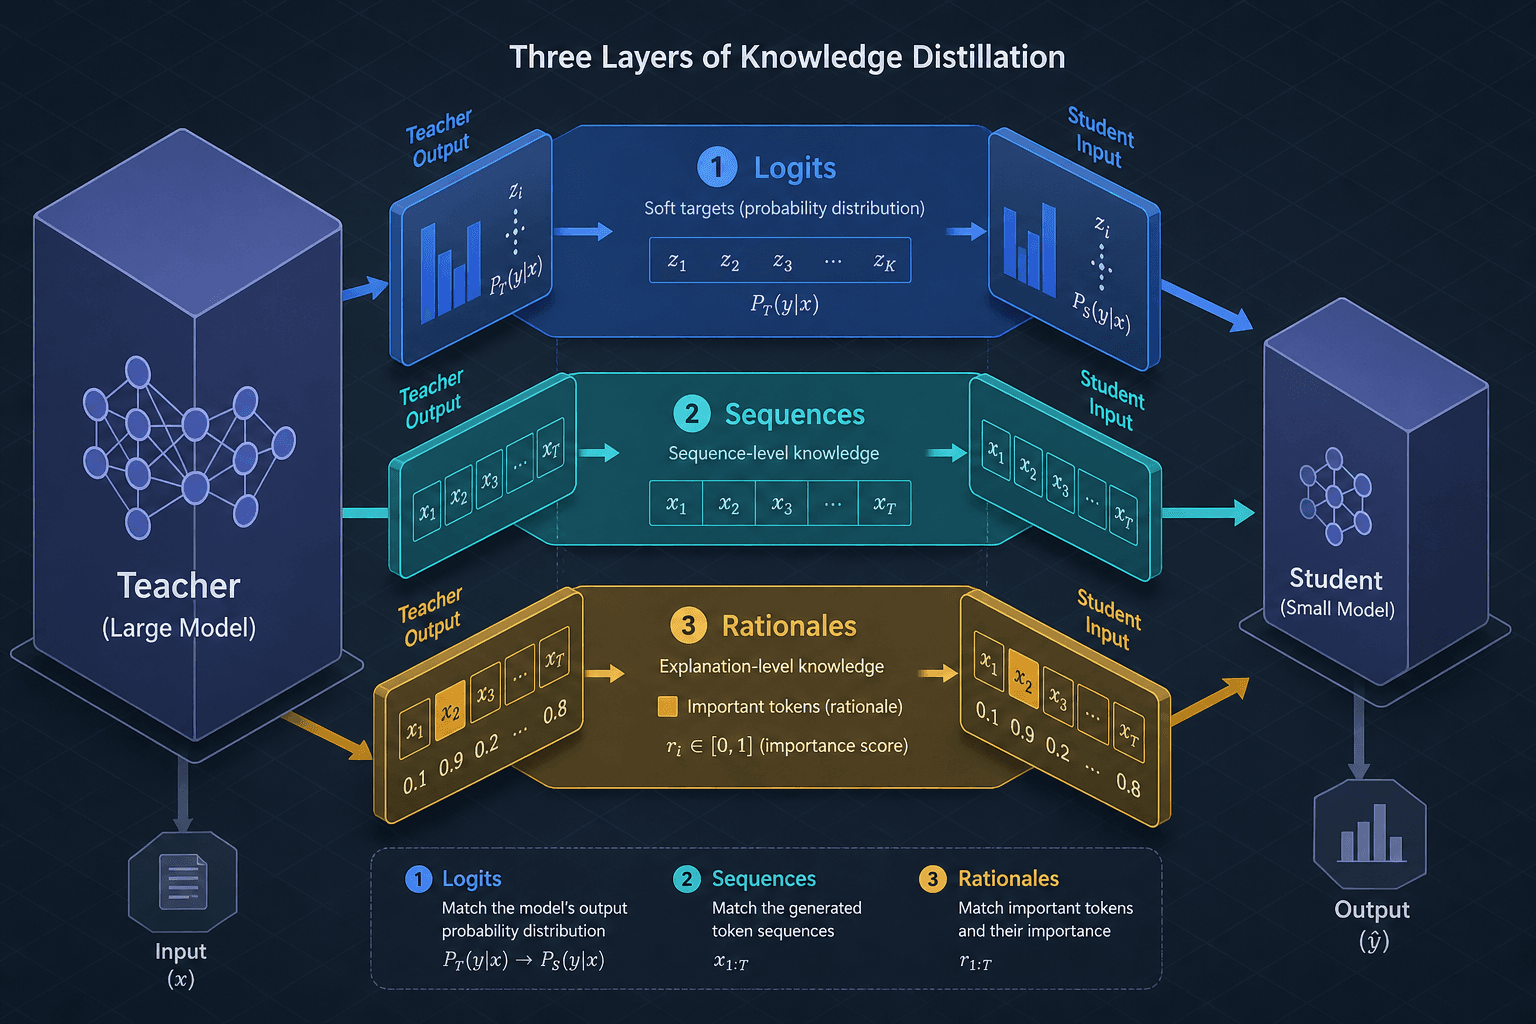
Part 3 · Small Models & DistillationA technical overview of knowledge distillation methods, covering logits, sequences, and rationales to help ML engineers optimize model performance.
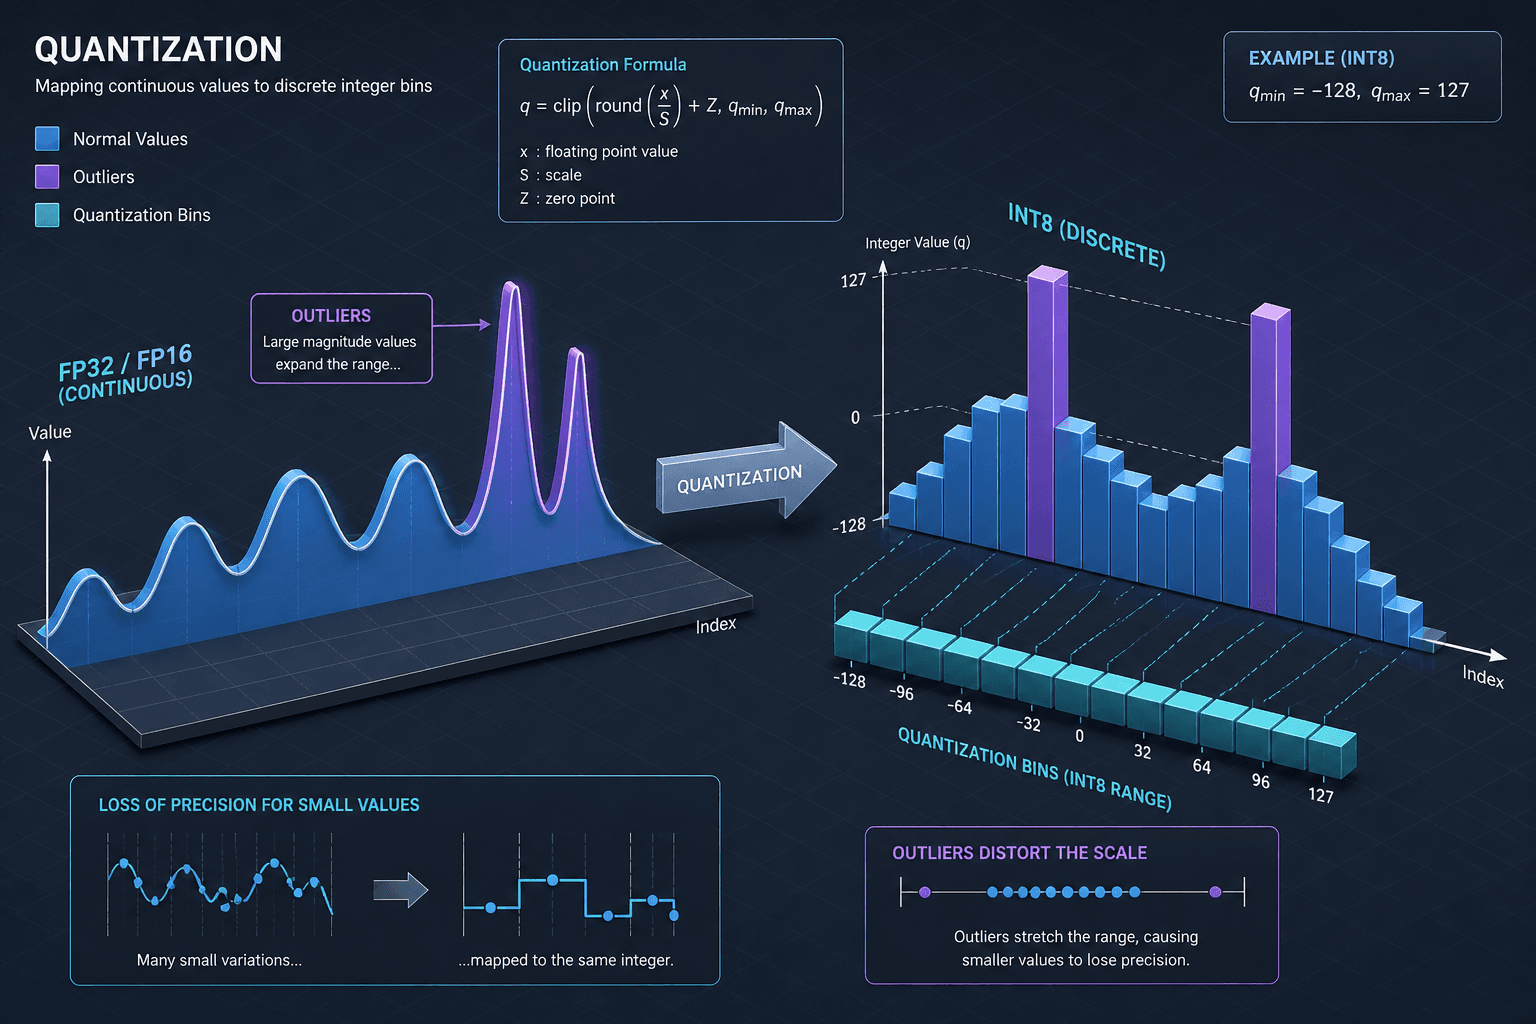
Part 2 · Small Models & DistillationExplore the mechanics of quantization, focusing on precision, dynamic range, and outlier management in fp16 and int8 formats for ML engineers.
Part 1 · Quantization in Practice