6 min readDevelopmentFeatured
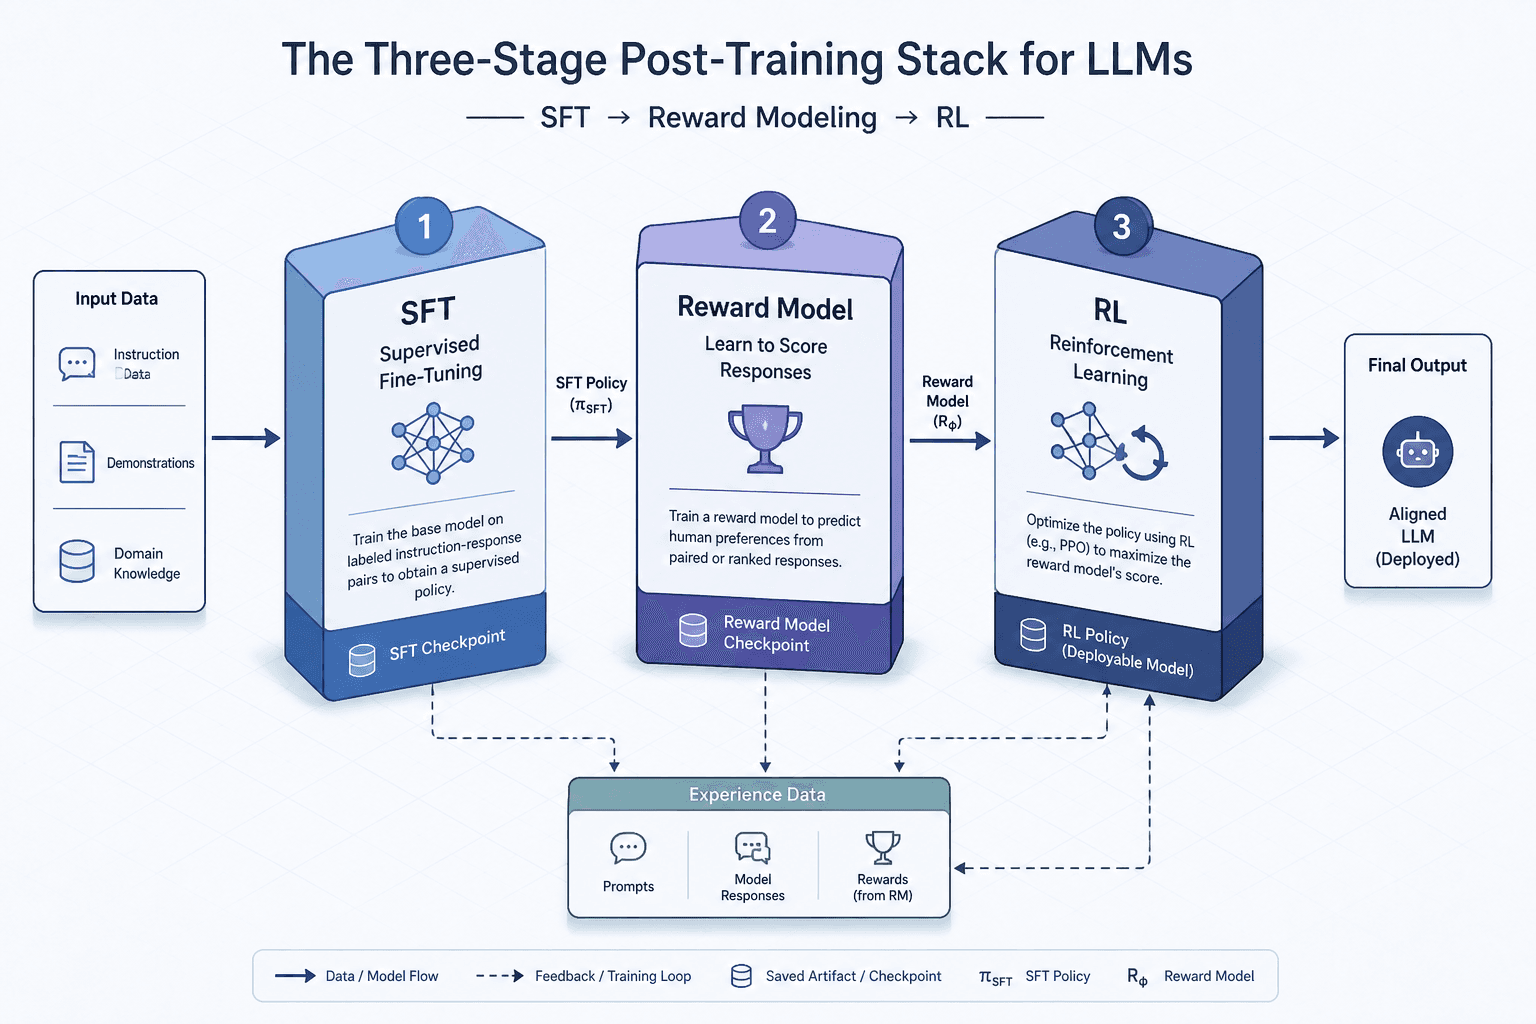
The Post-Training Stack: SFT, Reward Models, and RL
Explore the core components of the post-training stack: SFT, reward models, and RL. Learn how these techniques align large language models with human intent.
Part 1 · Post-Training & Alignment