8 min readDevelopment
RLHF, Step by Step
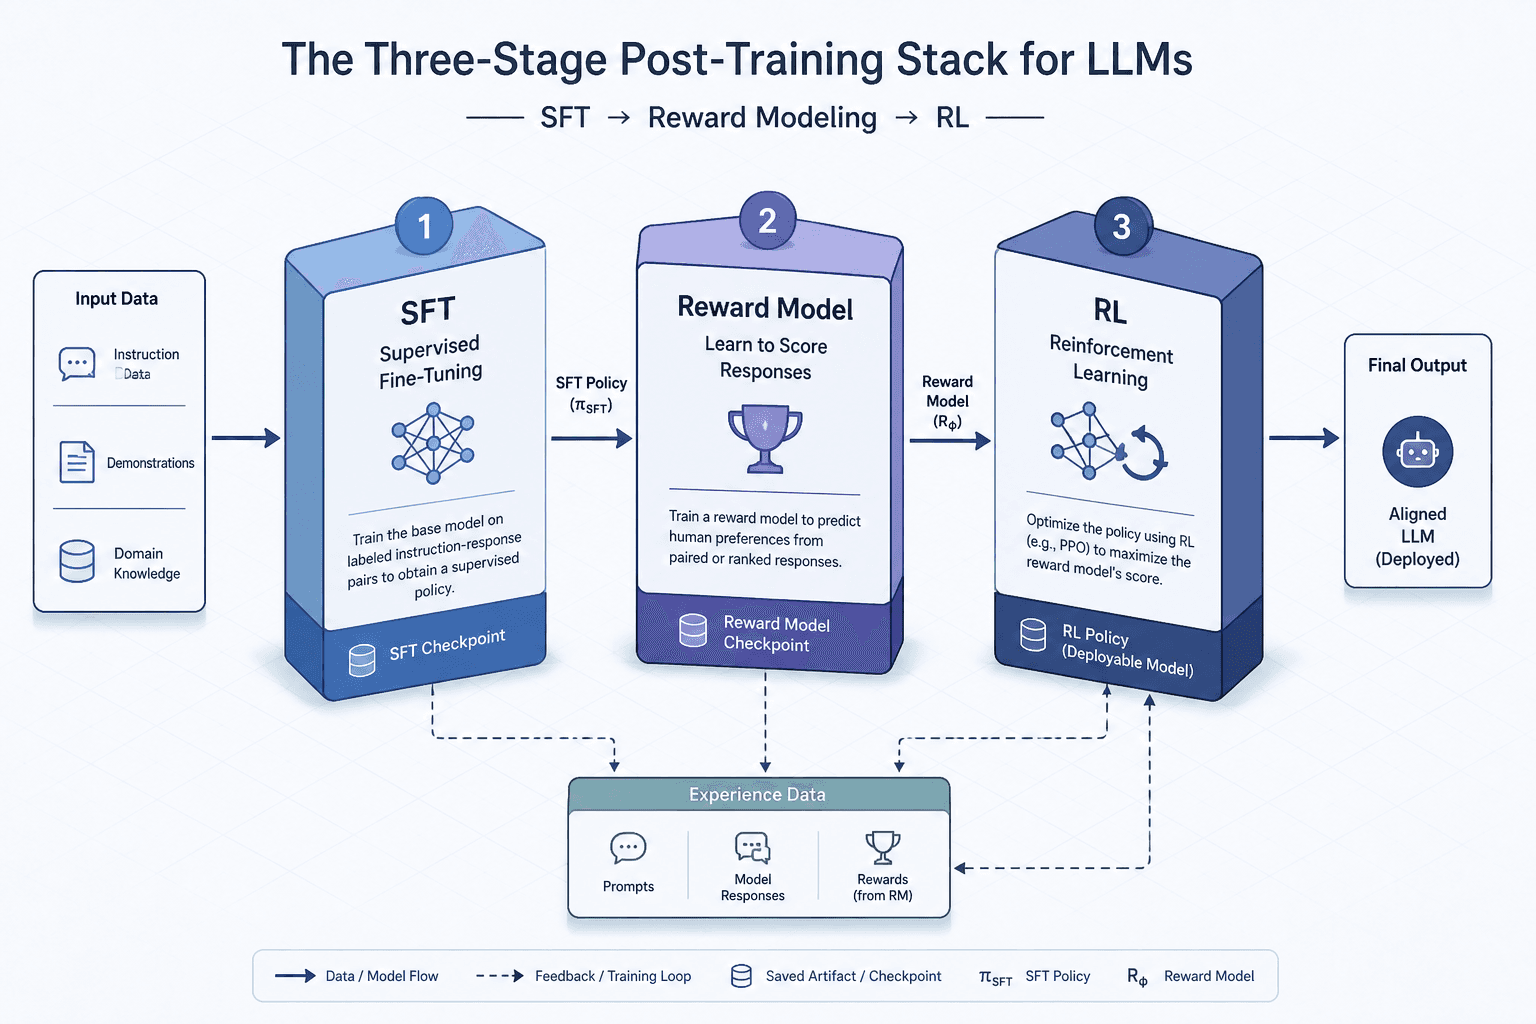
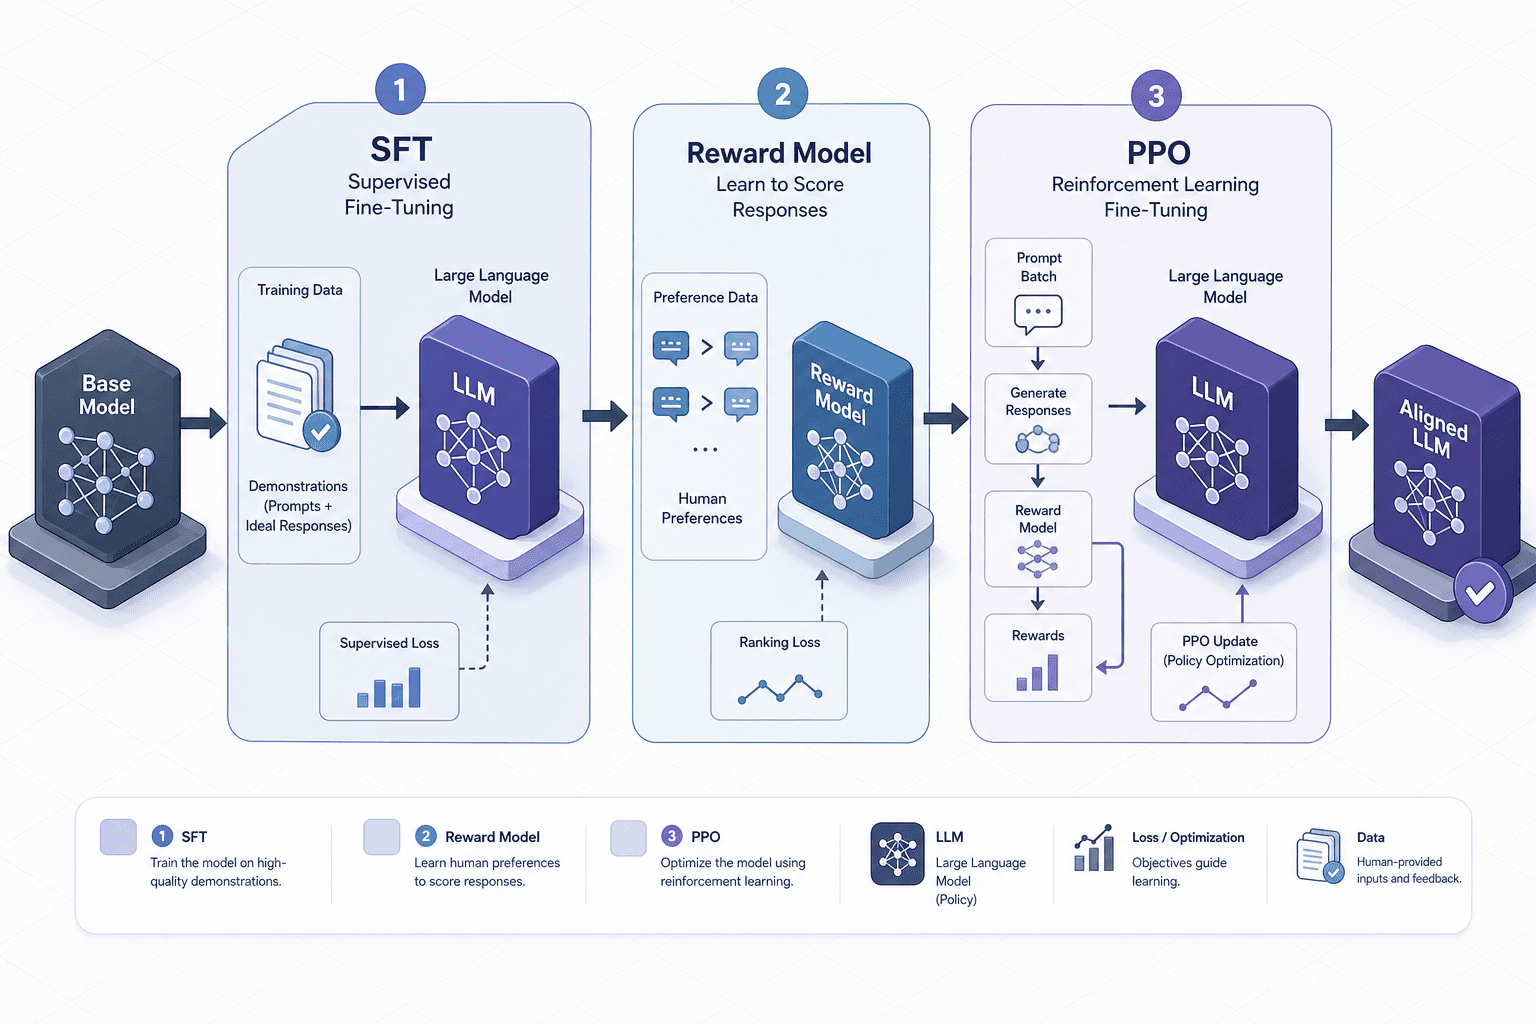
Understand the mechanics of RLHF, from collecting human preferences to training reward models and fine-tuning LLMs with PPO and KL constraints.
Part 2 · Post-Training & AlignmentTag
Read 2 articles on Reward Model by Ashish Srivastava — practical guides covering implementation patterns, security, and production lessons.
2 posts
Understand the mechanics of RLHF, from collecting human preferences to training reward models and fine-tuning LLMs with PPO and KL constraints.
Part 2 · Post-Training & AlignmentExplore the core components of the post-training stack: SFT, reward models, and RL. Learn how these techniques align large language models with human intent.
Part 1 · Post-Training & Alignment