6 min readDevelopmentFeatured
TensorRT-LLM: When the Extra Build Complexity Pays Off
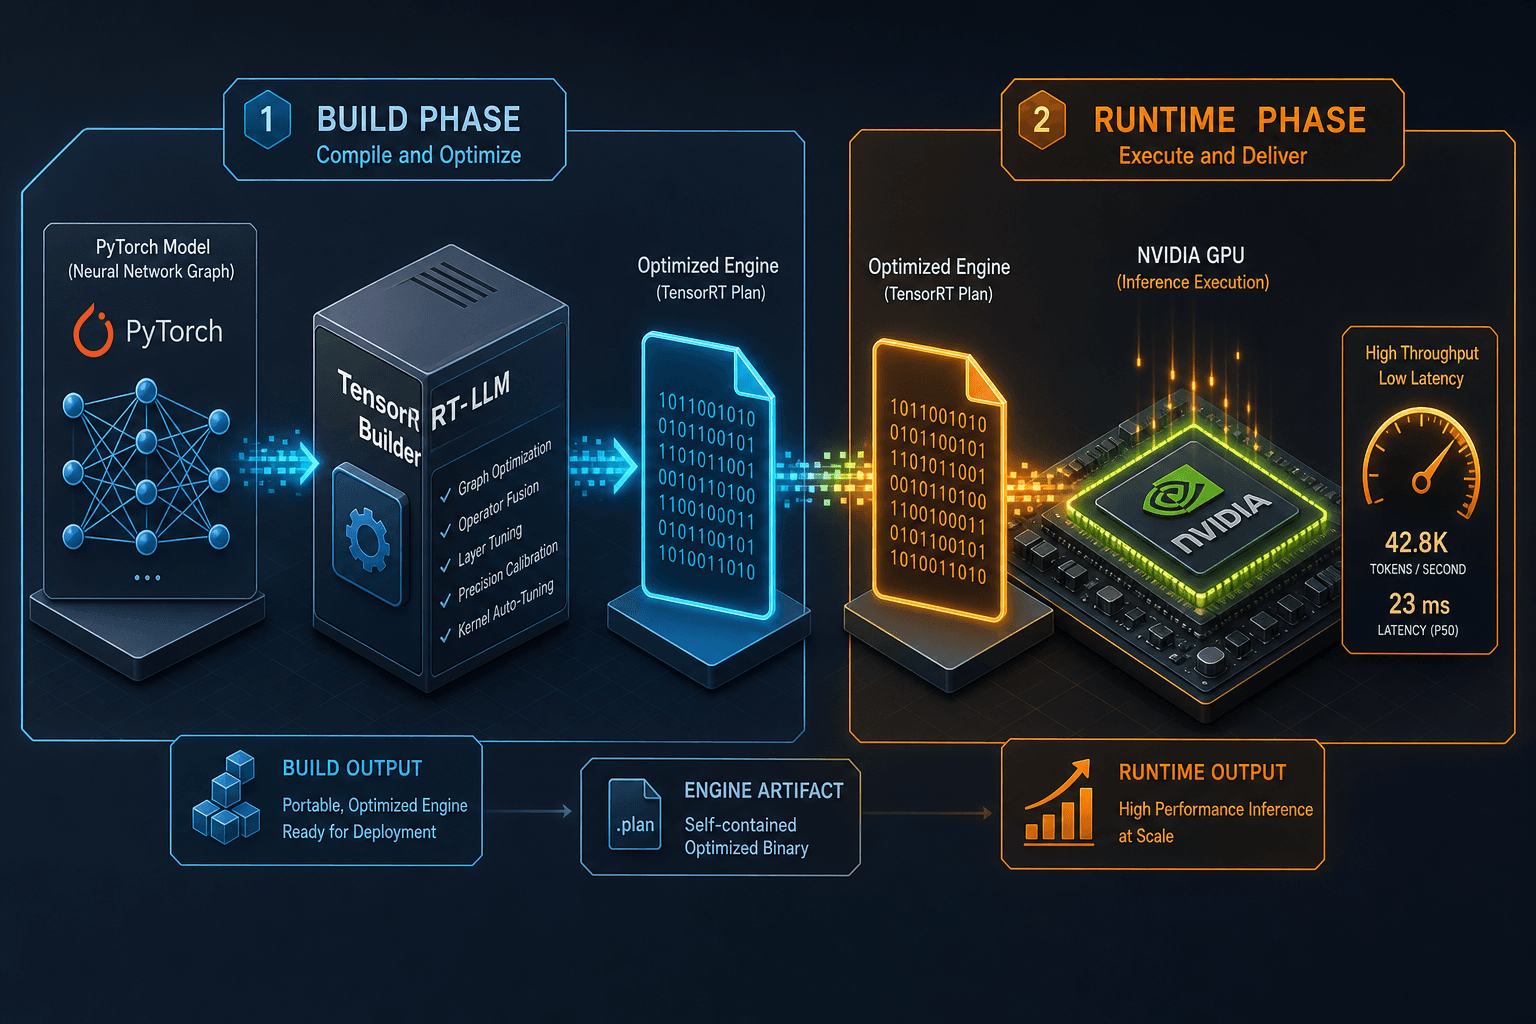
Explore why the extra steps in building TensorRT-LLM engines are justified by the substantial performance improvements they bring to inference workloads.
Tag
Read 2 articles on Gpu Optimization by Ashish Srivastava — practical guides covering implementation patterns, security, and production lessons.
2 posts
Explore why the extra steps in building TensorRT-LLM engines are justified by the substantial performance improvements they bring to inference workloads.
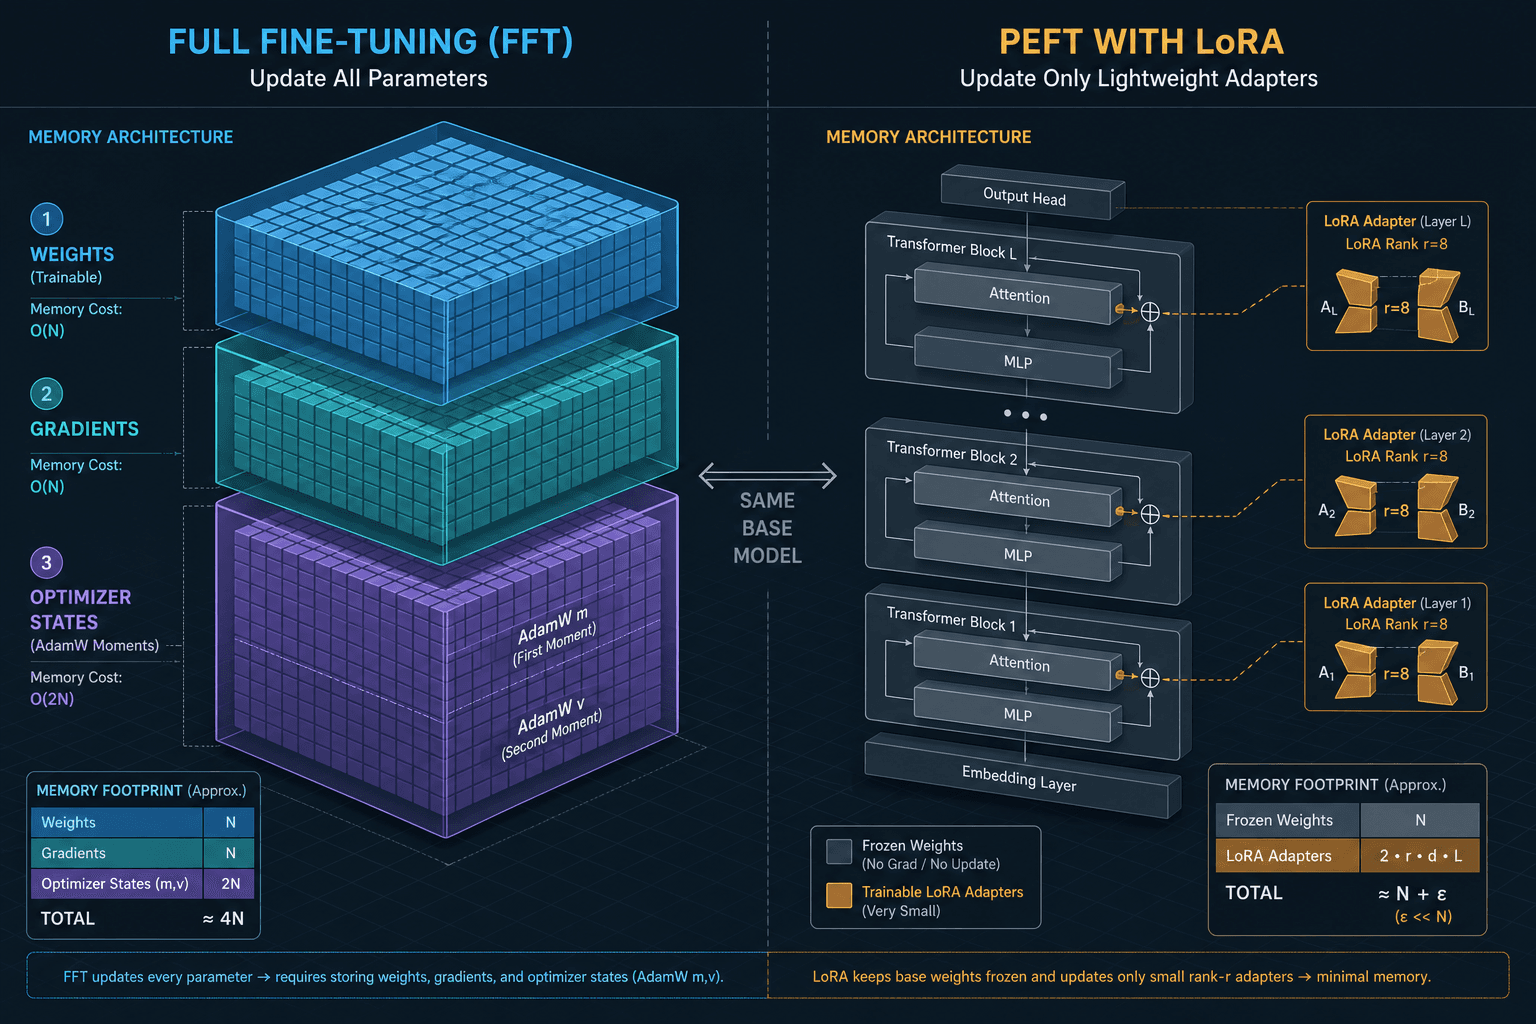
Compare the memory requirements of full fine-tuning and PEFT. We break down the math on optimizer states, activation checkpointing, and GPU utilization.
Part 2 · Fine-Tuning LLMs Hands-On