6 min readDevelopmentFeatured
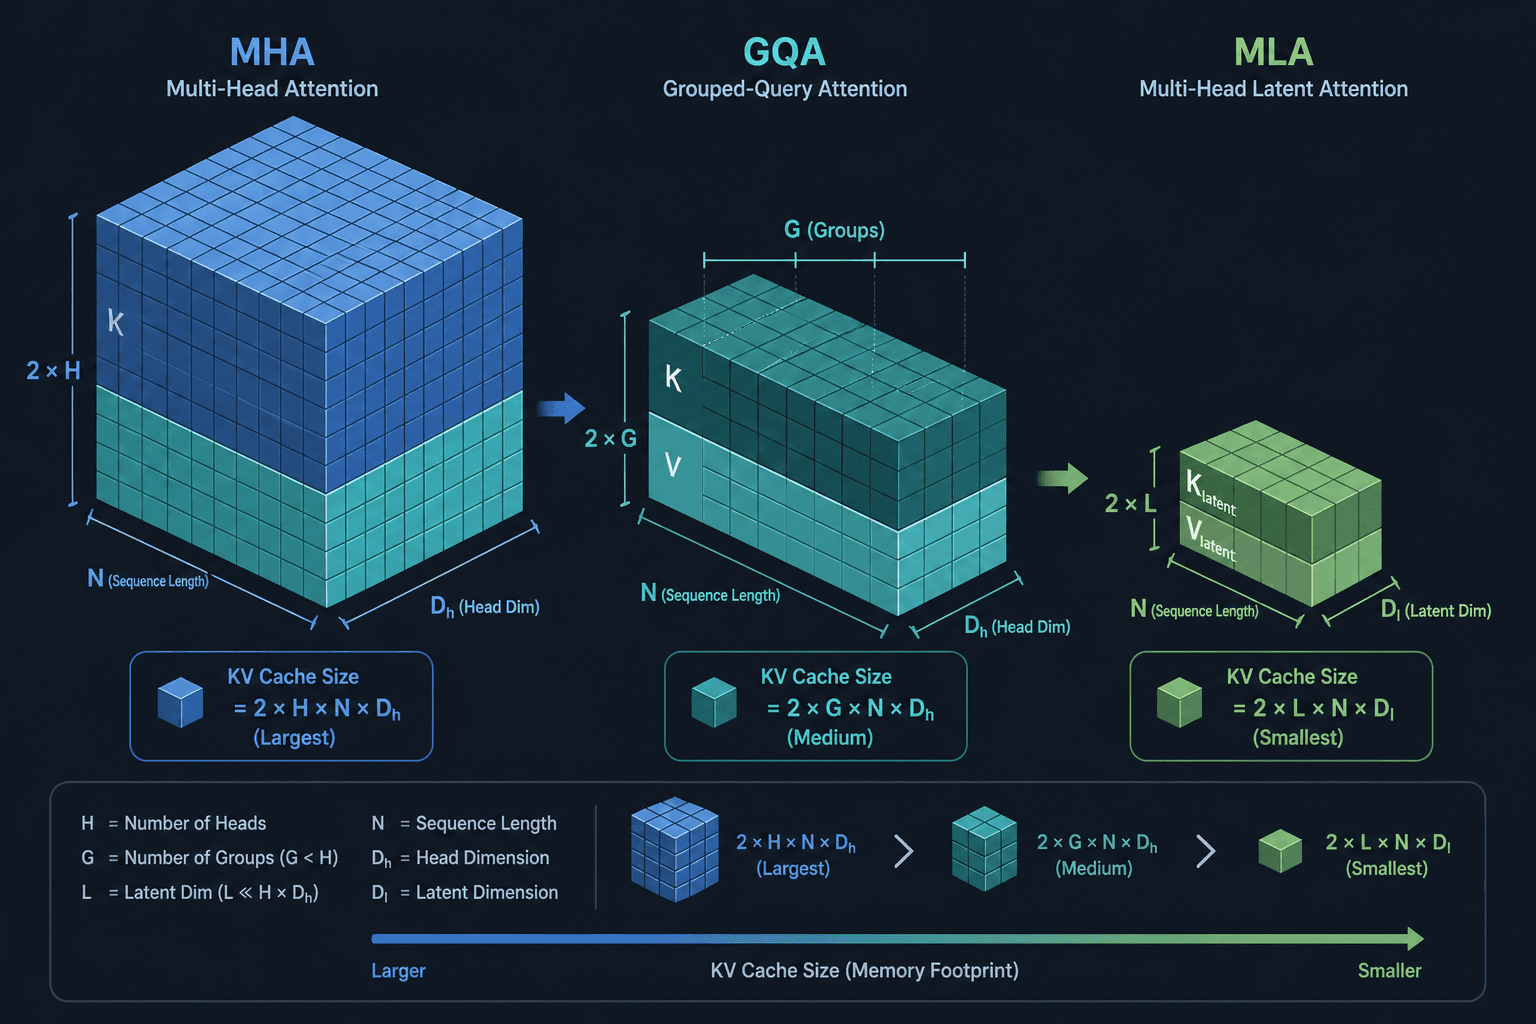
Multi-Head, Grouped-Query, and Multi-Head Latent Attention
Explore how MHA, GQA, and MLA architectures balance memory usage and computational efficiency in large language models, with a focus on reducing KV cache overhead.
Part 2 · Transformers Under the Hood