6 min readDevelopmentFeatured
Speculative Decoding: 2x Throughput for Free?
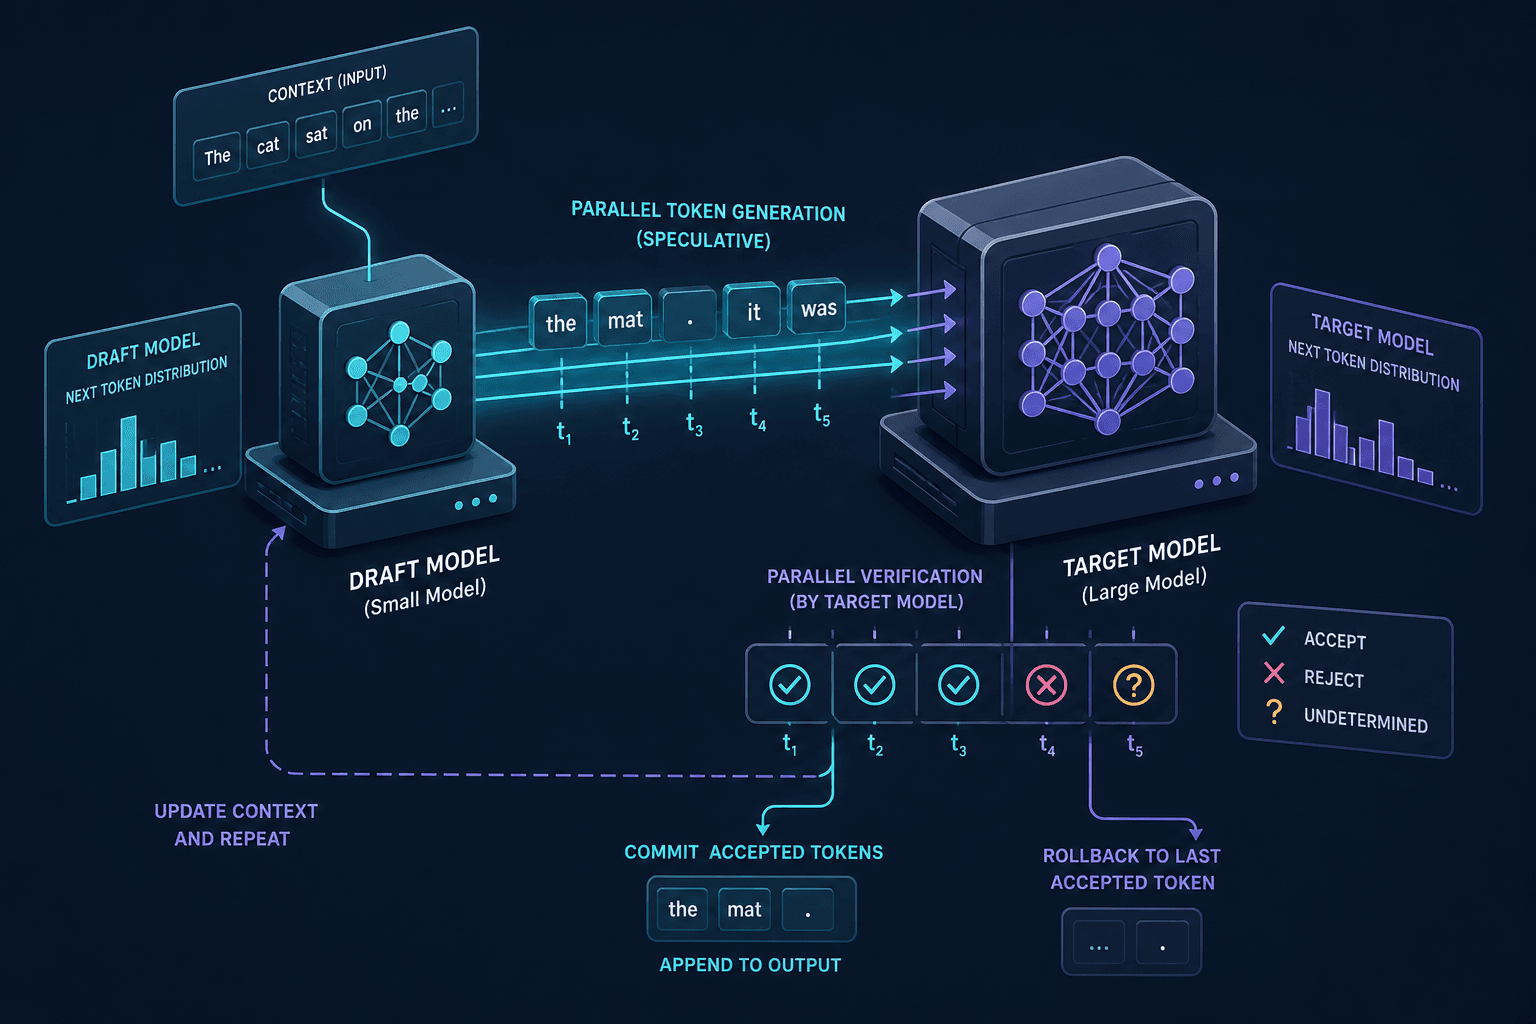
Explore how speculative decoding accelerates LLM inference by using smaller draft models to predict tokens, achieving significant throughput gains without compromising quality.