6 min readDevelopmentFeatured
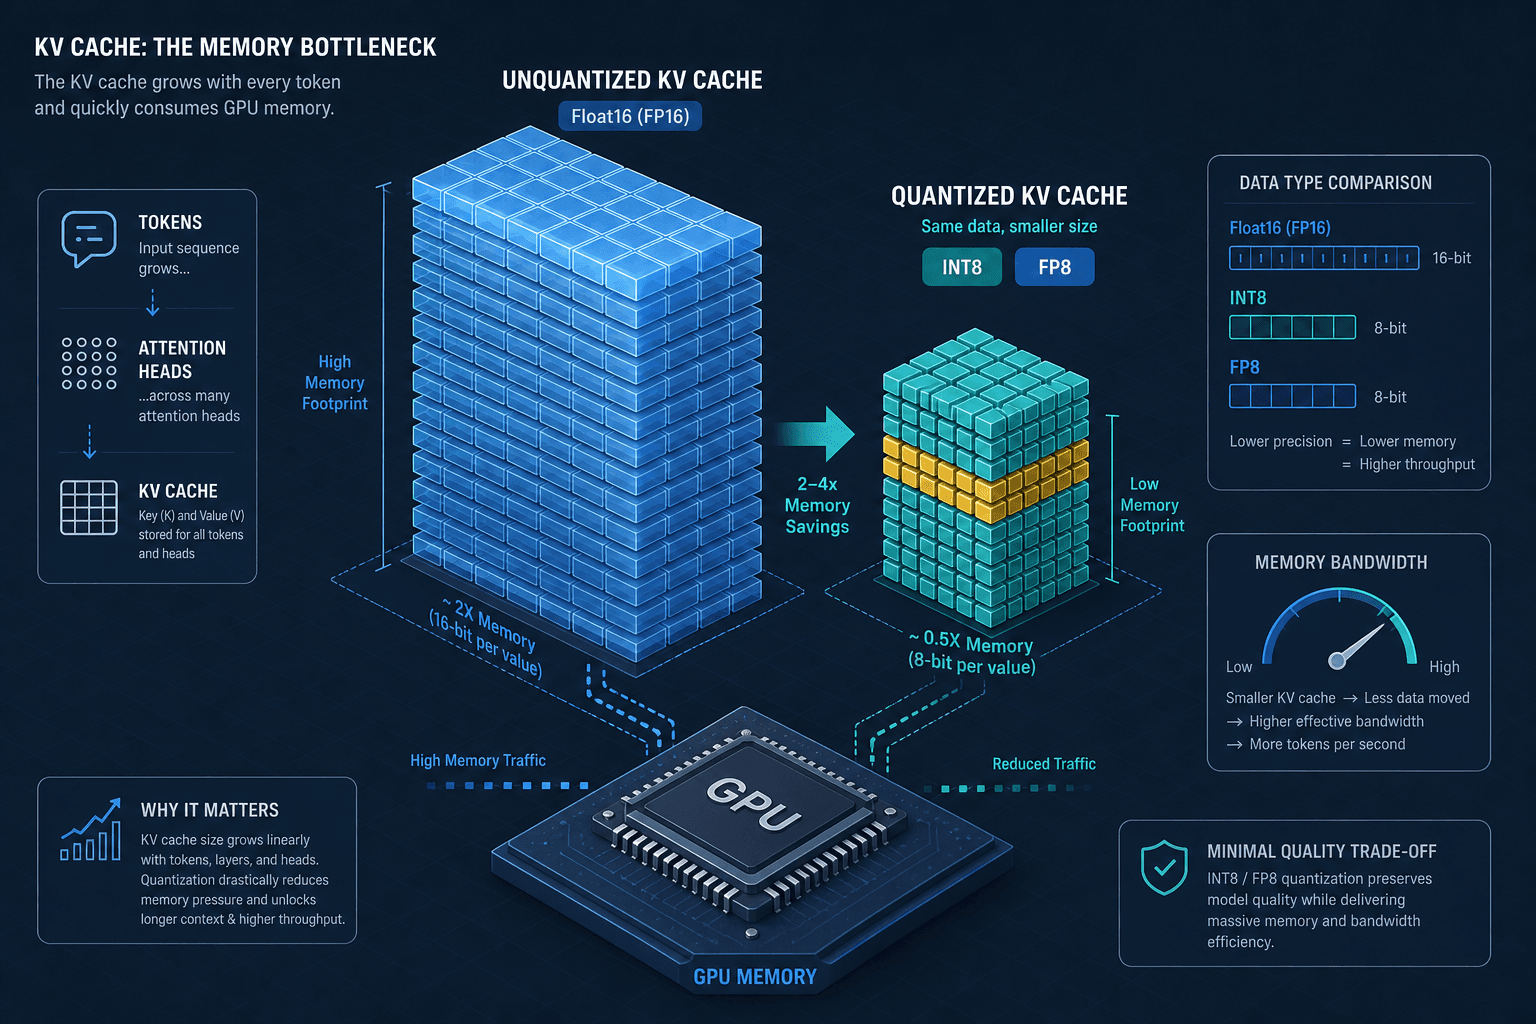
Quantizing the KV Cache Without Wrecking Quality
Learn how to apply quantization to the KV cache to save memory and speed up inference without significantly degrading model quality.
Part 4 · Quantization in PracticeTag
Read 1 article on Memory Efficiency by Ashish Srivastava — practical guides covering implementation patterns, security, and production lessons.
1 post · thin content (not indexed)
Learn how to apply quantization to the KV cache to save memory and speed up inference without significantly degrading model quality.
Part 4 · Quantization in Practice