6 min readDevelopmentFeatured
QLoRA: Fine-Tuning a 70B on One GPU
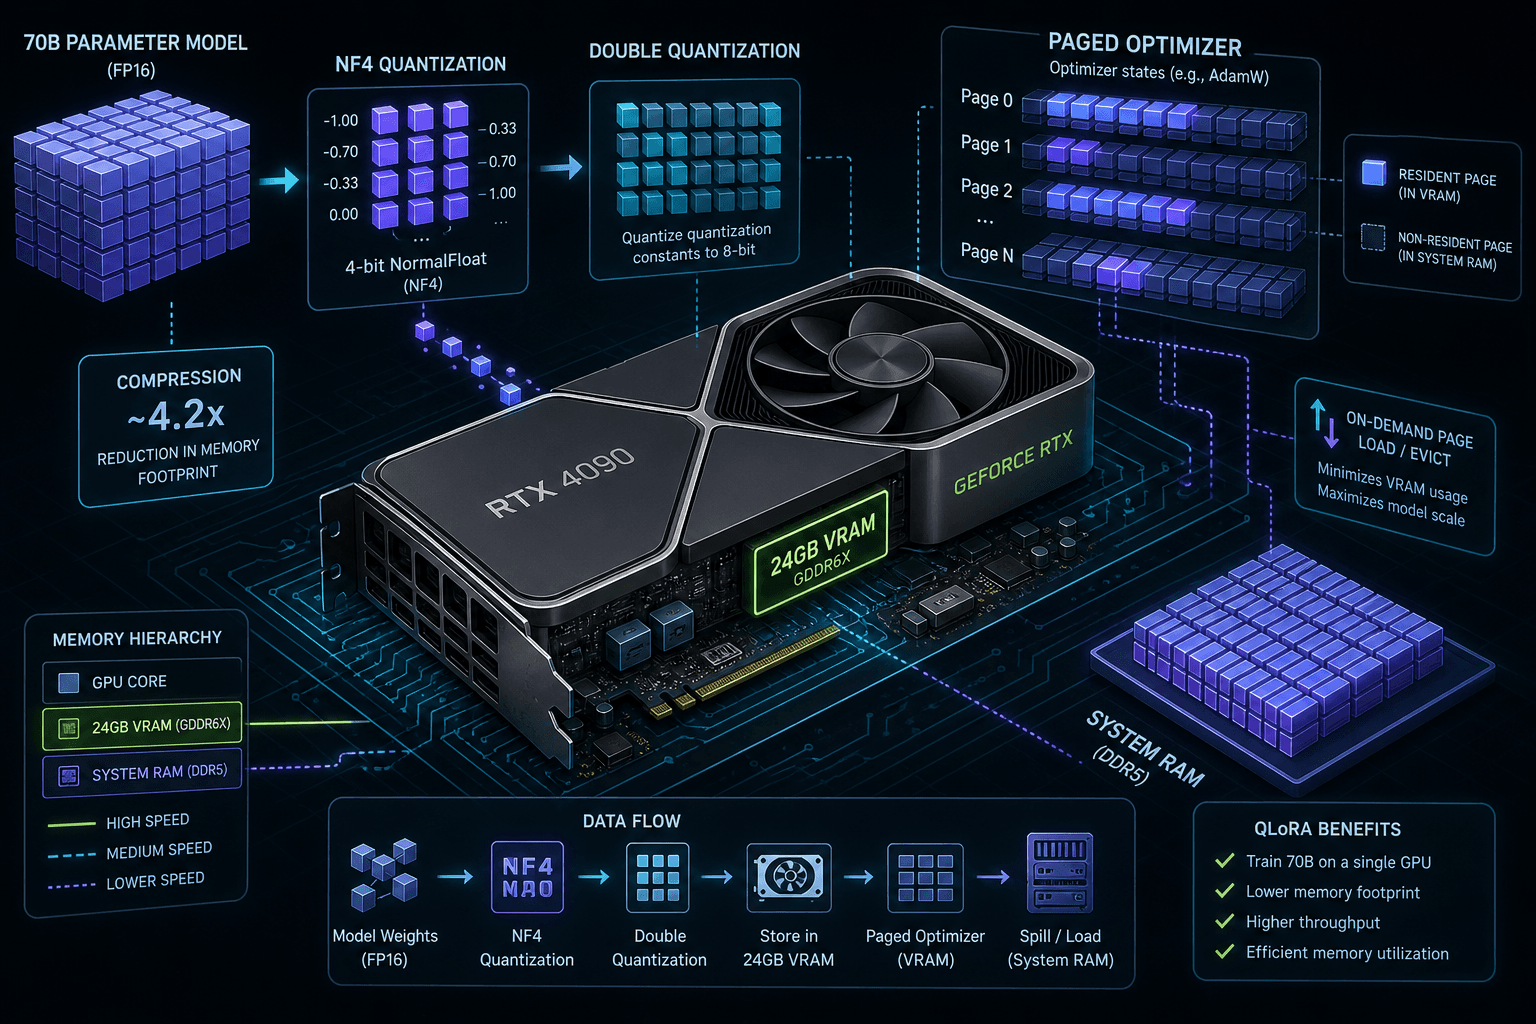
Learn how to fit 70B models into single-GPU memory using QLoRA, NF4 quantization, and paged optimizers for efficient fine-tuning.
Part 4 · Fine-Tuning LLMs Hands-OnTag
Read 2 articles on Memory Optimization by Ashish Srivastava — practical guides covering implementation patterns, security, and production lessons.
2 posts
Learn how to fit 70B models into single-GPU memory using QLoRA, NF4 quantization, and paged optimizers for efficient fine-tuning.
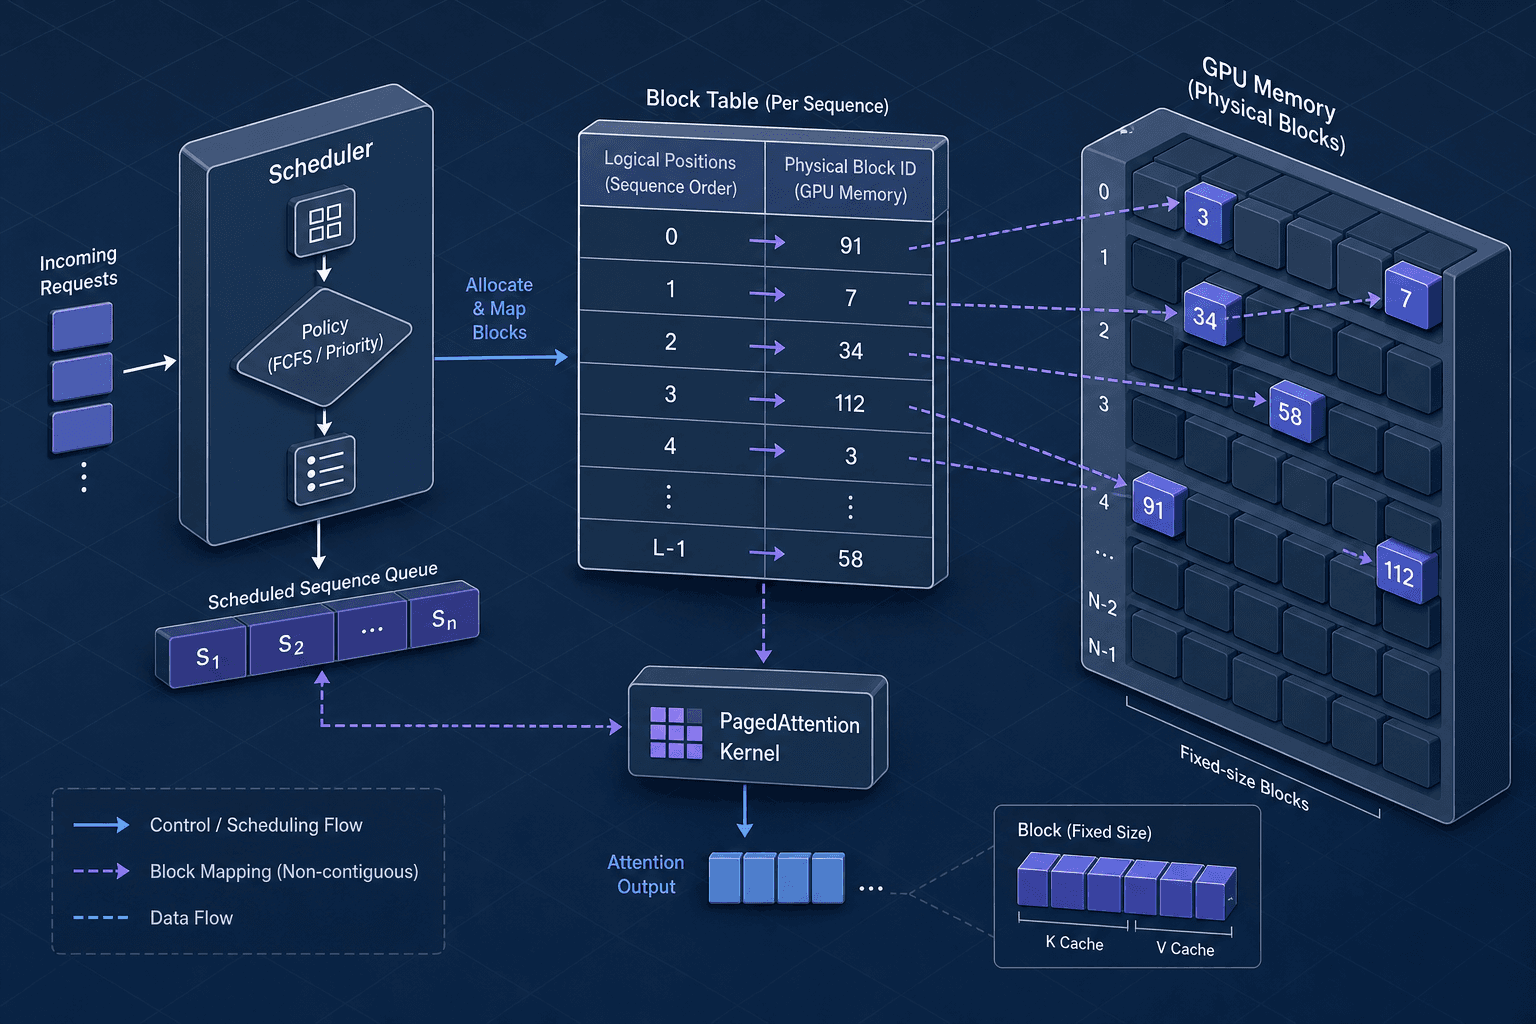
Part 4 · Fine-Tuning LLMs Hands-OnExplore how vLLM uses PagedAttention and a scheduler to optimize memory usage and throughput for large language models.
Part 1 · Production vLLM