6 min readDevelopmentFeatured
Chunked Prefill: Smoothing Out Your Tail Latency
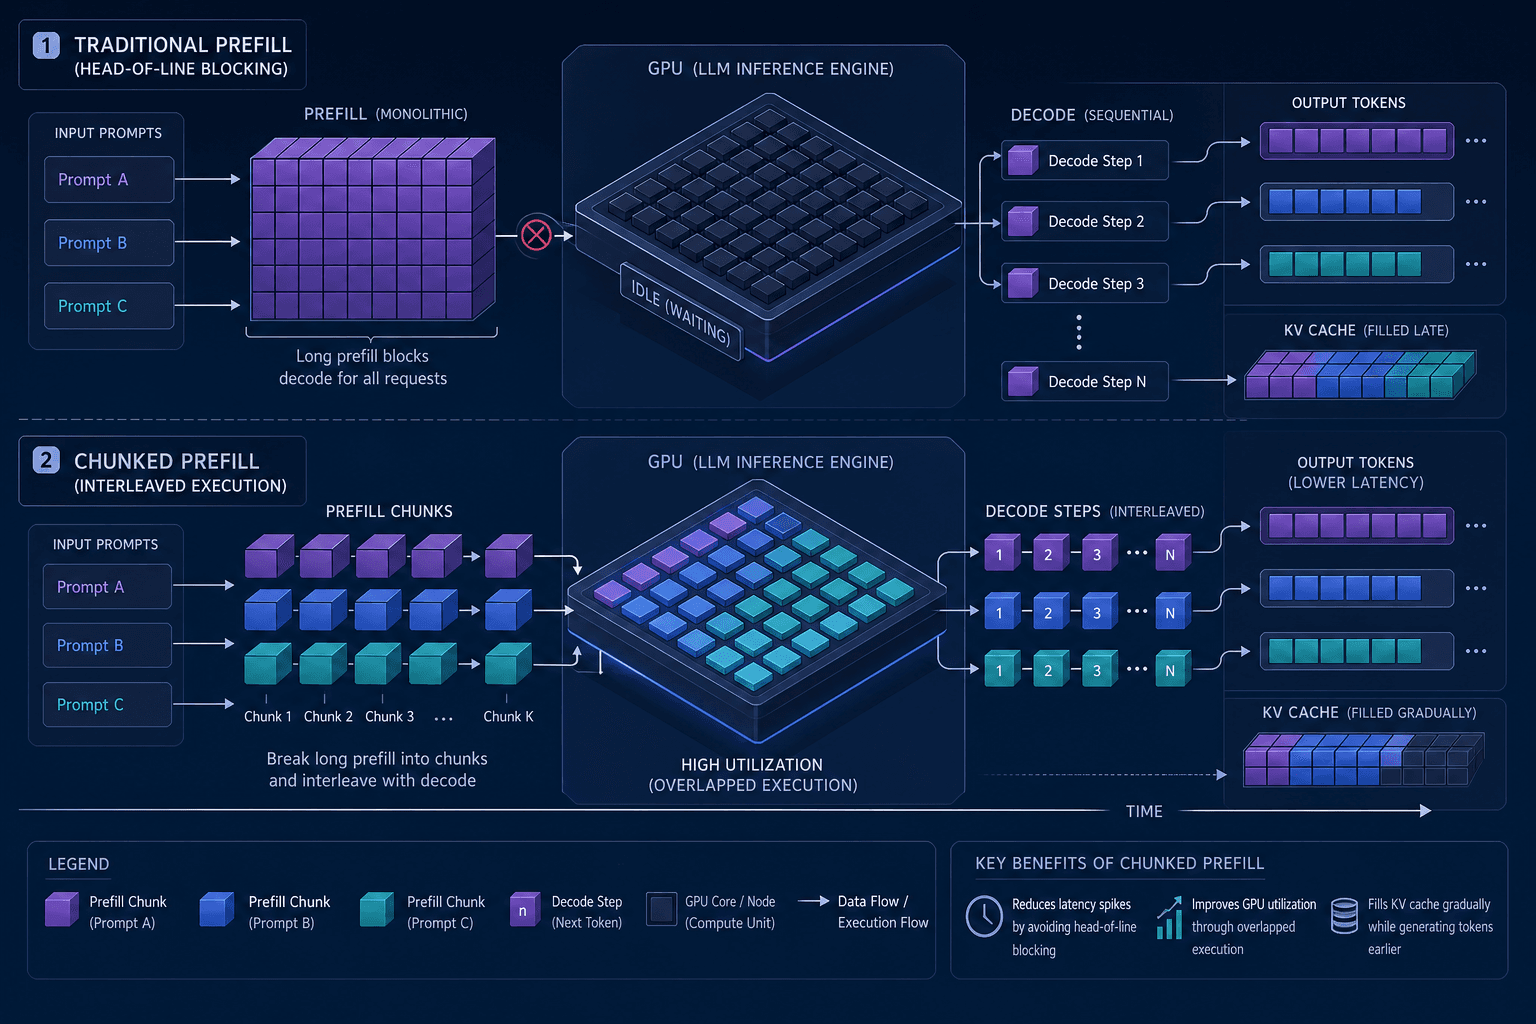
Learn how chunked prefill mitigates head-of-line blocking to smooth out p99 latency spikes in large language model serving.
Tag
Read 2 articles on P99 by Ashish Srivastava — practical guides covering implementation patterns, security, and production lessons.
2 posts
Learn how chunked prefill mitigates head-of-line blocking to smooth out p99 latency spikes in large language model serving.
Understanding TTFT, TPOT, and p99 is essential for optimizing LLM inference. This guide breaks down these metrics for SREs and backend developers.
Part 6 · LLM Inference from Scratch