Identity Analytics: Which Algorithms Actually Work
An examination of effective algorithms for identity analytics, focusing on anomaly detection, peer group analysis, and handling imbalanced data in security contexts.
In identity security, the "normal" state of a system is often indistinguishable from a compromised one across many dimensions. A user logging in from a new device might simply be traveling; a user accessing large volumes of data might be migrating files. This ambiguity creates a unique challenge for data scientists and security engineers: how do you detect a needle in a haystack where the haystack is constantly reshaping itself?
Generic anomaly detection algorithms often fail here because they assume a static definition of "normal." In reality, identity behavior is contextual. To build effective identity analytics, we must move beyond simple thresholding and embrace algorithms that understand peer context and handle extreme class imbalance. This article examines which mechanisms actually deliver value in production environments.
The Imbalance Trap
The primary reason most machine learning identity security models fail in identity security is class imbalance. In a typical enterprise directory, the ratio of malicious events to benign events is often less than 1:10,000. When you train a standard classifier (like Logistic Regression or Random Forest) on this data, the model learns to predict "benign" for every single input. This achieves 99.99% accuracy but provides zero value in machine learning identity security contexts.
The mechanism of failure lies in the loss function. Standard cross-entropy loss penalizes misclassification equally. If 99.99% of the data is class 0 (benign), the gradient descent optimization will prioritize minimizing error on class 0, effectively ignoring class 1 (threat).
To fix this, you cannot rely on accuracy. You must optimize for Precision-Recall AUC. However, metric selection is only half the solution. You must also adjust the algorithm's internal mechanics. Two approaches work in practice:
- Cost-Sensitive Learning: Assign a higher penalty to false negatives than false positives. For example, in a Random Forest, you can set
class_weight='balanced'in scikit-learn, which inversely scales weights proportional to class frequencies. This forces the model to pay attention to the rare class. - Resampling (With Caution): Techniques like SMOTE (Synthetic Minority Over-sampling Technique) generate synthetic samples for the minority class. However, in time-series identity data, SMOTE can create unrealistic hybrid behaviors that don't exist in reality. Instead, use undersampling of the majority class or specialized techniques like ADASYN that focus on difficult-to-learn examples.
Peer Group Analysis: Context Over Global Norms
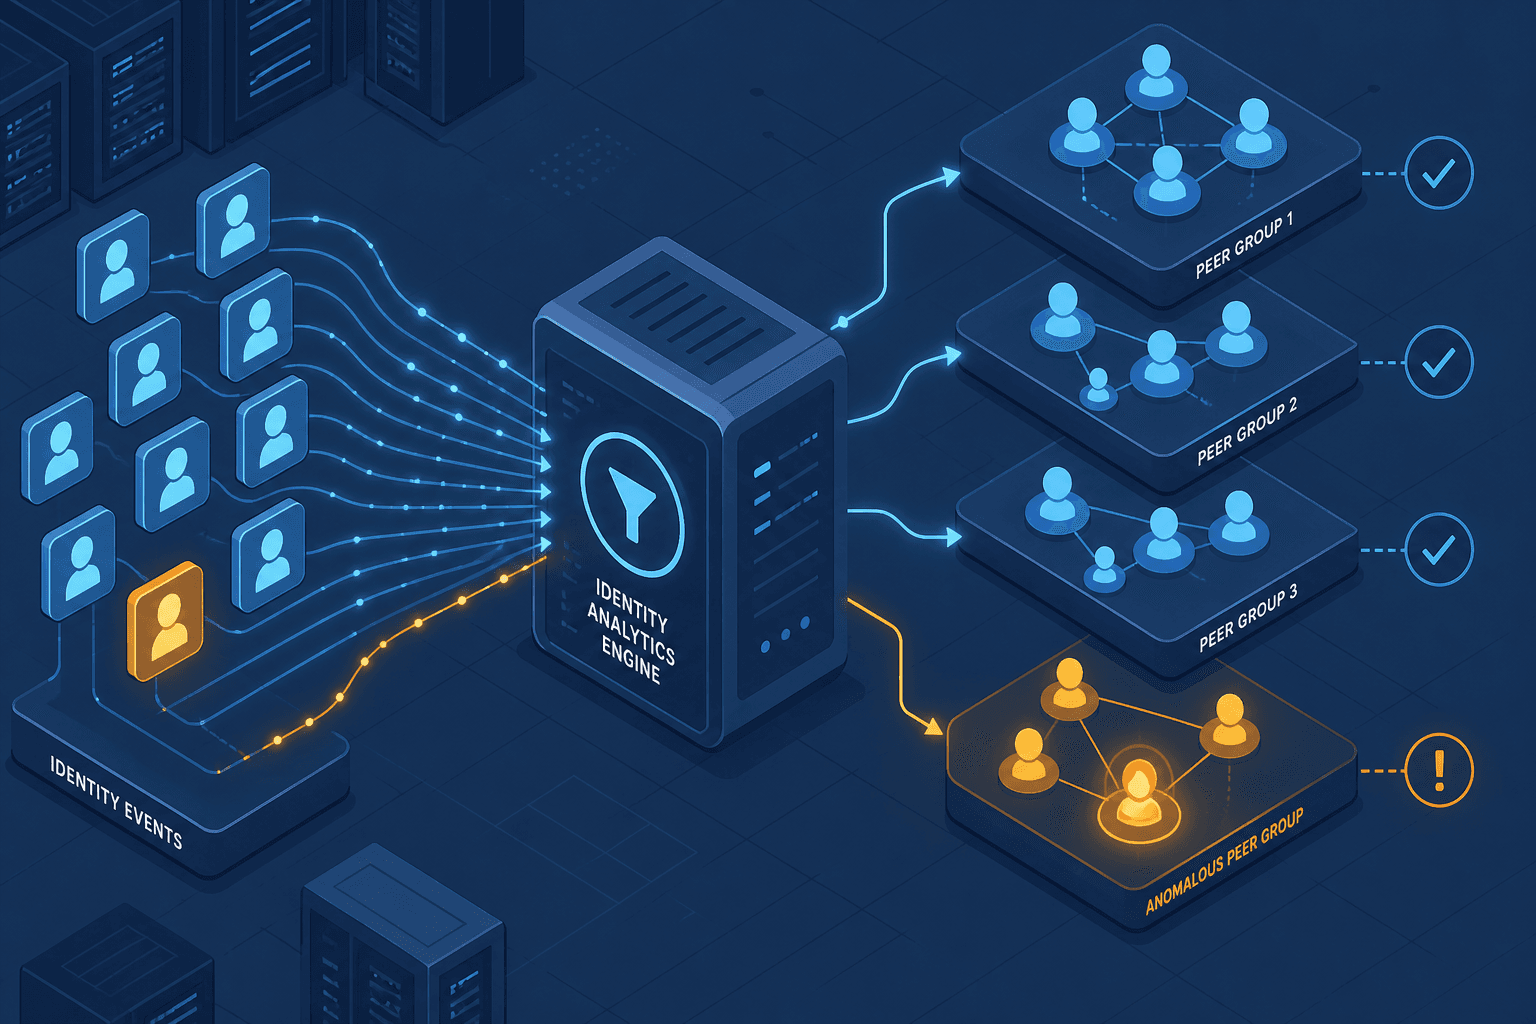
In the realm of machine learning identity security, global anomaly detection often falls short because it asks: "Is this event unusual compared to all users?" Peer Group Analysis (PGA) asks: "Is this event unusual compared to users with similar roles and privileges?"
PGA is the most effective mechanism for reducing false positives in machine learning identity security pipelines. Consider a Chief Financial Officer (CFO). If the CFO logs in at 3 AM from a new IP, a global model might flag this as an anomaly. However, if the model compares the CFO only to other executives, it might find that executive travel is a common pattern. Conversely, if a junior developer accesses the payroll database, PGA will flag this immediately because no other developers have that access profile.
The Mechanism of PGA
PGA operates in two stages:
- Clustering: Group users based on static attributes (department, job title, location) and dynamic attributes (typical login times, resource access patterns). Algorithms like HDBSCAN (Hierarchical Density-Based Spatial Clustering of Applications with Noise) are preferred over K-Means because they do not require pre-specifying the number of clusters and can handle noise (users who don't fit neatly into groups).
- Deviation Scoring: Once a user is assigned to a peer group, calculate their deviation from the group's median behavior. If User A is in the "Engineering" cluster, compare their file access volume against the 75th percentile of the Engineering cluster, not the entire company.
This approach transforms a global outlier problem into a local relative problem, significantly improving signal-to-noise ratio.
Algorithms That Work in Production
When selecting algorithms for machine learning identity security, not all anomaly detection methods are created equal. In identity analytics, three classes of algorithms stand out for their practical utility in machine learning identity security.
1. Isolation Forests
Isolation Forests are the workhorse of modern identity analytics. The mechanism is counter-intuitive: instead of profiling normal data, it isolates anomalies. It builds random trees by randomly selecting a feature and then randomly selecting a split value between the maximum and minimum values of the selected feature.
Anomalies are easier to isolate because they are few and different. They require fewer splits to be separated from the rest of the data. Normal points require many more splits to be isolated. The algorithm assigns an anomaly score based on the average path length across a forest of trees.
Why it works for identity:
- Efficiency: O(n) time complexity makes it scalable to millions of identity events.
- No Distribution Assumption: Unlike Gaussian models, it doesn't assume data follows a bell curve, which is crucial for identity data that is often multimodal.
- High-Dimensional Data: Handles the many features typical in IAM logs (timestamp, source IP, destination app, device type, etc.) well.
from sklearn.ensemble import IsolationForest

# Initialize with contamination rate reflecting low threat frequency
model = IsolationForest(contamination=0.001, random_state=42)

# Fit on benign identity logs (unlabeled or labeled as 'benign')
model.fit(benign_identity_features)

# Predict anomalies (-1 for anomaly, 1 for normal)
predictions = model.predict(identity_events)
2. Autoencoders
Autoencoders are neural networks trained to reconstruct their input. They consist of an encoder that compresses the input into a latent space representation and a decoder that reconstructs the input from that representation.
In identity analytics, you train an autoencoder exclusively on benign behavior. During inference, if a user's behavior is anomalous, the network will struggle to reconstruct it accurately, resulting in a high reconstruction error. This error becomes the anomaly score.
Why it works for identity:
- Temporal Patterns: Recurrent Autoencoders (using LSTM or GRU layers) can capture sequences of events. For example, they can learn that a user typically logs in, accesses email, then accesses a CRM, but not the reverse.
- Complex Non-Linearity: They can model complex interactions between features that tree-based models might miss.
However, autoencoders are computationally expensive and harder to interpret. They are best used for high-value targets or complex sequence detection, not as a first-pass filter.
3. One-Class Support Vector Machines (SVM)
One-Class SVM attempts to find a hyperplane that separates the data from the origin in a high-dimensional space. It defines a boundary around the normal data. Points outside this boundary are considered anomalies.
Why it works for identity:
- Robustness: It can be robust to noise if the kernel parameters are tuned correctly.
- Small Data Sets: It performs well when you have limited labeled data, relying only on the majority class.
However, One-Class SVM scales poorly with large datasets (O(n^2) or O(n^3) complexity), making it impractical for large enterprises processing millions of events daily.
Operationalizing the Signal
Operationalizing machine learning identity security signals requires more than just choosing the right algorithm. Identity analytics models generate thousands of alerts daily. If the false positive rate is high, security teams will ignore them—a phenomenon known as alert fatigue.
To ensure your algorithms deliver value in machine learning identity security operations, you must implement a feedback loop. Every alert must be reviewed, labeled as true or false positive, and fed back into the training set. This continuous learning cycle allows the model to adapt to changing user behaviors and new attack patterns.
Furthermore, integrate these models into your SIEM (Security Information and Event Management) or SOAR (Security Orchestration, Automation, and Response) platforms. The goal is not just to detect anomalies but to trigger automated responses, such as requiring multi-factor authentication (MFA) or locking an account, when the anomaly score exceeds a certain threshold.
Conclusion
Effective machine learning identity security requires a shift from global statistical outliers to contextual peer-group baselines. While Isolation Forests offer a strong balance of speed and accuracy for initial triage, Autoencoders provide deeper insights into complex behavioral sequences. Regardless of the algorithm, success depends on handling class imbalance through cost-sensitive learning and maintaining a tight feedback loop to reduce false positives. In identity security, the best algorithm is not the most complex one, but the one that best understands the context of the user within machine learning identity security.
Related posts
OWASP Top 10 for LLM Applications, Applied
A practical examination of the OWASP Top 10 for LLM Applications, covering security checklists, mitigations, and appsec review processes for developers.
Risk-Based Authentication With ML Scoring
Explore how machine learning enhances risk-based authentication by generating dynamic risk scores for adaptive identity verification.
Building Identity Analytics: Mining Authentication Logs for Insights
Learn how to build identity analytics by mining authentication logs with the ELK stack to detect anomalies and gain security insights.
