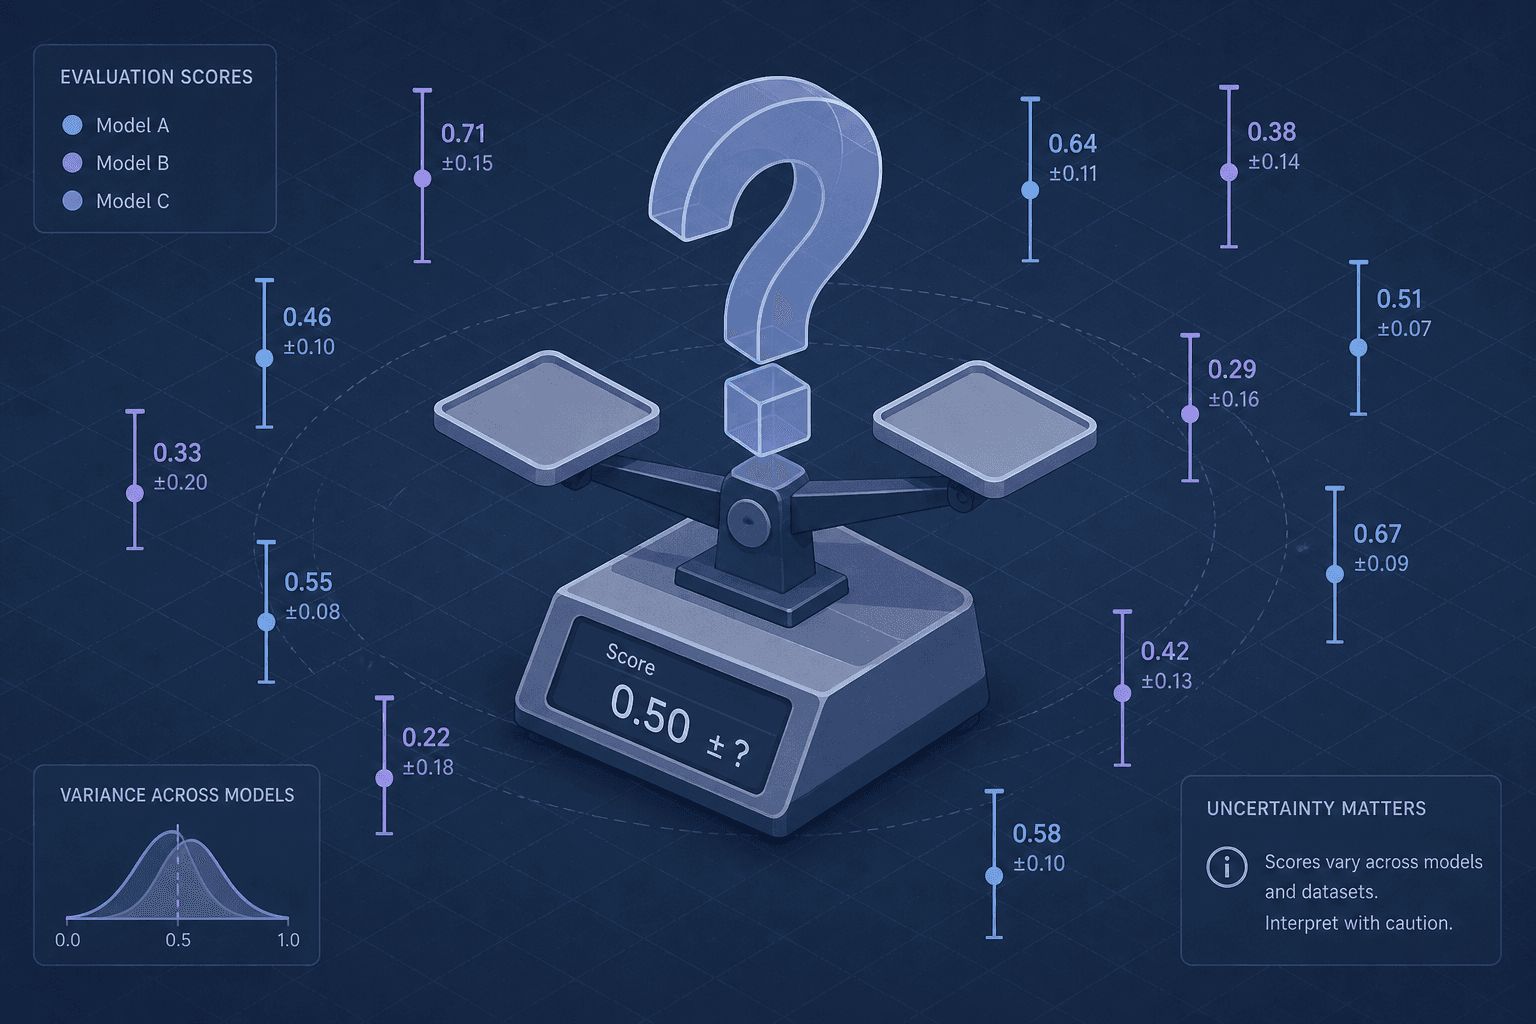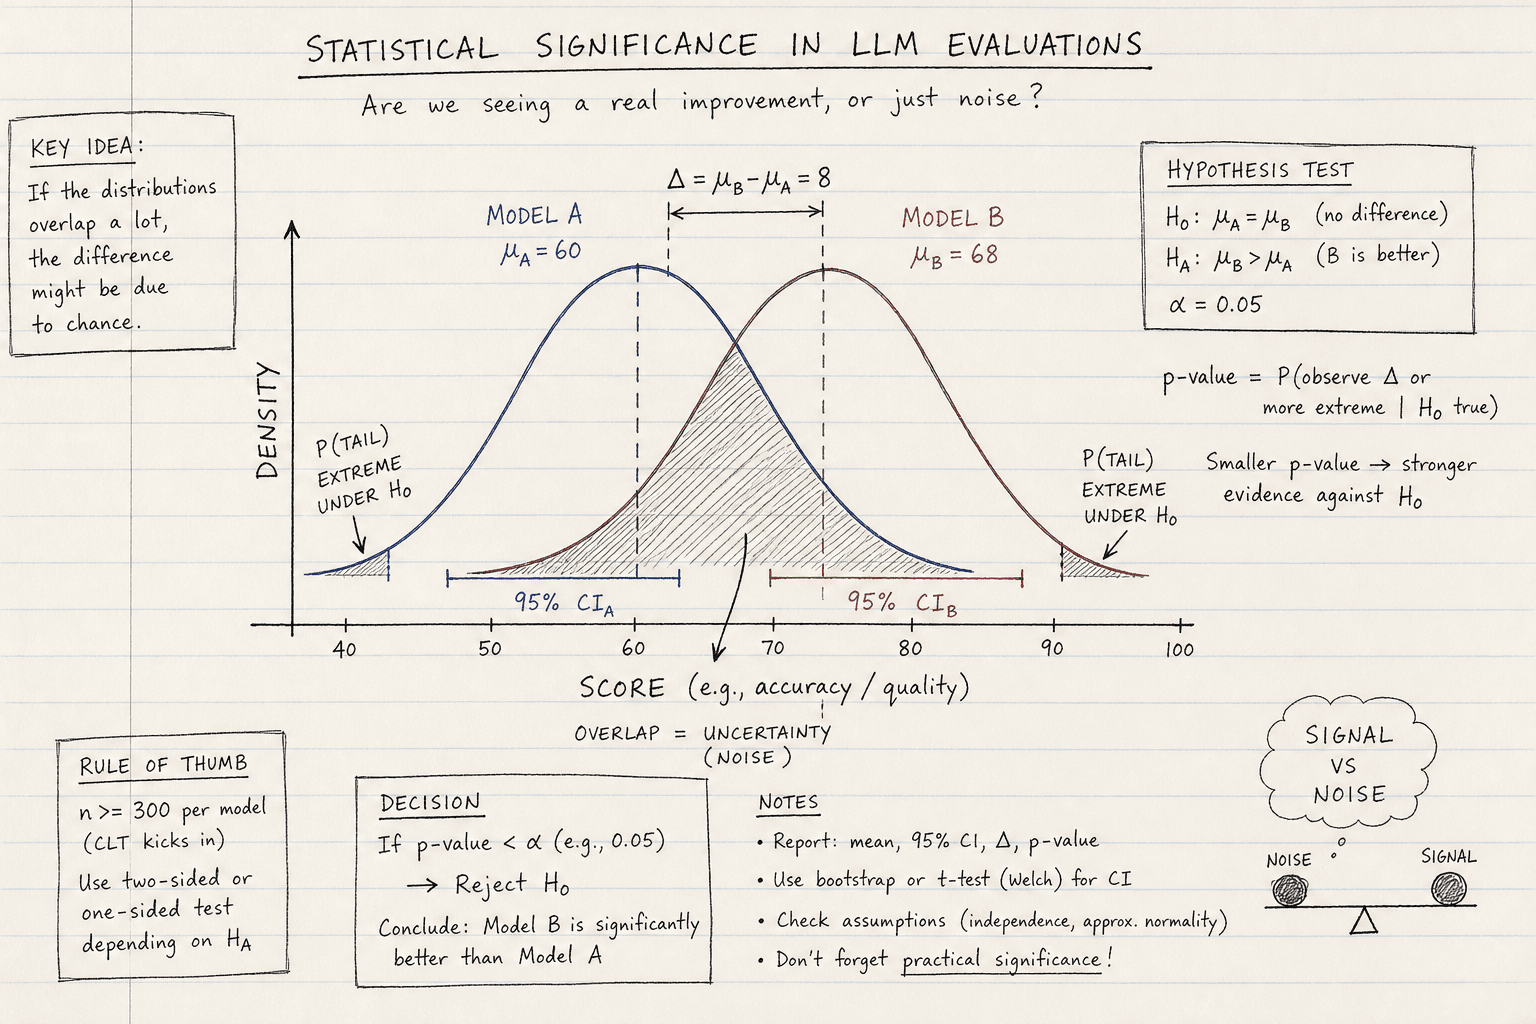
Statistical Significance in LLM Evals
Ensure your LLM evaluation results are reliable by understanding statistical significance, variance, and bootstrap sampling techniques for robust testing.
Part 7 · LLM Evaluation EngineeringTag
Read 8 articles on Llm Evaluation by Ashish Srivastava — practical guides covering implementation patterns, security, and production lessons.
8 posts
Ensure your LLM evaluation results are reliable by understanding statistical significance, variance, and bootstrap sampling techniques for robust testing.
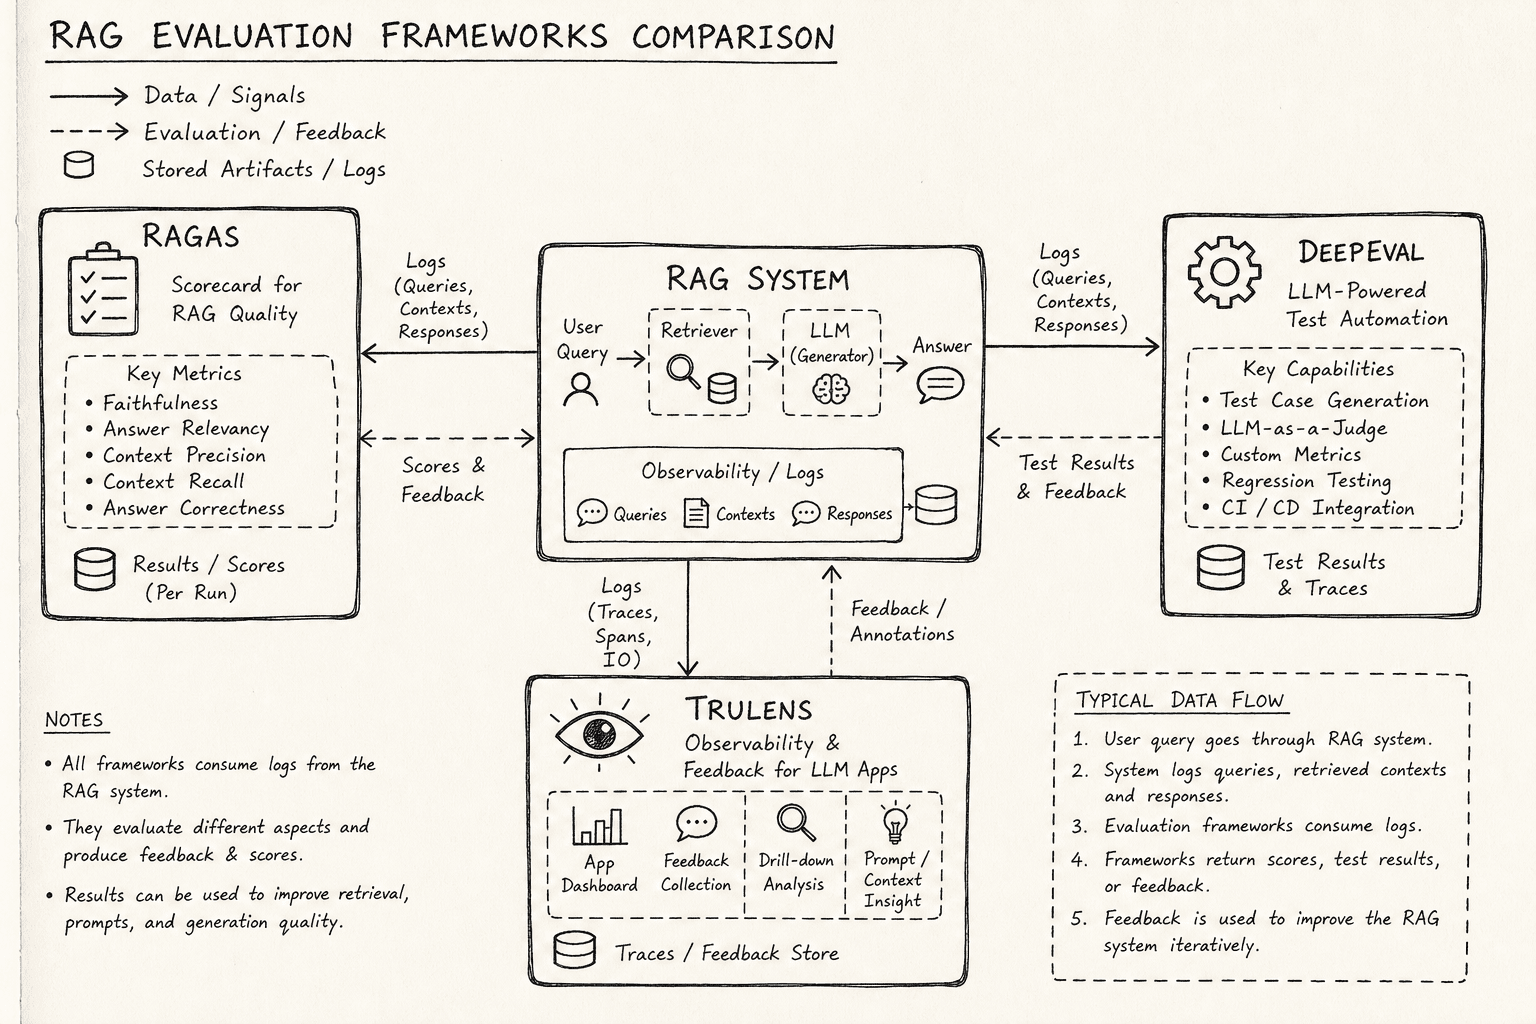
Part 7 · LLM Evaluation EngineeringCompare Ragas, DeepEval, and TruLens for RAG evaluation. See how metric frameworks differ to help ML engineers select the best tool.
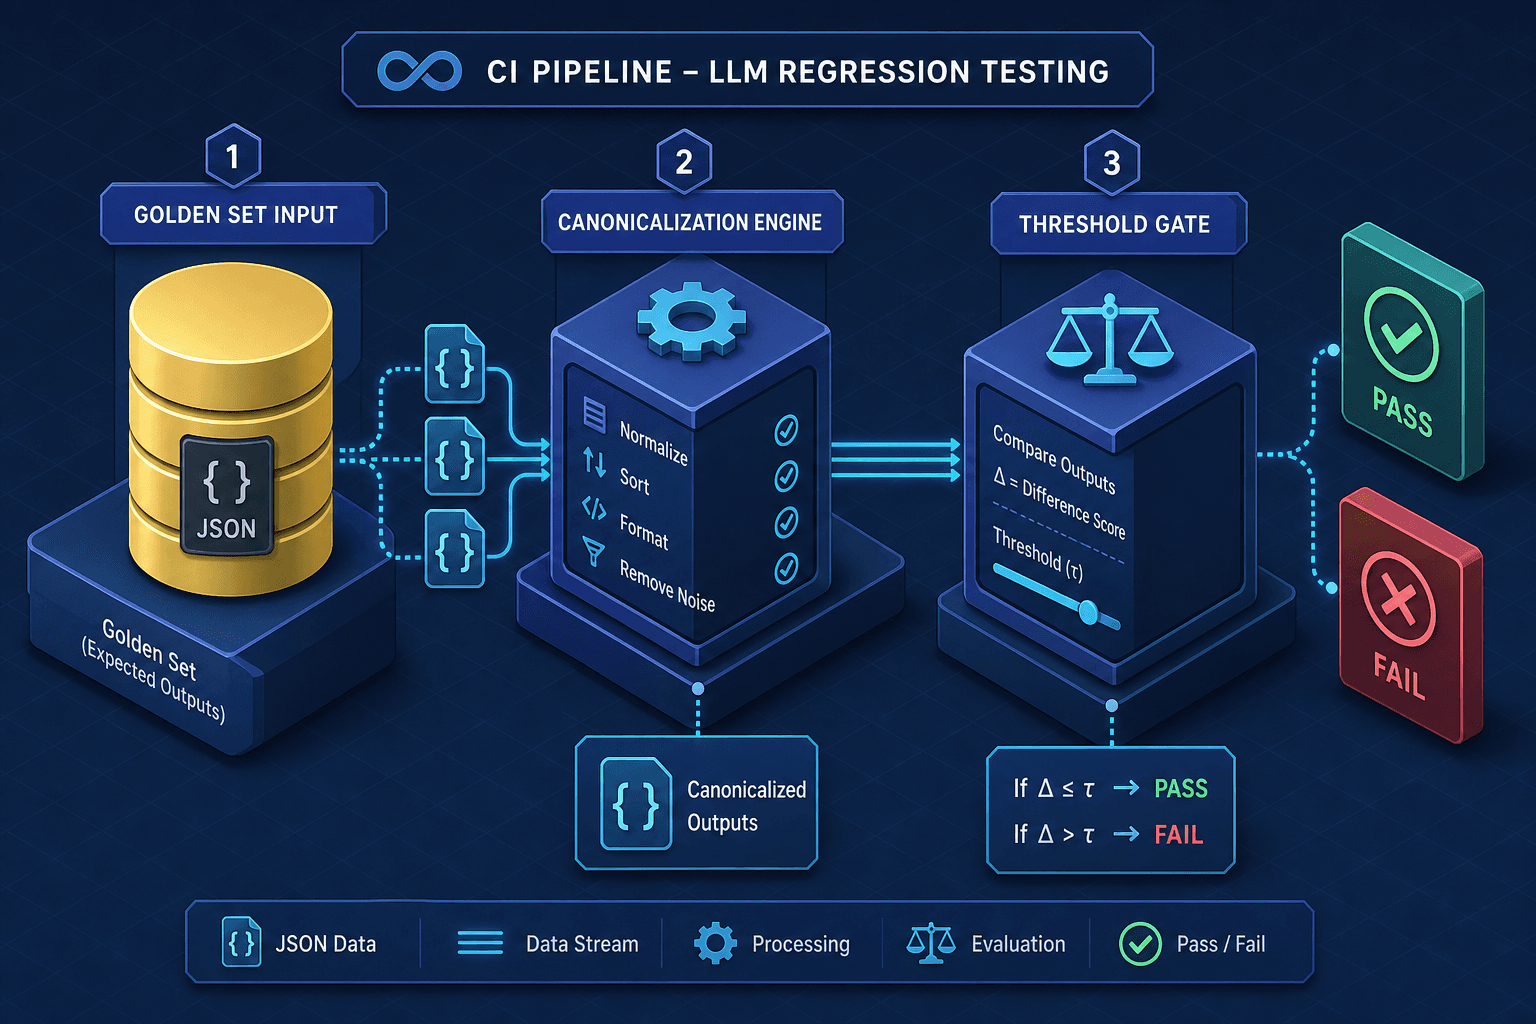
Learn how to establish reliable regression testing for AI models using CI pipelines, snapshot tests, and defined thresholds to maintain output stability.
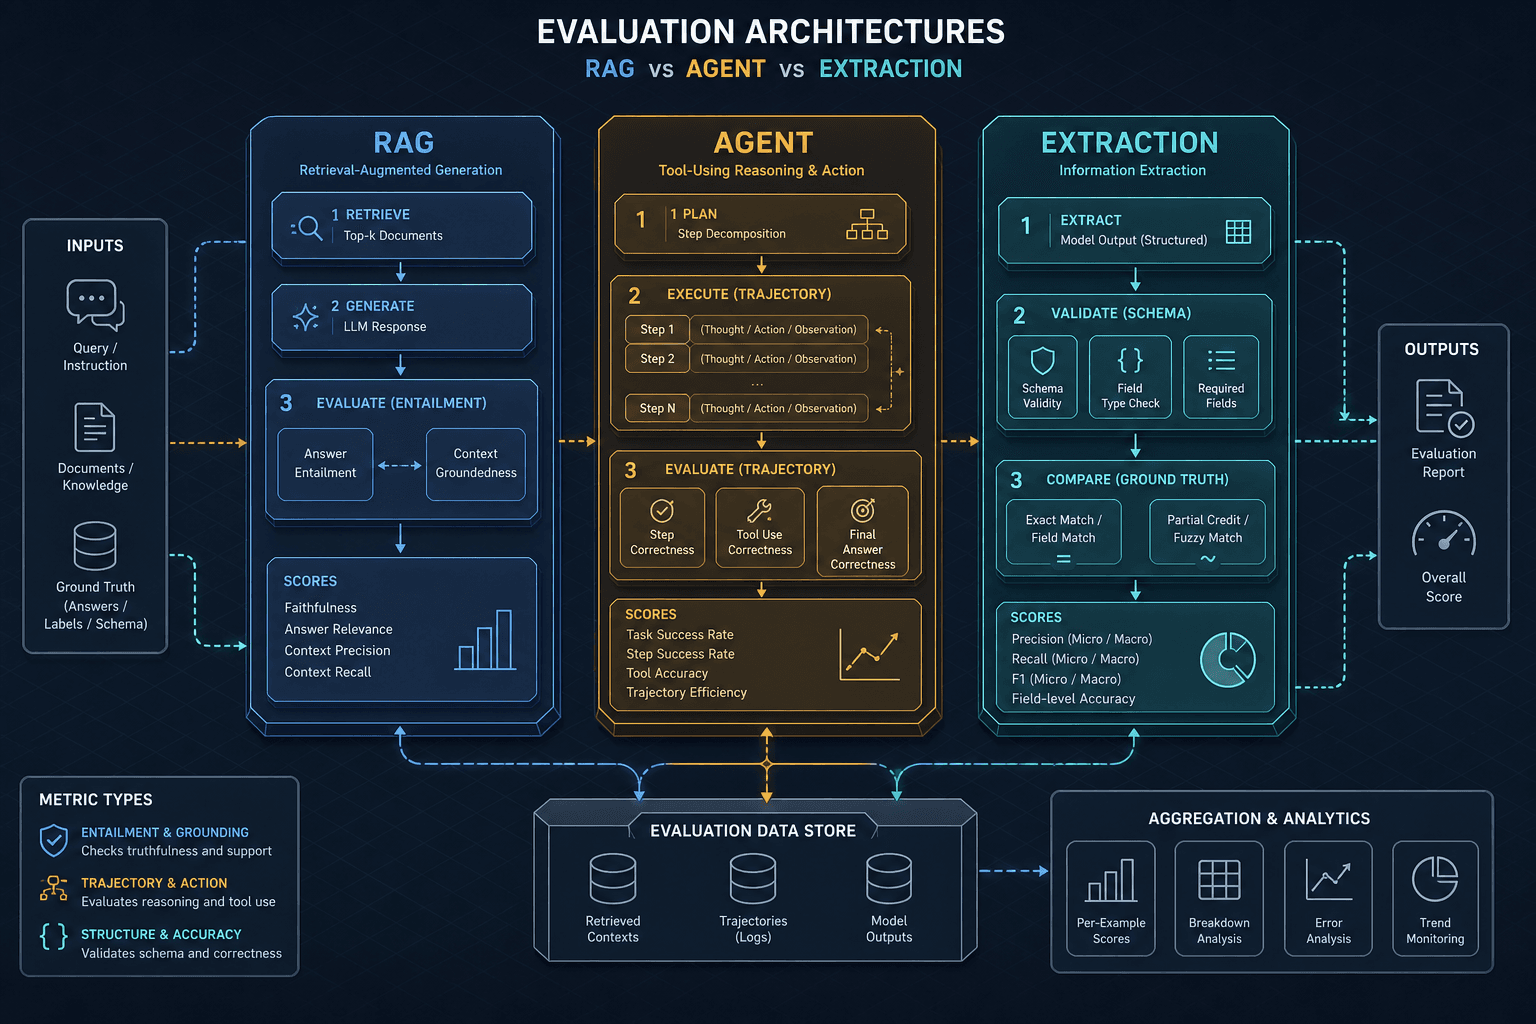
Part 5 · LLM Evaluation EngineeringA practical look at faithfulness, groundedness, trajectory metrics, extraction accuracy, and task metrics for evaluating RAG, agents, and extraction systems.
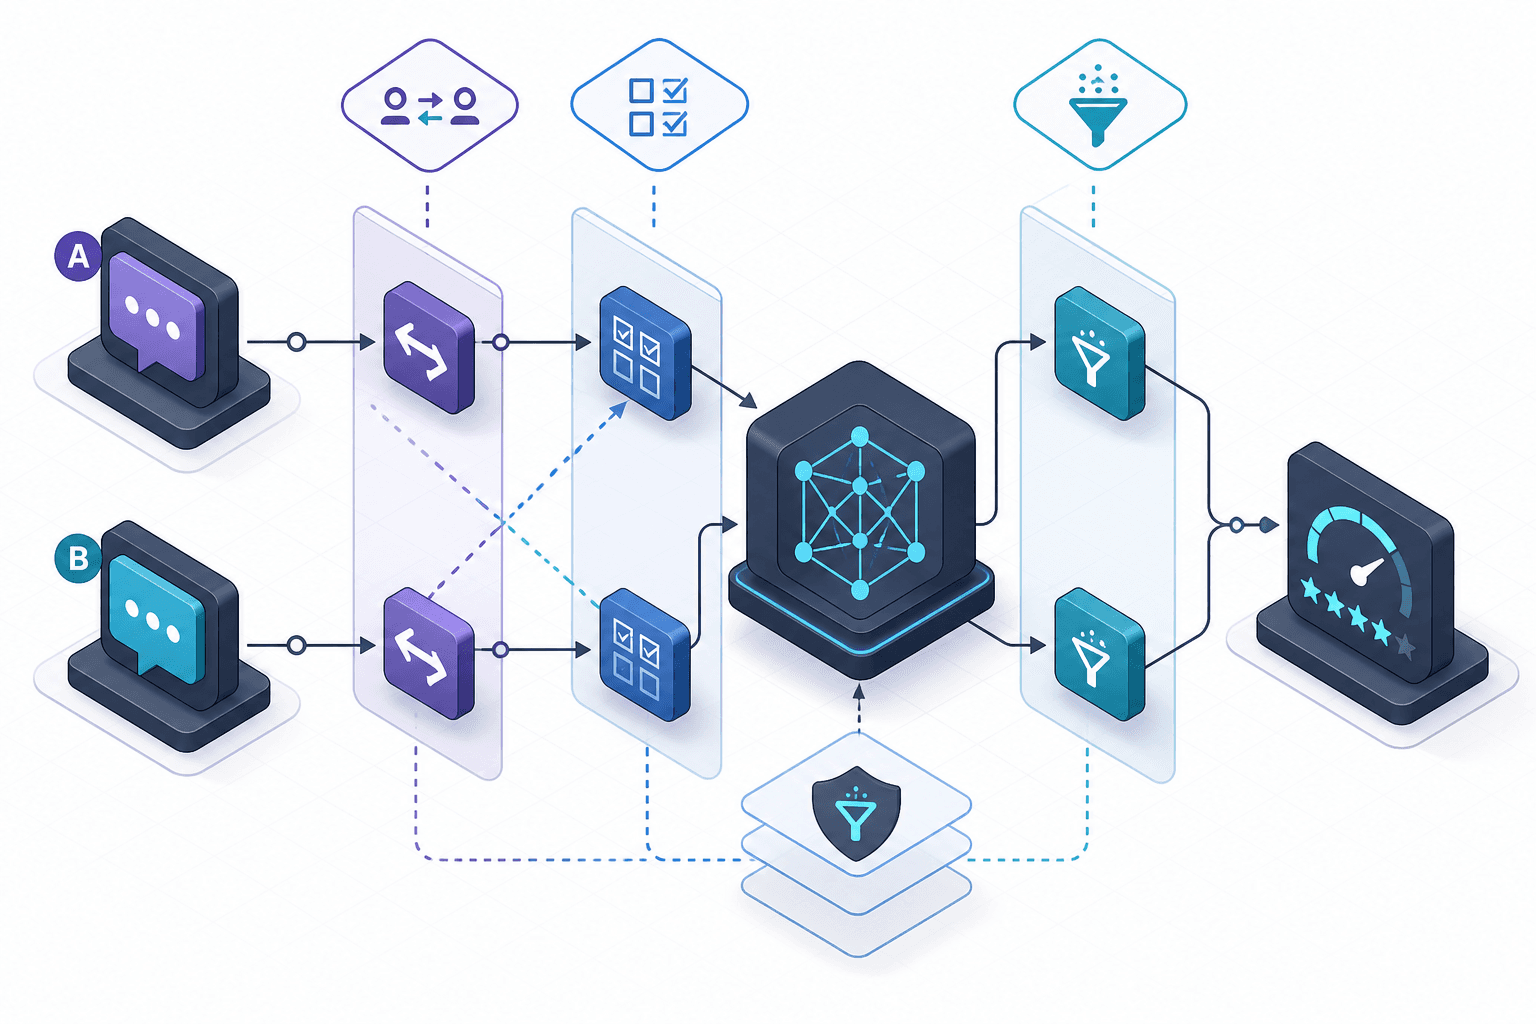
Part 4 · LLM Evaluation EngineeringExplore methods to stabilize LLM-as-a-judge evaluations, addressing position bias, calibration issues, and rubric design for reliable automated grading.
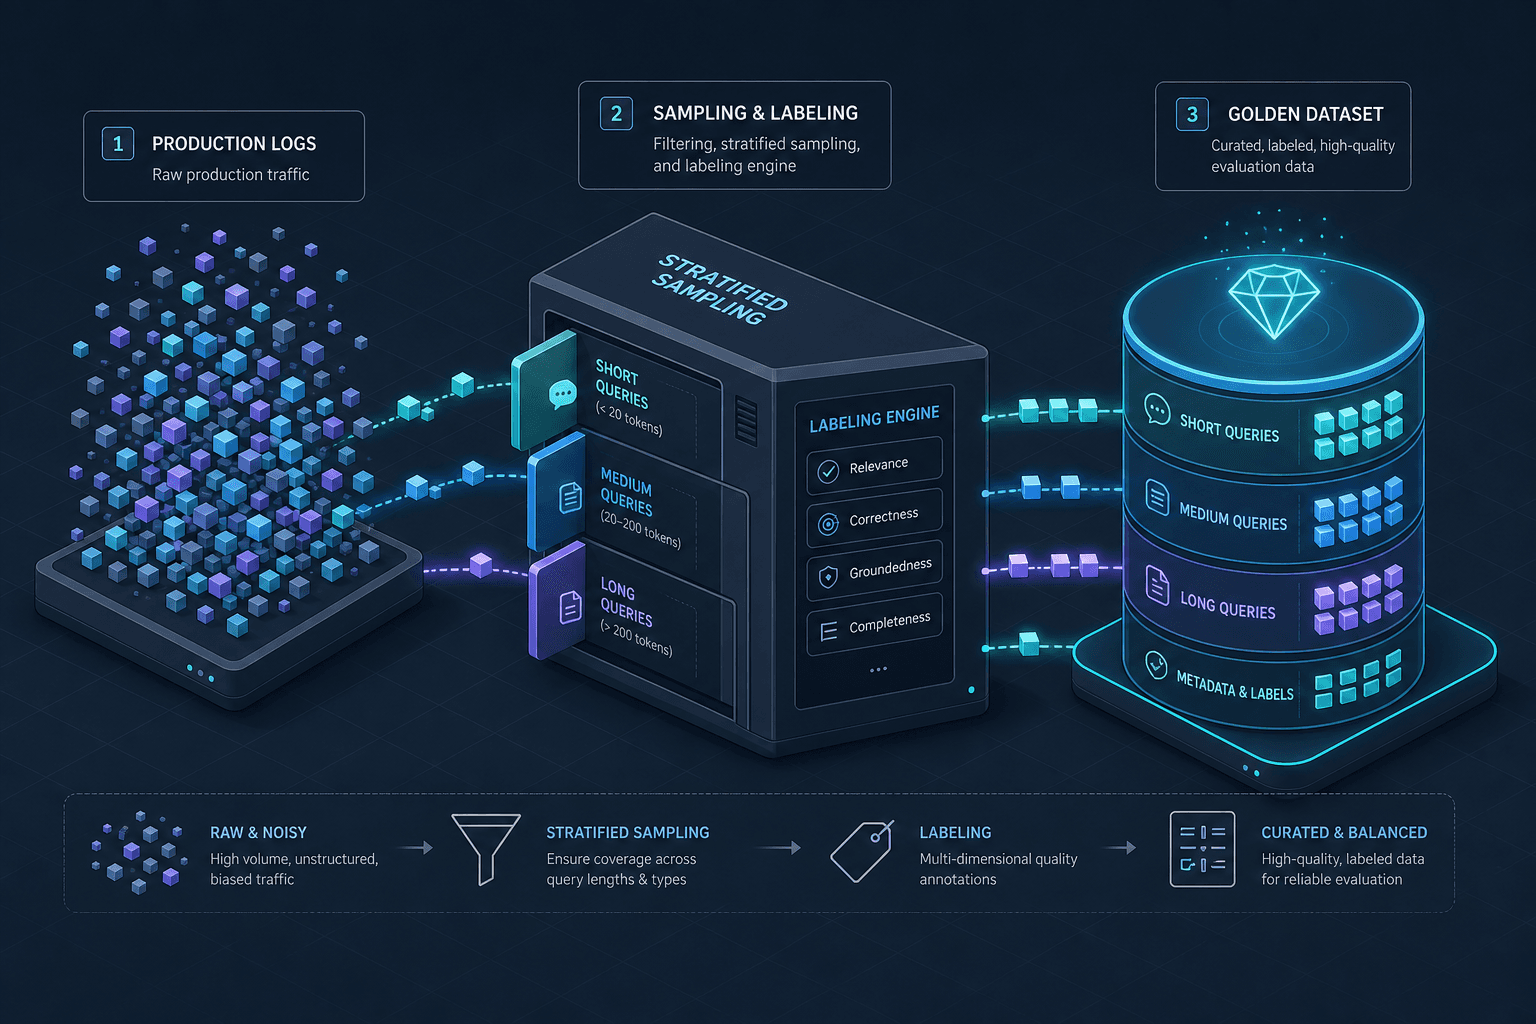
Part 3 · LLM Evaluation EngineeringLearn how to extract, sample, and label production traffic to build a reliable golden dataset for evaluating large language models in production environments.
Part 2 · LLM Evaluation EngineeringYour LLM evaluation suite might be giving you false confidence. We examine the statistical pitfalls of variance and small sample sizes in benchmarking.
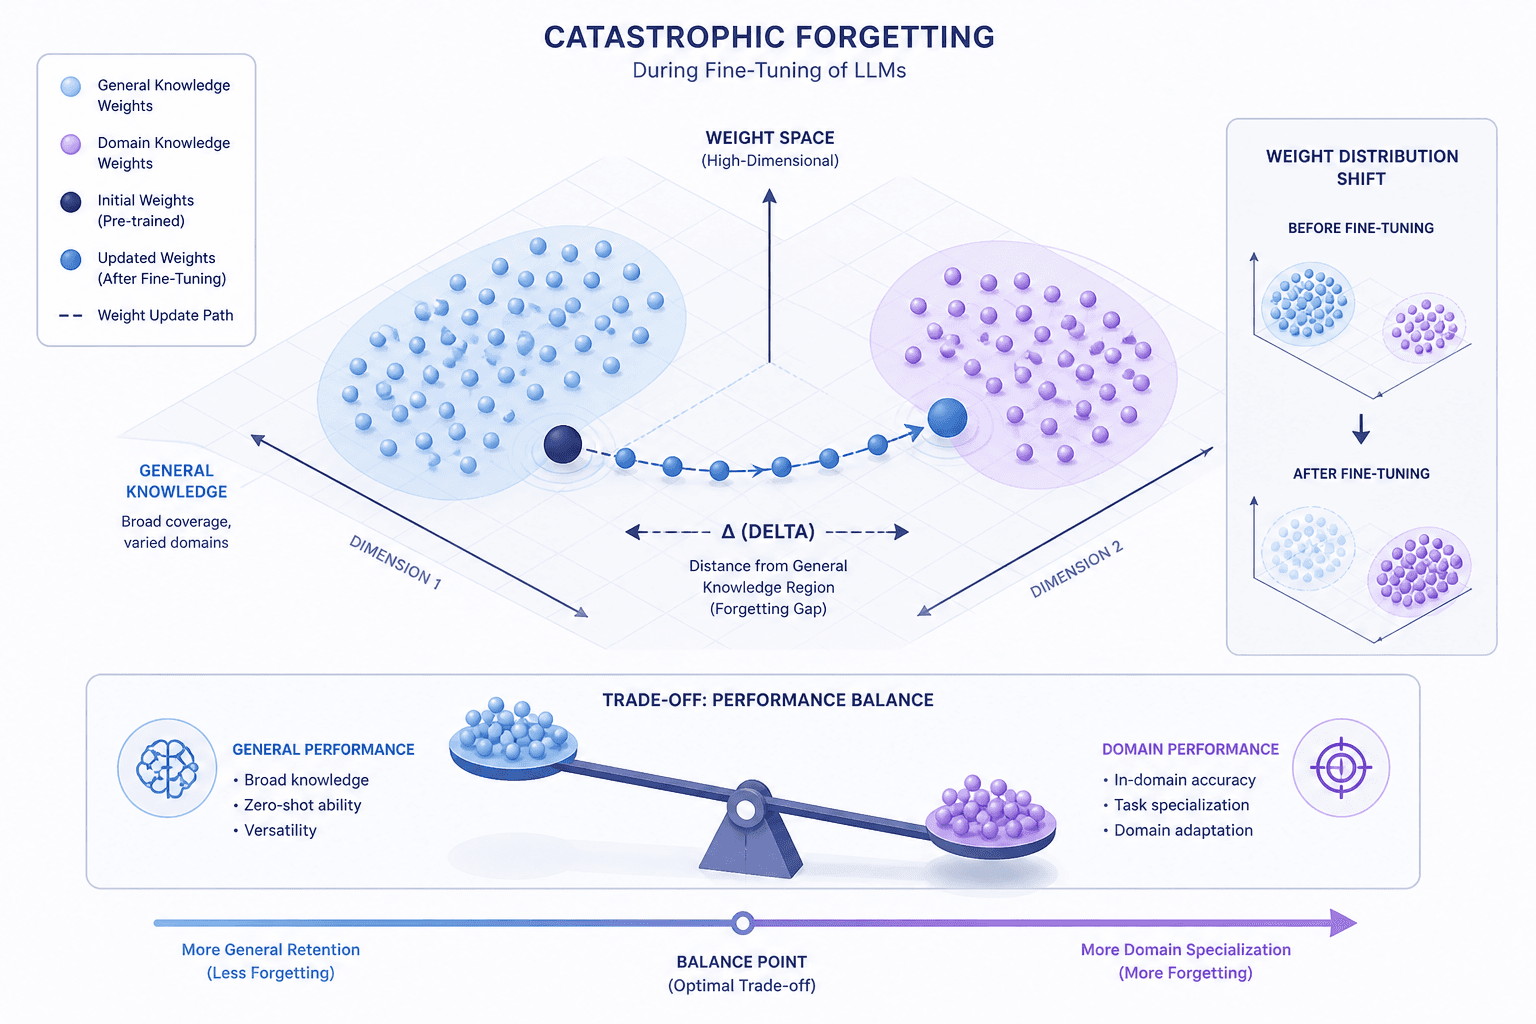
Part 1 · LLM Evaluation EngineeringLearn how to rigorously evaluate fine-tuned LLMs against their base counterparts using held-out datasets and regression testing strategies.
Part 7 · Fine-Tuning LLMs Hands-On