6 min readDevelopmentFeatured
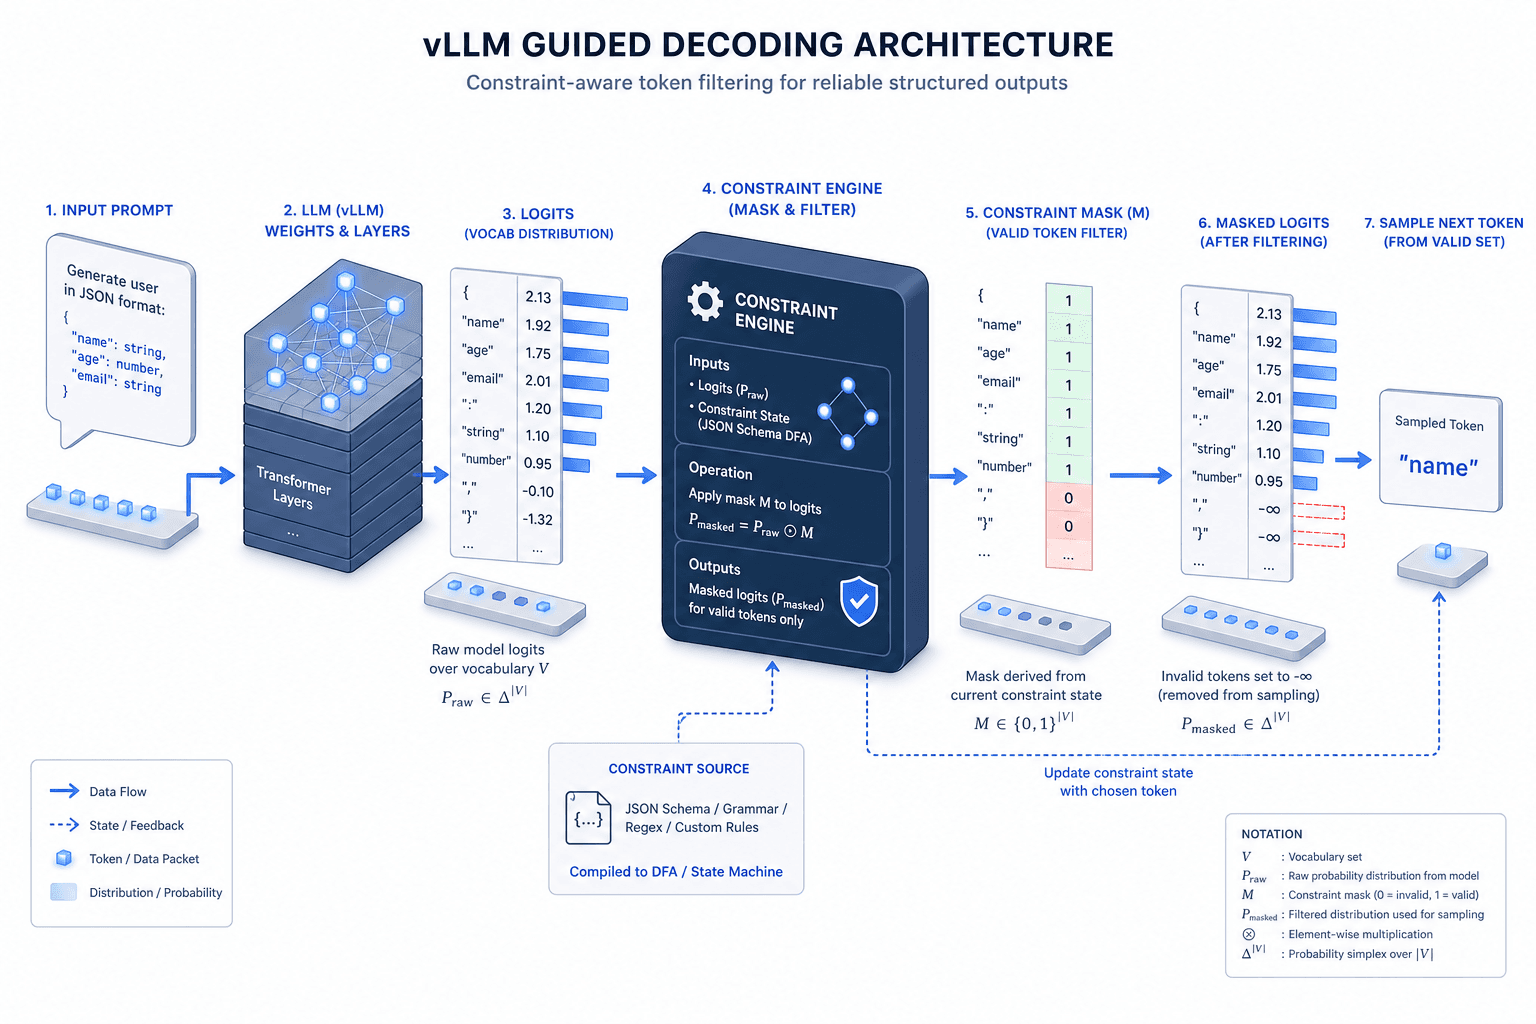
Structured Output and Guided Decoding in vLLM
Learn how to enforce strict output formats in vLLM using guided decoding, JSON schemas, and grammar constraints for production-grade reliability.
Part 6 · Production vLLMTag
Read 52 articles on Llm by Ashish Srivastava — practical guides covering implementation patterns, security, and production lessons.
52 posts · page 3 of 3
Learn how to enforce strict output formats in vLLM using guided decoding, JSON schemas, and grammar constraints for production-grade reliability.
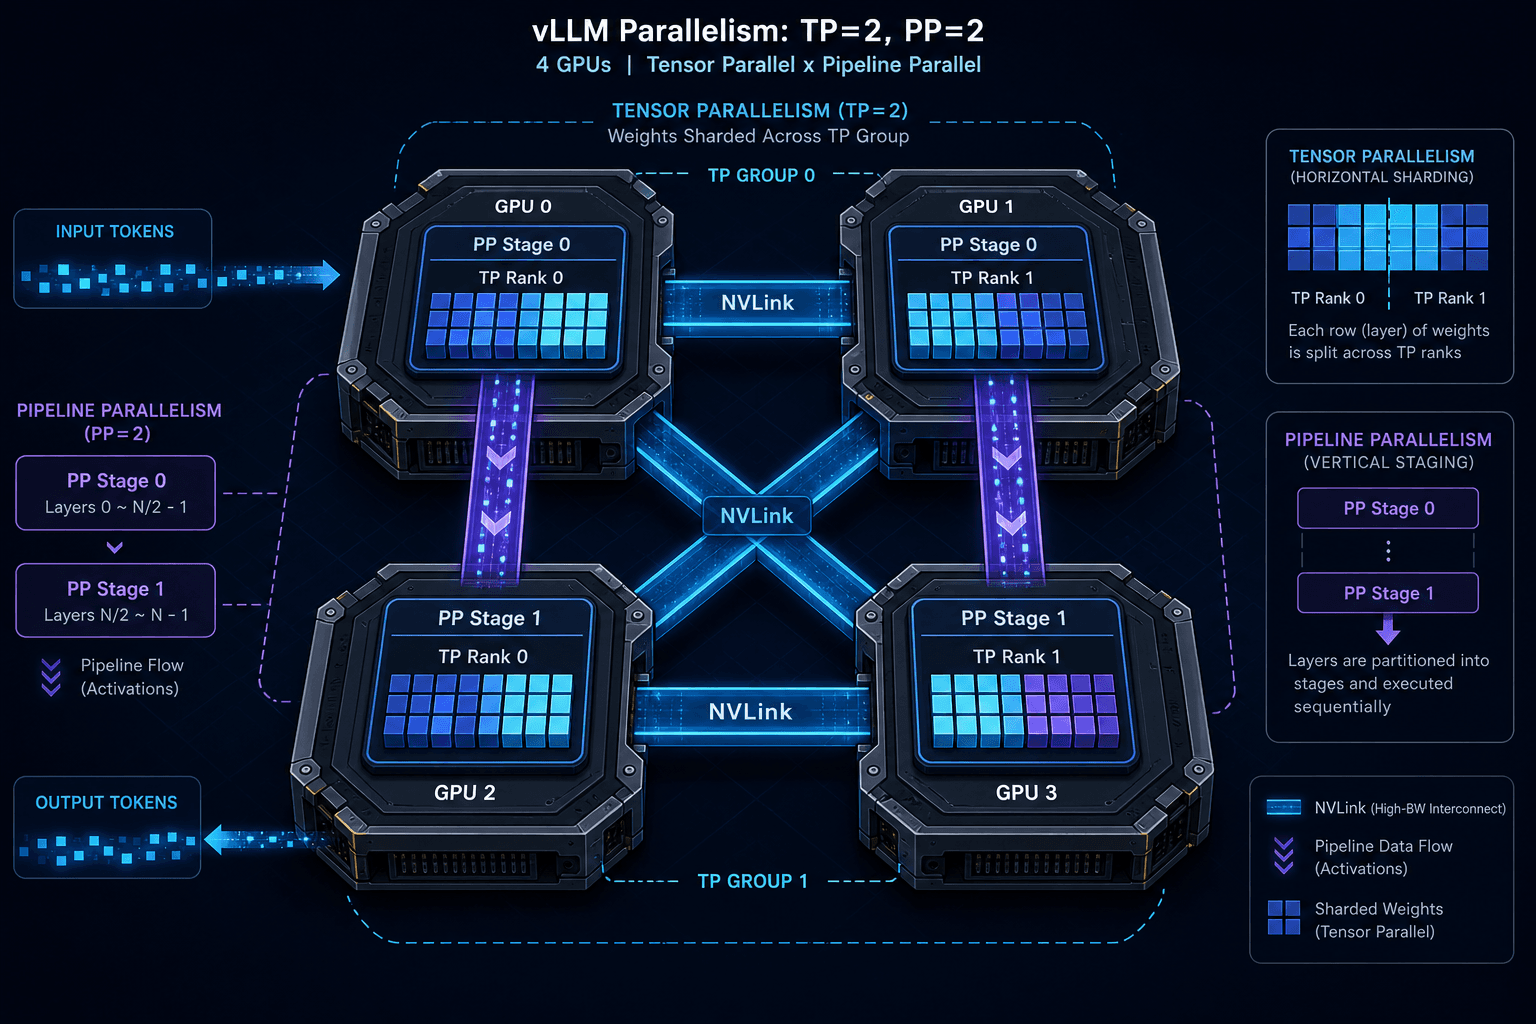
Part 6 · Production vLLMA technical breakdown of tensor and pipeline parallelism strategies in vLLM for infrastructure and ML engineers deploying large language models.
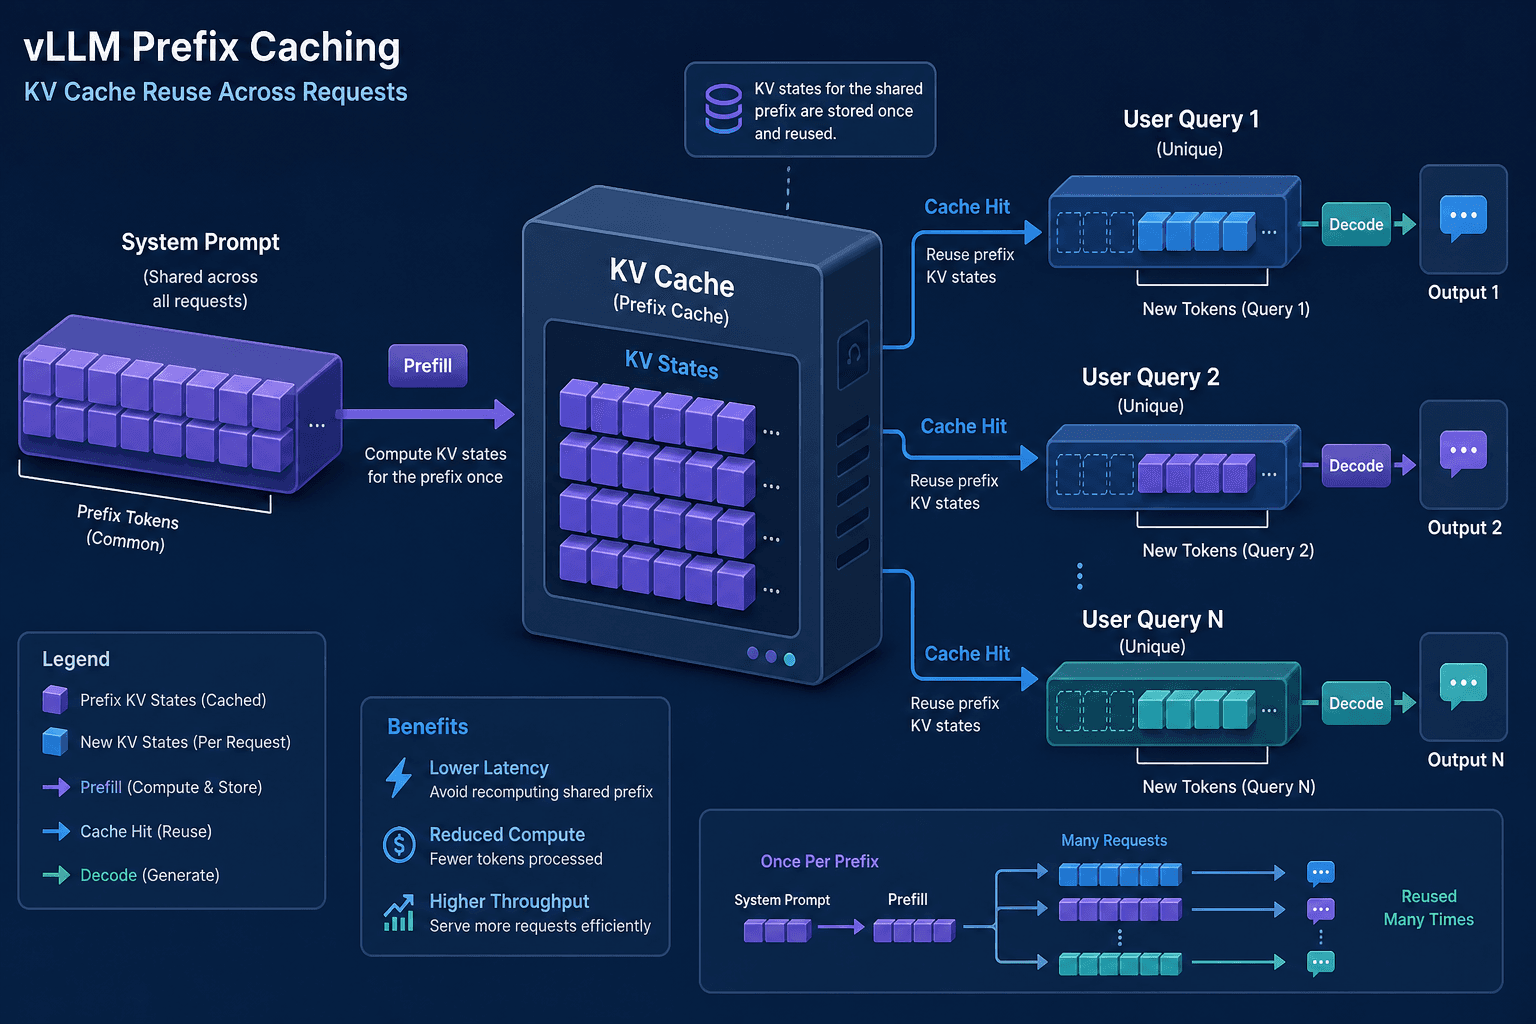
Part 5 · Production vLLMExplore the nuances of prefix caching in vLLM. Learn when automatic prefix caching boosts TTFT and cache hit rates, and identify scenarios where it offers little value.
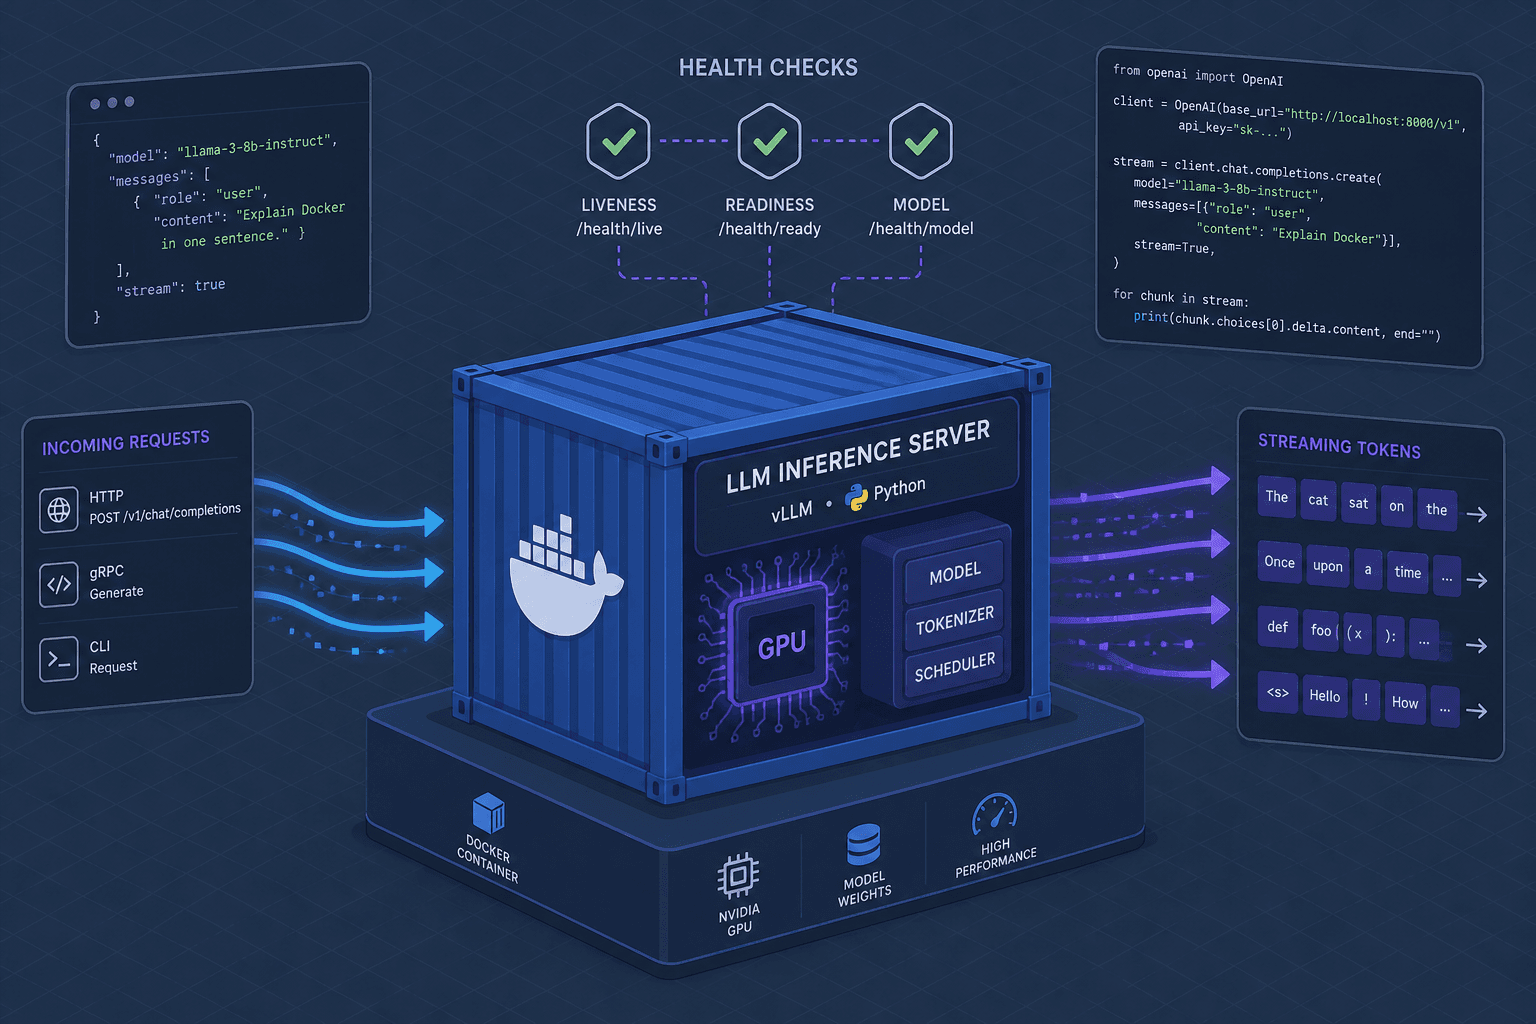
Part 4 · Production vLLMLearn to deploy a reliable inference server with Docker, implementing streaming responses and health checks for production readiness.
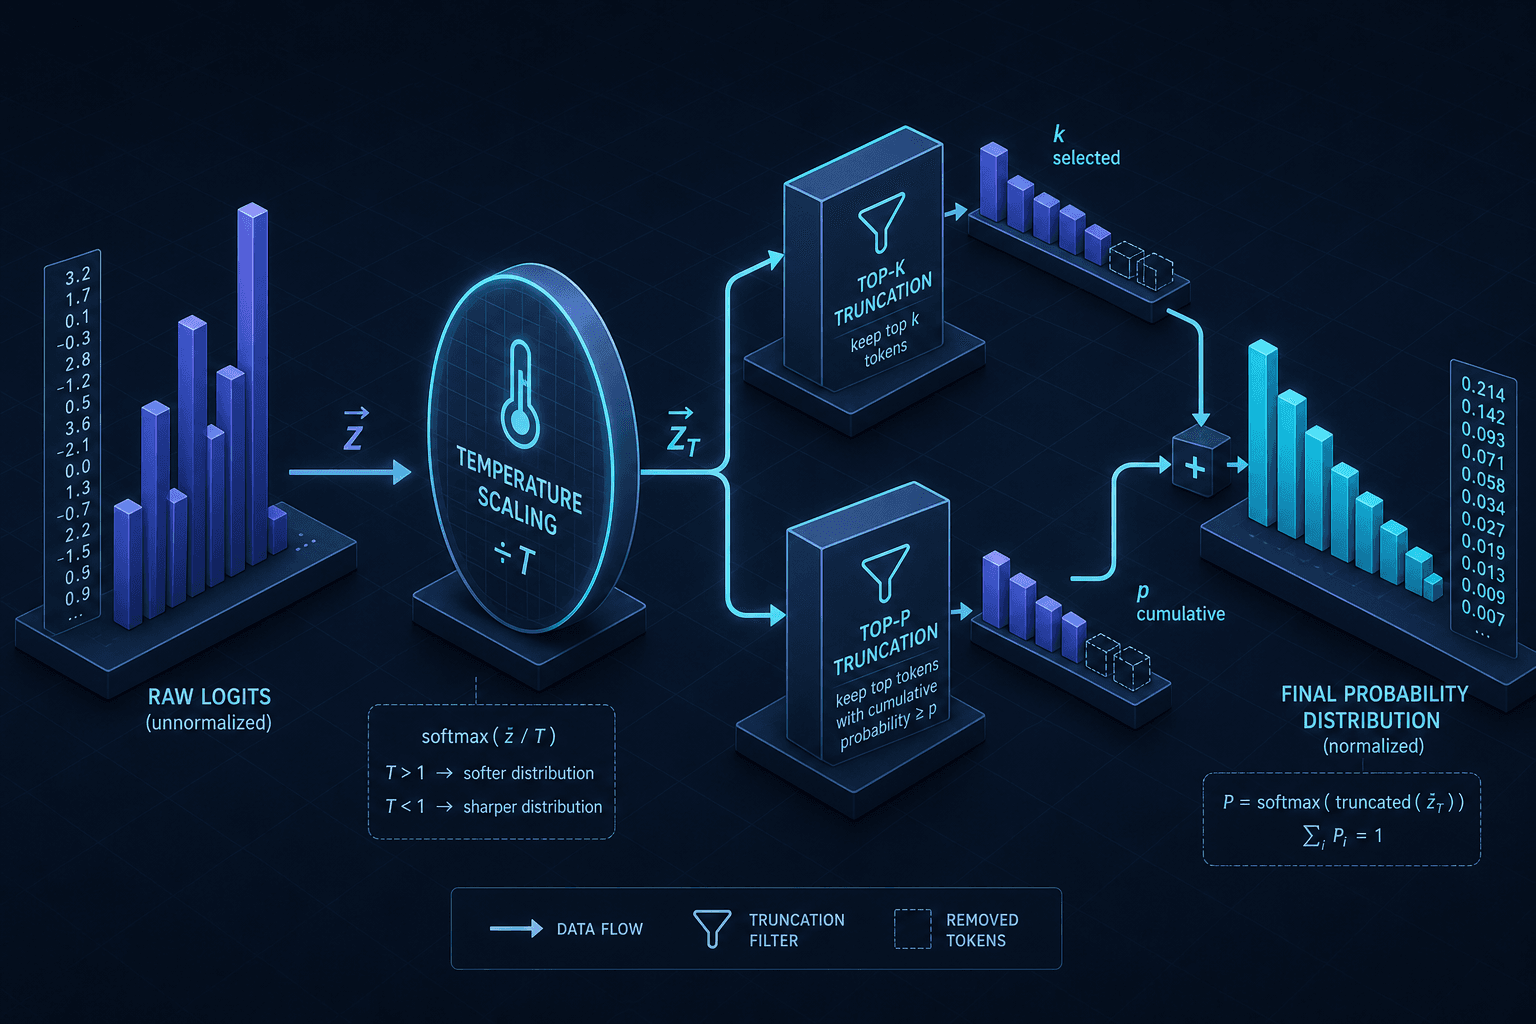
Part 8 · LLM Inference from ScratchA technical breakdown of sampling parameters like temperature, top-p, top-k, and min-p, explaining how they control the randomness and quality of LLM generation.
Part 7 · LLM Inference from ScratchUnderstanding TTFT, TPOT, and p99 is essential for optimizing LLM inference. This guide breaks down these metrics for SREs and backend developers.
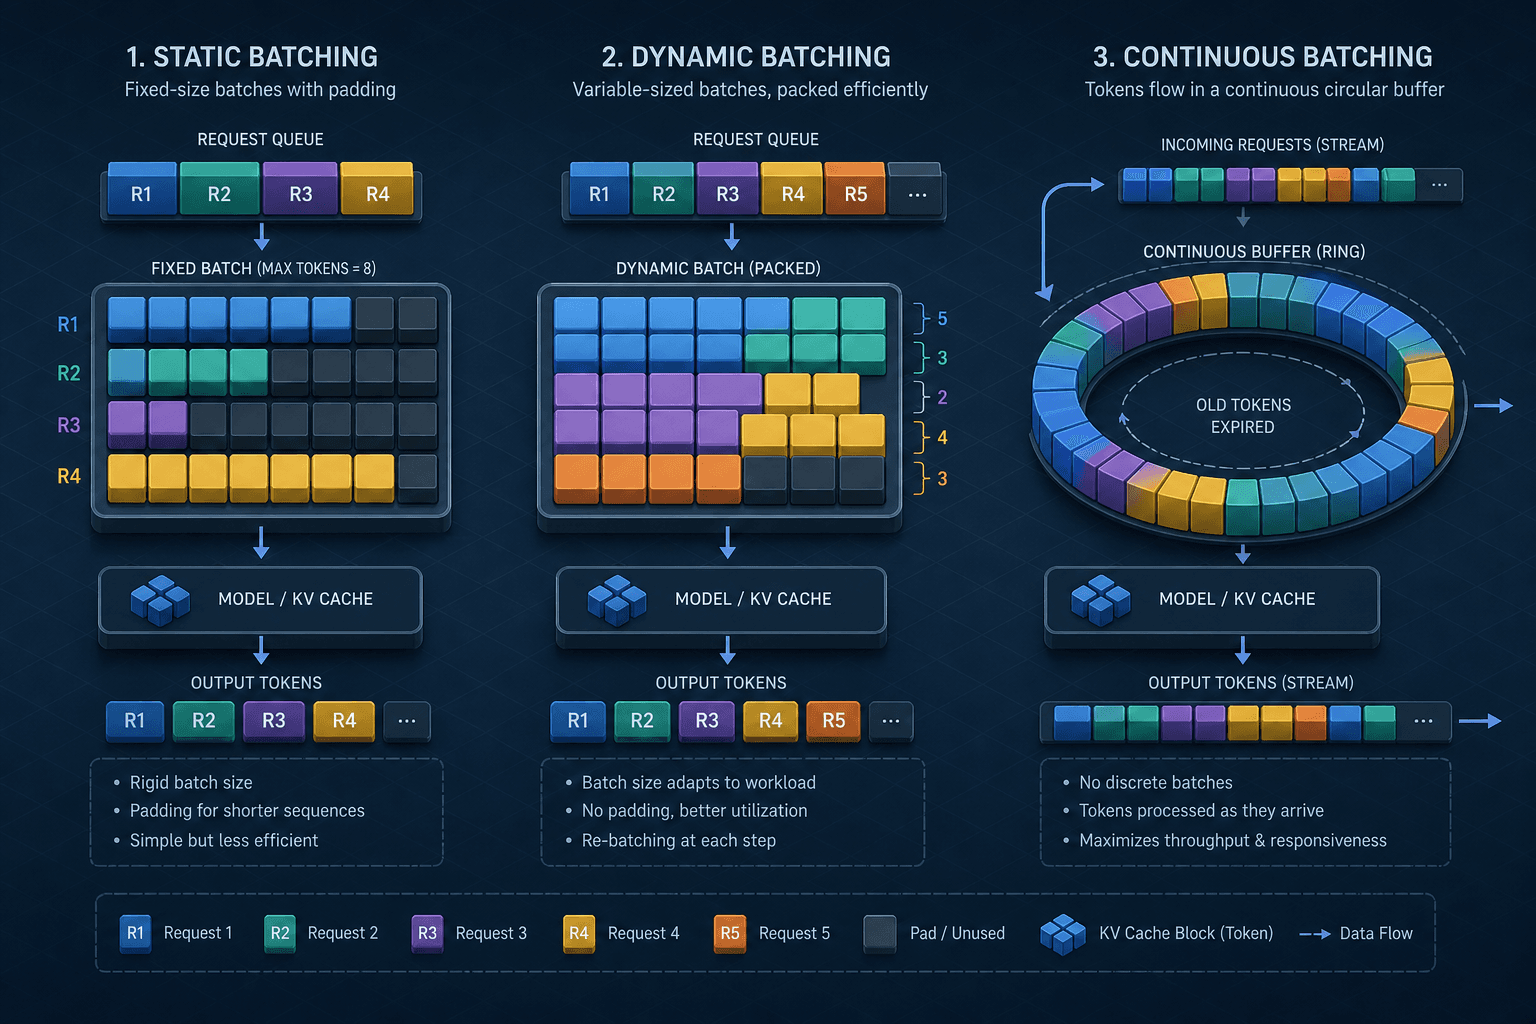
Part 6 · LLM Inference from ScratchExplore how static, dynamic, and continuous batching strategies impact LLM inference performance, focusing on throughput optimization and latency reduction.
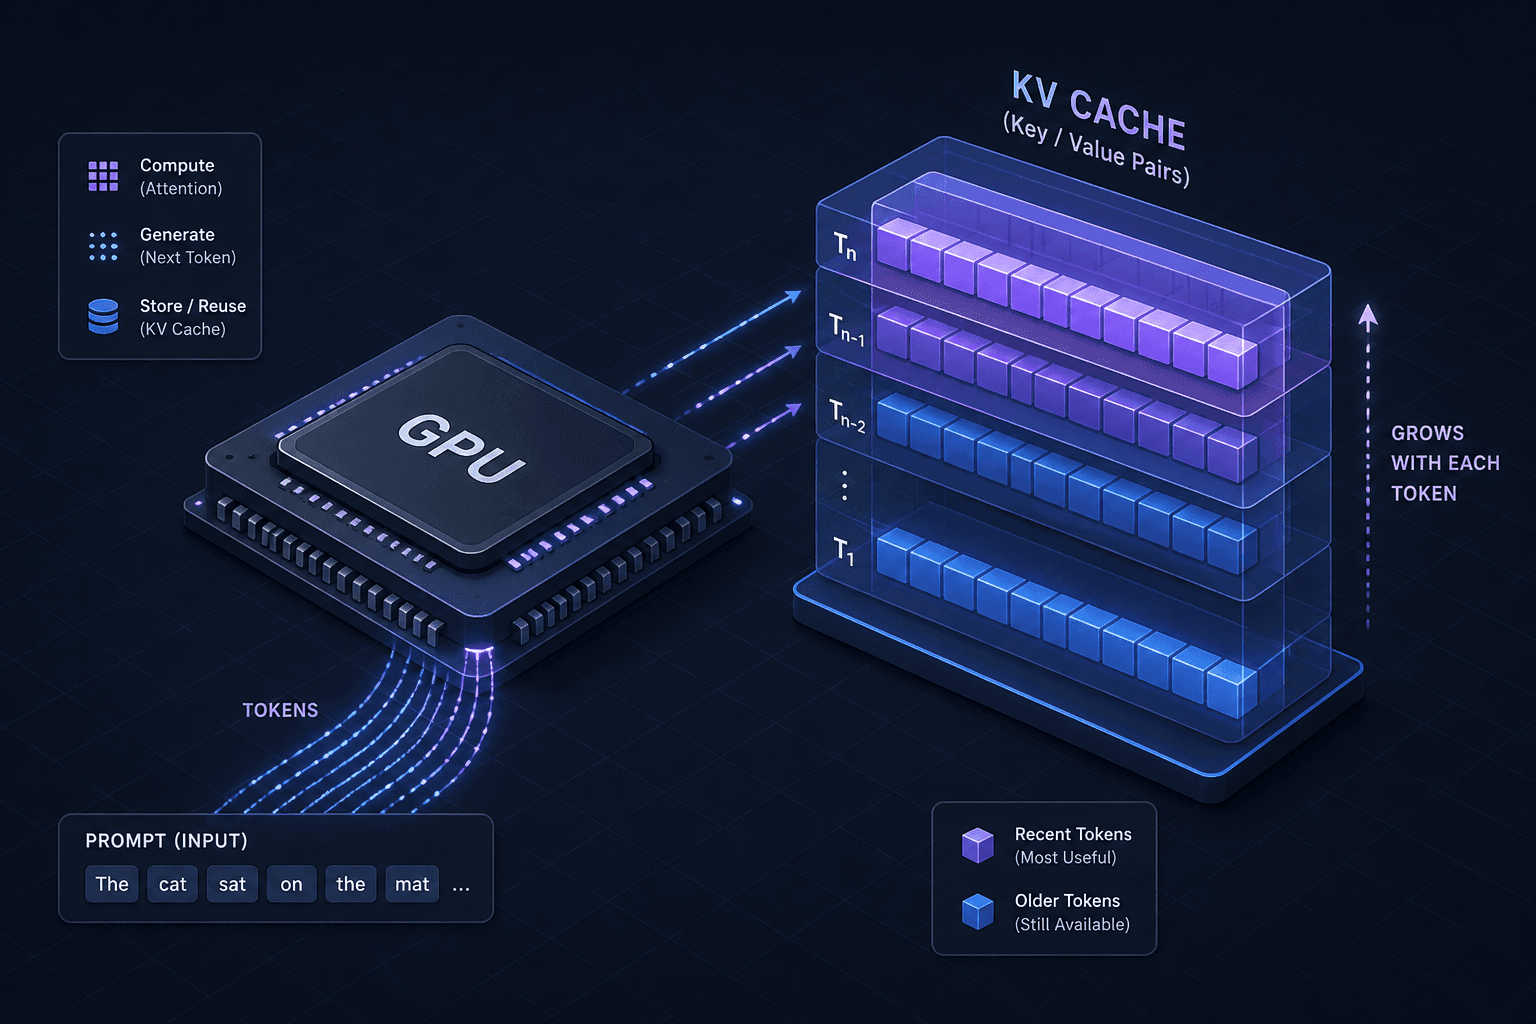
Part 5 · LLM Inference from ScratchUnderstand how the KV cache accelerates LLM inference by storing attention states, reducing redundant computation, and boosting concurrency efficiency.
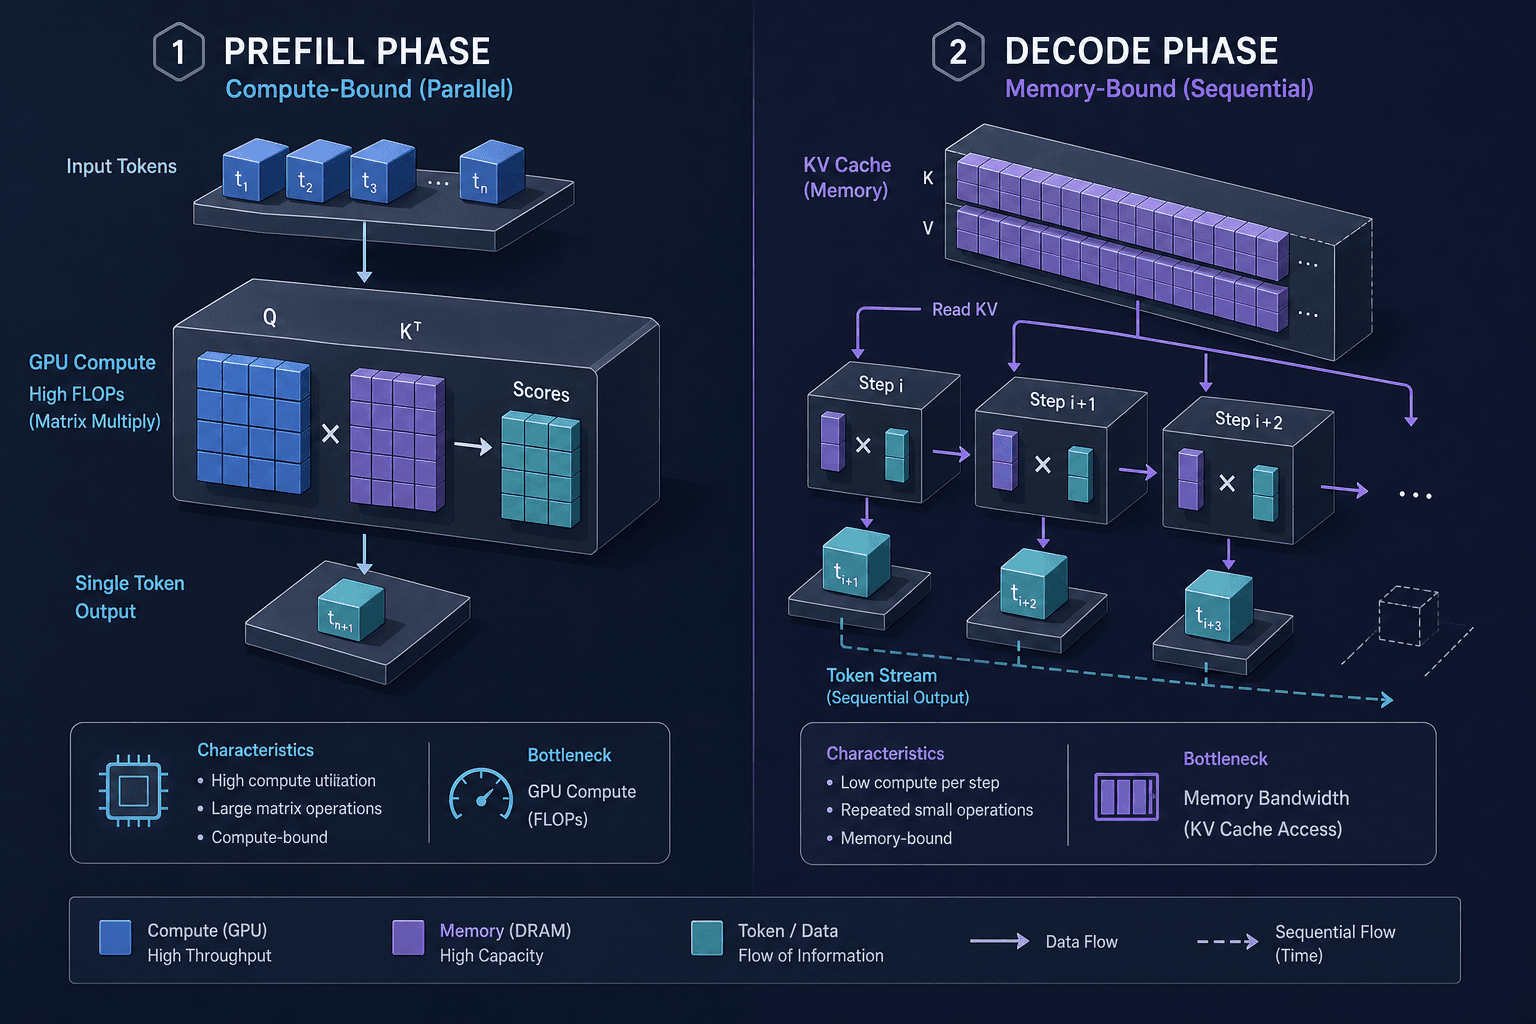
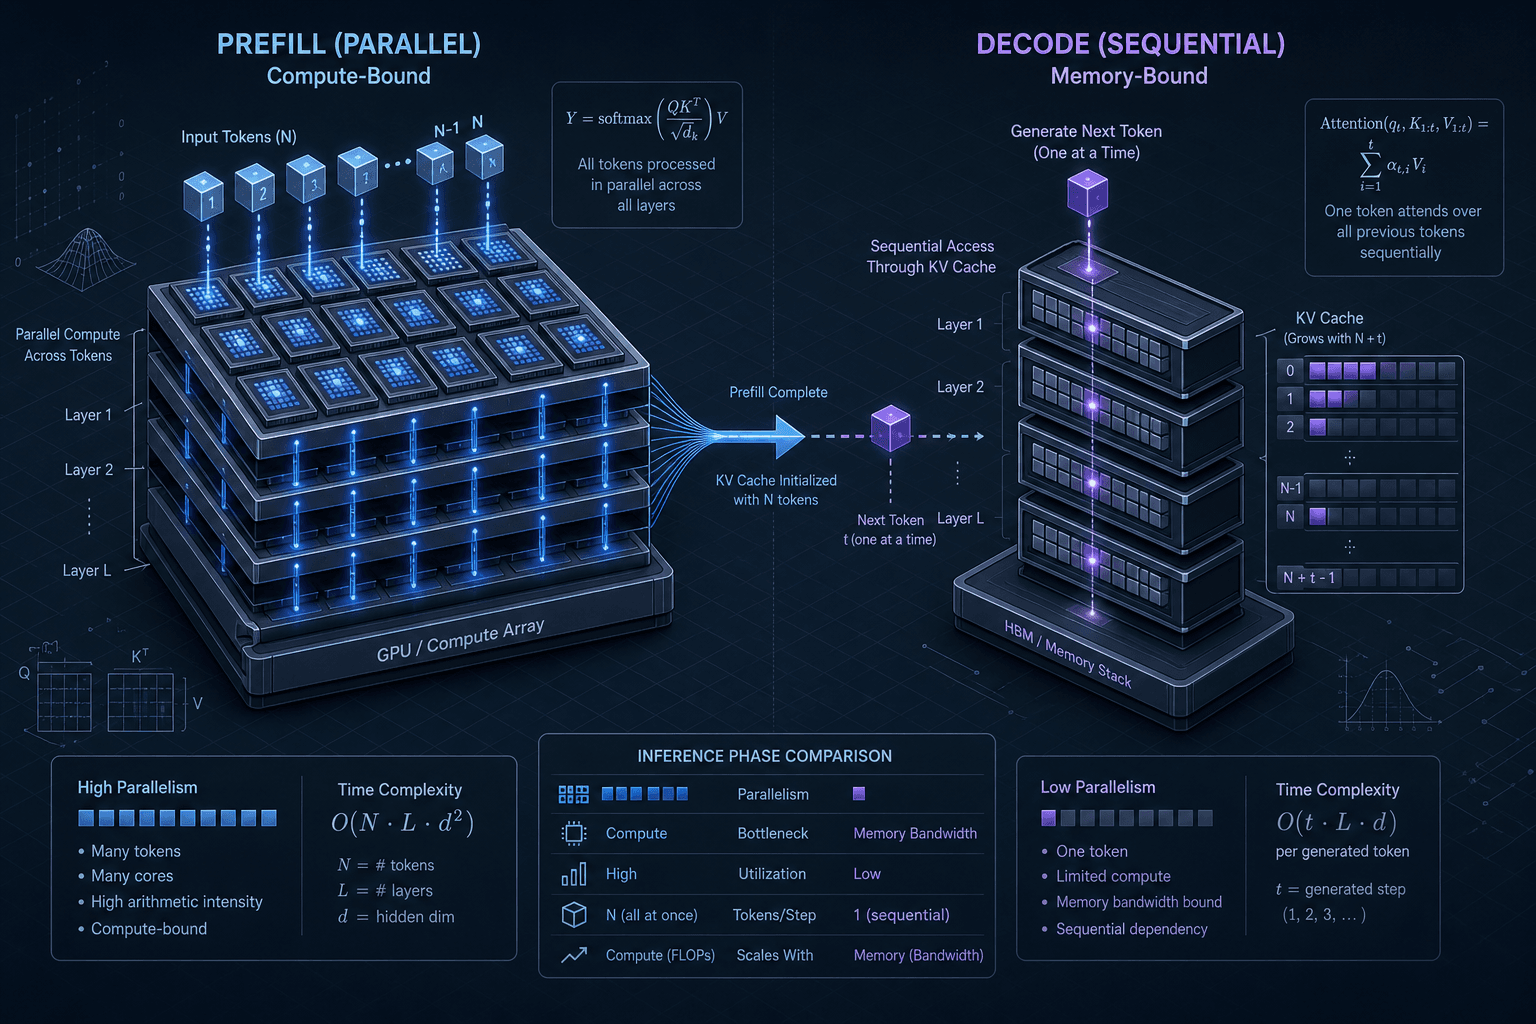
Part 4 · LLM Inference from ScratchUnderstand the distinct computational demands of the prefill and decode stages in large language model inference, from initial token generation to subsequent output.
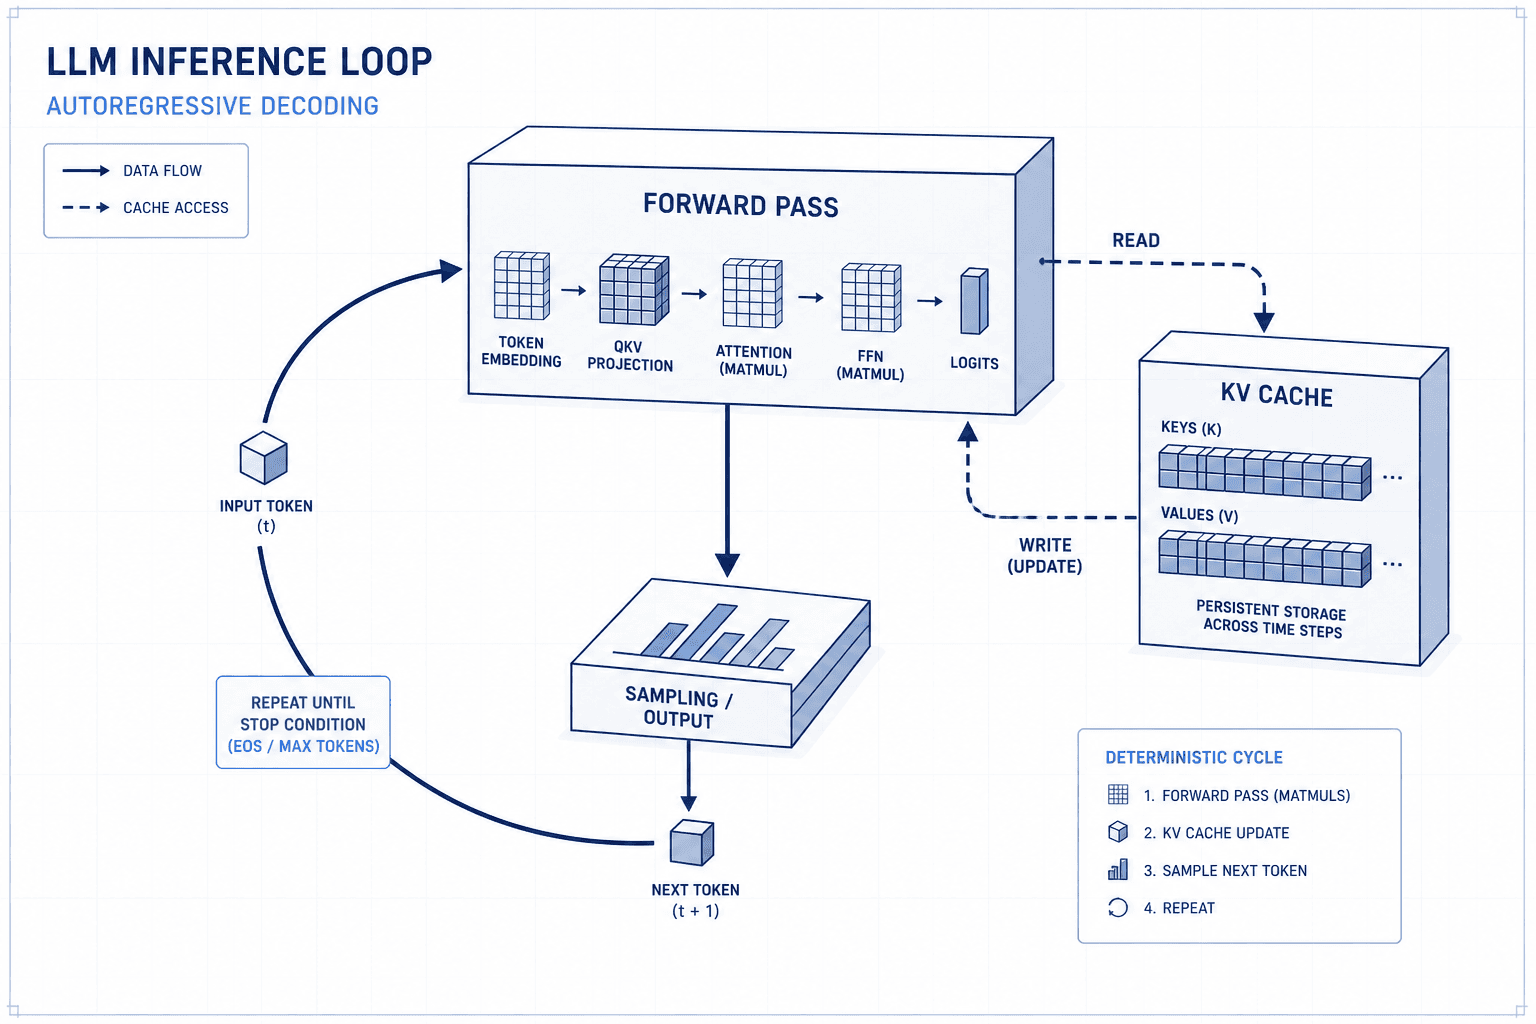
Part 3 · LLM Inference from ScratchUnderstand how LLMs generate text token by token. This guide breaks down the inference process, forward pass mechanics, and autoregressive logic for backend developers.
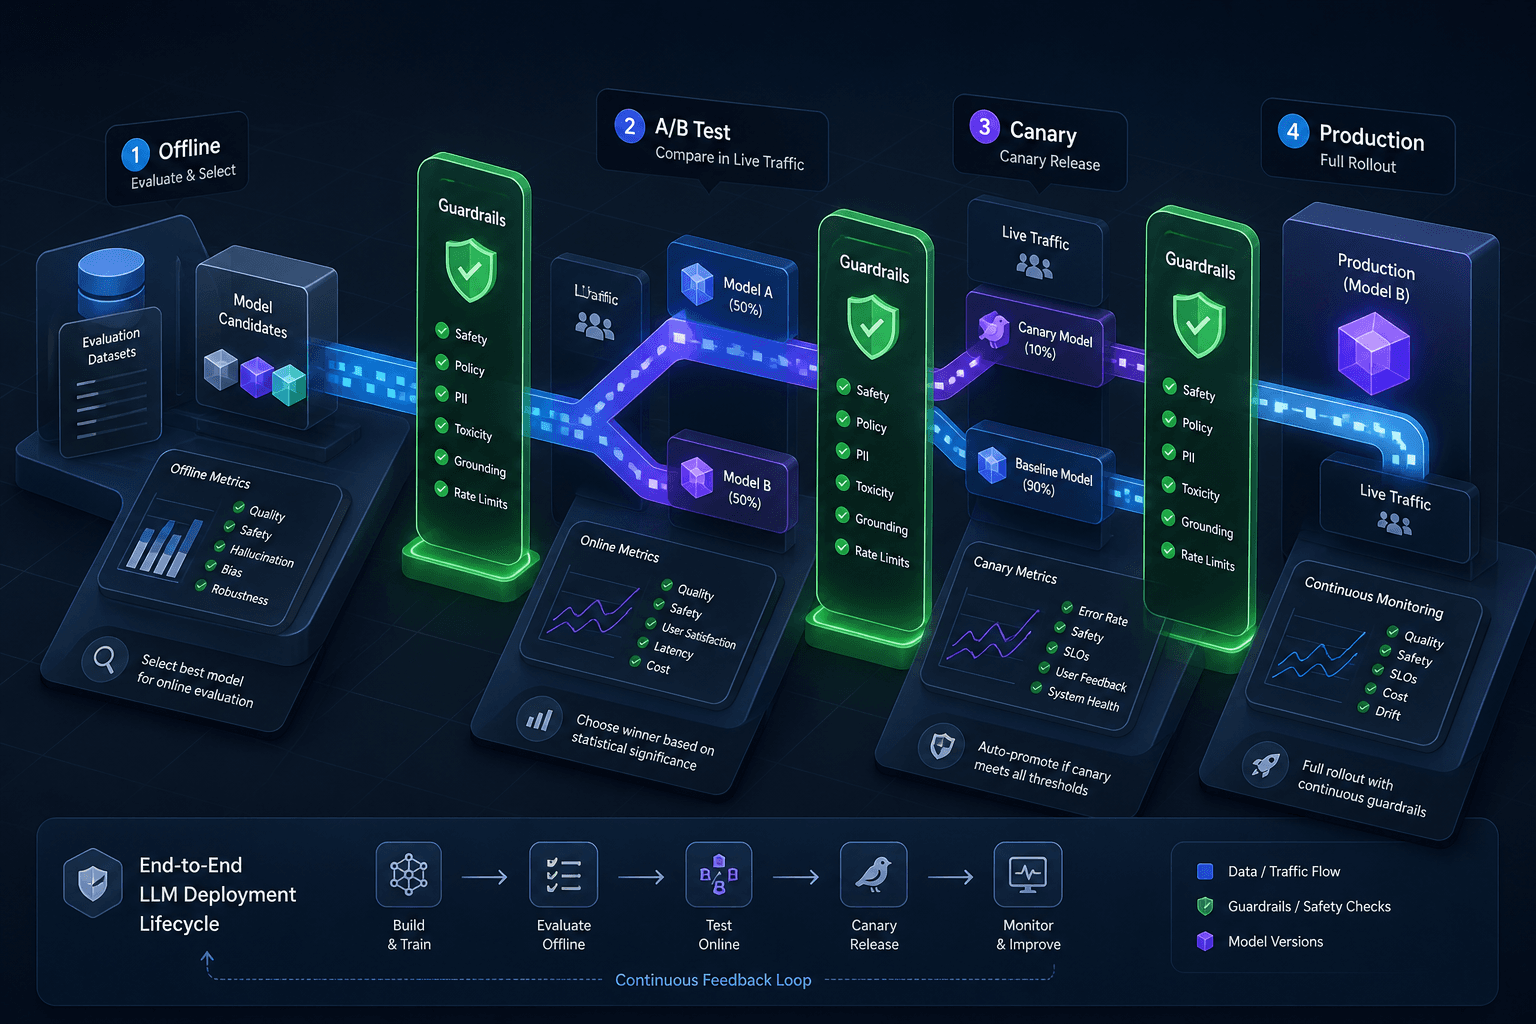
Part 1 · LLM Inference from ScratchA practical guide to deploying LLMs safely using online evaluation strategies like A/B testing, canary releases, and guarded rollouts.
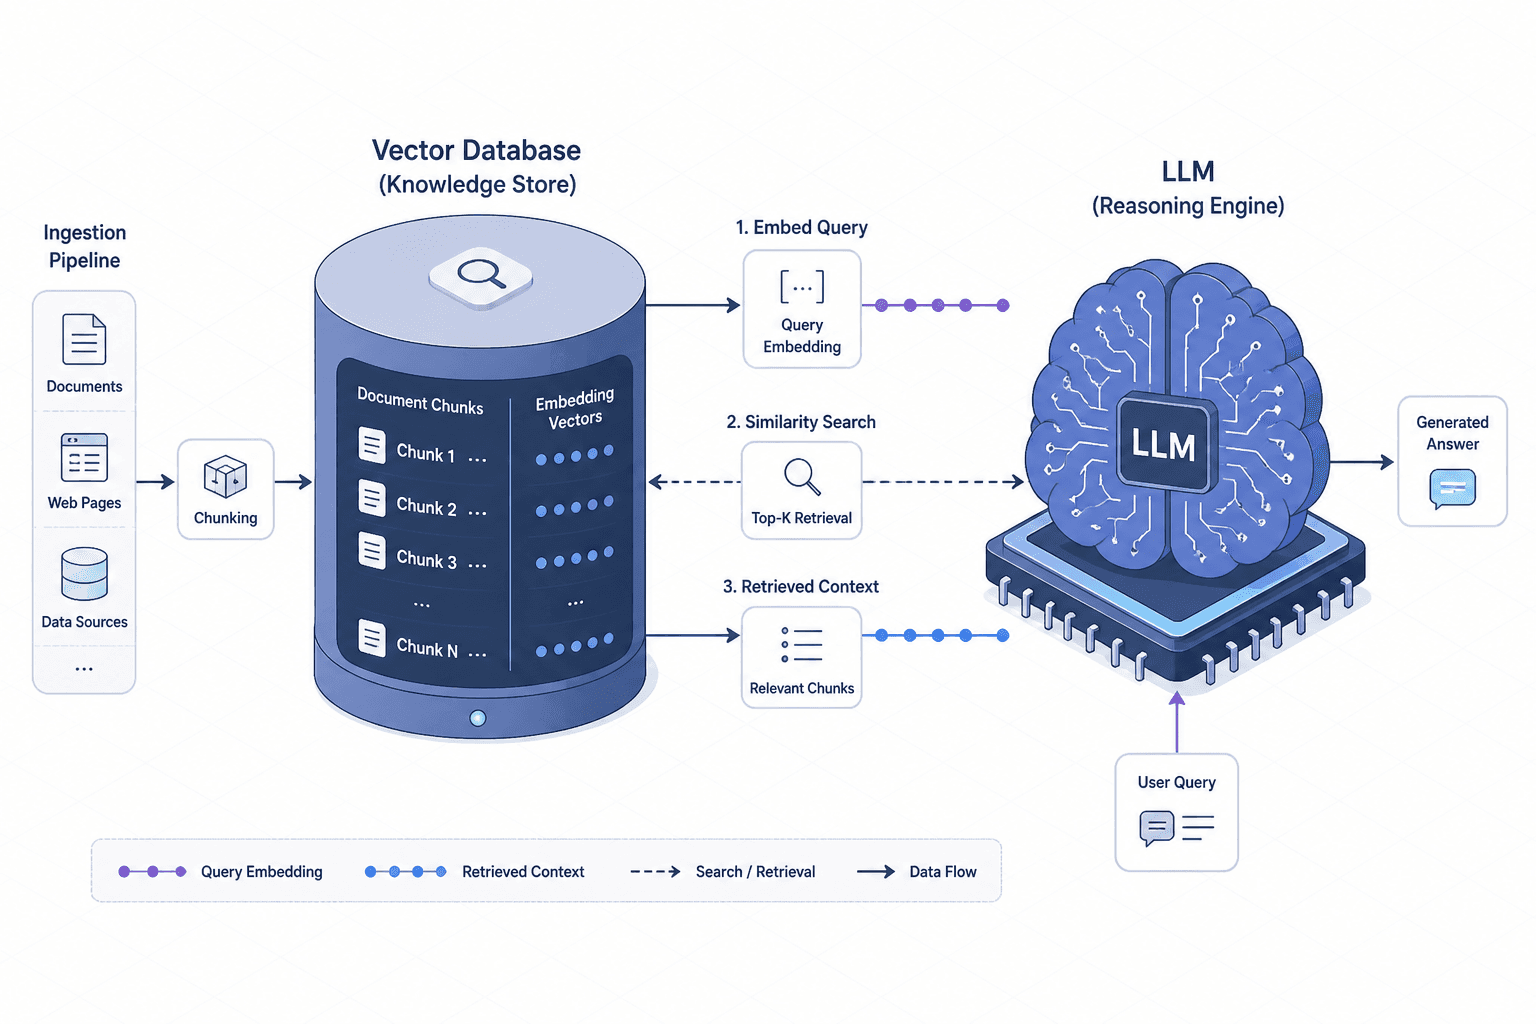
Part 6 · LLM Evaluation EngineeringRAG is often oversold. This article breaks down the actual mechanics of grounding LLMs with external data, what problems it solves, and where it falls short.
Part 1 · RAG from Zero to Production